


[ad_1]
Apache Hudi is an open-source transactional knowledge lake framework that tremendously simplifies incremental knowledge processing and knowledge pipeline improvement by offering record-level insert, replace, and delete capabilities. This record-level functionality is useful if you happen to’re constructing your knowledge lakes on Amazon Easy Storage Service (Amazon S3) or Hadoop Distributed File System (HDFS). You should utilize it to adjust to knowledge privateness laws and simplify knowledge ingestion pipelines that take care of late-arriving or up to date data from streaming knowledge sources, or to ingest knowledge utilizing change knowledge seize (CDC) from transactional methods. Apache Hudi is built-in with open-source huge knowledge analytics frameworks like Apache Spark, Apache Hive, Presto, and Trino. It means that you can keep knowledge in Amazon S3 or HDFS in open codecs like Apache Parquet and Apache Avro.
Beginning with launch model 5.28.0, Amazon EMR installs the Hudi element by default once you set up Spark, Hive, Presto, or Trino. Because the inclusion of Apache Hudi inside Amazon EMR, there was a number of enhancements and bug fixes which were added to Apache Hudi. Apache Hudi graduated as a top-level Apache challenge on June 2020.
On this publish, we offer a abstract of among the key new options and capabilities included since Apache Hudi launch variations 0.7.0 and 0.8.0. These new options and capabilities of Hudi can be found since Amazon EMR releases 5.33.0 and 6.3.0:
- Clustering
- Metadata-based file itemizing
- Amazon CloudWatch integration
- Optimistic Concurrency Management
- Amazon EMR configuration assist and enhancements
- Apache Flink integration
- Kafka commit callbacks
- Different enhancements
Clustering
We see extra use instances that want excessive throughput ingestion to knowledge lakes. Nevertheless, quicker knowledge ingestion typically results in smaller knowledge file sizes that always adversely impacts question efficiency, as a result of a lot of small information will increase the expensive I/O operations required to return outcomes. One other concern that we see is that the group of knowledge throughout ingestion is completely different from the group that will be most effective when querying the information. For instance, it’s handy to ingest ecommerce orders by OrderDate as they arrive in, however when queried, it’s higher if orders for a single buyer are saved collectively.
Apache Hudi model 0.7.0 introduces a brand new characteristic that means that you can cluster the Hudi tables. Clustering in Hudi is a framework that gives a pluggable technique to alter and reorganize the information structure whereas additionally optimizing the file sizes. With clustering, now you can optimize question efficiency with out having to trade-off knowledge ingest throughput.
You should utilize clustering to rewrite the information utilizing completely different strategies as per the completely different use case necessities:
- Enhance question efficiency with knowledge locality – This modifications the information structure on disk by sorting the information on one or many user-specified columns. With this method, we are able to enhance question efficiency by utilizing the Parquet file format’s means to carry out predicate push-down and skip the undesirable information and Parquet row teams. This technique can even management the file measurement to keep away from small information.
- Enhance knowledge freshness – This requirement assumes that the information locality will not be necessary or taken care of already on the time of ingestion. It’s ideally suited to be used instances the place contemporary knowledge is necessary, the place knowledge is ingested utilizing a number of small information and stitched or merged later utilizing the clustering framework.
You may run the clustering desk service asynchronously or synchronously. It additionally introduces the brand new motion kind REPLACE, which identifies the clustering motion within the Hudi metadata timeline.
Within the following instance, we create two Copy on Write (CoW) Hudi tables: amazon_reviews and amazon_reviews_clustered utilizing Amazon EMR launch model 6.3.0.
We use spark-shell to create the Hudi tables. Begin the Spark shell by operating the next on the Amazon EMR main node:
We then create the Hudi desk amazon_reviews utilizing the BULK_INSERT operation and with out clustering enabled:
We then create the Hudi desk amazon_reviews_clustered utilizing BULK_INSERT operation and inline clustering enabled and sorted by columns star_rating and total_votes:
Let’s question these two tables and validate efficiency distinction. To validate the efficiency, we are going to use Spark SQL CLI – a handy instrument to run the Hive metastore service in native mode and execute queries enter from the command line. To begin the Spark SQL CLI, we execute the next command:
We restart the Spark SQL CLI (spark-sql) session between every run so as to keep away from caching or heat executors, which can affect question efficiency.
Let’s run the question in opposition to the non-clustered Hudi desk by operating the next within the spark-sql interface:
Let’s additionally run the identical question on our clustered desk from the spark-sql interface:
Let’s examine the underlying file scan efficiency for the 2 completely different Hudi tables. The next screenshot is the output from the Spark UI, which reveals the modifications within the information scanned for a similar variety of output rows. First we see the information scanned for the unclustered Hudi desk.
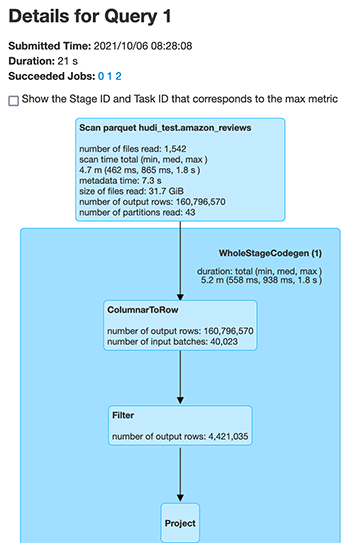
Subsequent, we see the information scanned for the clustered Hudi desk.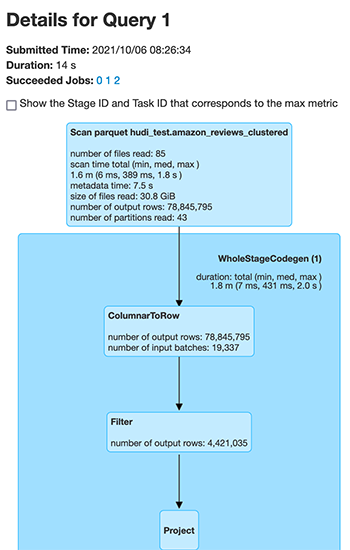
The variety of information scanned by Spark dropped from 1,542 information for the unclustered Hudi dataset to 85 information for the clustered Hudi dataset for the very same knowledge. Additionally, the variety of data scanned decreased from 160,796,570 to 78,845,795.
We in contrast the efficiency of the previous question for the amazon_reviews (non-clustered) and amazon_reviews_clustered (clustered) Hudi dataset, throughout Spark SQL, Hive, and PrestoDB. The cluster configuration used was 1 chief (m5.4xlarge) and a pair of cores (m5.4xlarge).
The next chart offers the question efficiency comparability utilizing completely different engines for the Hudi desk, that are unclustered, and for the Hudi desk, which is clustered.

We discovered that with clustering enabled for the Hudi desk, the question efficiency elevated for all three question engines, starting from 28% to 63%. The next desk offers the main points for the question efficiency for the Hudi desk, each with clustering enabled and disabled.
| Question Engine | Non-clustered Desk | Clustered Desk | Question Runtime Enchancment |
| Time (in seconds) | Time (in seconds) | ||
| Spark SQL | 21.6 | 15.4 | 28.7 % |
| Hive | 96.3 | 47 | 51.3 % |
| PrestoDB | 11.7 | 4.3 | 63.25 % |
Metadata-based file itemizing
Hudi write operations like compaction, cleansing, and international index, in addition to queries, carry out a file system itemizing to get the present view of the partitions and information within the dataset. For small datasets, this shouldn’t affect the efficiency drastically. Nevertheless, when working with giant knowledge, this itemizing operation can affect the efficiency negatively when studying the information. For instance, with HDFS because the underlying knowledge retailer, the checklist operation for a lot of information or partitions can overwhelm HDFS NameNode and have an effect on the soundness of job. In instances the place Amazon S3 is used because the underlying knowledge retailer, O(N) requires N partitions with a lot of information is time-consuming and can even lead to throttling errors.
With Apache Hudi model 0.7.0, you’ll be able to change this habits by enabling metadata-based itemizing for Hudi tables. This partitions and information checklist is saved in an inside metadata desk, which is carried out utilizing a Hudi Merge on Learn (MoR) desk. This metadata desk can take all some great benefits of the Hudi MoR desk, which incorporates the aptitude of low-latency updates, and the flexibility to atomically commit metadata updates and simply roll again if write fails. It additionally makes it simple to maintain metadata in sync with the Hudi desk as a result of each use a timeline for traceability. This index of the file checklist is saved utilizing HFiles for base and log file format for delta updates. The HFile format permits point-lookups of particular data primarily based on report key. The aim is to scale back O(N) checklist requires N partitions to O(1) get name to learn the metadata.
We in contrast question efficiency for a Hudi dataset with metadata itemizing enabled vs. not enabled. For this instance, we used a bigger dataset of three TB with Amazon EMR launch model 6.3.0. We used the next code snippet to create the metadata enabled and never enabled dataset by setting the HoodieMetadataConfig.METADATA_ENABLE_PROP (hoodie.metadata.allow) config:
On the question engine aspect, we are able to allow it through the next strategies:
- Spark knowledge supply:
- Spark SQL CLI:
- Hive:
- PrestoDB:
We used the next question to match question efficiency through Hive and PrestoDB:
The next chart offers the question efficiency comparability.

We discovered that with metadata itemizing, question execution runtime decreased by round 25% for the Hive engine, and by round 32% for PrestoDB. The next desk offers the main points of question execution runtime with and with out metadata itemizing.
| Question Engine | Metadata Disabled | Metadata Enabled | Question Runtime Enchancment |
| Time (in seconds) | Time (in seconds) | ||
| Hive | 415.28533 | 310.02367 | 25.35% |
| Presto | 72 | 48.6 | 32.50% |
Metadata itemizing issues
With Hudi 0.7.0 and 0.8.0, chances are you’ll not observe noticeable enhancements for queries through Spark SQL (with metadata itemizing), as a result of Hudi depends on Spark’s InMemoryFileIndex to do the precise file itemizing and may’t use the metadata. You might observe enhancements as a result of HoodieROPathFilter makes use of the metadata for its filtering. Nevertheless, with Hudi launch 0.9.0, we’re introducing a customized FileIndex implementation for Hudi to make use of metadata for file itemizing as a substitute of counting on Spark. Due to this fact, from 0.9.0, you’ll observe noticeable efficiency enhancements for Spark SQL queries.
Amazon CloudWatch integration
Apache Hudi offers MetricsReporter implementations like JmxMetricsReporter, MetricsGraphiteReporter, and DatadogMetricsReporter, which you should utilize to publish metrics to user-specified sinks. Amazon EMR, with its launch 6.4.0 having Hudi 0.8.0, has launched CloudWatchMetricsReporter, which you should utilize to publish these metrics to Amazon CloudWatch. It helps publish Hudi author metrics like commit length, rollback length, file-level metrics (variety of information added or deleted per commit), record-level metrics (data inserted or up to date per commit) and partition-level metrics (partitions inserted or up to date per commit). That is helpful in debugging Hudi jobs, in addition to making selections round cluster scaling.
You may allow the CloudWatch metric through the next configurations:
The next desk summarizes further configurations that you could change if wanted.
| Configuration | Description | Worth |
| hoodie.metrics.cloudwatch.report.interval.seconds | Frequency (in seconds) at which to report metrics to CloudWatch | Default worth is 60 seconds, which is ok for the default 1-minute decision supplied by CloudWatch |
| hoodie.metrics.cloudwatch.metric.prefix | Prefix to be added to every metric title | Default worth is empty (no prefix) |
| hoodie.metrics.cloudwatch.namespace | CloudWatch namespace underneath which metrics are printed | Default worth is Hudi |
| hoodie.metrics.cloudwatch.maxDatumsPerRequest | Most variety of datums to be included in a single request to CloudWatch | Default worth is 20, which is similar because the CloudWatch default |
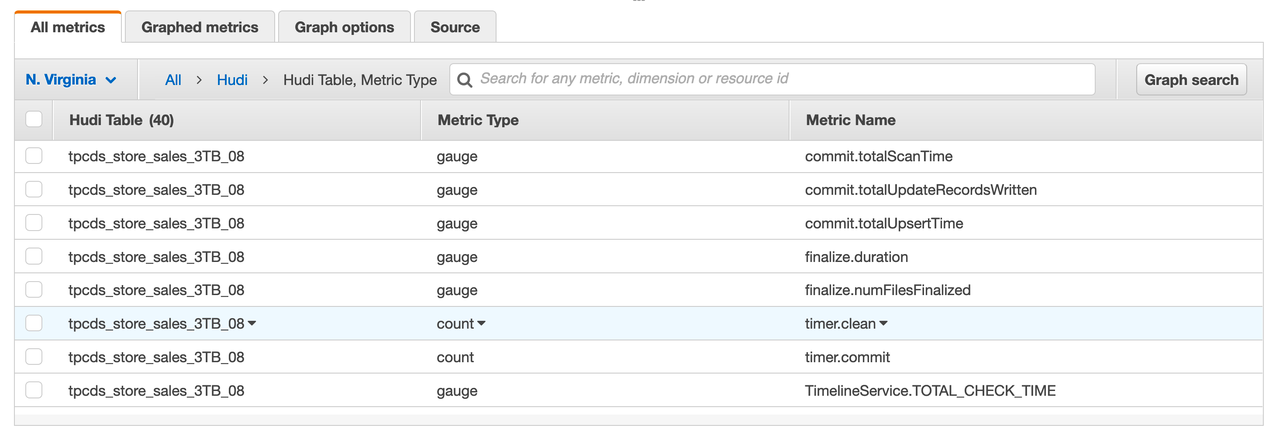
The next screenshot reveals among the metrics printed for a selected Hudi desk, together with the kind of metric and its title. These are dropwizard metrics; gauge represents the precise worth at a time limit, and counter represents a easy incrementing or decrementing integer.
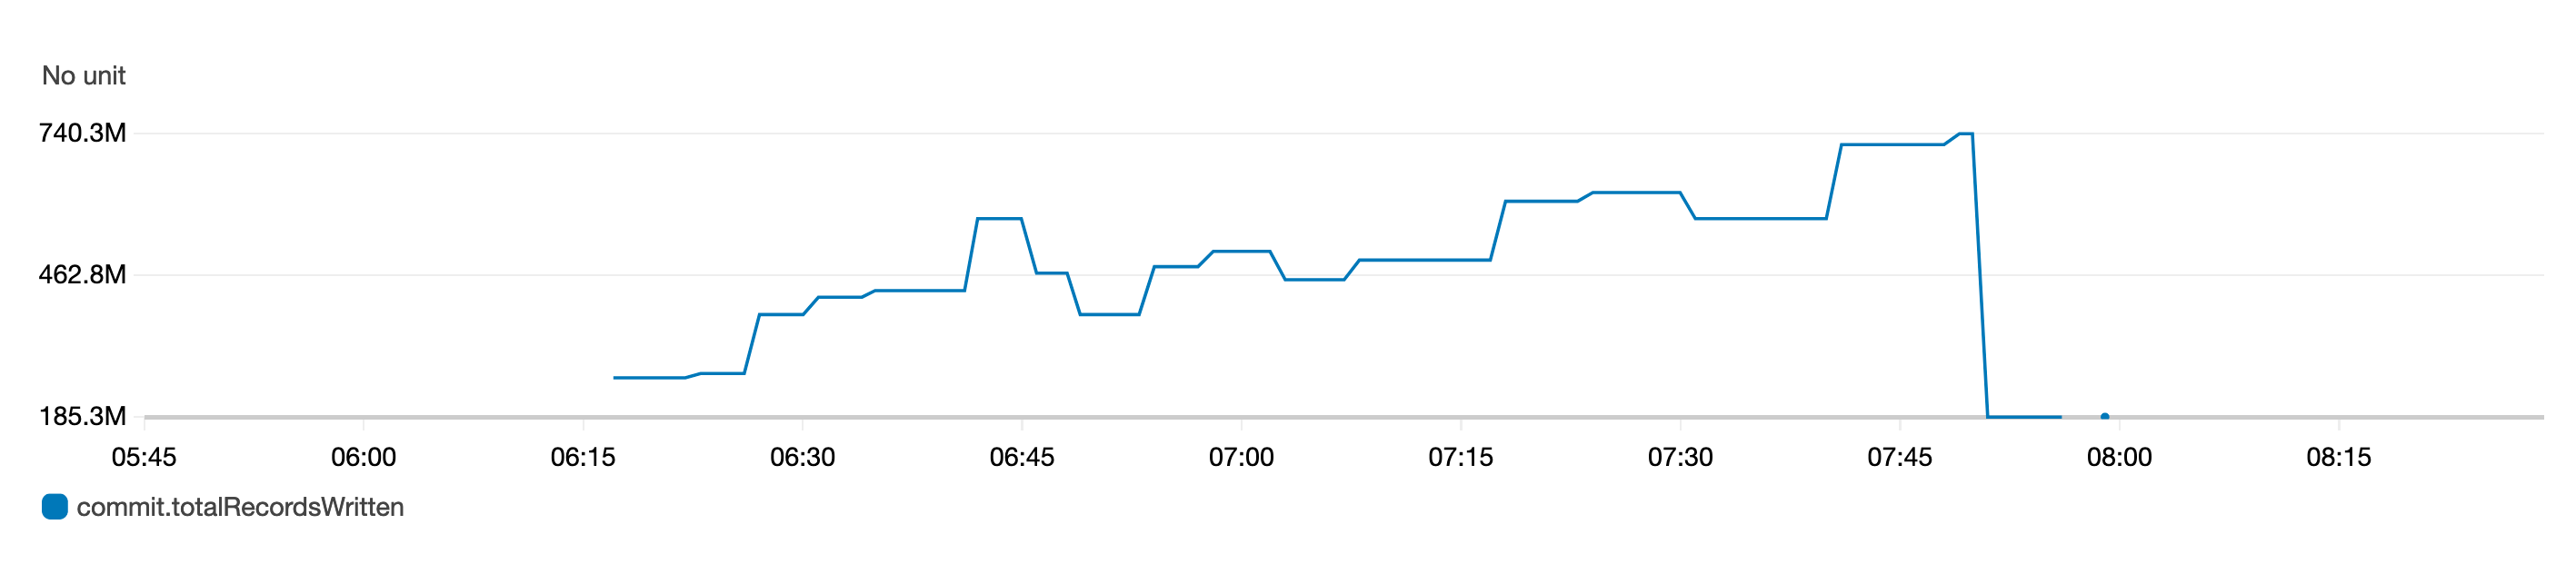
The next graph of the gauge metric represents the whole data written to a desk over time.
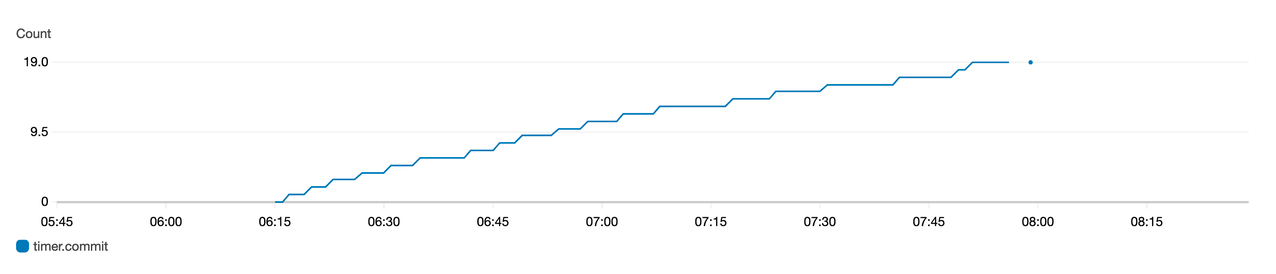
The next graph of the counter metric represents the variety of commits rising over time.
Optimistic Concurrency Management
A significant characteristic that has been launched with Hudi 0.8.0, and obtainable since Amazon EMR launch 6.4.0, is Optimistic Concurrency Management (OCC) to allow a number of writers to concurrently ingest knowledge into the identical Hudi desk. That is file-level OCC, which signifies that for any two commits (or writers) taking place to the identical desk on the similar time, each are allowed to succeed in the event that they don’t have writes to overlapping information. The characteristic requires buying locks, for which you should utilize both Zookeeper or HiveMetastore. For extra details about the ensures supplied, see Concurrency Management.
Amazon EMR clusters have Zookeeper put in, which you should utilize as a lock supplier to carry out concurrent writes from the identical cluster. To make it simpler to make use of, Amazon EMR preconfigures the lock supplier within the newly launched /and so on/hudi/conf/hudi-defaults.conf file (see the subsequent part) through the next properties:
Though the lock supplier is preconfigured, enabling of OCC nonetheless must be dealt with by the customers both through Hudi job choices or at cluster stage through the Amazon EMR Configurations API:
Amazon EMR configuration assist and enhancements
Amazon EMR launch 6.4.0 has launched the flexibility to configure and reconfigure Hudi through the configurations characteristic. Hudi configurations which are wanted throughout jobs and tables can now be configured at cluster stage through the hudi-defaults classification or /and so on/hudi/conf/hudi-defaults.conf file, just like different purposes like Spark and Hive. The next code is an instance of the hudi-defaults classification to allow metadata-based itemizing and CloudWatch metrics:
Amazon EMR routinely configures appropriate defaults for a couple of configs, to enhance the person expertise by eradicating the necessity for purchasers having to go them:
- HIVE_URL_OPT_KEY is configured to the cluster’s Hive server URL and not must be specified. That is notably helpful when operating a job in Spark cluster mode, the place customers beforehand needed to decide and themselves specify the Amazon EMR main IP.
- HBase particular configurations, that are helpful for utilizing HBase index with Hudi.
- Zookeeper lock supplier particular configuration, as mentioned underneath concurrency management, which makes it simpler to make use of OCC.
Extra modifications have been launched to scale back the variety of configurations that customers must go, and to deduce routinely the place doable:
Apache Flink integration
Apache Hudi began off with a really tight integration with Apache Spark. With launch model 0.7.0, we now have integrations obtainable to ingest knowledge utilizing Apache Flink. It required decoupling Spark from the inner desk format, writers, and desk companies code in a approach that can be utilized by different evolving engines within the trade like Flink.
Hudi 0.7.0 offers preliminary Flink assist through HooodieFlinkStreamer, which you should utilize to put in writing CoW tables by streaming knowledge from a Kafka matter utilizing Apache Flink. For instance, you should utilize the next Flink command to start out studying the subject ExampleTopic from the Kafka brokers broker-1, broker-2, and broker-3 operating on port 9092:
With Hudi 0.8.0, there have been main enhancements in Flink integration efficiency and scalability, in addition to the introduction of latest options like SQL connector for each supply and sink, author for MoR, batch reader for CoW and MoR, streaming reader for MoR, and state-backed indexing with bootstrap assist. For extra details about Flink integration design, see Apache Hudi meets Apache Flink. To get began with Flink SQL, see Flink Information.
Kafka commit callbacks
The earlier model (0.6.0) of Apache Hudi launched write commit callback performance. With this performance, Hudi can ship a callback message each time a profitable commit arrives to the Hudi dataset. The write commit callback supported HTTP methodology within the earlier launch. With Apache Hudi launch model 0.7.0, Hudi now helps write commit callback for Kafka as properly. Utilizing Kafka for sending the callback messages for each profitable commit can now allow you to construct asynchronous knowledge pipelines or enterprise processing logic each time the Hudi dataset sees a brand new commit. Now you can construct incremental ETL pipelines for processing new occasions that arrive within the Hudi knowledge lake.
The implementation of Kafka commit callback makes use of HoodieWriteCommitKafkaCallback because the hoodie.write.commit.callback.class. In addition to setting the commit callback class, you can too arrange further parameters for the Kafka bootstrap servers and the subject configurations.
The next is a code snippet the place commit callback messages are printed to the Kafka matter ExampleTopic hosted on the Kafka brokers b-1.demo-hudi.xxxxxx.xxx.kafka.us-east-1.amazonaws.com, b-2.demo-hudi.xxxxxx.xxx.kafka.us-east-1.amazonaws.com, and b-3.demo-hudi.xxxxxx.xxx.kafka.us-east-1.amazonaws.com when writing to a Hudi dataset:
The next is how the messages seem in your Kafka matter:
A downstream pipeline can now simply question these occasions from Kafka and course of the incremental knowledge into derived Hudi tables.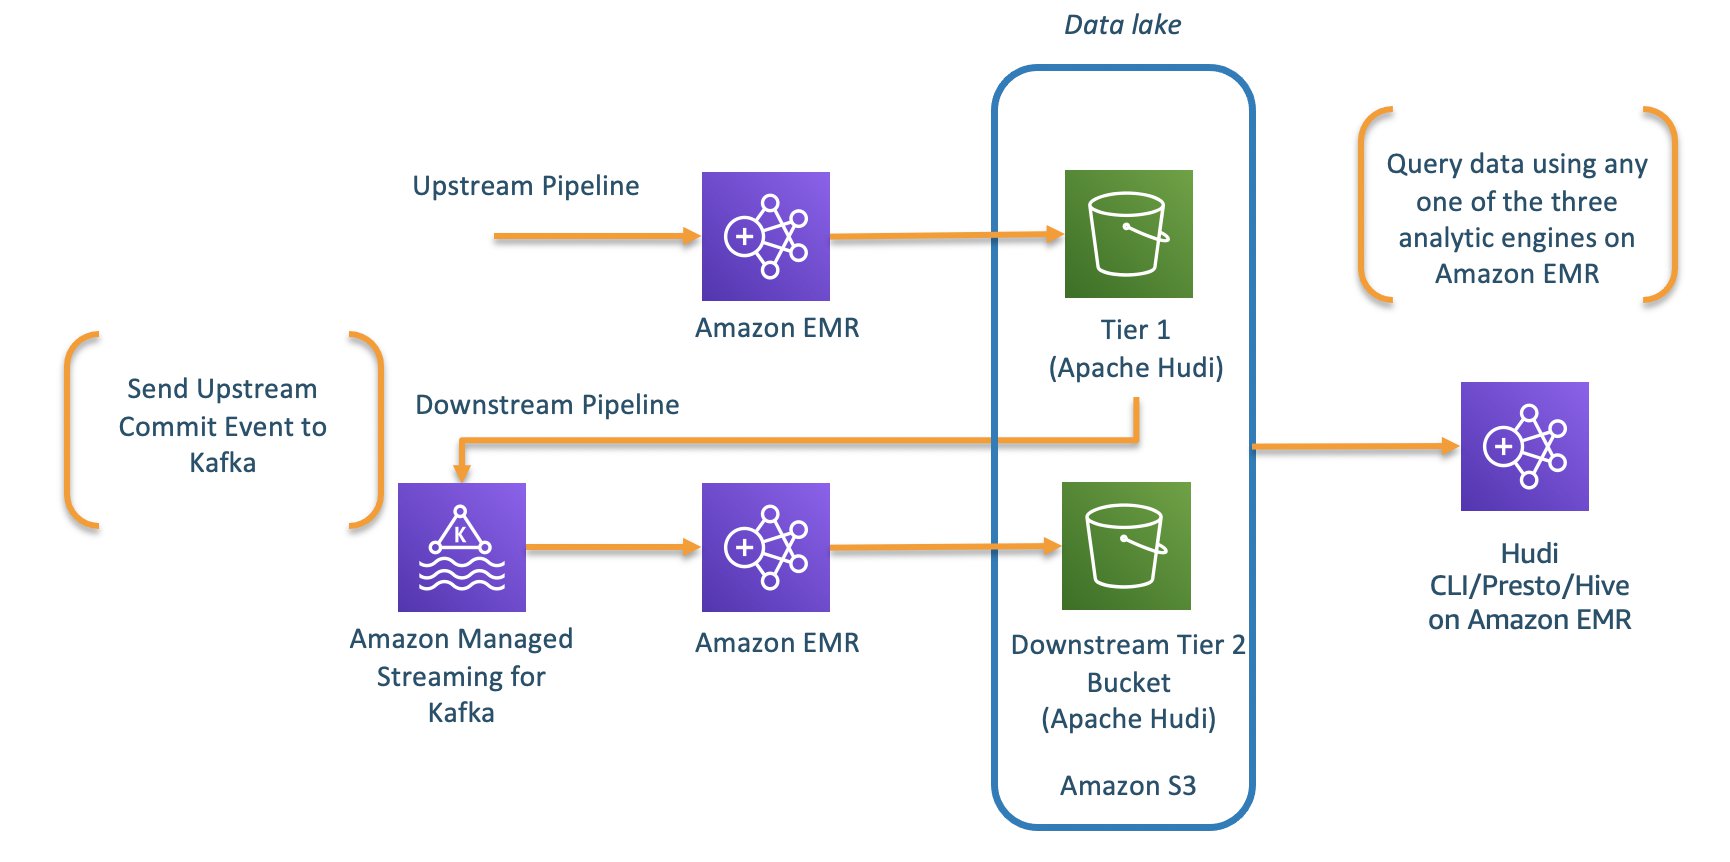
Different enhancements
In addition to the aforementioned enhancements, there have been some further modifications value mentioning. On the author aspect, there are the next enhancements:
- Assist for Spark 3 – Assist for writing and querying the information utilizing Apache Spark 3 is now obtainable with Apache Hudi 0.7.0 onwards. This works with Scala 2.12 bundle for
hudi-spark-bundle. - Insert overwrite and insert overwrite desk write operations – Apache Hudi 0.7.0 introduces two new operations,
insert_overwriteandinsert_overwrite_table, to assist batch ETL jobs the place a whole desk or partition is overwritten throughout every execution. You should utilize these operations as a substitute of theupsertoperation, and it’s should cheaper to run. - Delete partitions – The brand new API is now obtainable since 0.7.0 to delete a whole partition. This helps keep away from the usage of record-level deletes.
- Java author assist – Hudi 0.7.0 launched Java-based writing assist through the
HoodieJavaWriteClientclass.
Equally, on the question integration aspect, there have been the next enhancements:
- Structured streaming reads – Hudi 0.8.0 launched a Spark structured streaming supply implementation through the
HoodieStreamSourceclass. You should utilize it to assist streaming reads from Hudi tables. - Incremental question on MoR – Since Hudi 0.7.0, we now have incremental question assist for MoR tables, which you should utilize to incrementally pull knowledge by downstream purposes.
Conclusion
The brand new options launched in Apachi Hudi allow you to construct decoupled options by utilizing options like Kafka commit callback and Flink integration with Apache Hudi with Amazon EMR. You can too enhance your general efficiency of the Hudi knowledge lake by utilizing the capabilities of clustering and metadata tables.
In regards to the Authors
 Udit Mehrotra is a software program improvement engineer at Amazon Net Companies and an Apache Hudi PMC member/committer. He works on cutting-edge options of Amazon EMR and can also be concerned in open-source tasks reminiscent of Apache Hudi, Apache Spark, Apache Hadoop, and Apache Hive. In his spare time, he likes to play guitar, journey, binge watch, and hang around with mates.
 Gagan Brahmi is a Specialist Options Architect centered on Huge Knowledge & Analytics at Amazon Net Companies. Gagan has over 16 years of expertise in info expertise. He helps clients architect and construct extremely scalable, performant, and safe cloud-based options on AWS.
[ad_2]

