


[ad_1]
Immediately’s companies face an unprecedented progress within the quantity of information. A rising portion of the info is generated in actual time by IoT gadgets, web sites, enterprise purposes, and numerous different sources. Companies must course of and analyze this information as quickly because it arrives to make enterprise choices in actual time. Amazon Managed Streaming for Apache Kafka (Amazon MSK) is a totally managed service that allows constructing and operating stream processing purposes that use Apache Kafka to gather and course of information in actual time.
Stream processing purposes utilizing Apache Kafka don’t talk with one another immediately; they convey through sending and receiving messages over Kafka subjects. For stream processing purposes to speak effectively and confidently, a message payload construction should be outlined by way of attributes and information varieties. This construction describes the schema purposes use when sending and receiving messages. Nonetheless, with a lot of producer and shopper purposes, even a small change in schema (eradicating a discipline, including a brand new discipline, or change in information kind) could trigger points for downstream purposes which can be troublesome to debug and repair.
Historically, groups have relied on change administration processes (equivalent to approvals and upkeep home windows) or different casual mechanisms (documentation, emails, collaboration instruments, and so forth) to tell each other of information schema modifications. Nonetheless, these mechanisms don’t scale and are susceptible to errors. The AWS Glue Schema Registry means that you can centrally publish, uncover, management, validate, and evolve schemas for stream processing purposes. With the AWS Glue Schema Registry, you’ll be able to handle and implement schemas on information streaming purposes utilizing Apache Kafka, Amazon MSK, Amazon Kinesis Knowledge Streams, Amazon Kinesis Knowledge Analytics for Apache Flink, and AWS Lambda.
This publish demonstrates how Apache Kafka stream processing purposes validate messages utilizing an Apache Avro schema saved within the AWS Glue Schema registry residing in a central AWS account. We use the AWS Glue Schema Registry SerDe library and Avro SpecificRecord to validate messages in stream processing purposes whereas sending and receiving messages from a Kafka matter on an Amazon MSK cluster. Though we use an Avro schema for this publish, the identical method and idea applies to JSON schemas as nicely.
Use case
Let’s assume a fictitious rideshare firm that gives unicorn rides. To attract actionable insights, they should course of a stream of unicorn experience request messages. They count on rides to be highly regarded and need to be certain that their answer can scale. They’re additionally constructing a central information lake the place all their streaming and operation information is saved for evaluation. They’re buyer obsessed, in order that they count on so as to add new enjoyable options to future rides, like selecting the hair coloration of your unicorn, and might want to mirror these attributes within the experience request messages. To keep away from points in downstream purposes as a result of future schema modifications, they want a mechanism to validate messages with a schema hosted in a central schema registry. Having schemas in a central schema registry makes it simpler for the applying groups to publish, validate, evolve, and keep schemas in a single place.
Resolution overview
The corporate makes use of Amazon MSK to seize and distribute the unicorn experience request messages at scale. They outline an Avro schema for unicorn experience requests as a result of it gives wealthy information buildings, helps direct mapping to JSON, in addition to a compact, quick, and binary information format. As a result of the schema was agreed prematurely, they determined to make use of Avro SpecificRecord.SpecificRecord is an interface from the Avro library that enables the usage of an Avro document as a POJO. That is completed by producing a Java class (or lessons) from the schema, through the use of avro-maven-plugin. They use AWS Identification and Entry Administration (IAM) cross-account roles to permit producer and shopper purposes from the opposite AWS account to soundly and securely entry schemas within the central Schema Registry account.
The AWS Glue Schema Registry is in Account B, whereas the MSK cluster and Kafka producer and shopper purposes are in Account A. We use the next two IAM roles to allow cross-account entry to the AWS Glue Schema Registry. Apache Kafka shoppers in Account A assume a job in Account B utilizing an identity-based coverage as a result of the AWS Glue Schema Registry doesn’t help resource-based insurance policies.
- Account A IAM position – Permits producer and shopper purposes to imagine an IAM position in Account B.
- Account B IAM position – Trusts all IAM principals from Account A and permits them to carry out learn actions on the AWS Glue Schema Registry in Account B. In an actual use case state of affairs, IAM principals that may assume cross-account roles needs to be scoped extra particularly.
The next structure diagram illustrates the answer:

The answer works as follows:
- A Kafka producer operating in Account A assumes the cross-account Schema Registry IAM position in Account B by calling the AWS Safety Token Service (AWS STS)
assumeRoleAPI. - The Kafka producer retrieves the unicorn experience request Avro schema model ID from the AWS Glue Schema Registry for the schema that’s embedded within the unicorn experience request POJO. Fetching the schema model ID is internally managed by the AWS Glue Schema Registry SerDe’s serializer. The serializer must be configured as a part of the Kafka producer configuration.
- If the schema exists within the AWS Glue Schema Registry, the serializer decorates the info document with the schema model ID after which serializes it earlier than delivering it to the Kafka matter on the MSK cluster.
- The Kafka shopper operating in Account A assumes the cross-account Schema Registry IAM position in Account B by calling the AWS STS
assumeRoleAPI. - The Kafka shopper begins polling the Kafka matter on the MSK cluster for information information.
- The Kafka shopper retrieves the unicorn experience request Avro schema from the AWS Glue Schema Registry, matching the schema model ID that’s encoded within the unicorn experience request information document. Fetching the schema is internally managed by the AWS Glue Schema Registry SerDe’s deserializer. The deserializer must be configured as a part of the Kafka shopper configuration. If the schema exists within the AWS Glue Schema Registry, the deserializer deserializes the info document into the unicorn experience request POJO for the buyer to course of it.
The AWS Glue Schema Registry SerDe library additionally helps non-obligatory compression configuration to avoid wasting on information transfers. For extra details about the Schema Registry, see How the Schema Registry works.
Unicorn experience request Avro schema
The next schema (UnicornRideRequest.avsc) defines a document representing a unicorn experience request, which comprises experience request attributes together with the shopper attributes and system-recommended unicorn attributes:
Stipulations
To make use of this answer, you need to have two AWS accounts:
- Account A – For the MSK cluster, Kafka producer and shopper Amazon Elastic Compute Cloud (Amazon EC2) situations, and AWS Cloud9 atmosphere
- Account B – For the Schema Registry and schema
For this answer, we use Area us-east-1, however you’ll be able to change this as per your necessities.
Subsequent, we create the sources in every account utilizing AWS CloudFormation templates.
Create sources in Account B
We create the next sources in Account B:
- A schema registry
- An Avro schema
- An IAM position with the
AWSGlueSchemaRegistryReadonlyAccessmanaged coverage and an occasion profile, which permits all Account A IAM principals to imagine it - The
UnicornRideRequest.avscAvro schema proven earlier, which is used as a schema definition within the CloudFormation template
Ensure you have the suitable permissions to create these sources.
- Log in to Account B.
- Launch the next CloudFormation stack.
- For Stack identify, enter
SchemaRegistryStack. - For Schema Registry identify, enter
unicorn-ride-request-registry. - For Avro Schema identify, enter
unicorn-ride-request-schema-avro. - For the Kafka shopper’s AWS account ID, enter your Account A ID.
- For ExternalId, enter a singular random ID (for instance,
demo10A), which needs to be offered by the Kafka shoppers in Account Some time assuming the IAM position on this account.
For extra details about cross-account safety, see The confused deputy drawback.
- When the stack is full, on the Outputs tab of the stack, copy the worth for
CrossAccountGlueSchemaRegistryRoleArn.
The Kafka producer and shopper purposes created in Account A assume this position to entry the Schema Registry and schema in Account B.
- To confirm the sources had been created, on the AWS Glue console, select Schema registries within the navigation bar, and find
unicorn-ride-request-registry.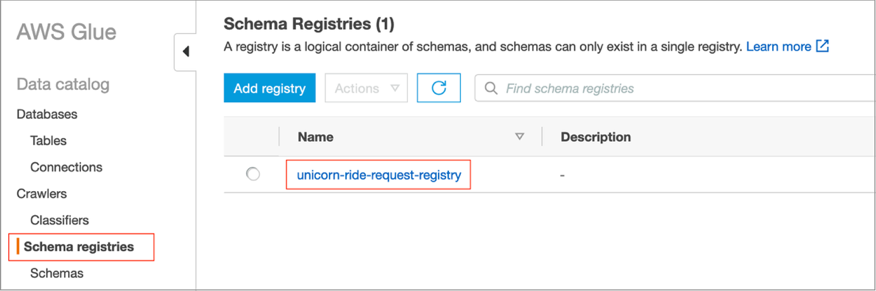
- Select the registry
unicorn-ride-request-registryand confirm that it comprisesunicorn-ride-request-schema-avrowithin the Schemas part. - Select the schema to see its content material.

The IAM position created by the SchemaRegistryStack stack permits all Account A IAM principals to imagine it and carry out learn actions on the AWS Glue Schema Registry. Let’s have a look at the belief relationships of the IAM position.
- On the
SchemaRegistryStackstack Outputs tab, copy the worth forCrossAccountGlueSchemaRegistryRoleName. - On the IAM console, seek for this position.
- Select Belief relationships and have a look at its trusted entities to verify that Account A is listed.
- Within the Circumstances part, verify that
sts:ExternalIdhas the identical distinctive random ID offered throughout stack creation.
Create sources in Account A
We create the next sources in Account A:
- A VPC
- EC2 situations for the Kafka producer and shopper
- An AWS Cloud9 atmosphere
- An MSK cluster
As a prerequisite, create an EC2 keypair and obtain it in your machine to have the ability to SSH into EC2 situations. Additionally create an MSK cluster configuration with default values. It is advisable have permissions to create the CloudFormation stack, EC2 situations, AWS Cloud9 atmosphere, MSK cluster, MSK cluster configuration, and IAM position.
- Log in to Account A.
- Launch the next CloudFormation stack to launch the VPC, EC2 situations, and AWS Cloud9 atmosphere.
- For Stack identify, enter
MSKClientStack. - Present the VPC and subnet CIDR ranges.
- For EC2 Keypair, select an present EC2 keypair.
- For the newest EC2 AMI ID, choose the default choice.
- For the cross-account IAM position ARN, use the worth for
CrossAccountGlueSchemaRegistryRoleArn(out there on the Outputs tab ofSchemaRegistryStack). - Await the stack to create efficiently.
- Launch the next CloudFormation stack to create the MSK cluster.
- For Stack identify, enter
MSKClusterStack. - Use Amazon MSK model 2.7.1.
- For the MSK cluster configuration ARN, enter the MSK cluster configuration ARN. One that you simply created as a part of the prerequisite.
- For the MSK cluster configuration revision quantity, enter 1 or change it in keeping with your model.
- For the shopper CloudFormation stack identify, enter
MSKClientStack(the stack identify that you simply created previous to this stack).
Configure the Kafka producer
To configure the Kafka producer accessing the Schema Registry within the central AWS account, full the next steps:
- Log in to Account A.
- On the AWS Cloud9 console, select the
Cloud9EC2Bastionatmosphere created by theMSKClientStackstack. - On the File menu, select Add Native Recordsdata.
- Add the EC2 keypair file that you simply used earlier whereas creating the stack.

- Open a brand new terminal and alter the EC2 keypair permissions:
- SSH into the
KafkaProducerInstanceEC2 occasion and set the Area as per your requirement: - Set the atmosphere variable
MSK_CLUSTER_ARNpointing to the MSK cluster’s ARN:
Change the .ClusterName worth within the code in case you used a unique identify for the MSK cluster CloudFormation stack. The cluster identify is identical because the stack identify.
- Set the atmosphere variable
BOOTSTRAP_BROKERSpointing to the bootstrap brokers: - Confirm the atmosphere variables:
- Create a Kafka matter referred to as
unicorn-ride-request-topicin your MSK cluster, which is utilized by the Kafka producer and shopper purposes later:
The MSKClientStack stack copied the Kafka producer shopper JAR file referred to as kafka-cross-account-gsr-producer.jar to the KafkaProducerInstance occasion. It comprises the Kafka producer shopper that sends messages to the Kafka matter unicorn-ride-request-topic on the MSK cluster and accesses the unicorn-ride-request-schema-avro Avro schema from the unicorn-ride-request-registry schema registry in Account B. The Kafka producer code, which we cowl later on this publish, is offered on GitHub.
- Run the next instructions and confirm
kafka-cross-account-gsr-producer.jarexists: - Run the next command to run the Kafka producer within the
KafkaProducerInstanceterminal:
The code has the next parameters:
- -bs –
$BOOTSTRAP_BROKERS(the MSK cluster bootstrap brokers) - -rn – The
CrossAccountGlueSchemaRegistryRoleArnworth from theSchemaRegistryStackstack outputs in Account B - -topic – the Kafka matter
unicorn-ride-request-topic - -reg –
us-east-1(change it in keeping with your Area, it’s used for the AWS STS endpoint and Schema Registry) - -nm:
500(the variety of messages the producer software sends to the Kafka matter) - -externalId – The identical exterior ID (for instance,
demo10A) that you simply used whereas creating the CloudFormation stack in Account B
The next screenshot reveals the Kafka producer logs exhibiting Schema Model Id obtained..., which suggests it has retrieved the Avro schema unicorn-ride-request-schema-avro from Account B and messages had been despatched to the Kafka matter on the MSK cluster in Account A.

Kafka producer code
The whole Kafka producer implementation is offered on GitHub. On this part, we break down the code.
getProducerConfig()initializes the producer properties, as proven within the following code:- VALUE_SERIALIZER_CLASS_CONFIG – The
GlueSchemaRegistryKafkaSerializer.class.getName()AWS serializer implementation that serializes information information (the implementation is offered on GitHub) - REGISTRY_NAME – The Schema Registry from Account B
- SCHEMA_NAME – The schema identify from Account B
- AVRO_RECORD_TYPE –
AvroRecordType.SPECIFIC_RECORD
- VALUE_SERIALIZER_CLASS_CONFIG – The
startProducer()assumes the position in Account B to have the ability to join with the Schema Registry in Account B and sends messages to the Kafka matter on the MSK cluster:
assumeGlueSchemaRegistryRole()as proven within the following code makes use of AWS STS to imagine the cross-account Schema Registry IAM position in Account B. (For extra info, see Momentary safety credentials in IAM.) The response fromstsClient.assumeRole(roleRequest)comprises the non permanent credentials, which embraceaccessKeyId,secretAccessKey, and asessionToken. It then units the non permanent credentials within the system properties. The AWS SDK for Java makes use of these credentials whereas accessing the Schema Registry (by the Schema Registry serializer). For extra info, see Utilizing Credentials.createUnicornRideRequest()makes use of the Avro schema (unicorn experience request schema) generated lessons to create aSpecificRecord. For this publish, the unicorn experience request attributes values are hard-coded on this methodology. See the next code:
Configure the Kafka shopper
The MSKClientStack stack created the KafkaConsumerInstance occasion for the Kafka shopper software. You possibly can view all of the situations created by the stack on the Amazon EC2 console.
To configure the Kafka shopper accessing the Schema Registry within the central AWS account, full the next steps:
- Open a brand new terminal within the
Cloud9EC2BastionAWS Cloud9 atmosphere.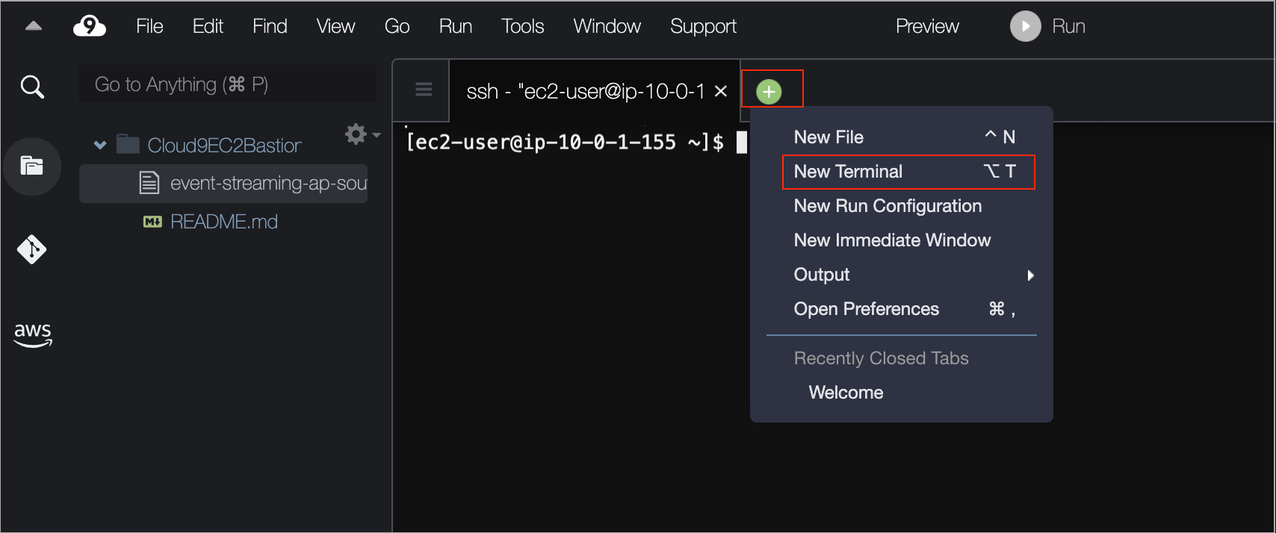
- SSH into the
KafkaConsumerInstanceEC2 occasion and set the Area as per your requirement: - Set the atmosphere variable
MSK_CLUSTER_ARNpointing to the MSK cluster’s ARN:
Change the .ClusterName worth in case you used a unique identify for the MSK cluster CloudFormation stack. The cluster identify is identical because the stack identify.
- Set the atmosphere variable
BOOTSTRAP_BROKERSpointing to the bootstrap brokers: - Confirm the atmosphere variables:
The MSKClientStack stack copied the Kafka shopper shopper JAR file referred to as kafka-cross-account-gsr-consumer.jar to the KafkaConsumerInstance occasion. It comprises the Kafka shopper shopper that reads messages from the Kafka matter unicorn-ride-request-topic on the MSK cluster and accesses the unicorn-ride-request-schema-avro Avro schema from the unicorn-ride-request-registry registry in Account B. The Kafka shopper code, which we cowl later on this publish, is offered on GitHub.
- Run the next instructions and confirm
kafka-cross-account-gsr-consumer.jarexists: - Run the next command to run the Kafka shopper within the
KafkaConsumerInstanceterminal:
The code has the next parameters:
- -bs –
$BOOTSTRAP_BROKERS(the MSK cluster bootstrap brokers) - -rn – The
CrossAccountGlueSchemaRegistryRoleArnworth from theSchemaRegistryStackstack outputs in Account B - -topic – The Kafka matter
unicorn-ride-request-topic - -reg –
us-east-1(change it in keeping with your Area, it’s used for the AWS STS endpoint and Schema Registry) - -externalId – The identical exterior ID (for instance,
demo10A) that you simply used whereas creating the CloudFormation stack in Account B
The next screenshot reveals the Kafka shopper logs efficiently studying messages from the Kafka matter on the MSK cluster in Account A and accessing the Avro schema unicorn-ride-request-schema-avro from the unicorn-ride-request-registry schema registry in Account B.
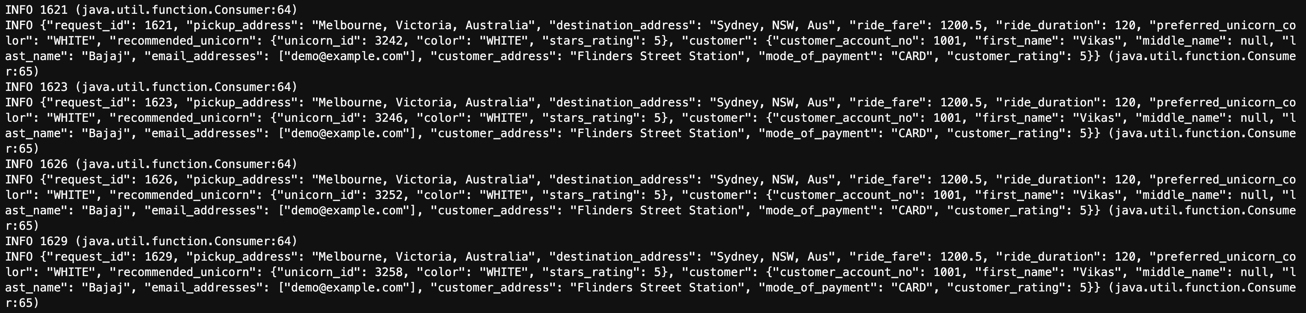
If you happen to see the same logs, it means each the Kafka shopper purposes have been in a position to join efficiently with the centralized Schema Registry in Account B and are in a position to validate messages whereas sending and consuming messages from the MSK cluster in Account A.
Kafka shopper code
The whole Kafka shopper implementation is offered on GitHub. On this part, we break down the code.
getConsumerConfig()initializes shopper properties, as proven within the following code:- VALUE_DESERIALIZER_CLASS_CONFIG – The
GlueSchemaRegistryKafkaDeserializer.class.getName()AWS deserializer implementation that deserializes theSpecificRecordas per the encoded schema ID from the Schema Registry (the implementation is offered on GitHub). - AVRO_RECORD_TYPE –
AvroRecordType.SPECIFIC_RECORD
- VALUE_DESERIALIZER_CLASS_CONFIG – The
startConsumer()assumes the position in Account B to have the ability to join with the Schema Registry in Account B and reads messages from the Kafka matter on the MSK cluster:
assumeGlueSchemaRegistryRole()as proven within the following code makes use of AWS STS to imagine the cross-account Schema Registry IAM position in Account B. The response fromstsClient.assumeRole(roleRequest)comprises the non permanent credentials, which embraceaccessKeyId,secretAccessKey, and asessionToken. It then units the non permanent credentials within the system properties. The SDK for Java makes use of these credentials whereas accessing the Schema Registry (by the Schema Registry serializer). For extra info, see Utilizing Credentials.
Compile and generate Avro schema lessons
Like every other a part of constructing and deploying your software, schema compilation and the method of producing Avro schema lessons needs to be included in your CI/CD pipeline. There are a number of methods to generate Avro schema lessons; we use avro-maven-plugin for this publish. The CI/CD course of also can use avro-tools to compile Avro schema to generate lessons. The next code is an instance of how you should utilize avro-tools:
Implementation overview
To recap, we begin with defining and registering an Avro schema for the unicorn experience request message within the AWS Glue Schema Registry in Account B, the central information lake account. In Account A, we create an MSK cluster and Kafka producer and shopper EC2 situations with their respective software code (kafka-cross-account-gsr-consumer.jar and kafka-cross-account-gsr-producer.jar) and deployed in them utilizing the CloudFormation stack.
Once we run the producer software in Account A, the serializer (GlueSchemaRegistryKafkaSerializer) from the AWS Glue Schema Registry SerDe library offered because the configuration will get the unicorn experience request schema (UnicornRideRequest.avsc) from the central Schema Registry residing in Account B to serialize the unicorn experience request message. It makes use of the IAM position (non permanent credentials) in Account B and Area, schema registry identify (unicorn-ride-request-registry), and schema identify (unicorn-ride-request-schema-avro) offered because the configuration to connect with the central Schema Registry. After the message is efficiently serialized, the producer software sends it to the Kafka matter (unicorn-ride-request-topic) on the MSK cluster.
Once we run the buyer software in Account A, the deserializer (GlueSchemaRegistryKafkaDeserializer) from the Schema Registry SerDe library offered because the configuration extracts the encoded schema ID from the message learn from the Kafka matter (unicorn-ride-request-topic) and will get the schema for a similar ID from the central Schema Registry in Account B. It then deserializes the message. It makes use of the IAM position (non permanent credentials) in Account B and the Area offered because the configuration to connect with the central Schema Registry. The buyer software additionally configures Avro’s SPECIFIC_RECORD to tell the deserializer that the message is of a particular kind (unicorn experience request). After the message is efficiently deserialized, the buyer software processes it as per the necessities.
Clear up
The ultimate step is to wash up. To keep away from pointless costs, it’s best to take away all of the sources created by the CloudFormation stacks used for this publish. The only method to take action is to delete the stacks. First delete the MSKClusterStack adopted by MSKClientStack from Account A. Then delete the SchemaRegistryStack from Account B.
Conclusion
On this publish, we demonstrated methods to use AWS Glue Schema Registry with Amazon MSK and stream processing purposes to validate messages utilizing an Avro schema. We created a distributed structure the place the Schema Registry resides in a central AWS account (information lake account) and Kafka producer and shopper purposes reside in a separate AWS account. We created an Avro schema within the schema registry within the central account to make it environment friendly for the applying groups to take care of schemas in a single place. As a result of AWS Glue Schema Registry helps identity-based entry insurance policies, we used the cross-account IAM position to permit the Kafka producer and shopper purposes operating in a separate account to securely entry the schema from the central account to validate messages. As a result of the Avro schema was agreed prematurely, we used Avro SpecificRecord to make sure kind security at compile time and keep away from runtime schema validation points on the shopper aspect. The code used for this publish is offered on GitHub for reference.
To be taught extra concerning the companies and sources on this answer, check with AWS Glue Schema Registry, the Amazon MSK Developer Information, the AWS Glue Schema Registry SerDe library, and IAM tutorial: Delegate entry throughout AWS accounts utilizing IAM roles.
In regards to the Creator
 Vikas Bajaj is a Principal Options Architect at Amazon Net Service. Vikas works with digital native clients and advises them on know-how structure and modeling, and choices and options to satisfy strategic enterprise targets. He makes positive designs and options are environment friendly, sustainable, and fit-for-purpose for present and future enterprise wants. Other than structure and know-how discussions, he enjoys watching and enjoying cricket.
[ad_2]

