


[ad_1]
This can be a collaborative put up from Databricks and Hightouch. We thank Luke Kline, Product Evangelist at Hightouch, for his contributions.
You completed organising your information lakehouse on Databricks. You might have a centralized location the place you may carry out all types of analytics, machine studying, synthetic intelligence, and enterprise intelligence.
Your information engineers are excited as a result of they will lastly begin tackling your entire streaming use instances, and your information scientists can begin focusing in your information science and machine studying use instances. Your information engineers are in a position to leverage this data to construct related information fashions to energy what you are promoting, and your information analysts are thrilled as a result of they now have the flexibility to run fast ad-hoc queries at a second’s discover.
As information resides in Databricks, Hightouch allows Reverse ETL, the place the info will be moved into operational programs like promoting, advertising and marketing, success, and different enterprise platforms to increase the worth of analytics on the lakehouse. Hightouch might help open up the worth of all these analytics to what you are promoting groups that want entry to the distinctive buyer information that exists inside the lakehouse:
- Information fashions: (subscription sort, LTV, ARR, product certified lead, content material watched, and so forth.)
- Product utilization information: (messages despatched, final login, workspaces created, new customers, and so forth.)
- Occasion information: (pages seen, session size, buying cart abandonment, objects in cart, and so forth.)
Transferring this information out of Databricks is now very easy. You don’t should construct a customized information pipeline for probably dozens of locations (advertisements, advertising and marketing, CRM, buyer success, ERP, and so forth). Hightouch offers a platform and programmatic strategy to make sure your information is within the correct format to be ingested.
The upkeep of those pipelines is now equally as environment friendly as a result of Hightouch takes care of managing continually altering APIs of upstream or downstream programs. On prime of this, Hightouch offers straightforward methods to handle information high quality with reside debugging and model management.
You not have to keep up labor-intensive pipelines in-house. Hightouch on Databricks is a good answer for Reverse ETL to get information into the arms of enterprise customers, the place it may be actioned and produce speedy affect to what you are promoting.
The answer: Reverse ETL
Reverse ETL is the method of shifting your remodeled information again into the instruments that run enterprise processes. Normally, locations include SaaS instruments used for development, advertising and marketing, gross sales, and assist. As a substitute of utilizing dashboards to make selections, Reverse ETL shifts the main target to placing your datasets to work by means of Operational Analytics – turning insights into motion routinely.
In case your greatest information solely exists in Databricks, what you are promoting groups are counting on generic data to energy their day-to-day actions. This might be one thing so simple as supplying your gross sales crew with up to date product utilization for brand new leads, sharing a brand new viewers along with your advertising and marketing crew for advert retargeting, serving to your buyer success crew determine, which assist tickets must be prioritized or notifying members of your crew when a particular occasion takes place in your app.
You’ll be able to in all probability consider a number of examples of knowledge that will be higher served elsewhere inside what you are promoting. There are lots of use instances that Hightouch can clear up with Reverse ETL, and you’ll quickly see why tech-first firms like Nauto are utilizing Hightouch to supercharge Databricks.
get began syncing information with Hightouch
Notice: Hightouch by no means shops your information, so that you don’t have to fret about compliance.
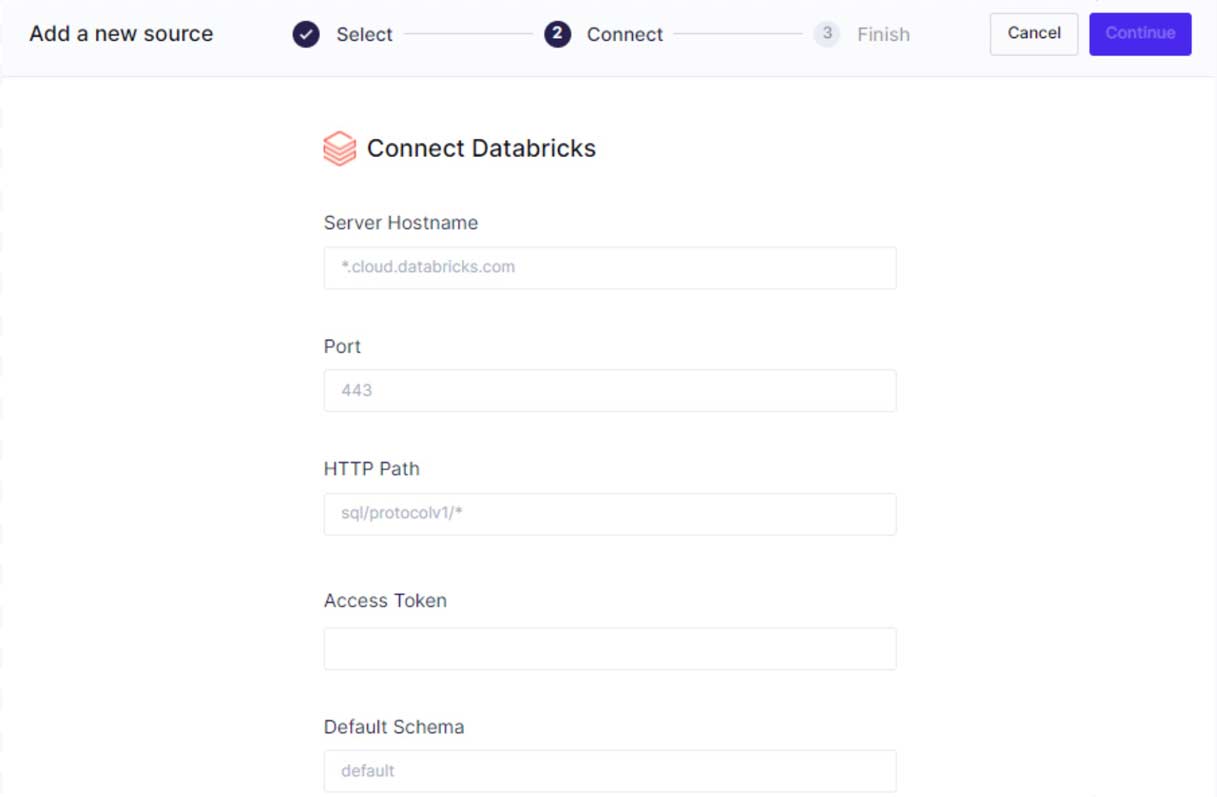
Step 1: Join Hightouch to Databricks.
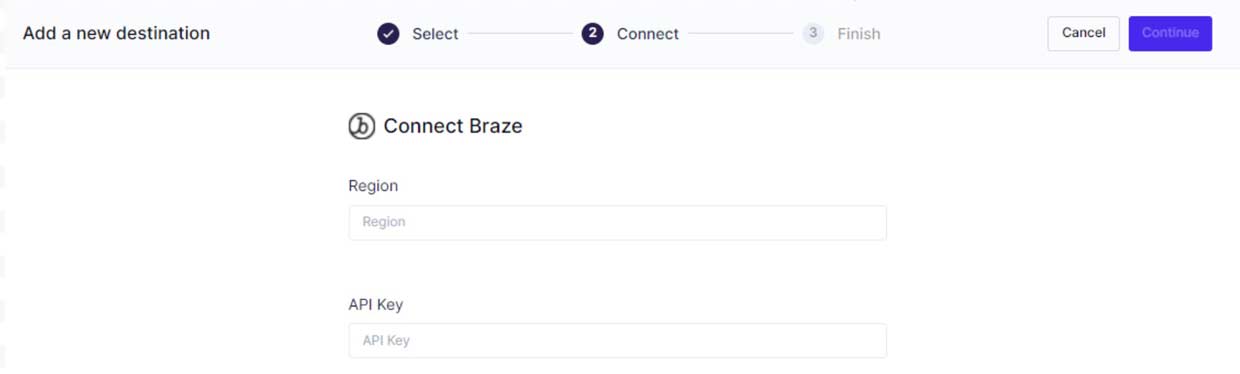
Step 2: Join Hightouch to your vacation spot.
Step 3: Create a knowledge mannequin or leverage an present one.

Step 4: Select your main key.
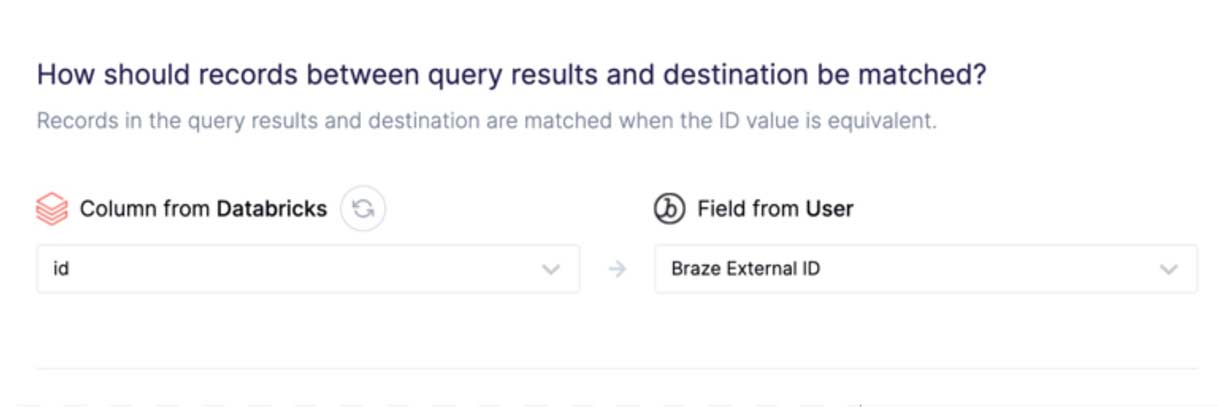
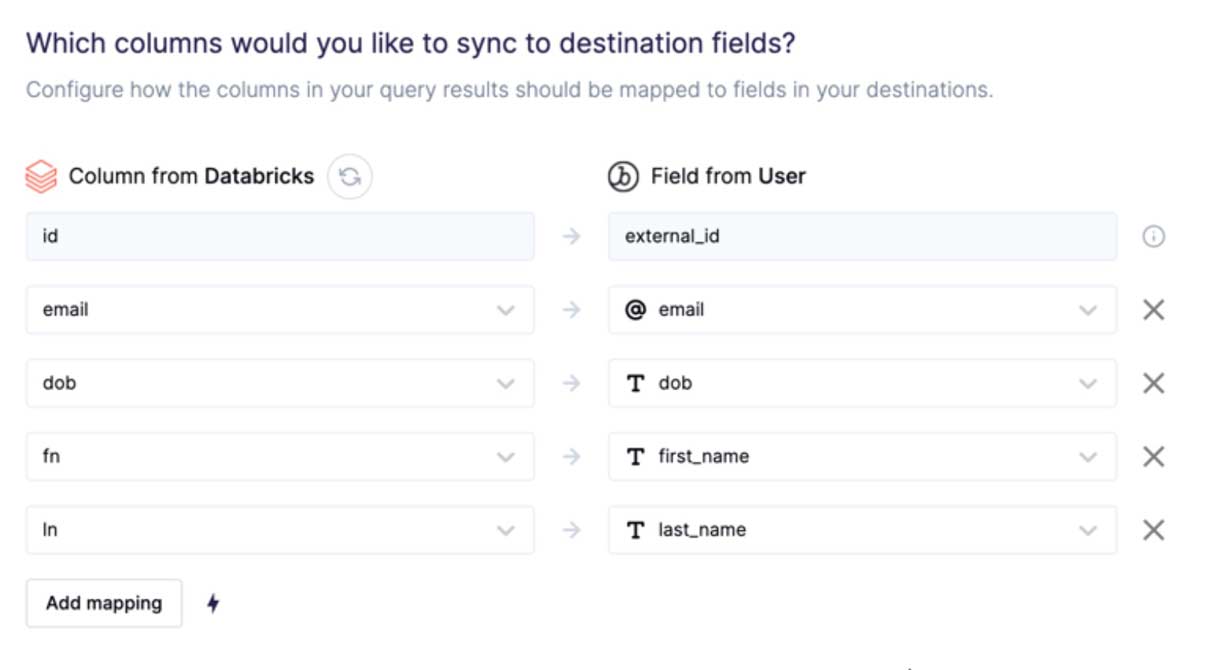
Step 5: Create your sync and map your Databricks columns to your finish vacation spot fields.
Step 6: Schedule your sync.

Getting began with Databricks and Hightouch
Go to Databricks docs for extra details about find out how to begin sending information from Databricks to Hightouch. You’ll be able to check the combination on Databricks without spending a dime by signing up for a 14-day free trial. If you wish to study extra about Reverse ETL, obtain Hightouch’s information. The primary integration with Hightouch is free so you may check it your self or e book a demo right here.
[ad_2]

