



[ad_1]
Log information have been receiving growing recognition from technical SEOs over the previous 5 years, and for a superb cause.
They’re probably the most reliable supply of knowledge to grasp the URLs that engines like google have crawled, which might be essential data to assist diagnose issues with technical search engine optimization.
Google itself acknowledges their significance, releasing new options in Google Search Console and making it straightforward to see samples of knowledge that might beforehand solely be accessible by analyzing logs.
As well as, Google Search Advocate John Mueller has publicly said how a lot good data log information maintain.
@glenngabe Log information are so underrated, a lot good data in them.
— 🦝 John (private) 🦝 (@JohnMu) April 5, 2016
With all this hype across the knowledge in log information, you might need to perceive logs higher, learn how to analyze them, and whether or not the websites you’re engaged on will profit from them.
This text will reply all of that and extra. Right here’s what we’ll be discussing:
A server log file is a file created and up to date by a server that information the actions it has carried out. A preferred server log file is an entry log file, which holds a historical past of HTTP requests to the server (by each customers and bots).
When a non-developer mentions a log file, entry logs are those they’ll often be referring to.
Builders, nonetheless, discover themselves spending extra time taking a look at error logs, which report points encountered by the server.
The above is essential: In the event you request logs from a developer, the very first thing they’ll ask is, “Which of them?”
Subsequently, all the time be particular with log file requests. If you need logs to investigate crawling, ask for entry logs.
Entry log information include a number of details about every request made to the server, comparable to the next:
- IP addresses
- Consumer brokers
- URL path
- Timestamps (when the bot/browser made the request)
- Request kind (GET or POST)
- HTTP standing codes
What servers embrace in entry logs varies by the server kind and typically what builders have configured the server to retailer in log information. Frequent codecs for log information embrace the next:
- Apache format – That is utilized by Nginx and Apache servers.
- W3C format – That is utilized by Microsoft IIS servers.
- ELB format – That is utilized by Amazon Elastic Load Balancing.
- Customized codecs – Many servers assist outputting a customized log format.
Different varieties exist, however these are the principle ones you’ll encounter.
Now that we’ve acquired a primary understanding of log information, let’s see how they profit search engine optimization.
Listed below are some key methods:
- Crawl monitoring – You may see the URLs engines like google crawl and use this to identify crawler traps, look out for crawl finances wastage, or higher perceive how rapidly content material adjustments are picked up.
- Standing code reporting – That is notably helpful for prioritizing fixing errors. Fairly than realizing you’ve acquired a 404, you’ll be able to see exactly what number of instances a consumer/search engine is visiting the 404 URL.
- Developments evaluation – By monitoring crawling over time to a URL, web page kind/website part, or your complete website, you’ll be able to spot adjustments and examine potential causes.
- Orphan web page discovery – You may cross-analyze knowledge from log information and a website crawl you run your self to find orphan pages.
All websites will profit from log file evaluation to some extent, however the quantity of profit varies massively relying on website measurement.
That is as log information primarily profit websites by serving to you higher handle crawling. Google itself states managing the crawl finances is one thing larger-scale or incessantly altering websites will profit from.
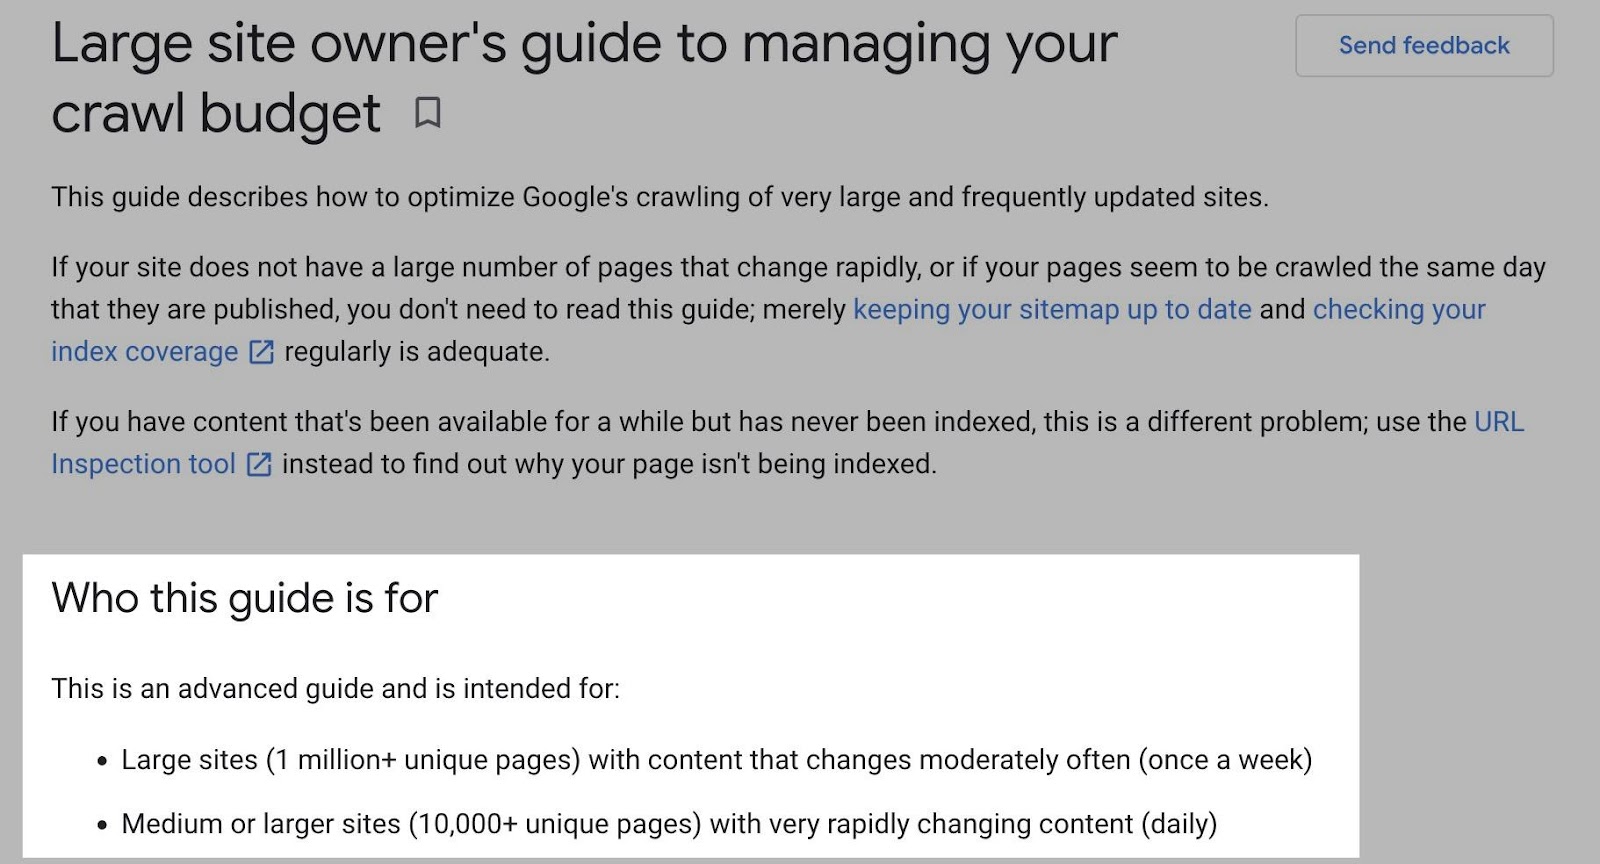
The identical is true for log file evaluation.
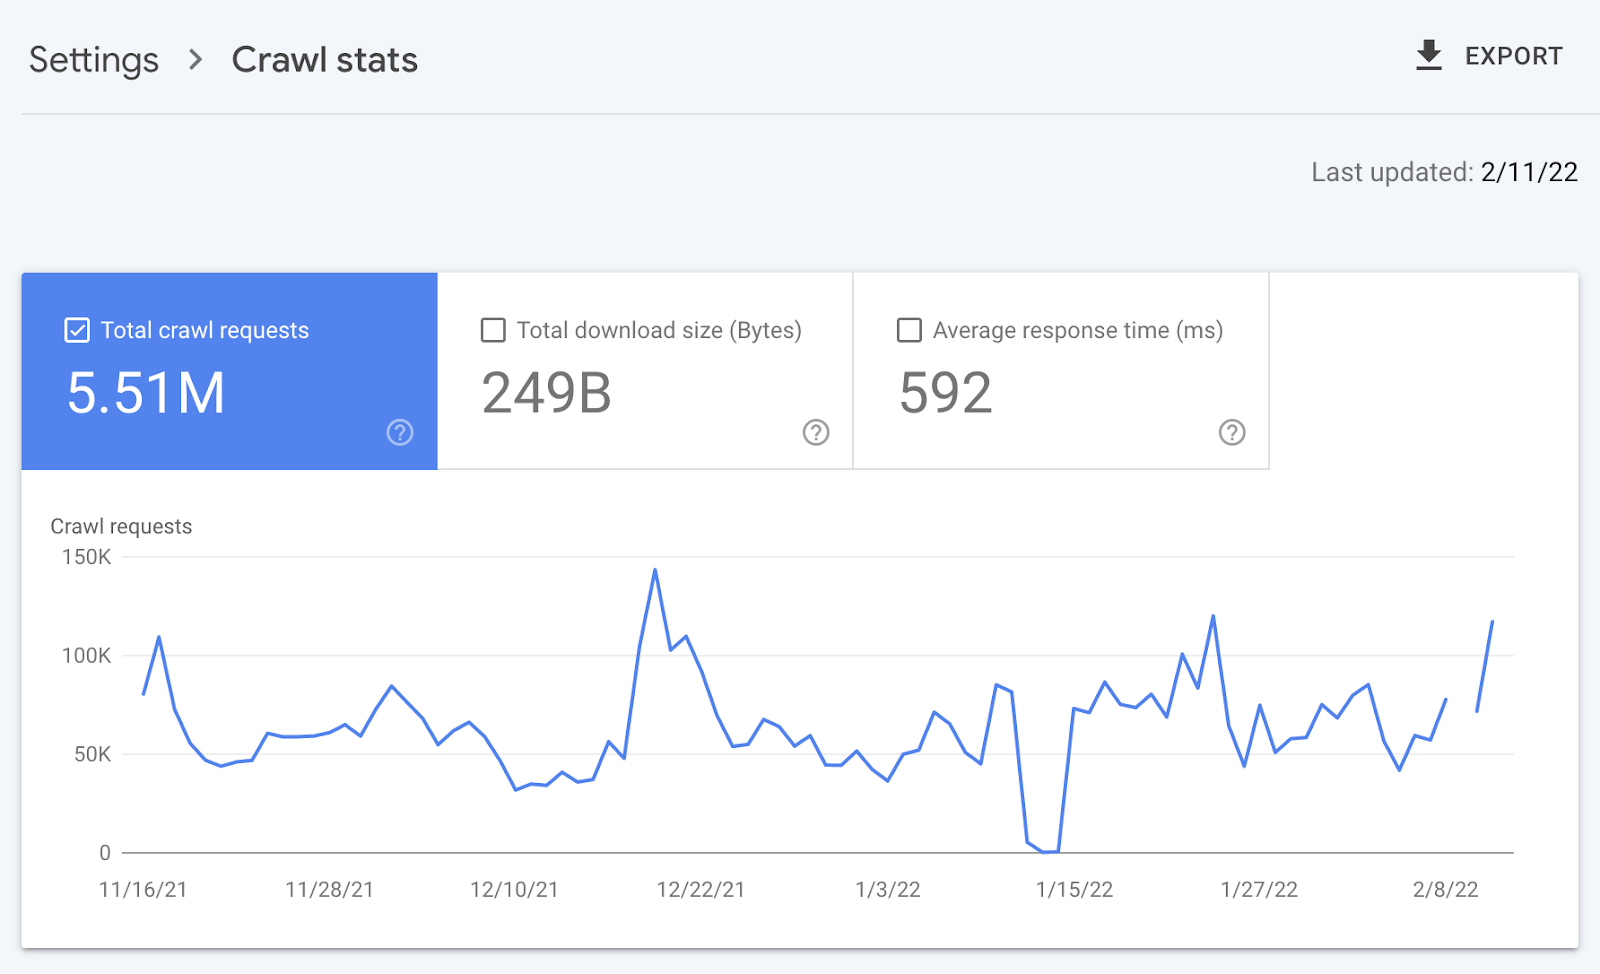
For instance, smaller websites can probably use the “Crawl stats” knowledge supplied in Google Search Console and obtain all the advantages talked about above—with out ever needing to the touch a log file.
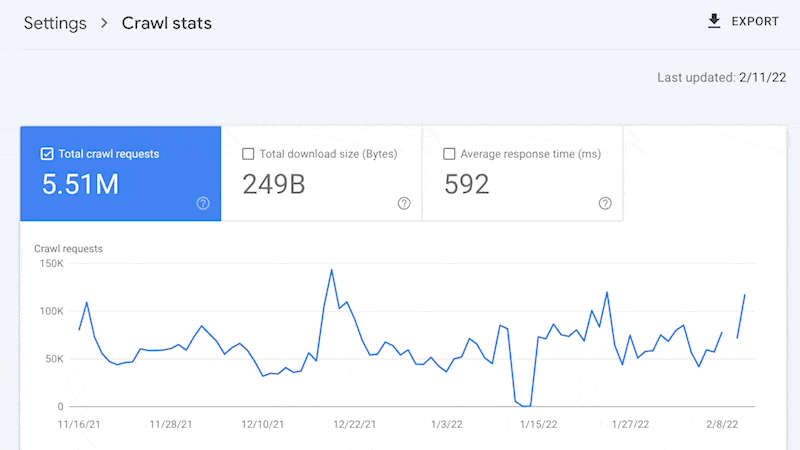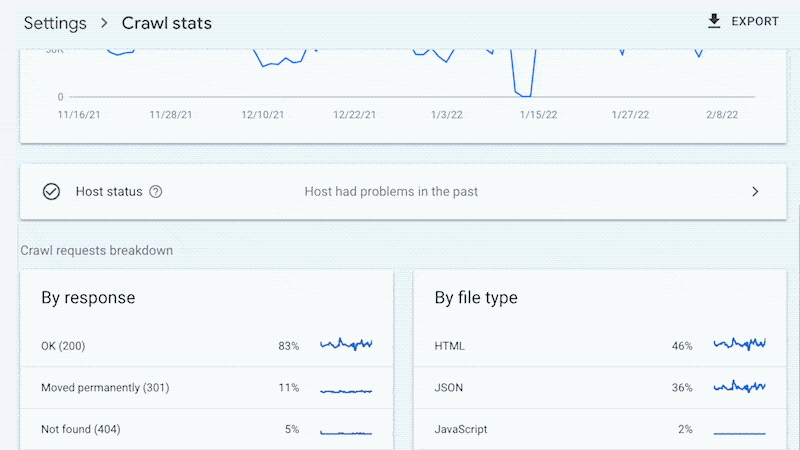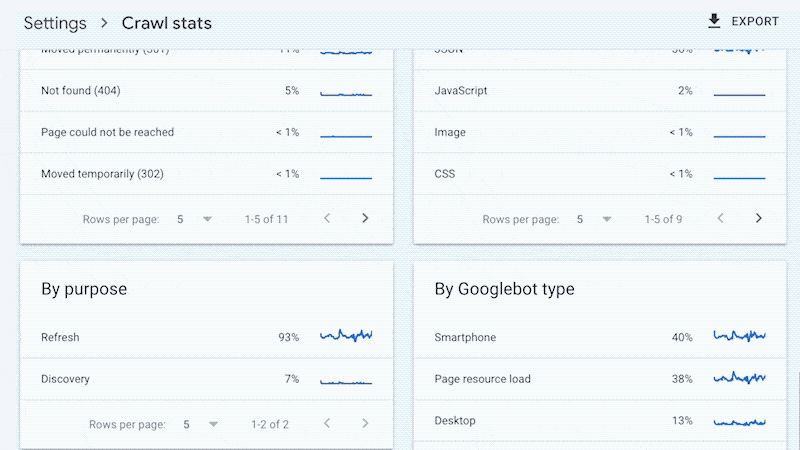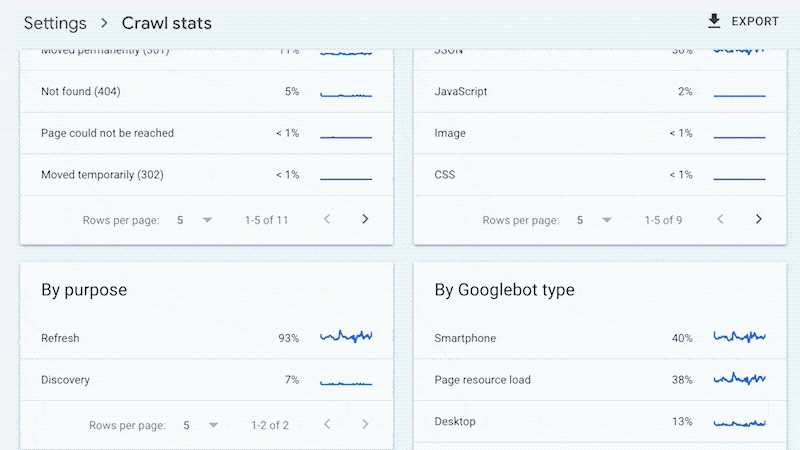
Sure, Google received’t present you with all URLs crawled (like with log information), and the tendencies evaluation is proscribed to a few months of knowledge.
Nevertheless, smaller websites that change occasionally additionally want much less ongoing technical search engine optimization. It’ll probably suffice to have a website auditor uncover and diagnose points.
For instance, a cross-analysis from a website crawler, XML sitemaps, Google Analytics, and Google Search Console will probably uncover all orphan pages.
You may additionally use a website auditor to find error standing codes from inside hyperlinks.
There are just a few key causes I’m pointing this out:
- Entry log information aren’t straightforward to come up with (extra on this subsequent).
- For small websites that change occasionally, the good thing about log information isn’t as a lot, that means search engine optimization focuses will probably go elsewhere.
Usually, to investigate log information, you’ll first should request entry to log information from a developer.
The developer is then probably going to have just a few points, which they’ll convey to your consideration. These embrace:
- Partial knowledge – Log information can embrace partial knowledge scattered throughout a number of servers. This often occurs when builders use varied servers, comparable to an origin server, load balancers, and a CDN. Getting an correct image of all logs will probably imply compiling the entry logs from all servers.
- File measurement – Entry log information for high-traffic websites can find yourself in terabytes, if not petabytes, making them arduous to switch.
- Privateness/compliance – Log information embrace consumer IP addresses that are personally identifiable data (PII). Consumer data may have eradicating earlier than it might be shared with you.
- Storage historical past – Because of file measurement, builders might have configured entry logs to be saved for just a few days solely, making them not helpful for recognizing tendencies and points.
These points will convey to query whether or not storing, merging, filtering, and transferring log information are well worth the dev effort, particularly if builders have already got a protracted checklist of priorities (which is commonly the case).
Builders will probably put the onus on the search engine optimization to clarify/construct a case for why builders ought to make investments time on this, which you have to to prioritize amongst different search engine optimization focuses.
These points are exactly why log file evaluation doesn’t occur incessantly.
Log information you obtain from builders are additionally typically formatted in unsupported methods by in style log file evaluation instruments, making evaluation harder.
Fortunately, there are software program options that simplify this course of. My favourite is Logflare, a Cloudflare app that may retailer log information in a BigQuery database that you just personal.
Now it’s time to begin analyzing your logs.
I’m going to indicate you the way to do that within the context of Logflare particularly; nonetheless, the recommendations on learn how to use log knowledge will work with any logs.
The template I’ll share shortly additionally works with any logs. You’ll simply want to ensure the columns within the knowledge sheets match up.
1. Begin by establishing Logflare (non-compulsory)
Logflare is easy to arrange. And with the BigQuery integration, it shops knowledge lengthy time period. You’ll personal the info, making it simply accessible for everybody.
There’s one problem. It’s essential swap out your area title servers to make use of Cloudflare ones and handle your DNS there.
For many, that is superb. Nevertheless, if you happen to’re working with a extra enterprise-level website, it’s unlikely you’ll be able to persuade the server infrastructure crew to vary the title servers to simplify log evaluation.
I received’t go by way of each step on learn how to get Logflare working. However to get began, all that you must do is head to the Cloudflare Apps a part of your dashboard.
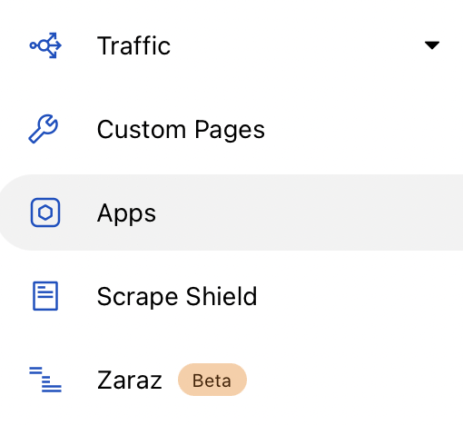
After which seek for Logflare.
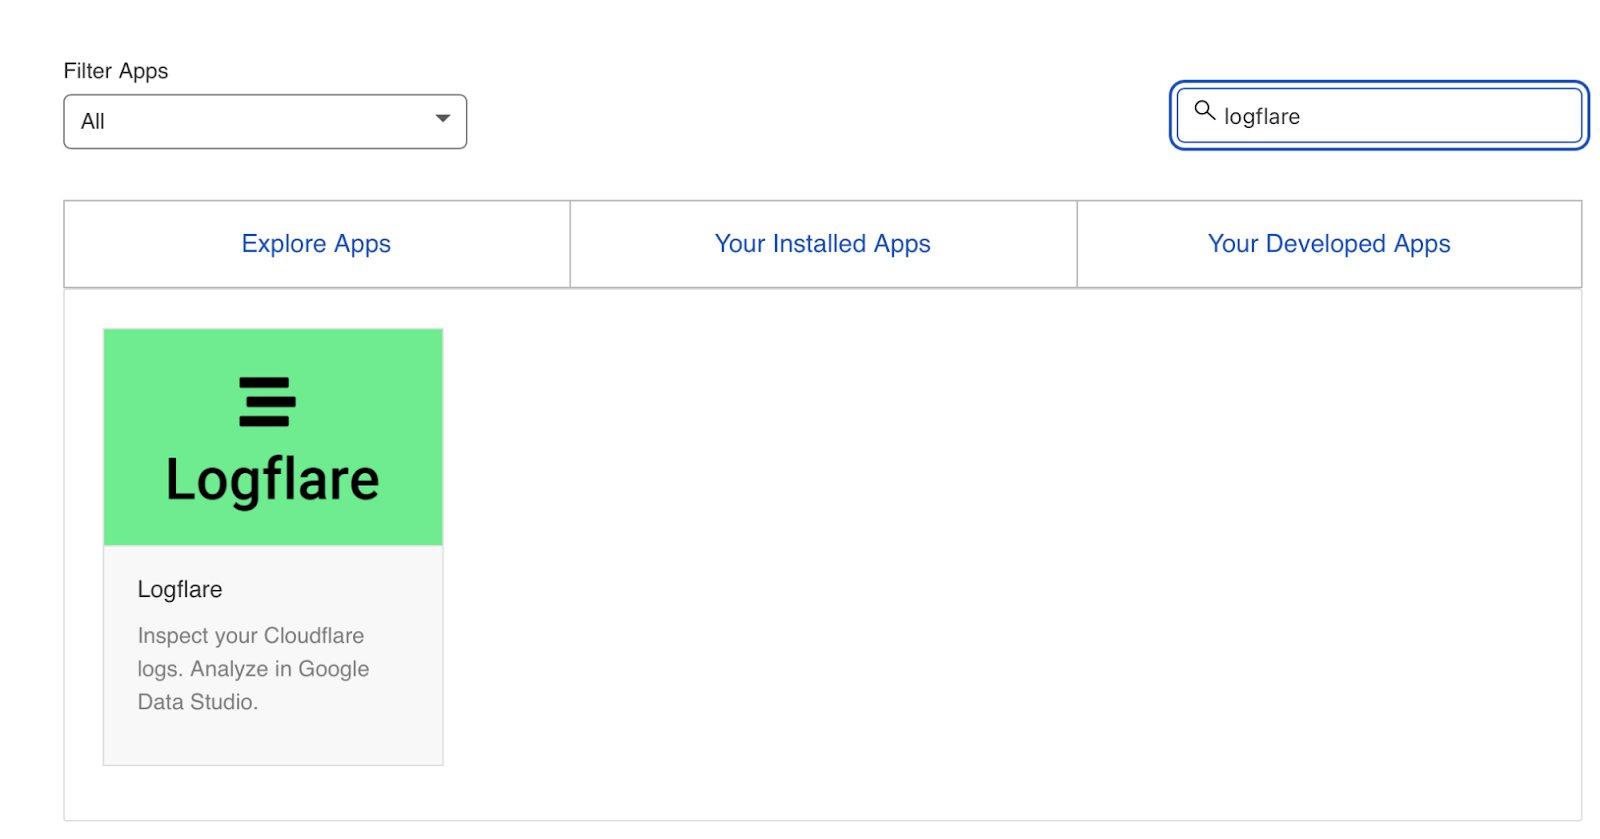
The setup previous this level is self-explanatory (create an account, give your undertaking a reputation, select the info to ship, and many others.). The one further half I like to recommend following is Logflare’s information to establishing BigQuery.
Keep in mind, nonetheless, that BigQuery does have a value that’s primarily based on the queries you do and the quantity of knowledge you retailer.
Sidenote.
It’s price noting that one vital benefit of the BigQuery backend is that you just personal the info. Meaning you’ll be able to circumvent PII points by configuring Logflare to not ship PII like IP addresses and delete PII from BigQuery utilizing an SQL question.
2. Confirm Googlebot
We’ve now saved log information (through Logflare or an alternate methodology). Subsequent, we have to extract logs exactly from the consumer brokers we need to analyze. For many, this will likely be Googlebot.
Earlier than we do this, we now have one other hurdle to leap throughout.
Many bots fake to be Googlebot to get previous firewalls (in case you have one). As well as, some auditing instruments do the identical to get an correct reflection of the content material your website returns for the consumer agent, which is crucial in case your server returns completely different HTML for Googlebot, e.g., if you happen to’ve arrange dynamic rendering.
I’m not utilizing Logflare
In the event you aren’t utilizing Logflare, figuring out Googlebot would require a reverse DNS lookup to confirm the request did come from Google.
Google has a useful information on validating Googlebot manually right here.
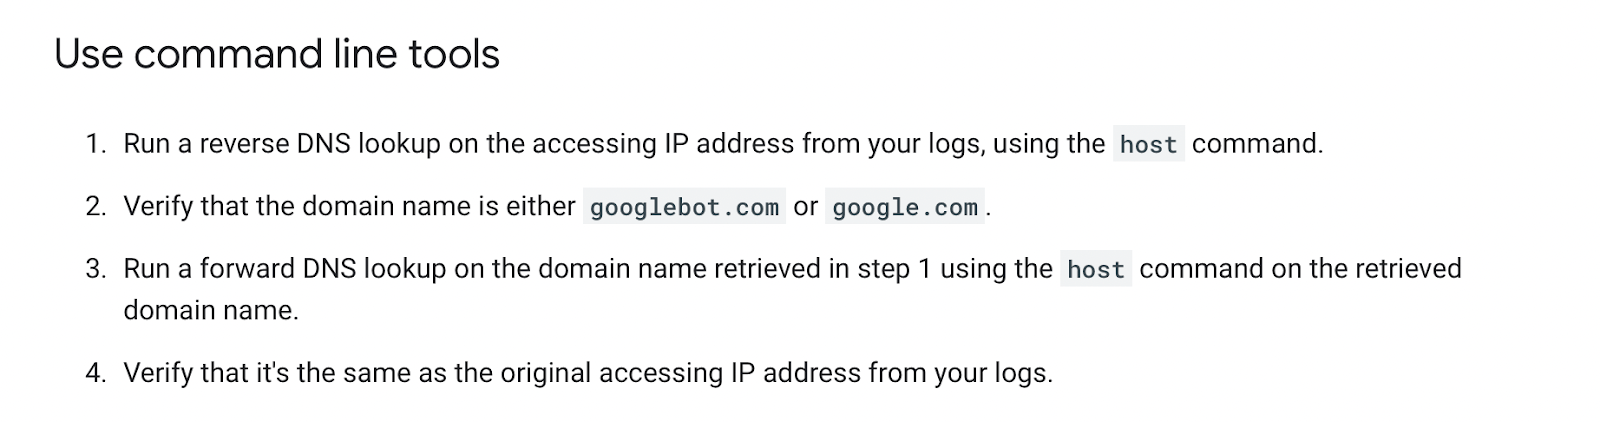
You are able to do this on a one-off foundation, utilizing a reverse IP lookup instrument and checking the area title returned.
Nevertheless, we have to do that in bulk for all rows in our log information. This additionally requires you to match IP addresses from an inventory supplied by Google.
The simplest means to do that is by utilizing server firewall rule units maintained by third events that block faux bots (leading to fewer/no faux Googlebots in your log information). A in style one for Nginx is “Nginx Final Unhealthy Bot Blocker.”
Alternatively, one thing you’ll word on the checklist of Googlebot IPs is the IPV4 addresses all start with “66.”
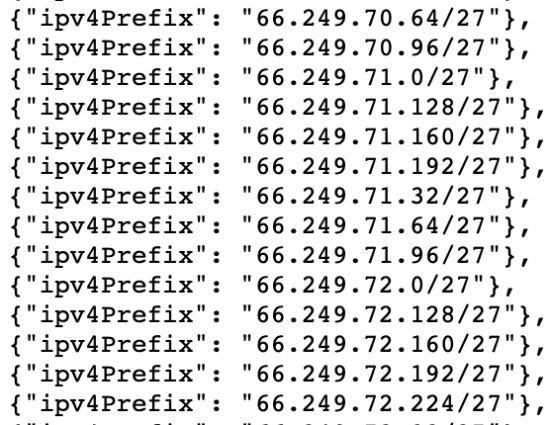
Whereas it received’t be 100% correct, you’ll be able to additionally verify for Googlebot by filtering for IP addresses beginning with “6” when analyzing the info inside your logs.
I’m utilizing Cloudflare/Logflare
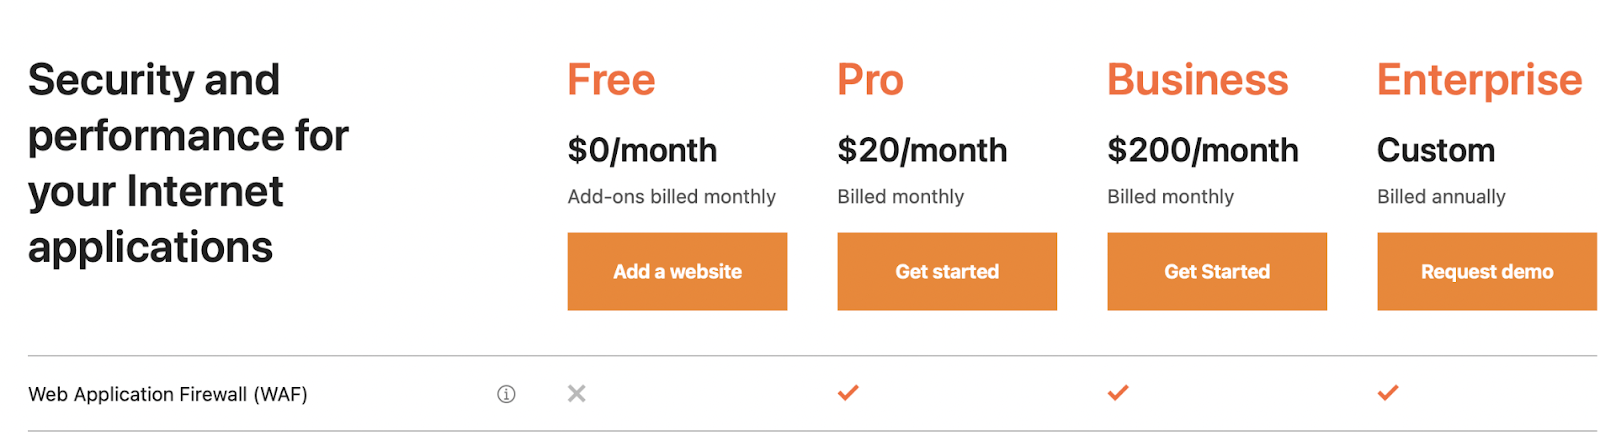
Cloudflare’s professional plan (at present $20/month) has built-in firewall options that may block faux Googlebot requests from accessing your website.
Cloudflare disables these options by default, however yow will discover them by heading to Firewall > Managed Guidelines > enabling “Cloudflare Specials” > choose “Superior”:
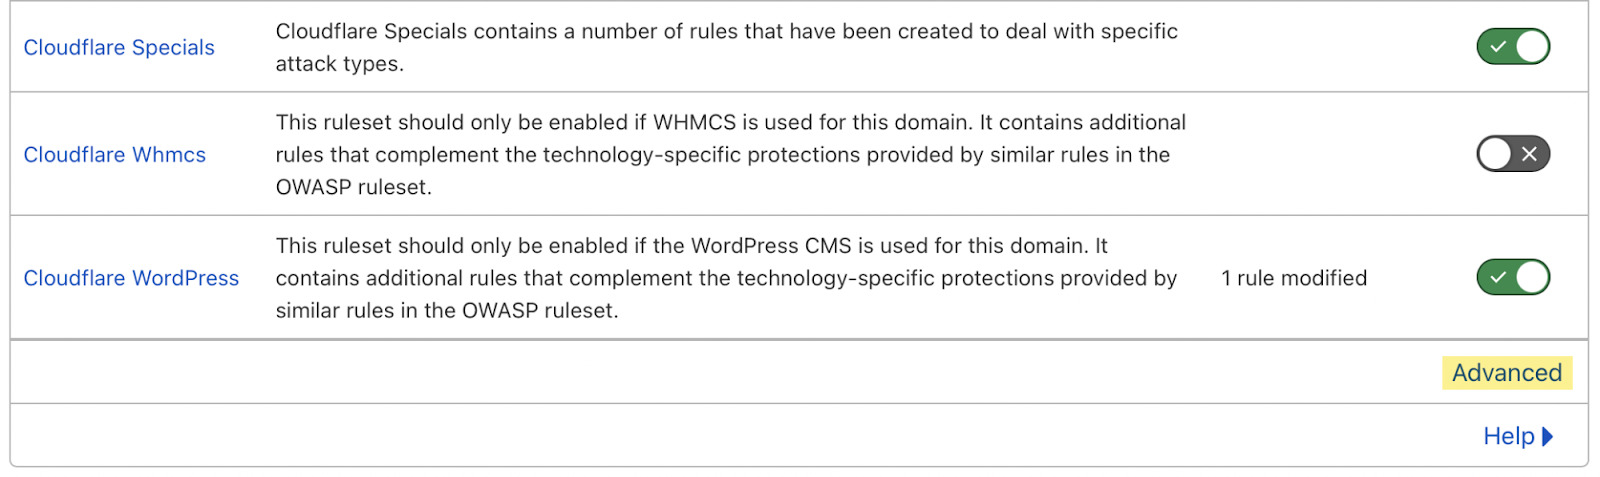
Subsequent, change the search kind from “Description” to “ID” and seek for “100035.”
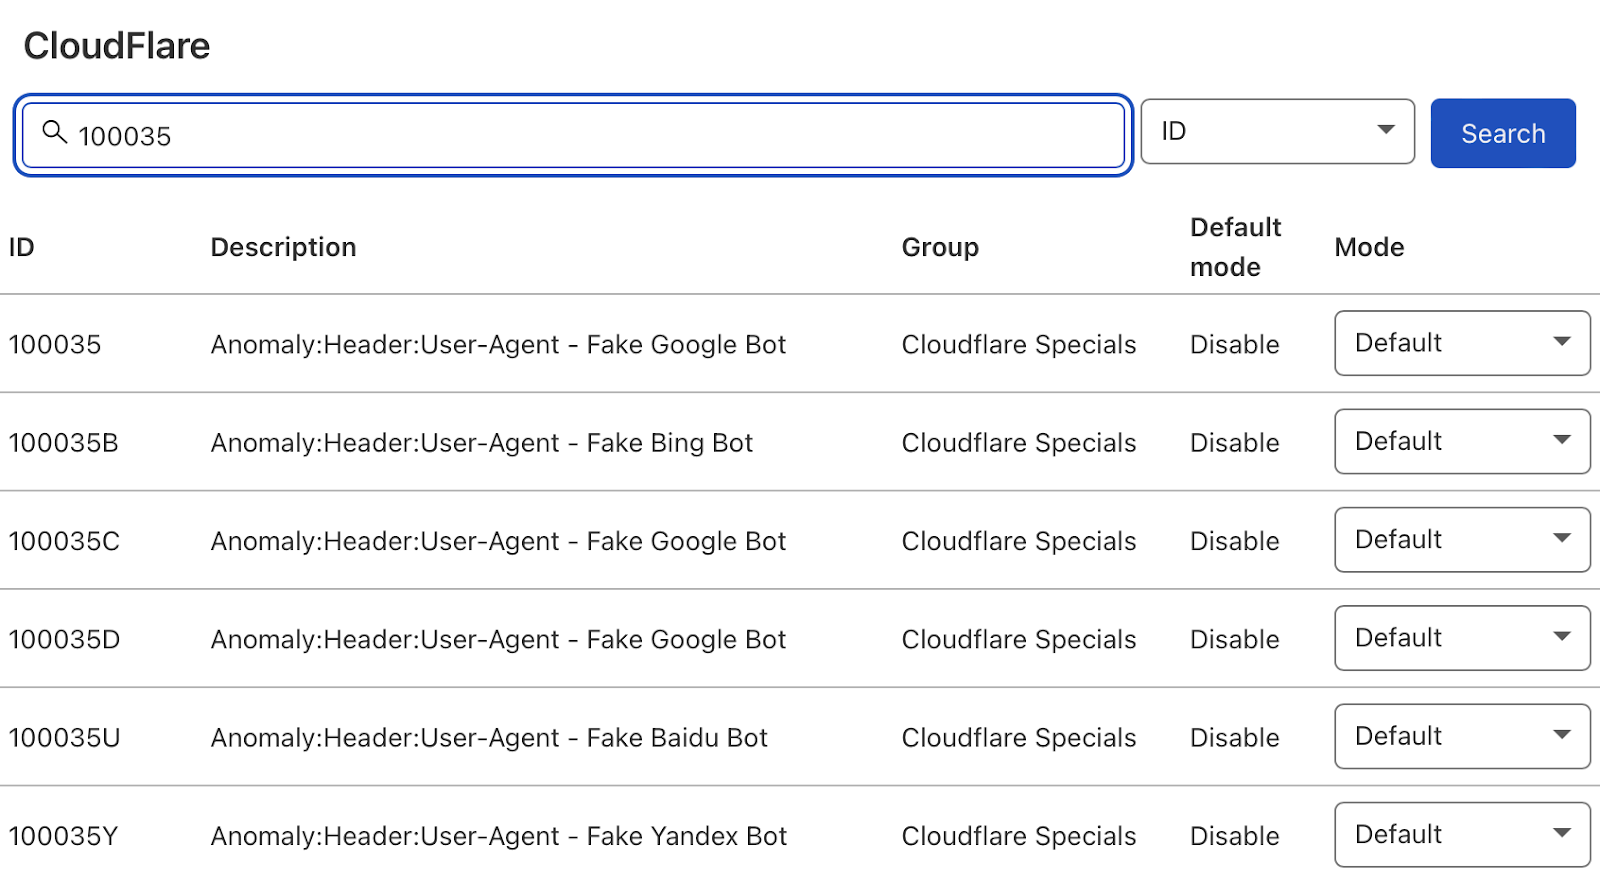
Cloudflare will now current you with an inventory of choices to dam faux search bots. Set the related ones to “Block,” and Cloudflare will verify all requests from search bot consumer brokers are reliable, retaining your log information clear.
3. Extract knowledge from log information
Lastly, we now have entry to log information, and we all know the log information precisely mirror real Googlebot requests.
I like to recommend analyzing your log information inside Google Sheets/Excel to begin with as a result of you’ll probably be used to spreadsheets, and it’s easy to cross-analyze log information with different sources like a website crawl.
There is no such thing as a one proper means to do that. You should use the next:
You can too do that inside a Knowledge Studio report. I discover Knowledge Studio useful for monitoring knowledge over time, and Google Sheets/Excel is healthier for a one-off evaluation when technical auditing.
Open BigQuery and head to your undertaking/dataset.
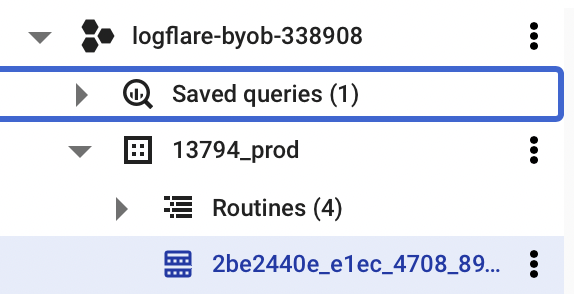
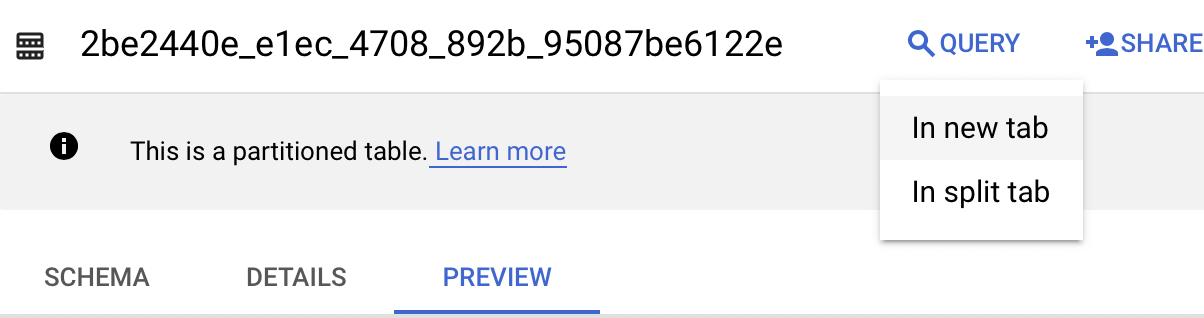
Choose the “Question” dropdown and open it in a brand new tab.
Subsequent, you’ll want to write down some SQL to extract the info you’ll be analyzing. To make this simpler, first copy the contents of the FROM a part of the question.
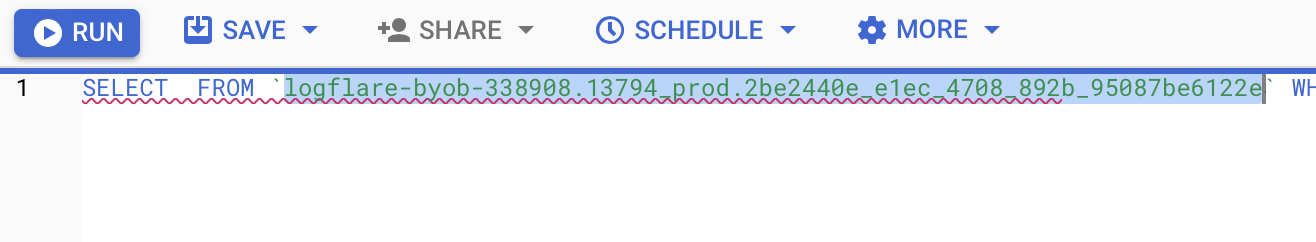
After which you’ll be able to add that inside the question I’ve written for you under:
SELECT DATE(timestamp) AS Date, req.url AS URL, req_headers.cf_connecting_ip AS IP, req_headers.user_agent AS User_Agent, resp.status_code AS Status_Code, resp.origin_time AS Origin_Time, resp_headers.cf_cache_status AS Cache_Status, resp_headers.content_type AS Content_Type
FROM `[Add Your from address here]`,
UNNEST(metadata) m,
UNNEST(m.request) req,
UNNEST(req.headers) req_headers,
UNNEST(m.response) resp,
UNNEST(resp.headers) resp_headers
WHERE DATE(timestamp) >= "2022-01-03" AND (req_headers.user_agent LIKE '%Googlebot%' OR req_headers.user_agent LIKE '%bingbot%')
ORDER BY timestamp DESC
This question selects all of the columns of knowledge which can be helpful for log file evaluation for search engine optimization functions. It additionally solely pulls knowledge for Googlebot and Bingbot.
Sidenote.
If there are different bots you need to analyze, simply add one other OR req_headers.user_agent LIKE ‘%bot_name%’ inside the WHERE assertion. You can too simply change the beginning date by updating the WHERE DATE(timestamp) >= “2022–03-03” line.
Choose “Run” on the high. Then select to avoid wasting the outcomes.
Subsequent, save the info to a CSV in Google Drive (that is the best choice as a result of bigger file measurement).
After which, as soon as BigQuery has run the job and saved the file, open the file with Google Sheets.
4. Add to Google Sheets
We’re now going to begin with some evaluation. I like to recommend utilizing my Google Sheets template. However I’ll clarify what I’m doing, and you’ll construct the report your self if you happen to need.
The template consists of two knowledge tabs to repeat and paste your knowledge into, which I then use for all different tabs utilizing the Google Sheets QUERY perform.
Sidenote.
If you wish to see how I’ve accomplished the stories that we’ll run by way of after establishing, choose the primary cell in every desk.
To begin with, copy and paste the output of your export from BigQuery into the “Knowledge — Log information” tab.
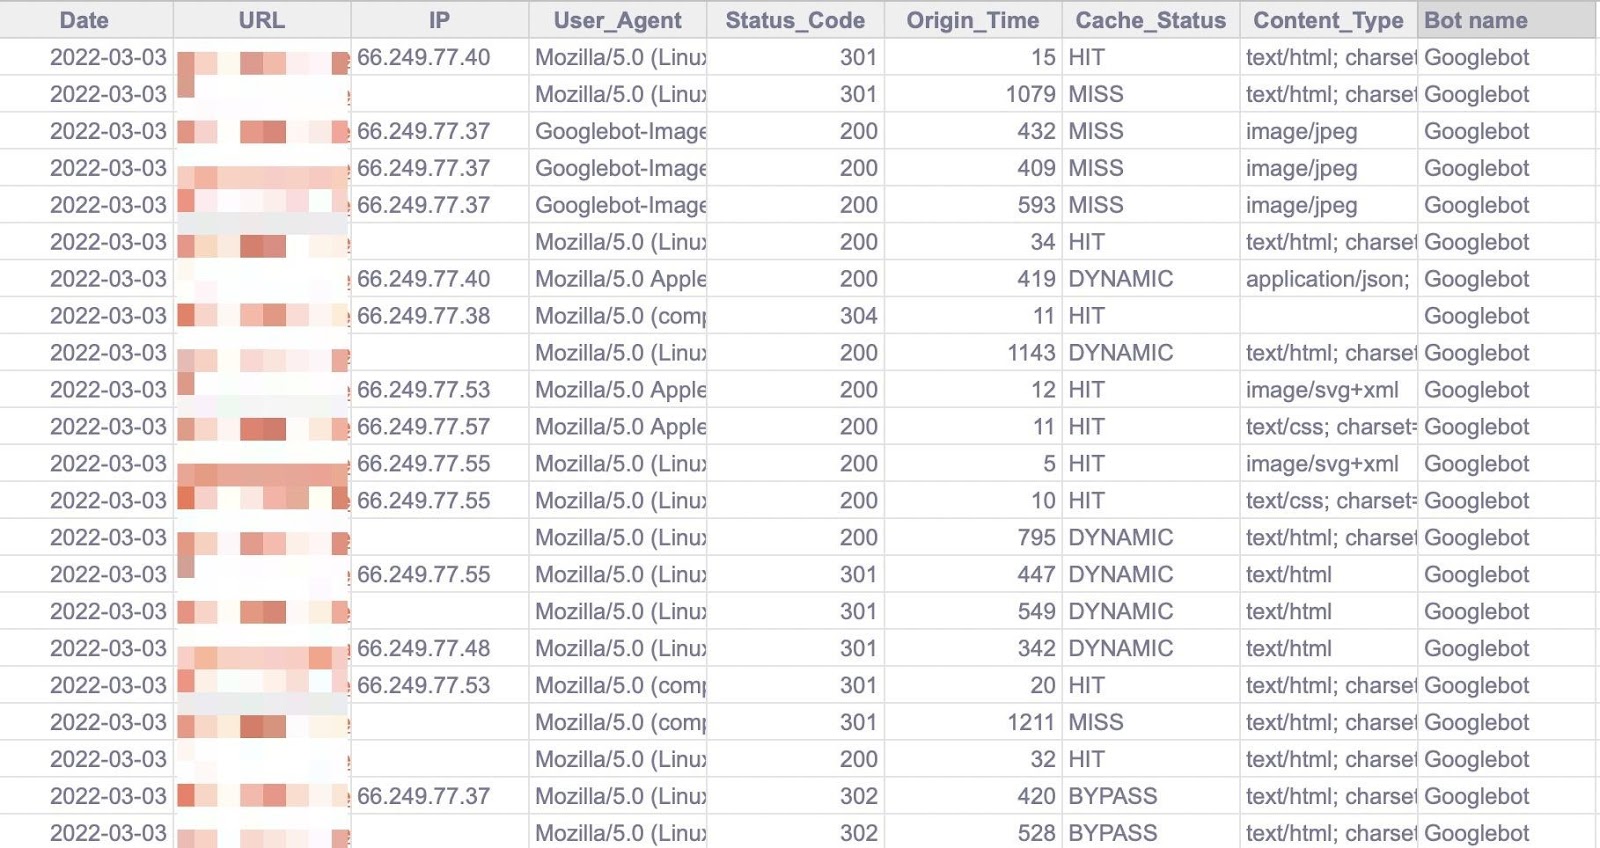
Observe that there are a number of columns added to the tip of the sheet (in darker gray) to make evaluation a bit of simpler (just like the bot title and first URL listing).
5. Add Ahrefs knowledge
In case you have a website auditor, I like to recommend including extra knowledge to the Google Sheet. Primarily, it’s best to add these:
- Natural site visitors
- Standing codes
- Crawl depth
- Indexability
- Variety of inside hyperlinks
To get this knowledge out of Ahrefs’ Website Audit, head to Web page Explorer and choose “Handle Columns.”
I then advocate including the columns proven under:
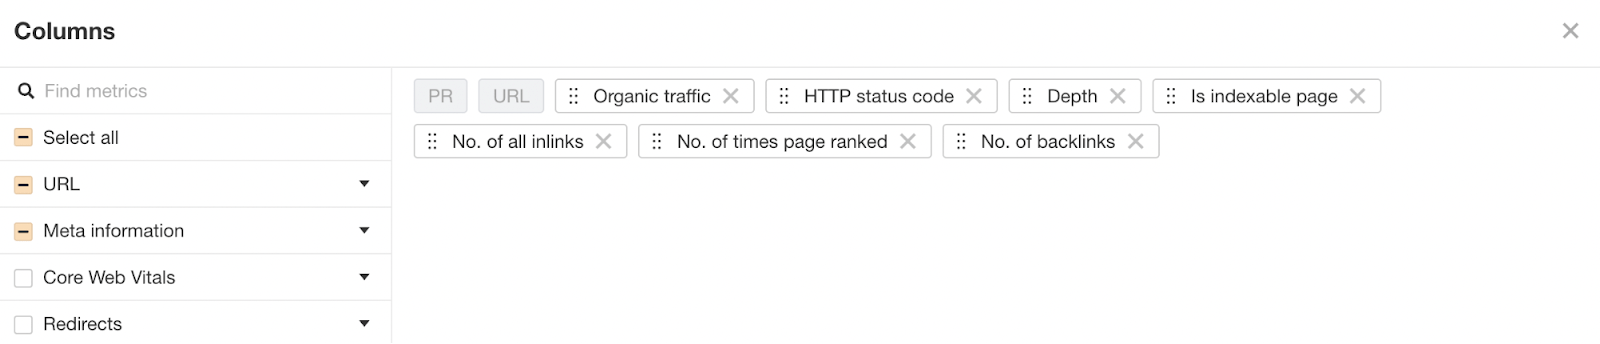
Then export all of that knowledge.
And duplicate and paste into the “Knowledge — Ahrefs” sheet.
6. Examine for standing codes
The very first thing we’ll analyze is standing codes. This knowledge will reply whether or not search bots are losing crawl finances on non-200 URLs.
Observe that this doesn’t all the time level towards an concern.
Typically, Google can crawl previous 301s for a few years. Nevertheless, it could actually spotlight a difficulty if you happen to’re internally linking to many non-200 standing codes.
The “Standing Codes — Overview” tab has a QUERY perform that summarizes the log file knowledge and shows the ends in a chart.
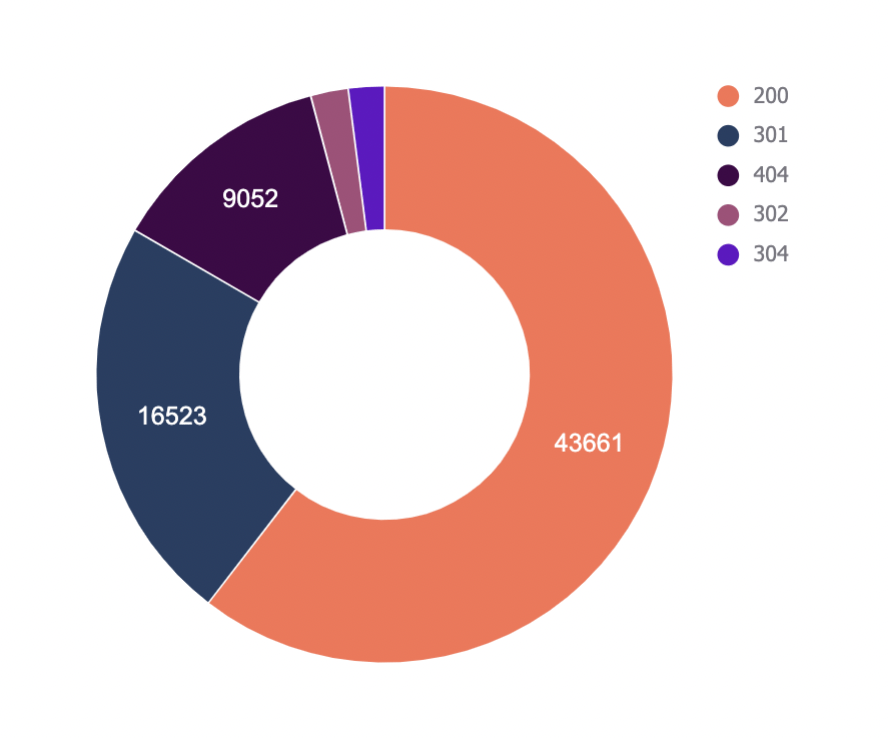
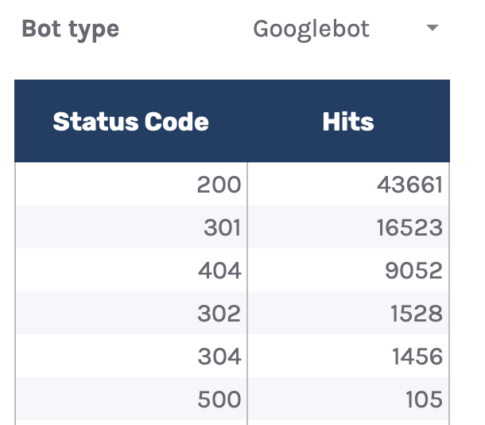
There’s additionally a dropdown to filter by bot kind and see which of them are hitting non-200 standing codes the most.
In fact, this report alone doesn’t assist us clear up the problem, so I’ve added one other tab, “URLs — Overview.”
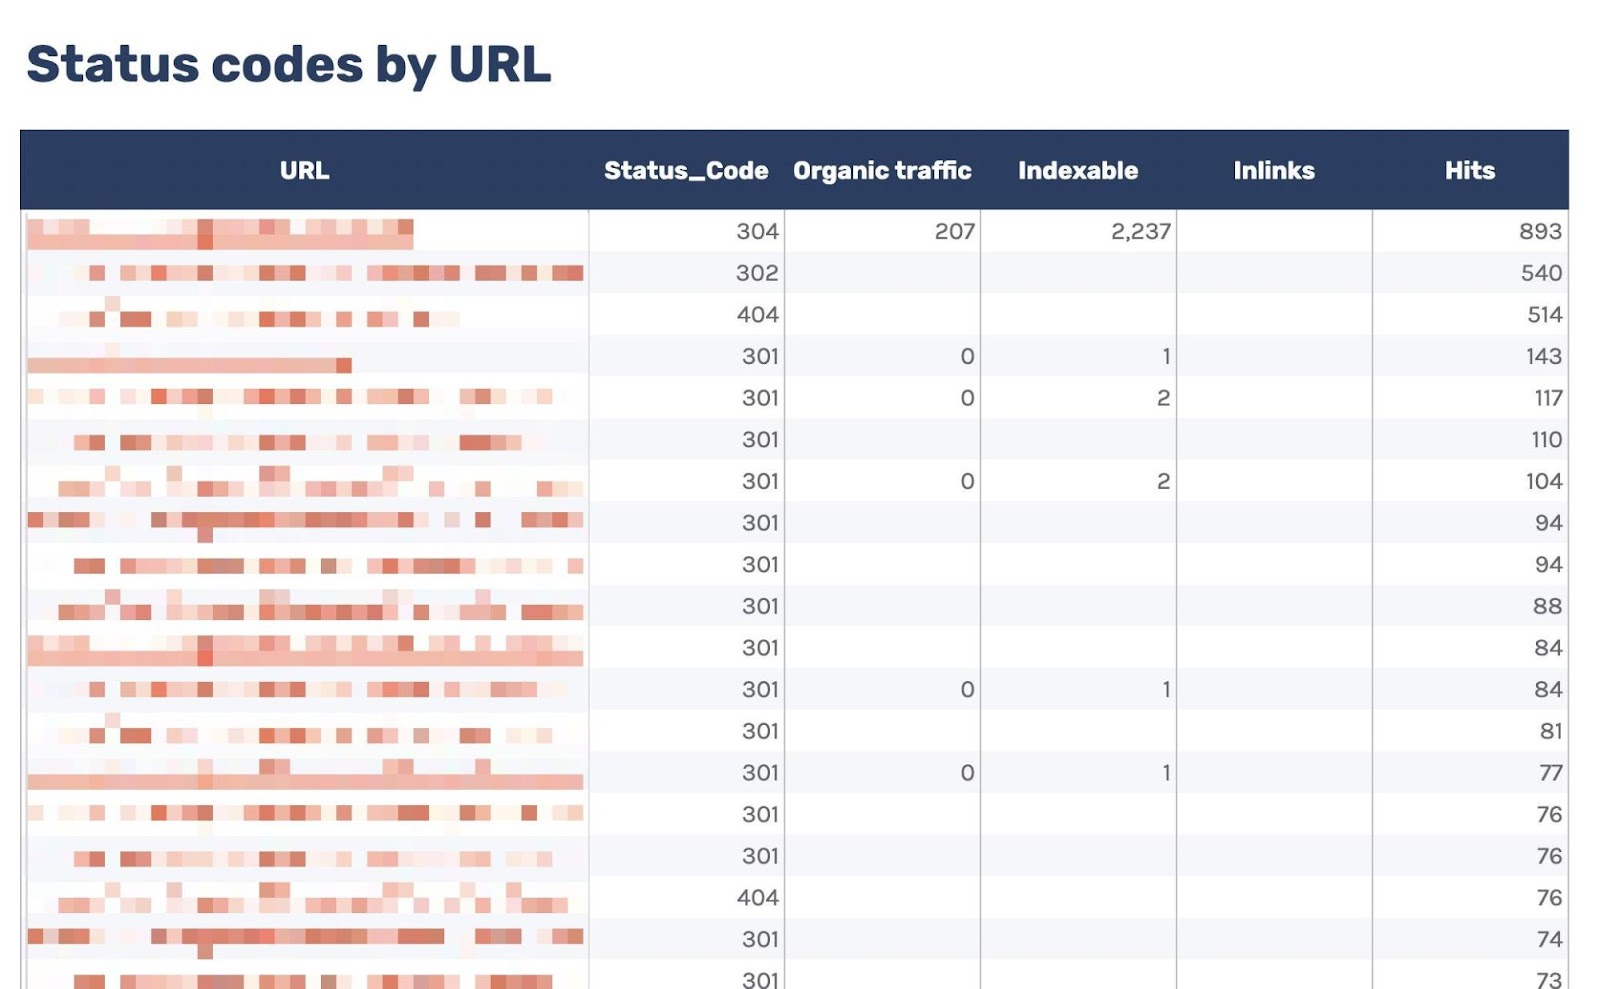
You should use this to filter for URLs that return non-200 standing codes. As I’ve additionally included knowledge from Ahrefs’ Website Audit, you’ll be able to see whether or not you’re internally linking to any of these non-200 URLs within the “Inlinks” column.
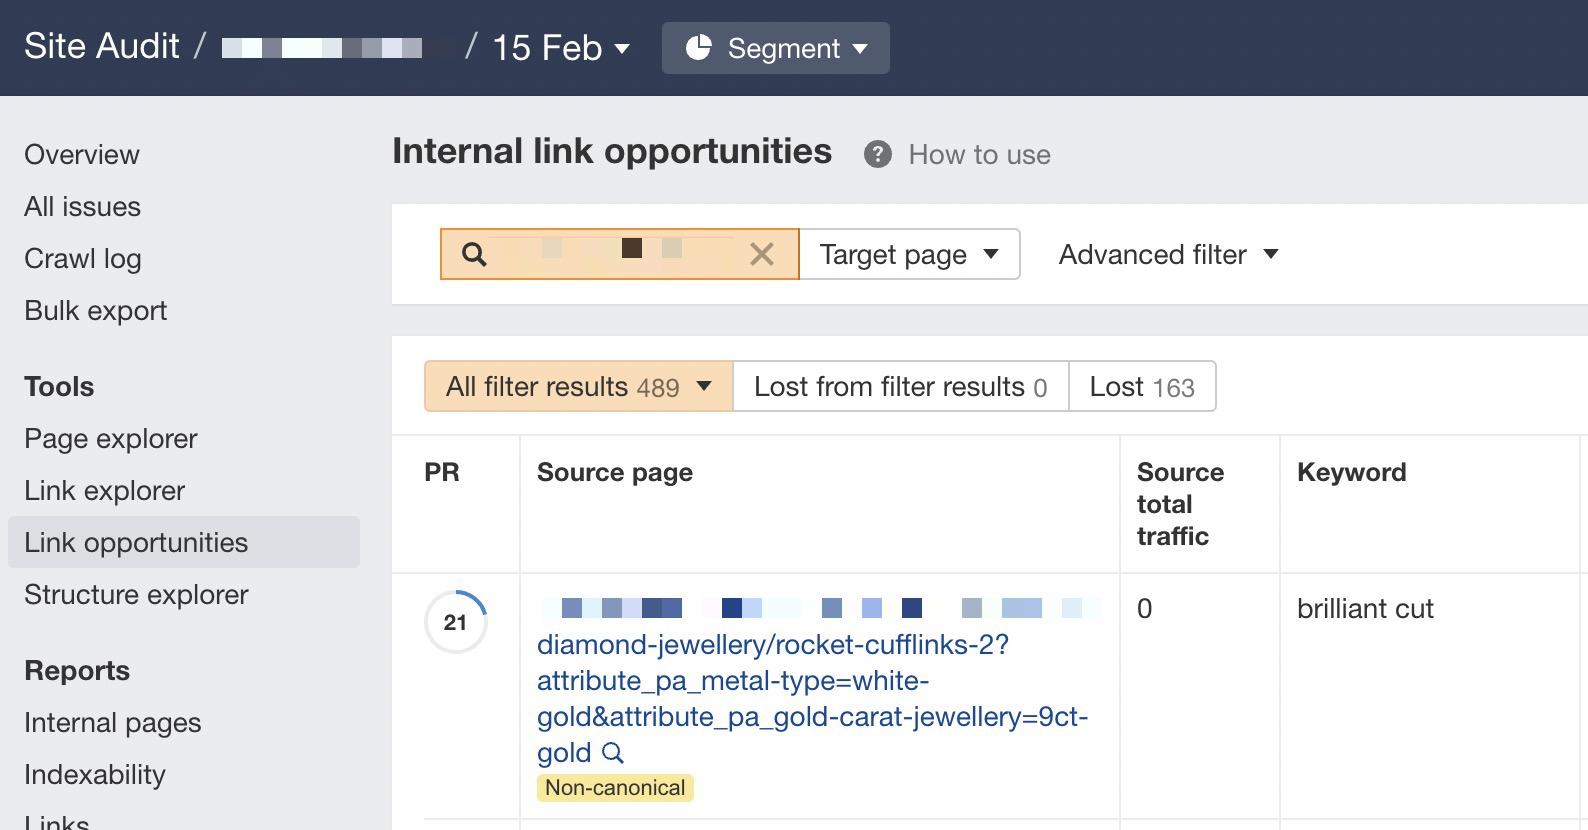
In the event you see numerous inside hyperlinks to the URL, you’ll be able to then use the Inside hyperlink alternatives report to identify these incorrect inside hyperlinks by merely copying and pasting the URL within the search bar with “Goal web page” chosen.
7. Detect crawl finances wastage
One of the best ways to spotlight crawl finances wastage from log information that isn’t on account of crawling non-200 standing codes is to seek out incessantly crawled non-indexable URLs (e.g., they’re canonicalized or noindexed).
Since we’ve added knowledge from our log information and Ahrefs’ Website Audit, recognizing these URLs is simple.
Head to the “Crawl finances wastage” tab, and also you’ll discover extremely crawled HTML information that return a 200 however are non-indexable.
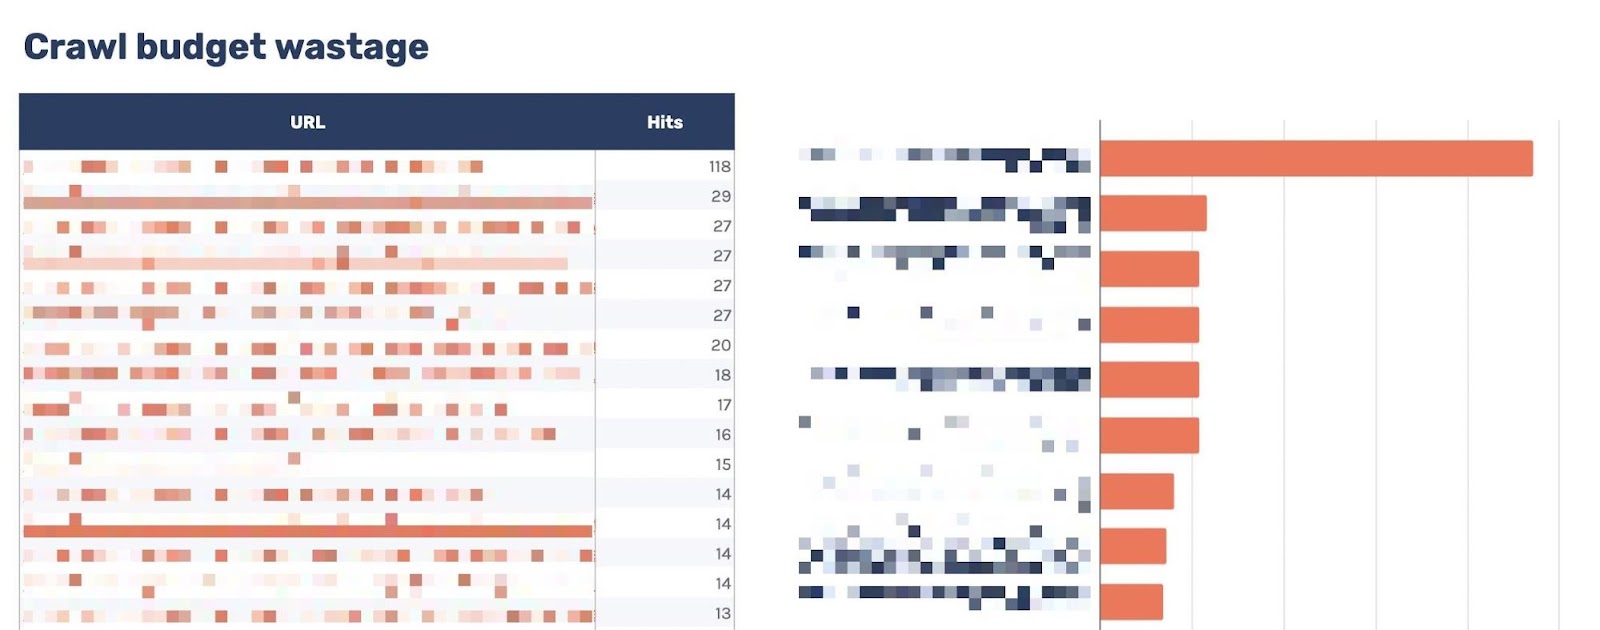
Now that you’ve got this knowledge, you’ll need to examine why the bot is crawling the URL. Listed below are some widespread causes:
- It’s internally linked to.
- It’s incorrectly included in XML sitemaps.
- It has hyperlinks from exterior websites.
It’s widespread for bigger websites, particularly these with faceted navigation, to hyperlink to many non-indexable URLs internally.
If the hit numbers on this report are very excessive and also you consider you’re losing your crawl finances, you’ll probably must take away inside hyperlinks to the URLs or block crawling with the robots.txt.
8. Monitor essential URLs
In case you have particular URLs in your website which can be extremely essential to you, you might need to watch how typically engines like google crawl them.
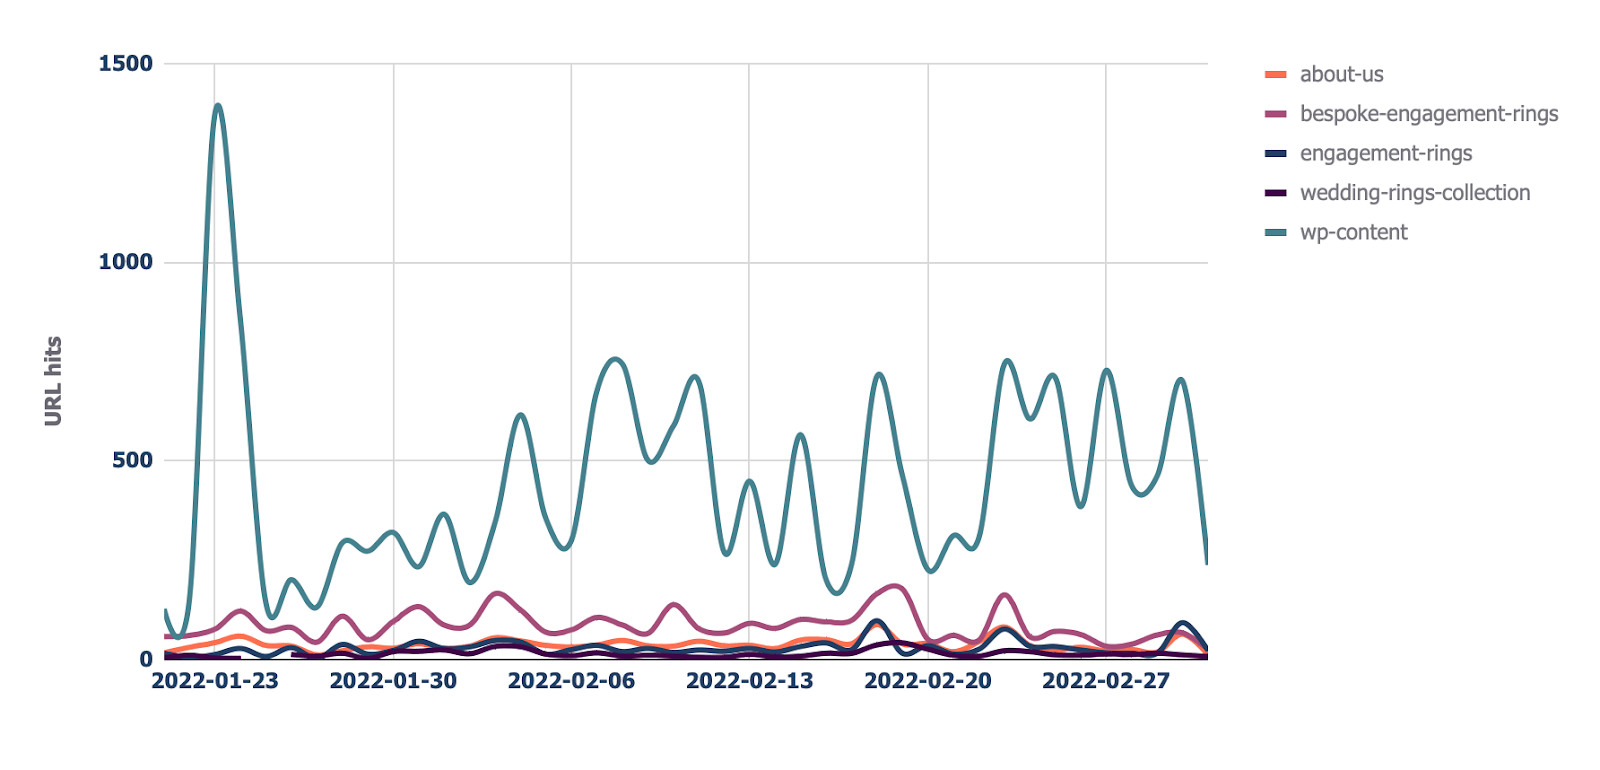
The “URL monitor” tab does simply that, plotting the day by day pattern of hits for as much as 5 URLs which you could add.
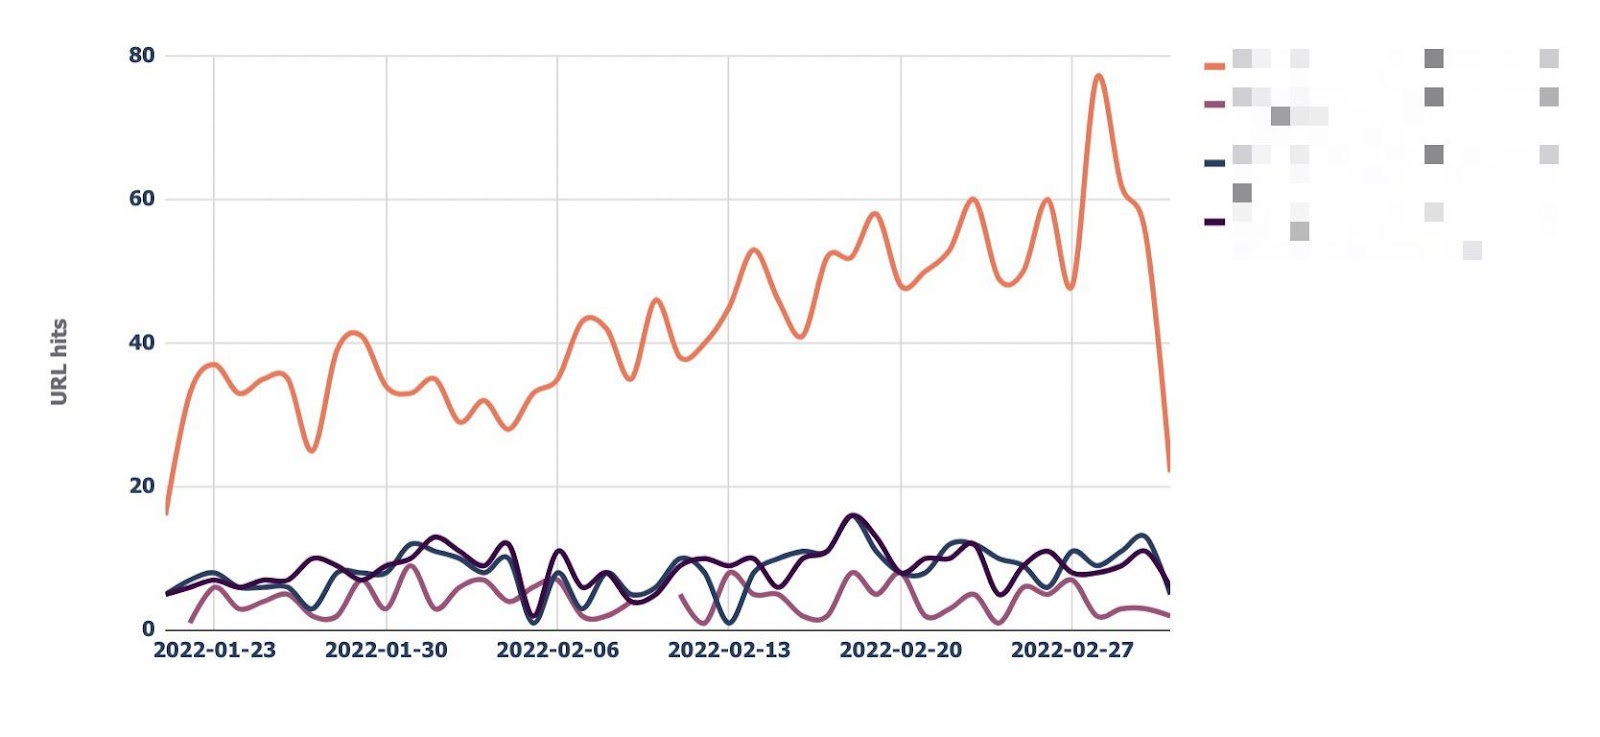
You can too filter by bot kind, making it straightforward to watch how typically Bing or Google crawls a URL.
Sidenote.
You may additionally use this report back to verify URLs you’ve not too long ago redirected. Merely add the previous URL and new URL within the dropdown and see how rapidly Googlebot notices the change.
Usually, the recommendation right here is that it’s a nasty factor if Google doesn’t crawl a URL incessantly. That merely isn’t the case.
Whereas Google tends to crawl in style URLs extra incessantly, it is going to probably crawl a URL much less if it doesn’t change typically.
Nonetheless, it’s useful to monitor URLs like this if you happen to want content material adjustments picked up rapidly, comparable to on a information website’s homepage.
In truth, if you happen to discover Google is recrawling a URL too incessantly, I’ll advocate for making an attempt to assist it higher handle crawl charge by doing issues like including <lastmod> to XML sitemaps. Right here’s what it seems like:
<?xml model="1.0" encoding="UTF-8"?>
<urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
<url>
<loc>https://www.logexample.com/instance</loc>
<lastmod>2022-10-04</lastmod>
</url>
</urlset>
You may then replace the <lastmod> attribute each time the content material of the web page adjustments, signaling Google to recrawl.
9. Discover orphan URLs
One other means to make use of log information is to find orphan URLs, i.e., URLs that you really want engines like google to crawl and index however haven’t internally linked to.
We will do that by checking for 200 standing code HTML URLs with no inside hyperlinks discovered by Ahrefs’ Website Audit.
You may see the report I’ve created for this named “Orphan URLs.”
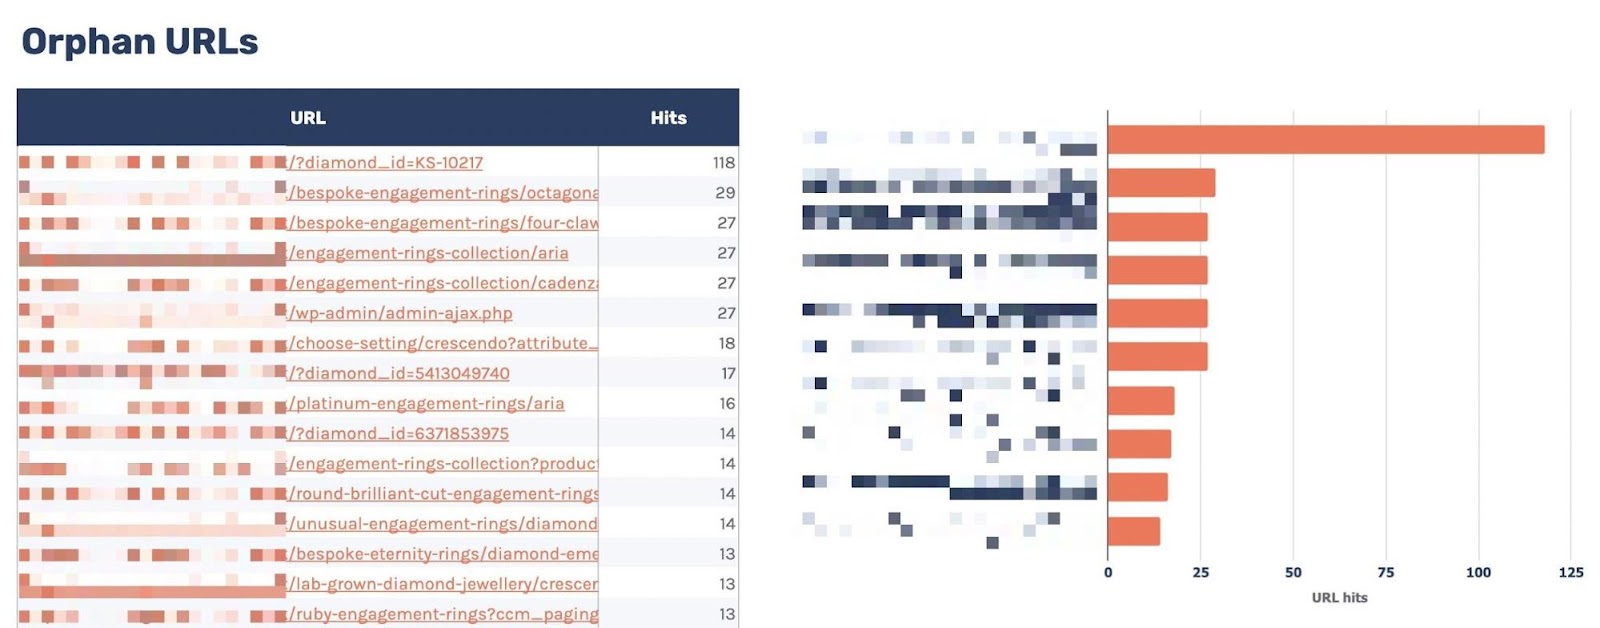
There’s one caveat right here. As Ahrefs hasn’t found these URLs however Googlebot has, these URLs is probably not URLs we need to hyperlink to as a result of they’re non-indexable.
I like to recommend copying and pasting these URLs utilizing the “Customized URL checklist” performance when establishing crawl sources to your Ahrefs undertaking.
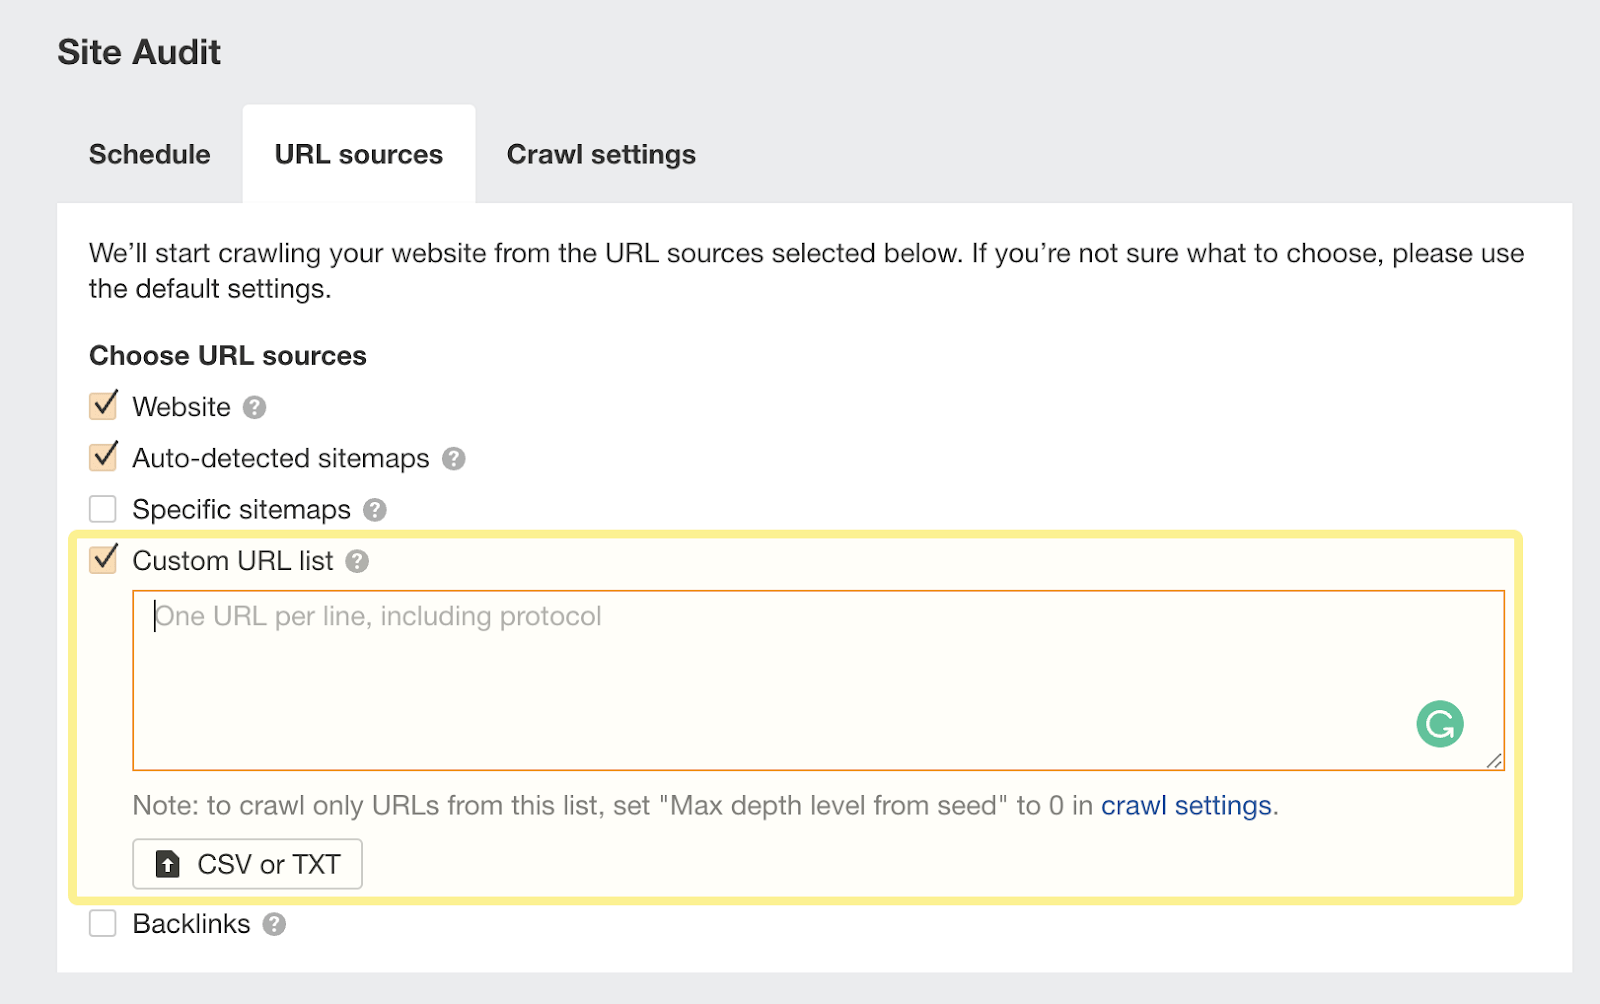
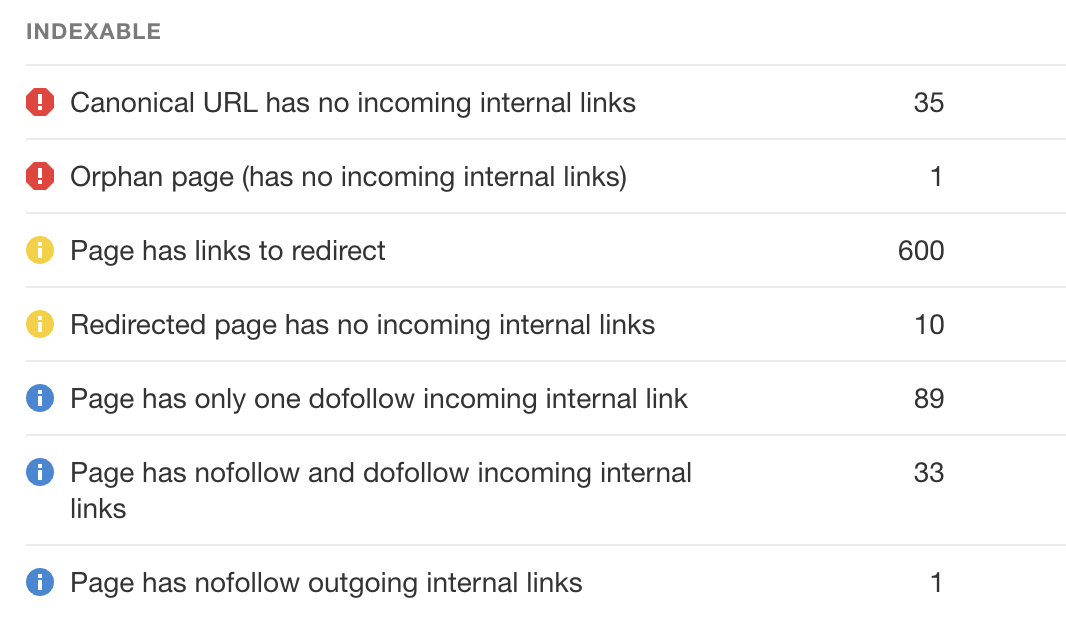
This fashion, Ahrefs will now take into account these orphan URLs present in your log information and report any points to you in your subsequent crawl:
10. Monitor crawling by listing
Suppose you’ve carried out structured URLs that point out the way you’ve organized your website (e.g., /options/feature-page/).
In that case, you can even analyze log information primarily based on the listing to see if Googlebot is crawling sure sections of the location greater than others.
I’ve carried out this sort of evaluation within the “Directories — Overview” tab of the Google Sheet.
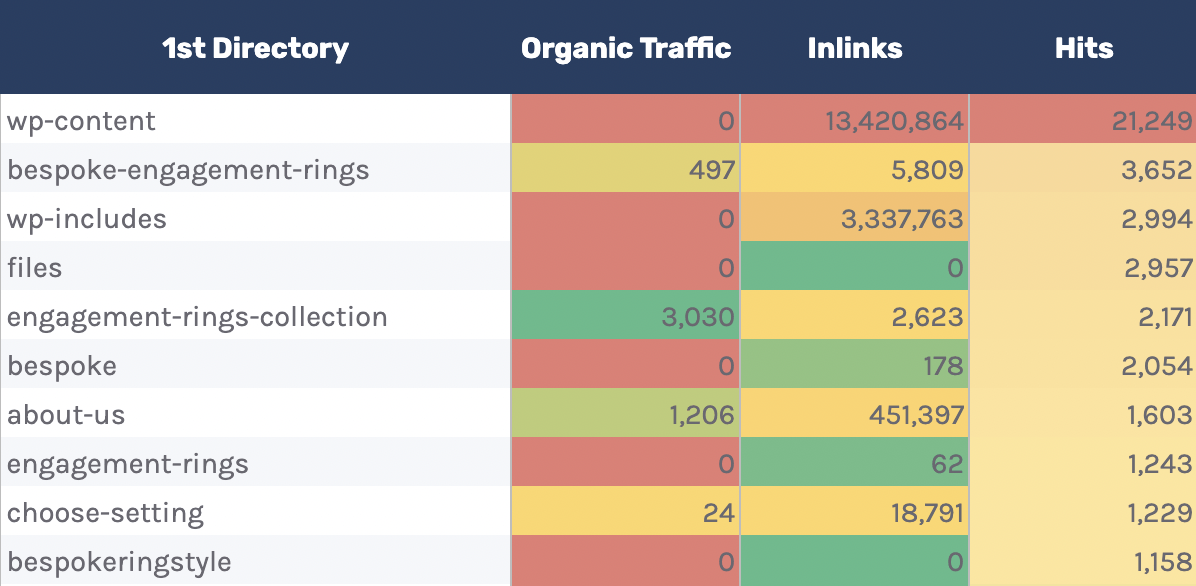
You may see I’ve additionally included knowledge on the variety of inside hyperlinks to the directories, in addition to whole natural site visitors.
You should use this to see whether or not Googlebot is spending extra time crawling low-traffic directories than high-value ones.
However once more, keep in mind this will happen, as some URLs inside particular directories change extra typically than others. Nonetheless, it’s price additional investigating if you happen to spot an odd pattern.
Along with this report, there may be additionally a “Directories — Crawl pattern” report if you wish to see the crawl pattern per listing to your website.
11. View Cloudflare cache ratios
Head to the “CF cache standing” tab, and also you’ll see a abstract of how typically Cloudflare is caching your information on the edge servers.
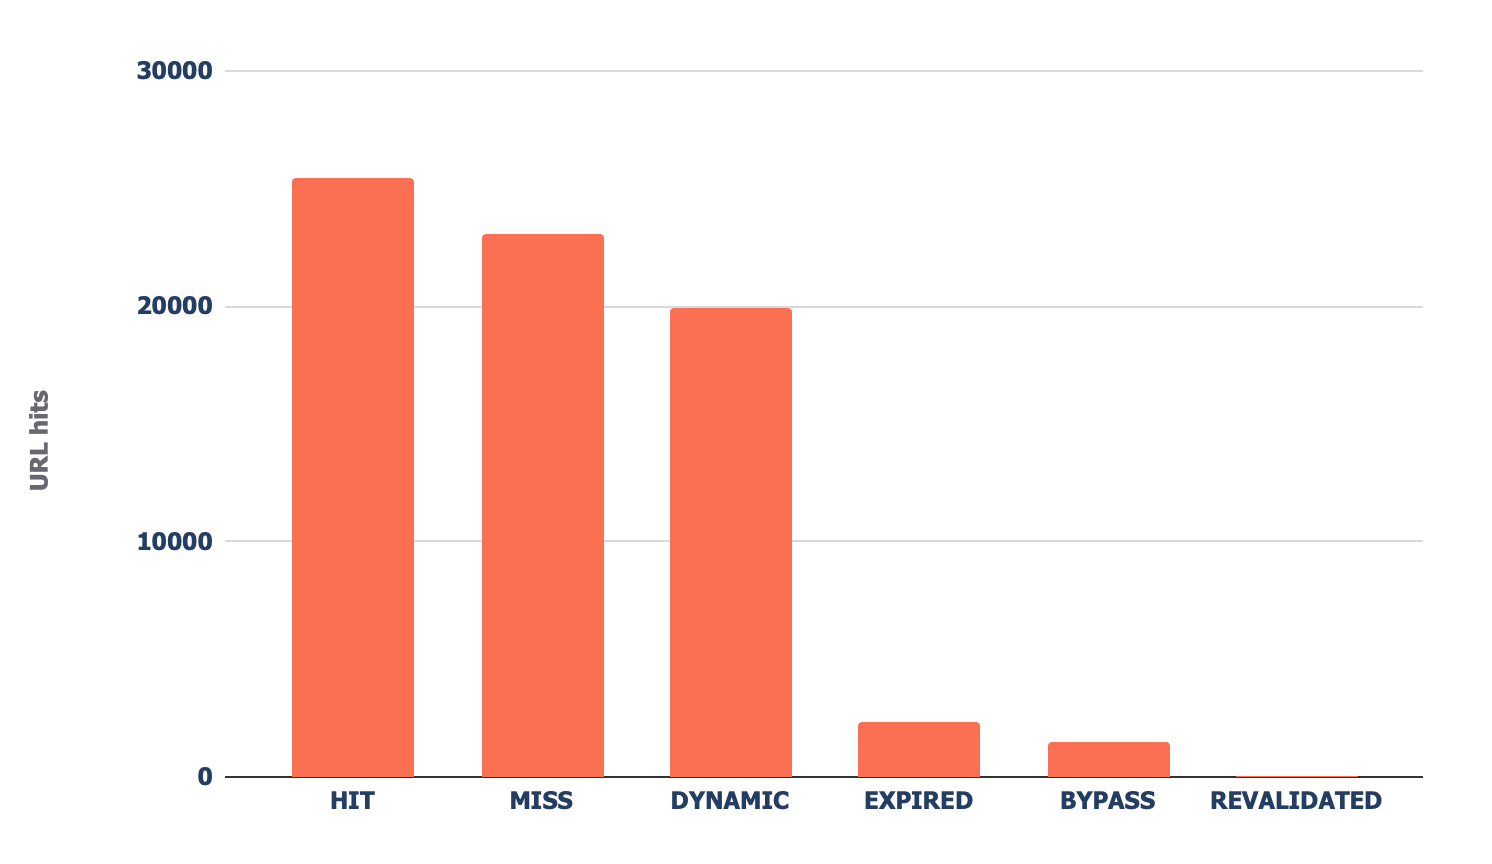
When Cloudflare caches content material (HIT within the above chart), the request not goes to your origin server and is served straight from its world CDN. This ends in higher Core Net Importants, particularly for world websites.
Sidenote.
It’s additionally price having a caching setup in your origin server (comparable to Varnish, Nginx FastCGI, or Redis full-page cache). That is in order that even when Cloudflare hasn’t cached a URL, you’ll nonetheless profit from some caching.
In the event you see a considerable amount of “Miss” or “Dynamic” responses, I like to recommend investigating additional to grasp why Cloudflare isn’t caching content material. Frequent causes can be:
- You’re linking to URLs with parameters in them – Cloudflare, by default, passes these requests to your origin server, as they’re probably dynamic.
- Your cache expiry instances are too low – In the event you set quick cache lifespans, it’s probably extra customers will obtain uncached content material.
- You aren’t preloading your cache – In the event you want your cache to run out typically (as content material adjustments incessantly), somewhat than letting customers hit uncached URLs, use a preloader bot that may prime the cache, comparable to Optimus Cache Preloader.
Sidenote.
I completely advocate establishing HTML edge-caching through Cloudflare, which considerably reduces TTFB. You are able to do this simply with WordPress and Cloudflare’s Automated Platform Optimization.
12. Examine which bots crawl your website the most
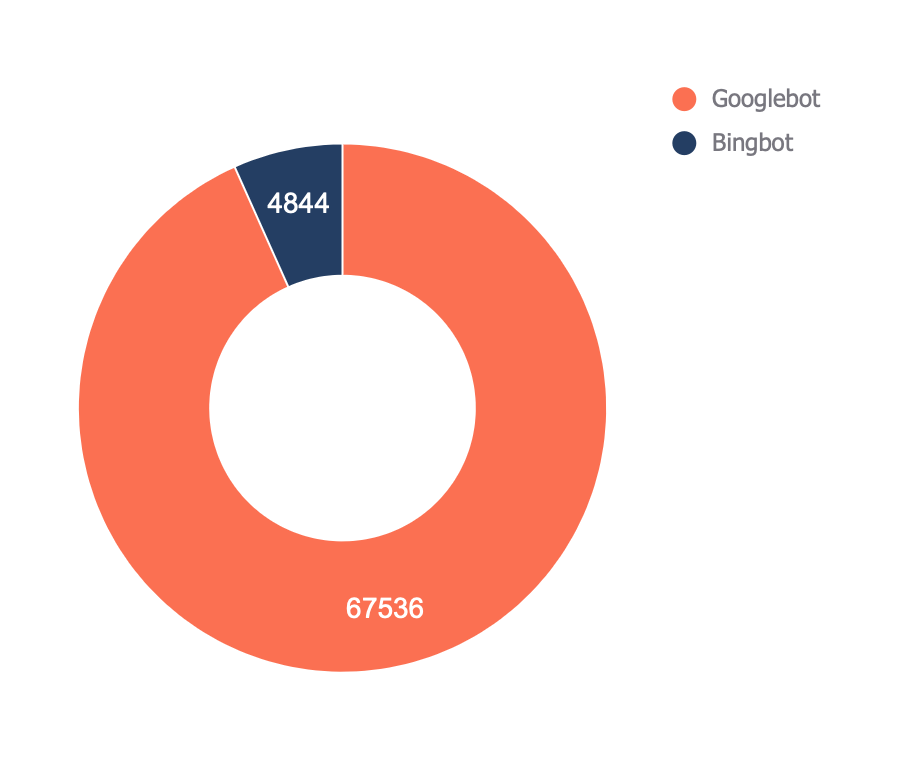
The ultimate report (discovered within the “Bots — Overview” tab) exhibits you which ones bots crawl your website the most:
Within the “Bots — Crawl pattern” report, you’ll be able to see how that pattern has modified over time.
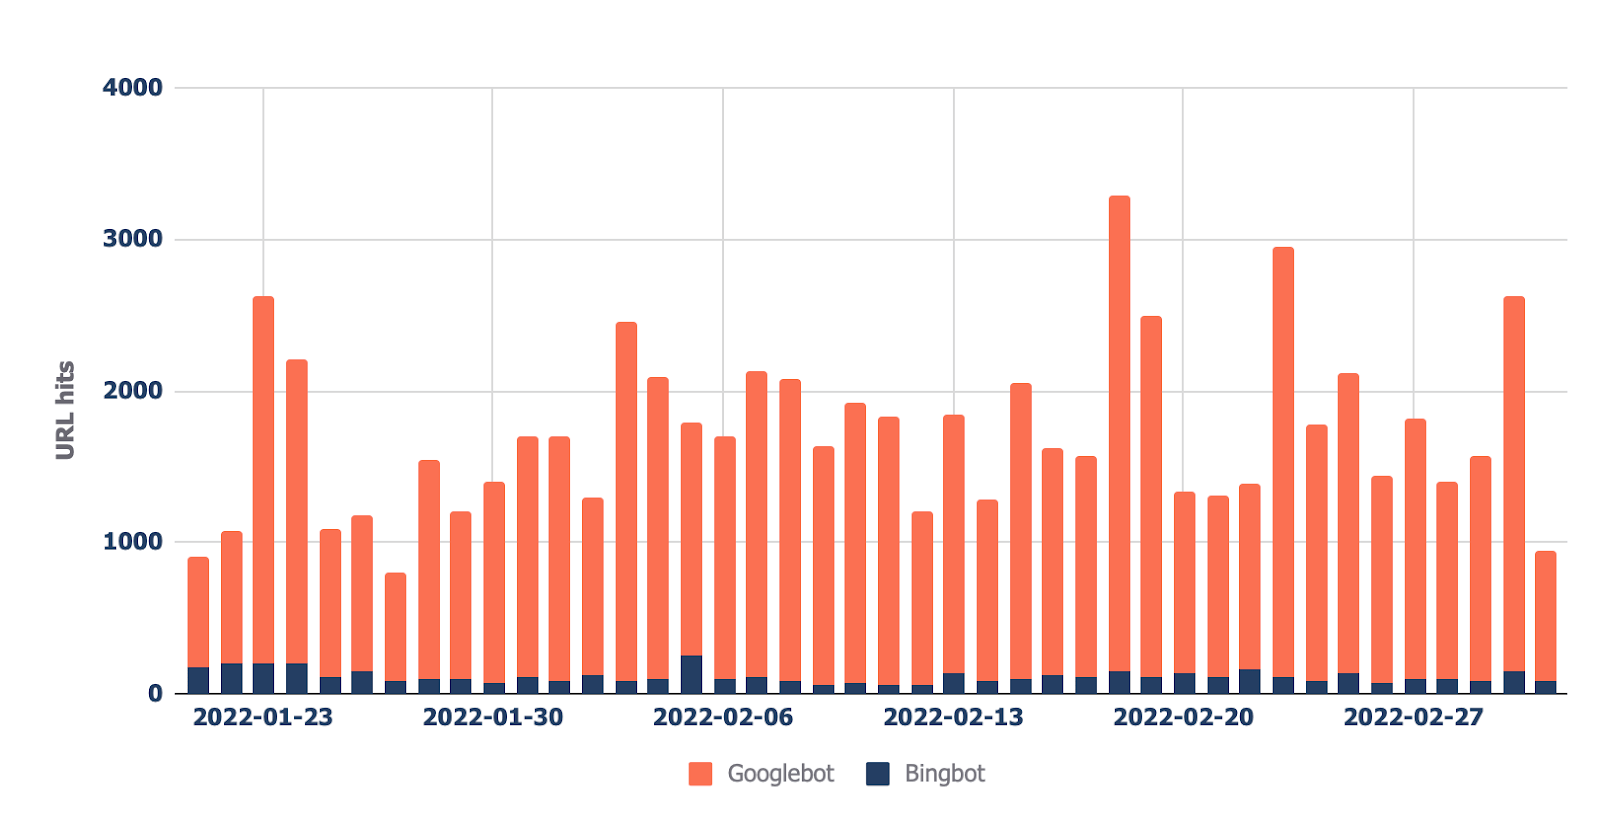
This report may help verify if there’s a rise in bot exercise in your website. It’s additionally useful when you’ve not too long ago made a big change, comparable to a URL migration, and need to see if bots have elevated their crawling to gather new knowledge.
Last ideas
You must now have a good suggestion of the evaluation you are able to do together with your log information when auditing a website. Hopefully, you’ll discover it straightforward to make use of my template and do that evaluation your self.
Something distinctive you’re doing together with your log information that I haven’t talked about? Tweet me.
[ad_2]

