


[ad_1]
Databricks’ Lakehouse platform empowers organizations to construct scalable and resilient knowledge platforms that permit them to drive worth from their knowledge. As the quantity of information has exploded during the last many years, an increasing number of restrictions have are available place to guard knowledge homeowners and knowledge firms almost about knowledge utilization. Laws like California Client Privateness Act (CCPA) and Basic Knowledge Safety Regulation (GDPR) emerged, and compliance with these rules is a necessity. Amongst different knowledge administration and knowledge governance necessities, these rules require companies to probably delete all private details about a shopper upon request. On this weblog put up we discover the methods to adjust to this requirement whereas using the Lakehouse structure with Delta Lake.
Earlier than we dive deep into the technical particulars, let’s paint the larger image.
Identification + Knowledge = Idatity
We didn’t invent this time period, however we completely find it irresistible! It merges the 2 focal factors of any group that operates within the digital area. The right way to determine their clients – id, and the best way to describe their clients – knowledge. The time period was initially coined by William James Adams Jr. (extra generally often known as will.i.am). The well-known rapper first used this time period throughout the World Financial Discussion board again in 2014 (see). In an try to postulate what people and organizations will care about in 2019 he mentioned “Idatity” – and he was spot on!
Only a few months earlier than the beginning of 2019, in Might 2018, EU Basic Knowledge Safety Regulation (GDPR) got here into impact. To be honest, GDPR was adopted in 2016 however solely turned enforceable starting Might 25, 2018. This laws is aimed to assist people shield their knowledge and outline rights one has over their knowledge (particulars). An identical act, California Client Privateness Act (CCPA) was launched in the US in 2018 and got here into impact on January 1, 2020.
Homo digitalis
This new species thrives in a habitat with omnipresent and completely linked screens and shows (see).
The information and id are actually gaining their deserved degree of consideration. If we observe people from an Web of Issues angle, we shortly notice that every considered one of us generates insane quantities of information in every passing second. Our telephones, laptops, toothbrushes, toasters, fridges, vehicles – all of them are units that emit knowledge. The road between the digital world and the bodily world is getting ever extra blurred.
We as a species are on a journey to transcend the bodily world – the primary earthly species that left the earth (in a much less bodily method). Much like the bodily world, guidelines of engagement are required in an effort to shield the inhabitants of this courageous new digital world.
That is exactly why basic knowledge safety rules such because the aforementioned GDPR and CCPA are essential to guard knowledge topics.
Definition of ‘Private knowledge’
Based on GDPR, private knowledge refers to any data referring to an recognized or identifiable pure particular person (‘knowledge topic’); an identifiable pure particular person is one who may be recognized, immediately or not directly, particularly by reference to an identifier reminiscent of a reputation, an identification quantity, location knowledge, a web-based identifier or to a number of components particular to the bodily, physiological, genetic, psychological, financial, cultural or social id of that pure particular person.
Based on CCPA, private knowledge refers to any data that identifies, pertains to, describes, is fairly able to being related to, or might fairly be linked, immediately or not directly, with a specific shopper or family.
One factor price noting is that these legislations aren’t actual copies of one another. Within the definitions above, we will notice that CCPA has a broader definition of what private knowledge is by referring to a family whereas GDPR refers to a person. This doesn’t imply that methods mentioned on this article should not relevant to CCPA, it merely signifies that on account of broader utility of CCPA additional design issues could also be wanted.
The appropriate to be forgotten
The main focus of our weblog will likely be on the “proper to be forgotten” (or the “proper to erasure”), one of many key points lined by the final knowledge safety rules such because the aforementioned GDPR and CCPA. “The appropriate to be forgotten” article regulates the info erasure obligations. Based on this text, private knowledge have to be erased with out undue delay [typically within 30 days of receipt of request] the place the info are now not wanted for his or her authentic processing goal, the info topic has withdrawn their consent and there’s no different authorized floor for processing, the info topic has objected and there are not any overriding legit grounds for the processing, or erasure is required to meet a statutory obligation beneath the EU legislation or the fitting of the Member States … (for full set of obligations see).
Is my knowledge used appropriately? Is my knowledge used solely whereas it’s wanted? Am I leaving knowledge breadcrumbs everywhere in the web? Can my knowledge find yourself within the fallacious fingers? These are certainly critical questions. Scary even. “The appropriate to be forgotten” addresses these issues and is designed to offer a degree of safety to the info topic. In a really simplified method we will learn “the fitting to be forgotten”: we’ve the fitting to have our knowledge deleted if the info processor doesn’t want it to offer us a service and/or if we’ve explicitly requested that they delete our knowledge.
Overlook-me-nots are costly!
Behind our floral association lies a not so hidden message about fines and penalties in case of information safety violations in accordance with GDPR. Based on Artwork. 83 GDPR the penalties can vary from 10 million euros or 2% in case of endeavor (whichever is greater) for much less extreme violations to twenty million euros or 4% within the case of endeavor for extra critical violations (see). These solely embrace regulator imposed penalties – injury to status and model injury are a lot tougher to quantify. The examples of those regulatory actions are many, as an example, Google bought fined $8 million by Sweden’s Knowledge Safety Authority (DPA) again in March 2020 (see extra) for the improper disposal of search end result hyperlinks.
On the planet of massive knowledge, enforcement of GDPR, or in our case, “the fitting to be forgotten” is usually a large problem. Nonetheless, the dangers hooked up to it are just too excessive for any group to disregard this use case for his or her knowledge.
ACID + Time Journey = Legislation abiding knowledge
We consider that Delta is the gold commonplace format for storing knowledge within the Databricks Lakehouse platform. With it, we will assure that our knowledge is saved with good governance and efficiency in thoughts. Delta helps that tables in our Delta lake (lakehouse storage layer) are ACID (atomic, constant, remoted, sturdy).
On high of bringing the consistency and governance of information warehouses to the lakehouse, Delta permits us to take care of the model historical past of our tables. Each atomic operation on high of a Delta desk will end in a brand new model of the desk. Every model will include details about the info commit and the parquet information which might be added/eliminated on this model (see). These variations may be referenced by way of the model quantity or by the logical timestamp. Shifting between variations is what we confer with as “Delta Time Journey”. Take a look at a hands-on demo should you’d wish to be taught extra about Delta Time Journey.
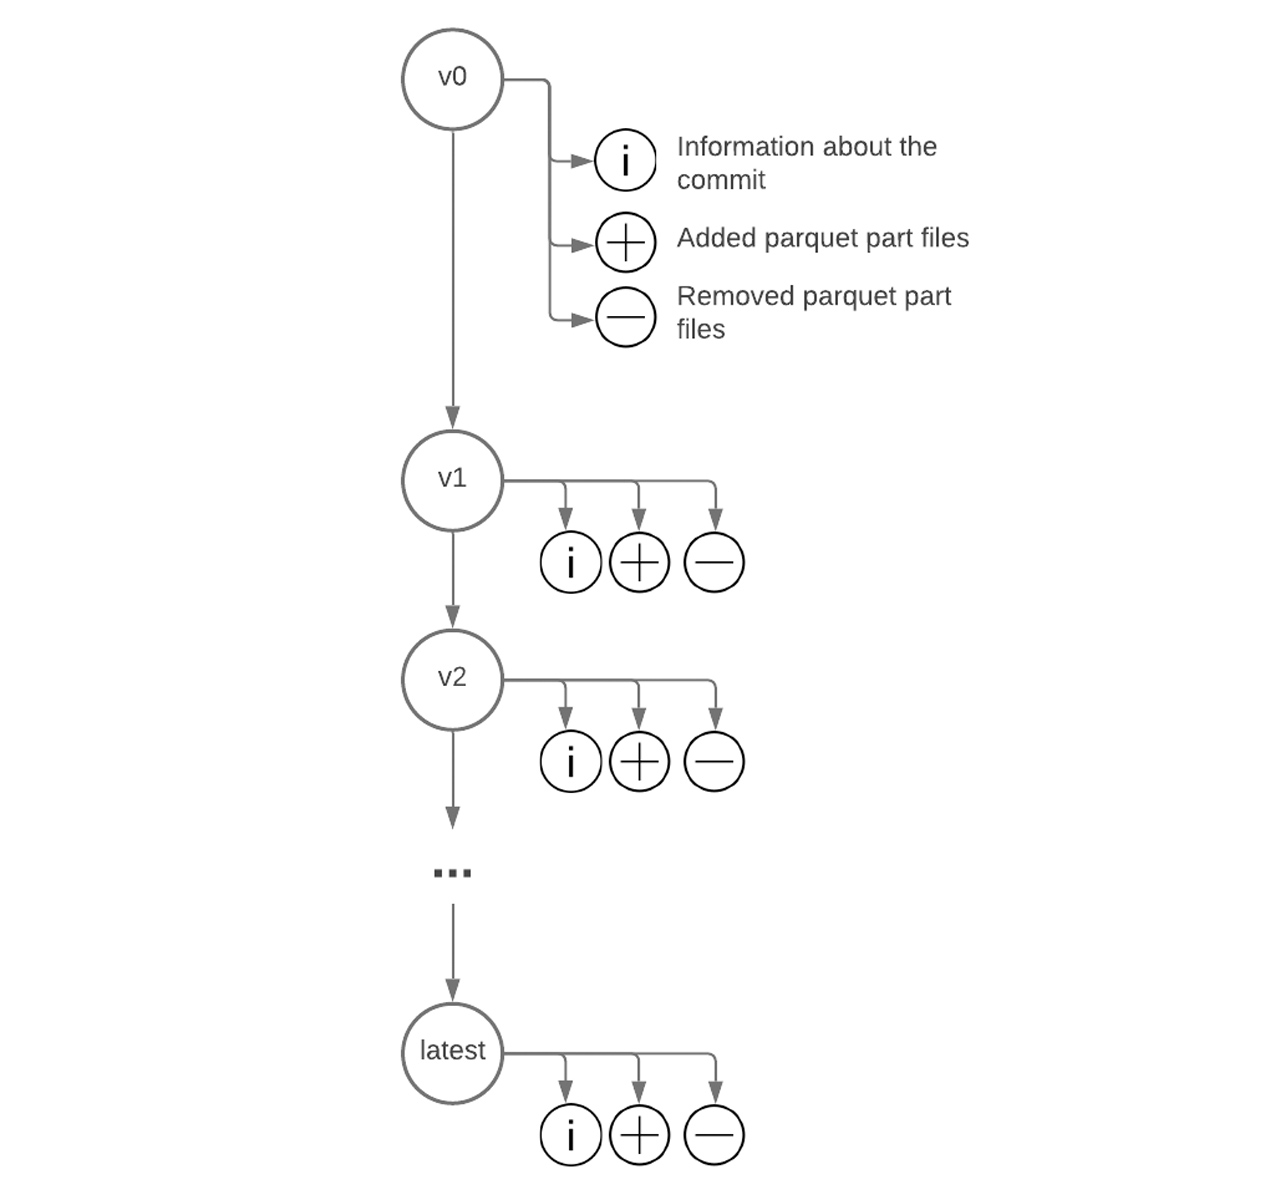
Having our knowledge nicely maintained and utilizing applied sciences that function with the info/tables in an atomic method may be of vital significance for GDPR compliance. Such applied sciences carry out writes in a coherent method – both all ensuing rows are written out or knowledge stays unchanged – this successfully avoids knowledge leakage on account of partial writes.
Whereas Delta Time Journey is a robust instrument, it nonetheless needs to be used inside the area of motive. Storing a historical past that’s too lengthy may cause efficiency degradation. This could occur each on account of accumulation of an excessive amount of knowledge and metadata required for model management.
Let’s take a look at a few of the potential approaches to implementing the “proper to be forgotten” requirement in your knowledge lake. Though the main focus of this weblog put up is principally on Delta lake, it’s important to have correct mechanisms in place to make all elements of the info platform compliant with rules. As a lot of the knowledge resides within the cloud storage, organising retention insurance policies is among the greatest practices.
Method 1 – Knowledge Amnesia
With Delta, we’ve yet one more instrument at our disposal to handle GDPR compliance and, particularly, “the fitting to be forgotten” – VACUUM. Vacuum operation removes the information which might be now not wanted and which might be older than a predefined retention interval. The default retention interval is 30 days to align with GDPR definition of undue delay. Our earlier weblog on an analogous matter explains intimately how you will discover and delete private data associated to a shopper by operating two instructions:
DELETE FROM knowledge WHERE e-mail = ‘shopper@area.com’;
VACUUM knowledge;
Completely different layers within the medallion structure might have completely different retention durations related to their Delta tables.
With Vacuum, we completely take away knowledge that requires erasure from our Delta desk. Nonetheless, Vacuum removes all of the variations of our desk which might be older than the retention interval. This leaves us in a scenario of digital obsolescence – knowledge amnesia. We’ve successfully eliminated the info we would have liked to, however within the course of we’ve deleted the evolutionary lineage of our desk. In easy phrases, we’ve restricted our capacity to time journey by means of the historical past of our Delta tables.
This reduces our capacity to retain the audit path of the info transformations that have been carried out on our Delta tables. Can’t we simply have each the erasure assurance and audit path? Let’s look into different potentialities.
Method 2 – Anonymization
One other method of defining “deletion of information” is remodeling the info in a method that can’t be reversed. This fashion the unique knowledge is destroyed however our capacity to extract statistical data will likely be preserved. If we observe “the fitting to be forgotten” requirement from this angle, we will apply transformations to the info in order that the particular person can’t be recognized by the knowledge obtained after these transformations. Throughout the many years of software program practices, an increasing number of refined methods have been developed to anonymise knowledge. Whereas anonymization is a extensively used strategy, it has some downsides.
The primary problem with anonymization is that it needs to be a part of the engineering practices from the very starting. Introducing it at later levels results in inconsistent state of the info storage with the likelihood that extremely delicate knowledge is made out there for the broad viewers by mistake. This strategy will work tremendous with small (when it comes to variety of columns) datasets and when utilized from the very starting of the event course of.
Method 3 – Pseudonymization/Normalized tables
Normalizing tables is a standard follow within the relational database world. All of us have heard about six generally used normalized types (or not less than a subset of them). Within the space of information warehouses this strategy developed into dimensional knowledge modeling, when knowledge shouldn’t be strictly normalized however offered in a type of information and dimensions. Throughout the area of massive knowledge applied sciences, normalization turned a much less extensively used instrument.
Within the case of “the fitting to be forgotten” requirement, normalization (or pseudonymization) can really result in a potential resolution. Let’s think about a Delta desk that accommodates ‘personally identifiable data’ (PII) columns and knowledge (not PII) columns. Fairly than deleting all information we will break up the desk into two:
- PII desk that accommodates delicate knowledge
- All different knowledge that’s not delicate and loses its capacity to determine an individual with out the opposite desk
On this case, we will nonetheless apply the strategy of “knowledge amnesia” to the primary desk and maintain the primary dataset intacted. This strategy has the next advantages:
- It’s fairly simple to implement
- It provides the likelihood to maintain the a lot of the knowledge out there for reuse (as an example for the ML fashions) whereas being compliant with rules
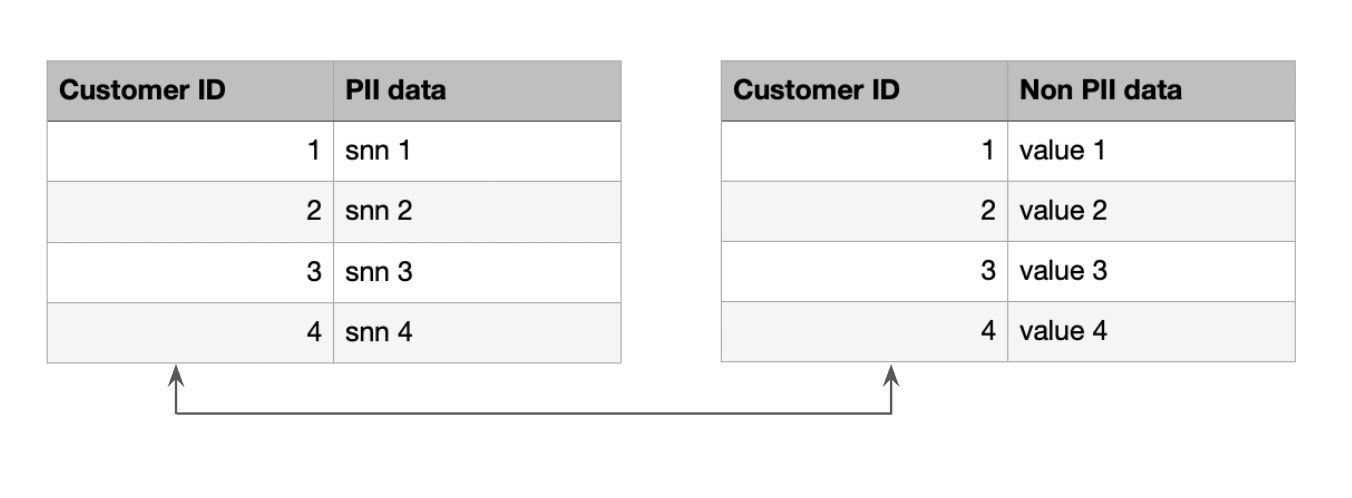
Whereas it feels like a superb strategy, we must also contemplate the draw back of it. Normalization/Pseudonymization comes hand in hand with the need to hitch datasets, which results in surprising prices and efficiency penalties. When normalization means splitting one desk into two, this strategy may be affordable, however with out management it could possibly simply go into a number of tables simply to get easy data from the dataset. Additionally splitting tables in PII and non-PII knowledge can shortly result in doubling of the variety of tables and inflicting knowledge governance hell.
One other caveat to remember is: with out management, it introduces ambiguity in knowledge construction. Say for instance, you’ll want to prolong your knowledge with a brand new column, the place are you going so as to add it: to the PII and non-PII desk?
This strategy works the perfect if the group is already utilizing normalized datasets, both with Delta or migrating to Delta. If the normalization is already part of knowledge structure, then implementing “knowledge amnesia” to solely PII knowledge is a logical strategy.
Method 4 – Selective reminiscence loss
While the aforementioned strategy to search out and completely delete buyer data may also help maintain you GDPR/CCPA compliant, operating the VACUUM on a Delta desk successfully curtails your capacity to time journey again to a model older than the required knowledge retention interval. It additionally may be tough to implement different approaches when you might have robust necessities for knowledge structure. Selective reminiscence loss provides the power to take away particular information from all variations of the Delta desk whereas holding different information intact.
This resolution is much less damaging in comparison with the Vacuum strategy. The first use case for this resolution is eradicating information from Delta tables whereas holding all variations on the Delta desk, so you’ll be able to proceed to make use of them on your analytics and machine studying use circumstances. The answer leverages Delta log performance to take away pointless knowledge. That is achieved by ingesting all parquet information from the Delta desk of curiosity and changing those that include to-be-removed information. The alternative half information will include all the unique knowledge besides the to-be-removed information.

This conduct may be achieved by way of a mixture of PySpark and PyArrow. PySpark is utilized to distribute the processing of historic half information and PyArrow to attain environment friendly filtering of particular person half information.
Though it lets you maintain all variations of the Delta desk and structure of information unchanged, there are a few issues to remember:
- Earlier than operating this operation, it’s necessary to configure the upstreams to cease writing to-be-removed information into the Delta desk
- As the answer is overwriting parquet information, this operation may be time consuming and should require a comparatively giant Spark cluster for bigger Delta tables
- This resolution requires recomputation of metadata related to every commit
- This resolution relaxes the requirement of immutability of delta commits – the mutable operations may be restricted to a devoted system account
The answer is offered as a demo pocket book that accommodates code alongside in depth descriptions. Moreover, the offered pocket book may be automated as a recurring job (ie. weekly/month-to-month).
Let’s take a look at a real-life instance to know how you may make use of the demo pocket book. Assume we’ve a desk that seems one thing like this:

And also you want to selectively delete rows based mostly on the `member_id` column, the place its values are 8 or 31. That is how you may invoke the pocket book with the requisite parameter.
dbutils.pocket book.run("02-UpdateInPlace", 60, {"filtered_list": "8, 31", "column_name": "member_id", "table_location":, "table_name": }) Given the truth that Delta Selective Reminiscence Loss is modifying the info and related metadata it does include a set of constraints:
- The answer shouldn’t be supported along with databricks.io.cache, as the present model of the library doesn’t help cache invalidation. This limitation may be overcome by disabling the cache or by restarting the cluster after removing is full. We suggested utilization of a devoted cluster for this operation. With this in thoughts and the truth that knowledge gained’t be reused throughout the runtime of the job, we argue that delta.io.cache shouldn’t be obligatory on this slender context of utility.
- The answer shouldn’t be supported along with DELTA_OPTIMIZE_METADATA_QUERY_ENABLED. Optimize metadata queries needs to be disabled.
- Deletes should not mechanically propagated to the Deep clone of the desk. That’s why knowledge removing ought to run on each tables.
Conclusion
On this weblog put up we’ve lined “the fitting to be forgotten” inside the area of GDPR/CCPA and its implications when implementing a Delta Lake inside the Databricks Lakehouse structure. We’ve mentioned a number of completely different approaches and we’ve proposed a novel strategy utilizing PySpark and PyArrow. And whereas this strategy does include sure limitations, it does present a superb tradeoff between the power to purge information from the entire Delta model historical past and sustaining the mentioned model historical past. This in impact preserves the most important superset of operations we will carry out on high of affected Delta tables. Utilizing this resolution one can preserve auditability of their tables and adjust to “the fitting to be forgotten” on the similar time.
Get began
To get began with the Selective Reminiscence Loss resolution try this pocket book. We hope you’ll be able to profit from this resolution. If in case you have an attention-grabbing use case and need to share the suggestions on this resolution, contact us!
[ad_2]

