


[ad_1]
Due to “Bundlegate”, it’s been a wild couple of weeks. Right here’s what occurred and the place I feel we’re going.
It’s been a wild couple of weeks in Knowledge Twitter with one other new scorching debate.
As I lay tossing and handing over mattress, desirous about the way forward for the fashionable knowledge stack, I couldn’t assist really feel the stress to jot down one more opinion piece 😉
What truly occurred?
In case you have been MIA, Gorkem Yurtseven kickstarted this debate with an article known as “The Unbundling of Airflow”.
He defined that when small merchandise turn out to be giant platforms, they’re ripe for unbundling, or having its element features abstracted into small, extra targeted merchandise. Craigslist is a good instance — its Neighborhood part has been taken over by Nextdoor, Personals by Tinder, Dialogue Boards by Reddit, For Sale by OfferUp, and so forth.
Gorkem argued that within the knowledge world, the identical factor is occurring with Airflow.
Earlier than the fragmentation of the information stack, it wasn’t unusual to create end-to-end pipelines with Airflow. Organizations used to construct nearly complete knowledge workflows as customized scripts developed by in-house knowledge engineers. Greater corporations even constructed their very own frameworks inside Airflow, for instance, frameworks with dbt-like performance for SQL transformations to be able to make it simpler for knowledge analysts to jot down these pipelines.
At the moment, knowledge practitioners have many instruments below their belt and solely very hardly ever they’ve to achieve for a device like Airflow… If the unbundling of Airflow means all of the heavy lifting is completed by separate instruments, what’s left behind?
Gorkem Yurtseven
As one of many knowledge groups again within the day that ended up constructing our personal dbt-like performance for transformations in R and Python, Gorkem’s phrases hit residence.
Airflow’s functions have been constructed into ingestion instruments (Airbyte, Fivetran, and Meltano), transformation layers (dbt), reverse ETL (Hightouch and Census), and extra.
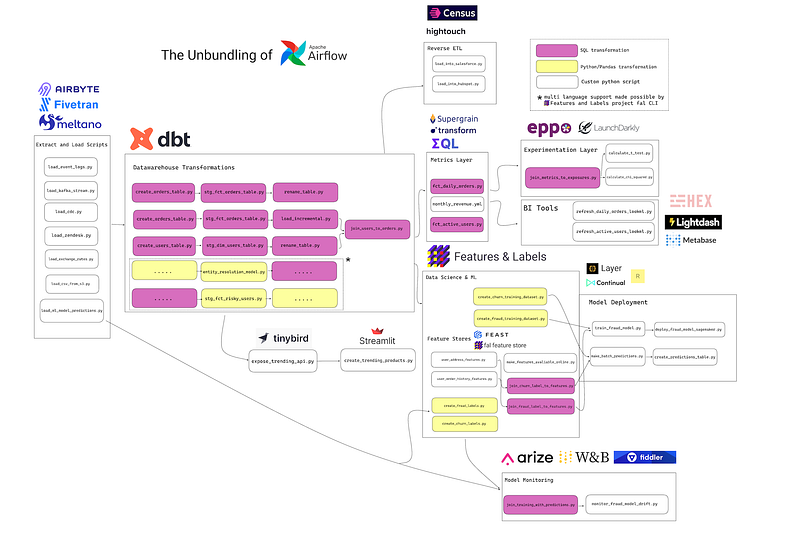
Sadly, this has led to a loopy quantity of fragmentation within the knowledge stack. I joke about this lots, however actually I really feel horrible for somebody shopping for knowledge know-how proper now. The fragmentation and overlaps are mind-blowing for even an insider like me to totally grasp.
Nick Schrock from Elementl wrote a response on Dagster’s weblog titled the “Rebundling of the Knowledge Platform” that broke the information neighborhood… once more. He agreed with Gorkem that the information stack was being unbundled, and stated that this unbundling was creating its personal set of issues.
I don’t assume anybody believes that this is a perfect finish state. The put up itself advocates for consolidation. Having this many instruments with out a coherent, centralized management aircraft is lunacy, and a horrible endstate for knowledge practitioners and their stakeholders… And but, that is the fact we’re slouching towards on this “unbundled” world.
Nick Schrock
Then, whereas I used to be writing this text, Ananth Packkildurai chimed in on the controversy — first with a tweet after which with the most recent challenge of his Knowledge Engineering Weekly e-newsletter.
Ananth agreed with the concept that unbundling has occurred, however tied it to a bigger challenge. As knowledge groups and firms have grown, knowledge has turn out to be extra complicated and knowledge orchestration, high quality, lineage, and mannequin administration have turn out to be important issues.
The info stack unbundled to resolve these particular issues, which simply resulted in siloed, “duct tape methods”.
The info neighborhood usually compares the fashionable tech stack with the Unix philosophy. Nonetheless, we’re lacking the working system for the information. We have to merge each the mannequin and activity execution unit into one unit. In any other case, any abstraction we construct with out the unification will additional amplify the disorganization of the information. The info as an asset will stay an aspirational aim.
Ananth Packkildurai
So… what’s my take? The place are we headed?
There are two varieties of individuals within the knowledge world — those that imagine in bundling and people who assume unbundling is the longer term.
I imagine that the reply lies someplace within the center. Listed here are a few of my predictions and takes.
1. There’ll completely be extra bundling from our present model of the fashionable knowledge stack.
The present model of the fashionable knowledge stack, with a brand new firm launching each 45 minutes, is unsustainable. We’re completely in the midst of the golden period of innovation within the MDS, funded fairly generously by Enterprise Capital $$ — all in seek for the subsequent Snowflake. I’ve heard tales of completely glad (knowledge) product managers in FAANG corporations being handed tens of millions of {dollars} to “check out any thought”.
This euphoria has had large benefits. A ton of good persons are fixing knowledge groups’ greatest tooling challenges. Their work has made the fashionable knowledge stack a factor. It has made the “knowledge operate” extra mainstream. And, most significantly, it has spurred innovation.
However, actually, this received’t final endlessly. The money will dry up. Consolidation, mergers, and acquisitions will occur. (We’ve already began seeing glimpses of this with dbt’s transfer into the metrics layer and Hevo’s transfer to introduce reverse ETL together with their knowledge ingestion product.) Most significantly, prospects will begin demanding much less complexity as they make selections about their knowledge stack. That is the place bundling will begin to win.
2. Nonetheless, we by no means will (and shouldn’t ever) have a completely bundled knowledge stack.
Consider it or not, the information world began off with the imaginative and prescient of a completely bundled knowledge stack. A decade in the past, corporations like RJ Metrics and Domo aimed to create their very own holistic knowledge platforms.
The problem with a completely bundled stack is that assets are at all times restricted and innovation stalls. This hole will create a chance for unbundling, and so I imagine we’ll undergo cycles of bundling and unbundling. That being stated, I imagine that the information area particularly has peculiarities that make it tough for bundled platforms to really win.
My co-founder Varun and I spend a ton of time desirous about the DNA of corporations or merchandise. We predict it’s essential — maybe crucial factor that defines who succeeds in a class of product.
Let’s have a look at the cloud battles. AWS, for instance, has at all times been largely targeted on scale —one thing they do an awesome job in. Then again, Azure coming from Microsoft has at all times had a extra end-user-focused DNA, stemming from its MS Workplace days. It’s no shock that AWS doesn’t do as properly in creating world-class, consumer expertise–targeted purposes as Azure, whereas Azure doesn’t do as properly in scaling technical workloads as AWS.
Earlier than we will discuss in regards to the DNA of the information world, we’ve to acknowledge that its sheer variety. The people of information are knowledge engineers, analysts, analytics engineers, scientists, product managers, enterprise analysts, citizen scientists, and extra. Every of those individuals has their very own favourite and equally numerous knowledge instruments, every thing from SQL, Looker, and Jupyter to Python, Tableau, dbt, and R. And knowledge initiatives have their very own technical necessities and peculiarities — some want real-time processing whereas some want pace for ad-hoc evaluation, resulting in an entire host of information infrastructure applied sciences (warehouses, lakehouses, and every thing in between).
Due to this variety, the know-how for every of those completely different personas and use circumstances every could have very completely different DNA. For instance, an organization constructing BI ought to be targeted on the end-user expertise, whereas firm constructing an information warehouse ought to be targeted on reliability and scaling.
This is the reason I imagine that whereas bundling will occur, it can solely occur in areas the place merchandise’ basic DNA is comparable. For instance, we are going to seemingly see knowledge high quality merge with knowledge transformation, and doubtlessly knowledge ingestion merge with reverse ETL. Nonetheless, we most likely received’t see knowledge high quality bundled with reverse ETL.
3. Metadata holds the important thing to unlocking concord in a various knowledge stack.
Whereas we’ll see extra consolidation, the basic variety of information and the people of information isn’t going away. There’ll at all times be use circumstances the place Python is best than SQL or real-time processing is best than batch, and vice versa.
In case you perceive this basic actuality, you need to cease trying to find a future with a common “bundled knowledge platform” that works for everybody — and as a substitute discover methods for the varied components of our unbundled knowledge stack to work collectively, in good concord.
Knowledge is chaos. That doesn’t imply that work must be.
I imagine that the important thing to serving to our knowledge stack work collectively is in activating metadata. We’ve solely scratched the floor of what metadata can do for us, however utilizing metadata to its fullest potential can basically change how our knowledge methods function.
At the moment, metadata is used for (comparatively) simplistic use circumstances like knowledge discovery and knowledge catalogs. We take a bunch of metadata from a bunch of instruments and put it right into a device we name the information catalog or the information governance device. The issue with this method is that it mainly provides yet another siloed device to an already siloed knowledge stack.
As an alternative, take a second and picture what a world might appear to be when you might have a Section or Zapier-like expertise within the fashionable knowledge stack — the place metadata can create concord throughout all our instruments and energy good experiences.
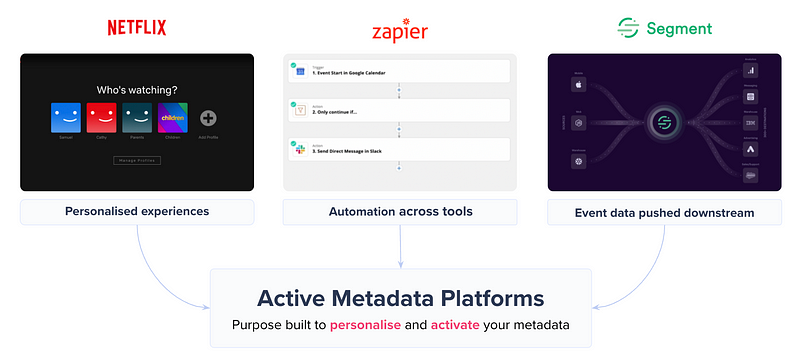
For instance, one use case for metadata activation might be so simple as notifying downstream shoppers of upstream adjustments.
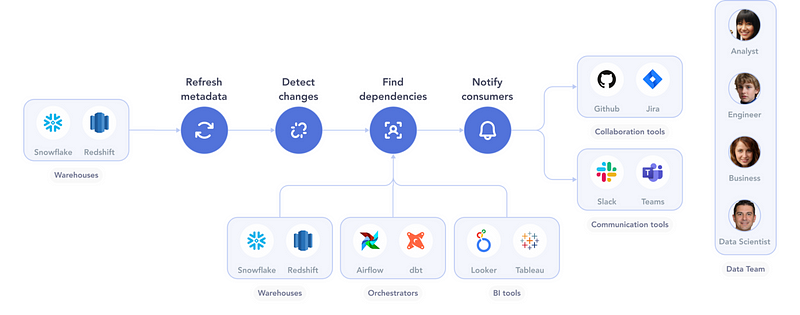
A Zap-like workflow for this straightforward course of might appear to be this:
When an information retailer adjustments…
- Refresh metadata: Crawl the information retailer to retrieve its up to date metadata.
- Detect adjustments: Examine the brand new metadata towards the earlier metadata. Establish any adjustments that might trigger an affect — including or eradicating columns, for instance.
- Discover dependencies: Use lineage to search out customers of the information retailer. These might embrace transformation processes, different knowledge shops, BI dashboards, and so forth.
- Notify shoppers: Notify every shopper by means of their most popular communication channel — Slack, Jira, and many others.
This workflow may be integrated as a part of the testing phases of fixing an information retailer. For instance, the CI/CD course of that adjustments the information retailer might additionally set off this workflow. Orchestration can then notify shoppers earlier than manufacturing methods change.
In Stephen Bailey’s phrases, “Nobody is aware of what the information stack will appear to be in ten years, however I can assure you this: metadata would be the glue.”
I feel this debate is way from over, nevertheless it’s superb what number of insights and scorching takes (like this one) that it has stirred up.
To maintain the dialogue going, we’re internet hosting Gorkem Yurtseven, Nick Schrock, and Ananth Packkildurai for our Nice Knowledge Debate on Tuesday, 15 March.
Join the digital occasion right here: https://atlan.com/great-data-debate/
Header picture: Bakhrom Tursunov on Unsplash
[ad_2]

