



[ad_1]
Lately, we’ve got seen dramatic enhancements on lexical duties comparable to computerized speech recognition (ASR). Nevertheless, machine methods nonetheless battle to know paralinguistic features — comparable to tone, emotion, whether or not a speaker is sporting a masks, and so forth. Understanding these features represents one of many remaining tough issues in machine listening to. As well as, state-of-the-art outcomes usually come from ultra-large fashions educated on personal knowledge, making them impractical to run on cellular gadgets or to launch publicly.
In “Common Paralinguistic Speech Representations Utilizing Self-Supervised Conformers”, to look in ICASSP 2022, we introduce CAP12— the twelfth layer of a 600M parameter mannequin educated on the YT-U coaching dataset utilizing self-supervision. We display that the CAP12 mannequin outperforms practically all earlier ends in our paralinguistic benchmark, generally by giant margins, although earlier outcomes are sometimes task-specific. In “TRILLsson: Distilled Common Paralinguistic Speech Representations”, we introduce the small, performant, publicly-available TRILLsson fashions and display how we lowered the dimensions of the high-performing CAP12 mannequin by 6x-100x whereas sustaining 90-96% of the efficiency. To create TRILLsson, we apply data distillation on appropriately-sized audio chunks and use completely different structure sorts to coach smaller, sooner networks which are sufficiently small to run on cellular gadgets.
1M-Hour Dataset to Practice Extremely-Giant Self-Supervised Fashions
We leverage the YT-U coaching dataset to coach the ultra-large, self-supervised CAP12 mannequin. The YT-U dataset is a extremely various, 900M+ hour dataset that incorporates audio of varied matters, background situations, and speaker acoustic properties.
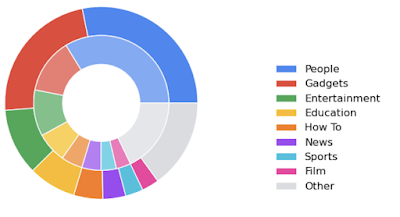 |
| Video classes by size (outer) and quantity (internal), demonstrating the range within the YT-U dataset (determine from BigSSL) |
We then modify a Wav2Vec 2.0 self-supervised coaching paradigm, which may remedy duties utilizing uncooked knowledge with out labels, and mix it with ultra-large Conformer fashions. As a result of self-training would not require labels, we are able to take full benefit of YT-U by scaling up our fashions to a number of the largest mannequin sizes ever educated, together with 600M, 1B, and 8B parameters.
NOSS: A Benchmark for Paralinguistic Duties
We display that an intermediate illustration of one of many earlier fashions incorporates a state-of-the-art illustration for paralinguistic speech. We name the 600M parameter Conformer mannequin with out relative consideration Conformer Utilized to Paralinguistics (CAP). We exhaustively search by means of all intermediate representations of six ultra-large fashions and discover that layer 12 (CAP12) outperforms earlier representations by vital margins.
To measure the standard of the roughly 300 candidate paralinguistic speech representations, we consider on an expanded model of the NOn-Semantic Speech (NOSS) benchmark, which is a set of well-studied paralinguistic speech duties, comparable to speech emotion recognition, language identification, and speaker identification. These duties deal with paralinguistics features of speech, which require evaluating speech options on the order of 1 second or longer, reasonably than lexical options, which require 100ms or shorter. We then add to the benchmark a mask-wearing process launched at Interspeech 2020, a faux speech detection process (ASVSpoof 2019), a process to detect the extent of dysarthria from mission Euphonia, and an extra speech emotion recognition process (IEMOCAP). By increasing the benchmark and growing the variety of the duties, we empirically display that CAP12 is much more usually helpful than earlier representations.
Easy linear fashions on time-averaged CAP12 representations even outperform complicated, task-specific fashions on 5 out of eight paralinguistic duties. That is shocking as a result of comparable fashions generally use extra modalities (e.g., imaginative and prescient and speech, or textual content and speech) as effectively. Moreover, CAP12 is exceptionally good at emotion recognition duties. CAP12 embeddings additionally outperform all different embeddings on all different duties with solely a single exception: for one embedding from a supervised community on the dysarthria detection process.
| Mannequin | Voxceleb† | Voxforge | Speech Instructions | ASVSpoof2019∗∗ | Euphonia# | CREMA-D | IEMOCAP |
| Prev SoTA | – | 95.4 | 97.9 | 5.11 | 45.9 | 74.0∗ | 67.6+ |
| TRILL | 12.6 | 84.5 | 77.6 | 74.6 | 48.1 | 65.7 | 54.3 |
| ASR Embedding | 5.2 | 98.9 | 96.1 | 11.2 | 54.5 | 71.8 | 65.4 |
| Wav2Vec2 layer 6†† | 17.9 | 98.5 | 95.0 | 6.7 | 48.2 | 77.4 | 65.8 |
| CAP12 | 51.0 | 99.7 | 97.0 | 2.5 | 51.5 | 88.2 | 75.0 |
| Check efficiency on the NOSS Benchmark and prolonged duties. “Prev SoTA” signifies the earlier greatest performing state-of-the-art mannequin, which has arbitrary complexity, however all different rows are linear fashions on time-averaged enter. † Filtered in keeping with YouTube’s privateness tips. ∗∗ Makes use of equal error fee [20]. # The one private dataset. We exclude it from mixture scores. ∗ Audio and visible options utilized in earlier state-of-the-art fashions. + The earlier state-of-the-art mannequin carried out cross-validation. For our analysis, we maintain out two particular audio system as a take a look at. †† Wav2Vec 2.0 mannequin from HuggingFace. Greatest total layer was layer 6. |
TRILLsson: Small, Excessive High quality, Publicly Obtainable Fashions
Just like FRILL, our subsequent step was to make an on-device, publicly accessible model of CAP12. This concerned utilizing data distillation to coach smaller, sooner, mobile-friendly architectures. We experimented with EfficientNet, Audio Spectrogram Transformer (AST), and ResNet. These mannequin sorts are very completely different, and canopy each fixed-length and arbitrary-length inputs. EfficientNet comes from a neural structure search over imaginative and prescient fashions to seek out concurrently performant and environment friendly mannequin buildings. AST fashions are transformers tailored to audio inputs. ResNet is a typical structure that has proven good efficiency throughout many alternative fashions.
We educated fashions that carried out on common 90-96% in addition to CAP12, regardless of being 1%-15% the dimensions and educated utilizing solely 6% the info. Apparently, we discovered that completely different structure sorts carried out higher at completely different sizes. ResNet fashions carried out greatest on the low finish, EfficientNet within the center, and AST fashions on the bigger finish.
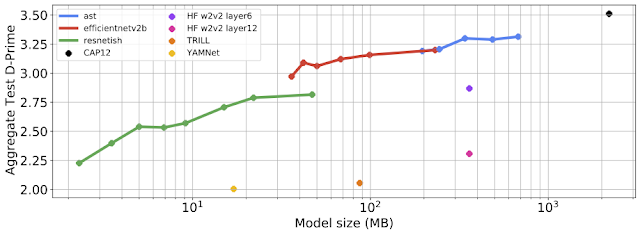 |
| Combination embedding efficiency vs. mannequin dimension for varied pupil mannequin architectures and sizes. We display that ResNet architectures carry out greatest for small sizes, EfficientNetV2 performs greatest within the midsize mannequin vary, as much as the biggest mannequin dimension examined, after which the bigger AST fashions are greatest. |
We carry out data distillation with the aim of matching a pupil, with a fixed-size enter, to the output of a instructor, with a variable-size enter, for which there are two strategies of producing pupil targets: international matching and native matching. World matching produces distillation targets by producing CAP12 embeddings for a whole audio clip, after which requires {that a} pupil match the goal from only a small section of audio (e.g., 2 seconds). Native matching requires that the coed community match the common CAP12 embedding simply over the smaller portion of the audio that the coed sees. In our work, we targeted on native matching.
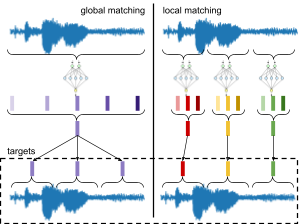 |
| Two sorts of producing distillation targets for sequences. Left: World matching makes use of the common CAP12 embedding over the entire clip for the goal for every native chunk. Proper: Native matching makes use of CAP12 embeddings averaged simply over native clips because the distillation goal. |
Remark of Bimodality and Future Instructions
Paralinguistic data exhibits an sudden bimodal distribution. For the CAP mannequin that operates on 500 ms enter segments, and two of the full-input Conformer fashions, intermediate representations progressively improve in paralinguistic data, then lower, then improve once more, and at last lose this data in the direction of the output layer. Surprisingly, this sample can also be seen when exploring the intermediate representations of networks educated on retinal pictures.
 |
| 500 ms inputs to CAP present a comparatively pronounced bimodal distribution of paralinguistic data throughout layers. |
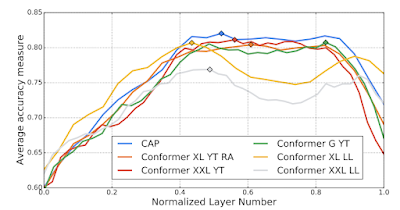 |
| Two of the conformer fashions with full inputs present a bimodal distribution of paralinguistic data throughout layers. |
We hope that smaller, sooner fashions for paralinguistic speech unlock new functions in speech recognition, text-to-speech technology, and understanding consumer intent. We additionally anticipate that smaller fashions might be extra simply interpretable, which is able to permit researchers to know what features of speech are vital for paralinguistics. Lastly, we hope that our open-sourced speech representations are utilized by the group to enhance paralinguistic speech duties and consumer understanding in personal or small datasets.
Acknowledgements
I would wish to thank my co-authors Aren Jansen, Wei Han, Daniel Park, Yu Zhang, and Subhashini Venugopalan for his or her onerous work and creativity on this mission. I would additionally wish to thank the members of the big collaboration for the BigSSL work, with out which these tasks wouldn’t be doable. The staff contains James Qin, Anmol Gulati, Yuanzhong Xu, Yanping Huang, Shibo Wang, Zongwei Zhou, Bo Li, Min Ma, William Chan, Jiahui Yu, Yongqiang Wang, Liangliang Cao, Khe Chai Sim, Bhuvana Ramabhadran, Tara N. Sainath, Françoise Beaufays, Zhifeng Chen, Quoc V. Le, Chung-Cheng Chiu, Ruoming Pang, and Yonghui Wu.
[ad_2]

