


[ad_1]
On this publish I discover tips on how to help analytical queries with out encountering prohibitive scan prices, by leveraging secondary indexes in DynamoDB. I additionally consider the professionals and cons of this strategy in distinction to extracting knowledge to a different system like Athena, Spark or Elastic.
Rockset just lately added help for DynamoDB – which principally means you may run quick SQL on DynamoDB tables with none ETL. As I spoke to our customers, I got here throughout other ways by which international secondary indexes (GSI) are used for analytical queries.
DynamoDB shops knowledge below the hood by partitioning it over a lot of nodes based mostly on a user-specified partition key subject current in every merchandise. This user-specified partition key could be optionally mixed with a kind key to signify a main key. The first key acts as an index, making question operations on it cheap. A question operation can do equality comparability (=) on the partition key and comparative operations (>, <, =, BETWEEN) on the type key if specified. Performing operations that aren’t coated by the above scheme requires the usage of a scan operation, which is usually executed by scanning over the complete DynamoDB desk in parallel. These scans could be sluggish and costly when it comes to Learn Capability Items (RCUs) as a result of they require a full learn of the complete desk. Scans additionally are inclined to decelerate when the desk dimension grows as there’s extra knowledge to scan to provide outcomes.
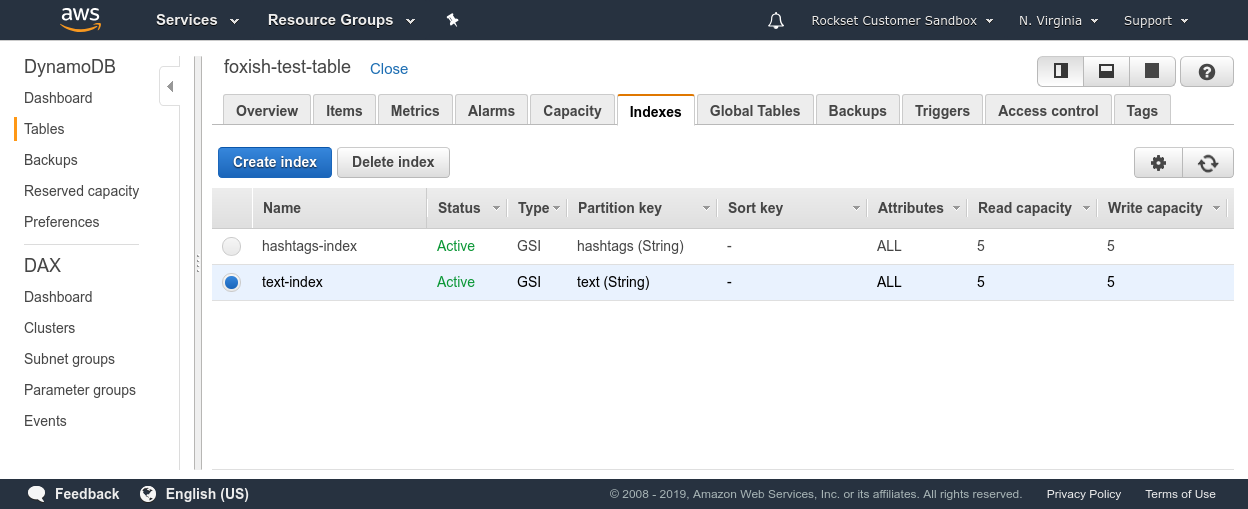
If we wish to help analytical queries with out encountering prohibitive scan prices, we are able to leverage secondary indexes in DynamoDB. Secondary indexes additionally consist of making partition keys and non-compulsory kind keys over fields that we wish to question over in a lot the identical method as the first key. Secondary indexes are sometimes used to enhance software efficiency by indexing fields that are queried fairly often. Question operations on secondary indexes may also be used to energy particular options by means of analytic queries which have clearly outlined necessities—like computing a leaderboard in a recreation. One clear benefit of this strategy of performing analytical queries is that there is no such thing as a want for some other system.

Nevertheless, it’s infeasible to make use of this strategy for a wider vary of analytical queries due to the restricted sorts of queries it helps. The complete gamut of analytics requires filtering on a number of fields, grouping, ordering, becoming a member of knowledge between knowledge units, and many others., which can’t be achieved merely by means of secondary indexes. Secondary indexes that may be created are additionally restricted in quantity and require some planning to make sure that they scale nicely with the info. A badly chosen partition key can worsen efficiency and improve prices considerably. Knowledge in DynamoDB can have a nested construction together with arrays and objects, however indexes can solely be constructed on sure primitive sorts. This will power denormalizing of the info to flatten nested objects and arrays with the intention to construct secondary indexes, which may probably explode the variety of writes carried out and related prices. Other than price and suppleness, there are additionally safety and efficiency issues relating to supporting analytic use circumstances on an operational knowledge retailer in a manufacturing surroundings.
Benefits
- No extra setup exterior DynamoDB
- Quick and scalable serving for fundamental analytical queries over listed fields
Disadvantages
- Costly when queries require scans over DynamoDB
- Very restricted help for analytical queries over indexes; no SQL queries, grouping, or joins
- Can not arrange indexes on nested fields with out denormalizing knowledge and exploding out writes
- Safety and efficiency implications of working analytical queries on an operational database
This strategy could also be appropriate if we have now an software that requires a selected function that’s easy sufficient to be realized utilizing a question over an index. The elevated storage and I/O price and the restricted question capability make it unsuitable for the broader vary of analytical queries in any other case. Subsequently, for a majority of analytic use circumstances, it’s price efficient to export the info from DynamoDB into a distinct system that permits us to question with greater constancy.
If you’re contemplating extracting knowledge to a different system, there are a number of totally different choices for real-time analytics:
- DynamoDB + Glue + S3 + Athena
- DynamoDB + Hive/Spark
- DynamoDB + AWS Lambda + Elasticsearch
- DynamoDB + Rockset
I examine every of those when it comes to ease of setup, upkeep, question functionality, latency in my different weblog publish Analytics on DynamoDB: Evaluating Athena, Spark and Elastic, the place I additionally consider which use circumstances every of them are finest suited to.
Different DynamoDB assets:
[ad_2]

