


[ad_1]
Tarballs are used industry-wide for packaging and distributing recordsdata, and that is no totally different at Databricks. Day-after-day we launch hundreds of thousands of VMs throughout a number of cloud suppliers. One of many first steps on each one in every of these VMs is extracting a reasonably sizable tar.lz4 file containing a particular Apache Spark™ runtime. As a part of an effort to assist convey down bootstrap occasions, we needed to see what may very well be executed to assist velocity up the method of extracting this massive tarball.
Current strategies
Proper now, the commonest technique for extracting tarballs is to invoke some command (e.g. curl, wget, and even their browser) to obtain the uncooked tarball domestically, after which use tar to extract the contents to their ultimate location on disk. There are two common strategies that exist proper now to enhance upon this.
Piping the obtain on to tar
Tar makes use of a sequential file format, which signifies that extraction at all times begins firstly of the file and makes its method in the direction of the top. A facet impact of that is that you just don’t want your complete file current to start extraction. Certainly tar can soak up “-“ because the enter file and it’ll learn from commonplace enter. Couple this with a downloader dumping to plain output (wget -O -) and you’ll successfully begin untarring the file in parallel as the remainder continues to be being downloaded. If each the obtain section and the extraction section take roughly the identical time, this will theoretically halve the entire time wanted.
Parallel obtain
Single stream downloaders typically don’t maximize the total bandwidth of a machine resulting from bottlenecks within the I/O path (e.g., bandwidth caps set per obtain stream from the obtain supply). Current instruments like aria2c assist mitigate this by downloading with parallel streams from a number of sources to the identical file on disk. This may provide vital speedups, each by using a number of obtain streams and by writing them in parallel to disk.
What fastar does totally different
Parallel downloads + piping
The primary aim of fastar was to mix the advantages of piping downloads on to tar with the elevated velocity of parallel obtain streams. Sadly aria2c is designed for writing on to disk. It doesn’t have the required synchronization mechanisms wanted for changing the a number of obtain streams to a single logical stream for normal output.
Fastar employs a bunch of employee threads which can be all liable for downloading their very own slices of the general file. Just like different parallel downloaders, it takes benefit of the HTTP RANGE header to verify every employee solely downloads the chunk it’s liable for. The primary distinction is that these employees make use of golang channels and a shared io.Author object to synchronize and merge the totally different obtain streams. This enables for a number of employees to be always pulling information in parallel whereas the eventual client solely sees a sequential, in-order stream of bytes.
Assuming 4 employee threads (this quantity is consumer configurable), the high-level logic is as follows:
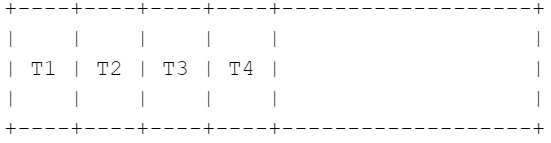
- Kick off threads (T1 – T4), which begin downloading chunks in parallel beginning firstly of the file. T1 begins instantly writing to stdout whereas threads T2-T4 save to in-memory buffers till it’s their flip.
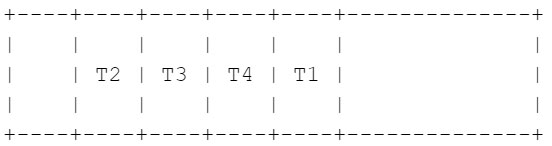
- As soon as T1 is completed writing its present chunk to stdout, it indicators T2 that it’s their flip, and begins downloading the subsequent chunk it’s liable for (proper after T4’s present chunk). T2 begins writing the information they saved of their buffer to stdout whereas the remainder of the threads proceed with their downloads. This course of continues for the entire file.
Multithreaded tar extraction
The opposite large space for enchancment was precise extraction of recordsdata to disk by tar itself. As alluded to earlier, one of many causes aria2c is such a quick file downloader is that it writes to disk with a number of streams. Holding a excessive queue depth when writing ensures that the disk at all times has work to do and isn’t sitting idle ready for the subsequent command. It additionally permits the disk to always rearrange write operations to maximise throughput. That is particularly necessary when, for instance, untarring many small recordsdata. The inbuilt tar command is single threaded, extracting all recordsdata from the archive in a single scorching loop.
To get round this, fastar additionally makes use of a number of threads for writing particular person extracted recordsdata to disk. For every file within the stream, fastar will copy the file information to a buffer, which is then handed to a thread to put in writing to disk within the background. Some file varieties must be dealt with in another way right here for correctness. Folders are written synchronously to make sure they exist earlier than any subfiles are written to disk. One other particular case right here is tough hyperlinks. Since they require the dependent file to exist in contrast to symlinks, we have to take care to synchronize file creation round them.
High quality of life options
Fastar additionally features a few options to enhance ease of use:
- S3 hosted obtain help. Fastar additionally helps downloading from S3 buckets utilizing the s3://bucket/key format
- Compression help. Fastar internally handles decompression of gzip and lz4 compressed tarballs. It may well even mechanically infer which compression schema is utilized by sniffing the primary few bytes for a magic quantity.
Efficiency numbers
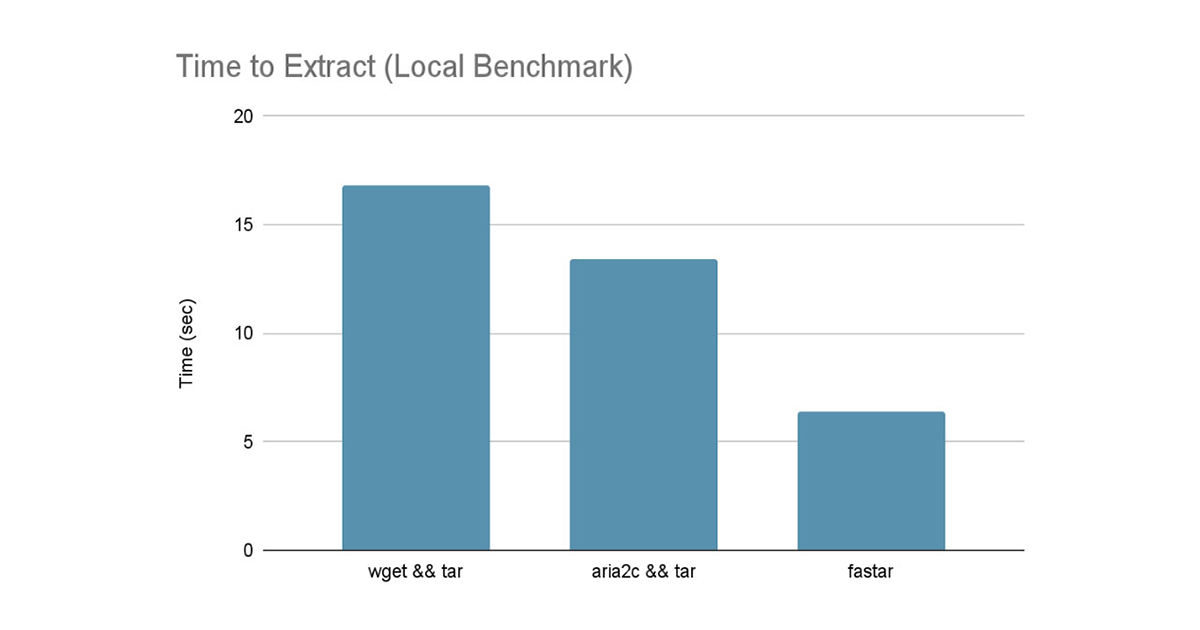
To check domestically, we used an lz4 compressed tarball of a container filesystem (2.6GB compressed, 4.3GB uncompressed). This was hosted on a neighborhood HTTP server serving from an in-memory file system. The tarball was then downloaded and extracted to the identical in-memory file system. This could characterize a theoretical greatest case state of affairs as we aren’t IO certain with the reminiscence backed file system.
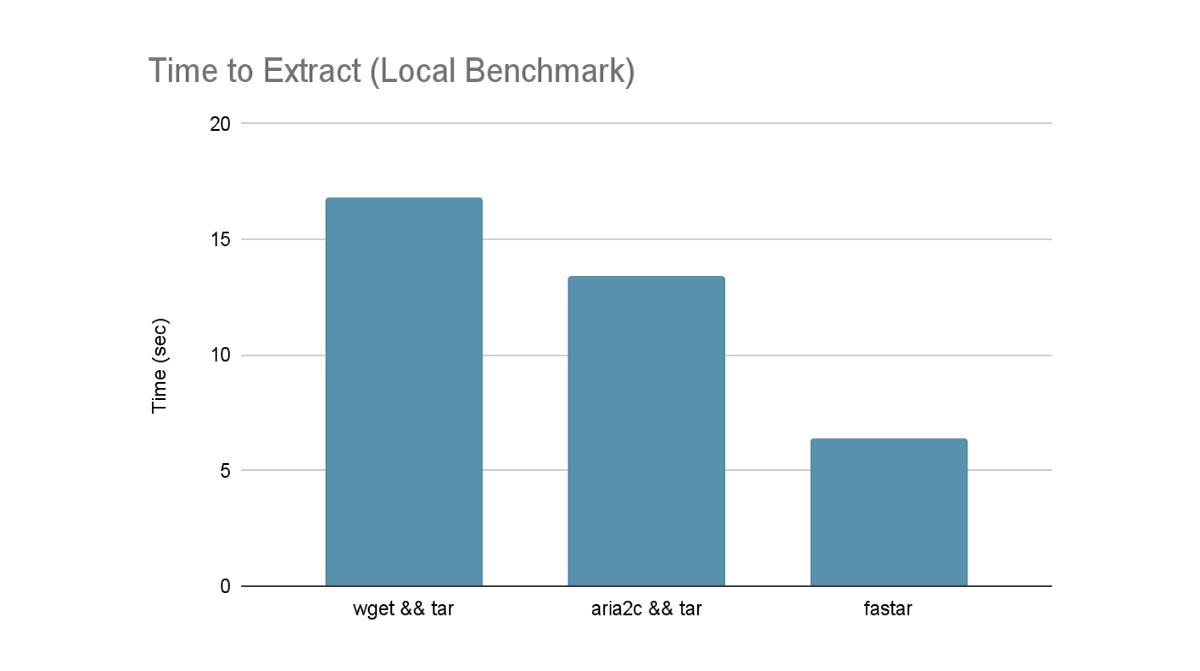
For manufacturing affect, the next reveals the velocity distinction when extracting one of many largest pictures we help on a reside cluster (7.6GB compressed, 16.1GB uncompressed). Pre-fastar, we used aria2c on Azure and boto3 on AWS to obtain the picture earlier than extracting it with tar.
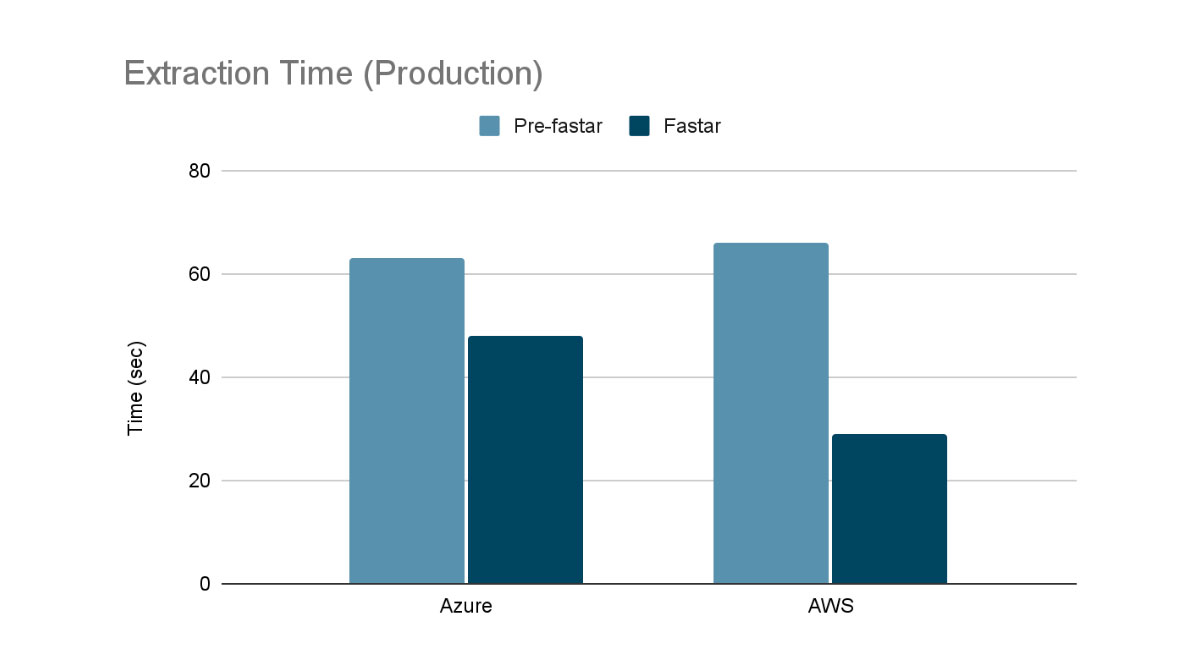
From the assessments above, fastar can provide vital velocity enhancements, each in artificial and real-world benchmarks. In artificial workloads we obtain a virtually 3x enchancment over naively calling wget && tar and double the efficiency in comparison with utilizing the already quick aria2c && tar. Lastly in manufacturing workloads we see a 1.3x enchancment in Azure Databricks and over a 2x enchancment in Databricks on AWS.
Excited by engaged on issues like this? Take into account making use of to Databricks!
Additionally tell us should you would discover this software helpful and we are able to look into open sourcing it!
[ad_2]

