


[ad_1]
Earlier than you possibly can create visuals and dashboards that convey helpful data, you might want to rework and put together the underlying information. With AWS Glue DataBrew, now you can simply rework and put together datasets from Amazon Easy Storage Service (Amazon S3), an Amazon Redshift information warehouse, Amazon Aurora, and different Amazon Relational Database Service (Amazon RDS) databases and add them into Amazon S3 to visualise the remodeled information in a dashboard utilizing Amazon QuickSight or different enterprise intelligence (BI) instruments like Tableau.
DataBrew now additionally helps writing ready information into Tableau Hyper format, permitting you to simply take ready datasets from Amazon S3 and add them into Tableau for additional visualization and evaluation. Hyper is Tableau’s in-memory information engine know-how optimized for quick information ingest and analytical question processing on massive or complicated datasets.
On this submit, we use DataBrew to extract information from Amazon Redshift, cleanse and rework information utilizing DataBrew to Tableau Hyper format with none coding, and retailer it in Amazon S3.
Overview of answer
The next diagram illustrates the structure of the answer.
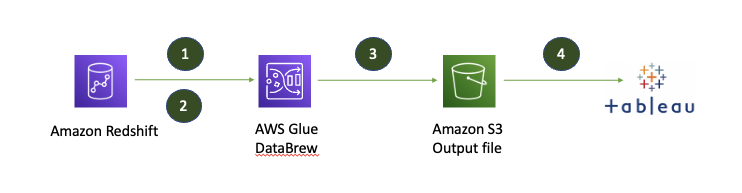
The answer workflow contains the next steps:
- You create a JDBC connection for Amazon Redshift and a DataBrew venture on the DataBrew console.
- DataBrew queries information from Amazon Redshift by making a recipe and performing transformations.
- The DataBrew job writes the ultimate output to an S3 bucket in Tableau Hyper format.
- Now you can add the file into Tableau for additional visualization and evaluation.
Conditions
For this walkthrough, you must have the next stipulations:
The next screenshots present the configuration for creating an Amazon Redshift cluster utilizing the Amazon Redshift console with demo gross sales information. For extra details about community safety for the cluster, see Setting Up a VPC to Hook up with JDBC Knowledge Shops.
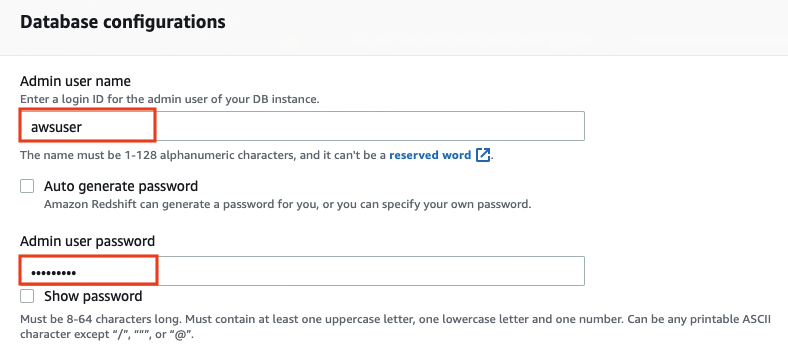
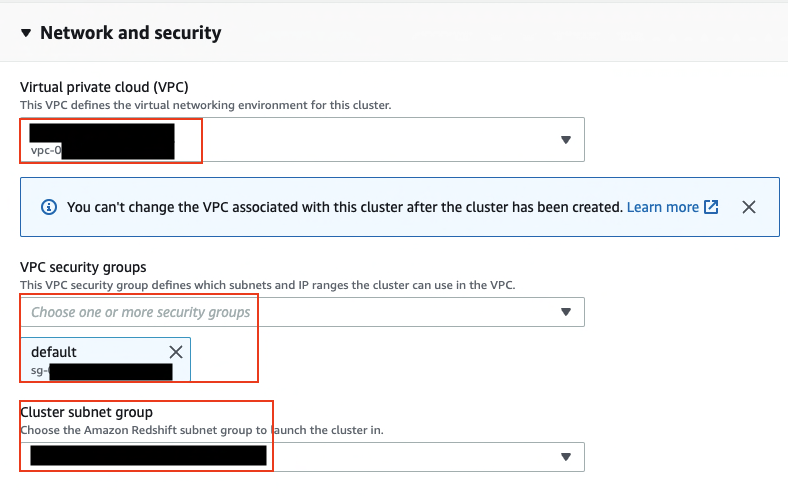
For this submit, we use the pattern information that comes with the Amazon Redshift cluster.
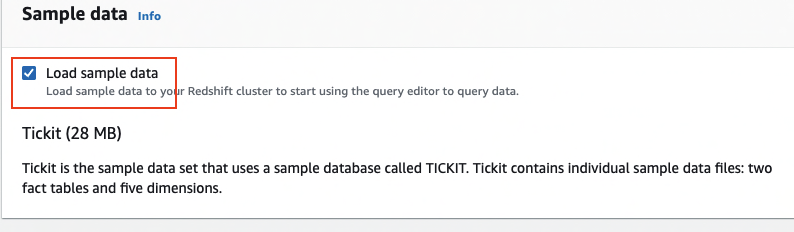
On this submit, we solely show rework your Amazon Redshift information to Hyper format; importing the file for additional evaluation is out of scope.
Create an Amazon Redshift connection
On this step, you employ the DataBrew console to create an Amazon Redshift connection.
- On the DataBrew console, select Datasets.
- On the Connections tab, select Create connection.
- For Connection identify, enter a reputation (for instance,
ticket-db-connection). - For Connection kind, choose Amazon Redshift.
- Within the Connection entry part, present particulars like cluster identify, database identify, consumer identify, and password.
- Select Create connection.

Create your dataset
To create a brand new dataset, full the next steps:
- On the DataBrew console, select Datasets.
- On the Datasets tab, select Join new dataset.
- For Dataset identify, enter
gross sales.
- For Hook up with new dataset, choose Amazon Redshift.
- Select the connection you created (
AwsGlueDataBrew-tickit-sales-db-connection). - Choose the general public schema and gross sales desk
- Within the Further configurations part, for Enter S3 vacation spot, enter the S3 bucket you created as a prerequisite.
DataBrew makes use of this bucket to retailer the intermediate outcomes.
- Select Create dataset.
 In case your question is taking an excessive amount of time, then add
LIMITclause in your Choose assertion.
Create a venture utilizing the dataset
To create a brand new venture, full the next steps:
- On the DataBrew console, select Tasks and select Create venture.
- For Venture identify, enter
sales-project. - For Connected recipe, select Create new recipe.
- For Recipe identify, enter
sales-project-recipe.
- For Choose a dataset, choose My datasets.
- Choose the
gross salesdataset.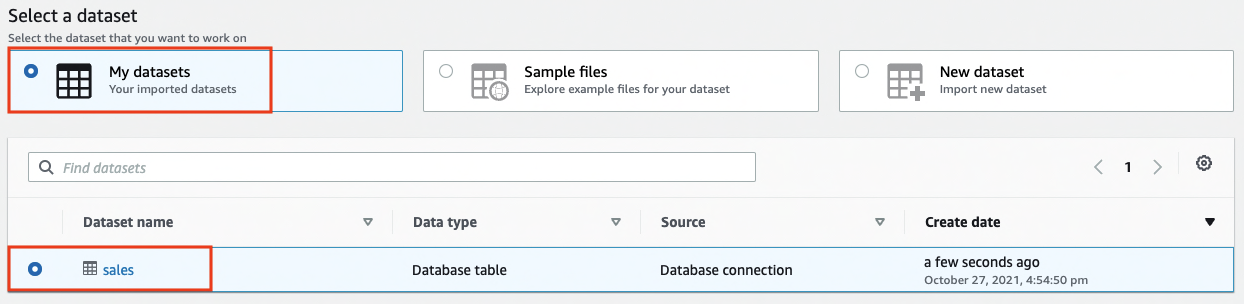
- Below Permissions, for Function identify, select an present IAM position created through the stipulations or create a brand new position.
- Select Create venture.

When the venture is opened, a DataBrew interactive session is created. DataBrew retrieves pattern information based mostly in your sampling configuration choice.
Once we join a dataset to an Amazon Redshift cluster in your VPC, DataBrew provisions an elastic community interface in your VPC with no public IPV4 tackle. Due to this, you might want to provision a NAT gateway in your VPC in addition to an acceptable subnet route desk configured for the subnets related to the AWS Glue community interfaces. To make use of DataBrew with a VPC subnet with no NAT, you need to have a gateway VPC endpoint to Amazon S3 and a VPC endpoint for the AWS Glue interface in your VPC. For extra data, see Create a gateway endpoint and Interface VPC endpoints (AWS PrivateLink).
Construct a metamorphosis recipe
On this step, we carry out some characteristic engineering strategies (transformations) to organize our dataset and drop the pointless columns from our dataset that aren’t required for this train.
- On the DataBrew console, select Column.
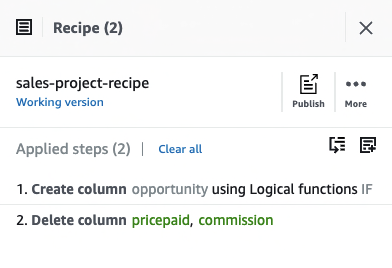
- Select Delete.

- For Supply columns, choose the columns
pricepaidandcommissions. - Select Apply.

Add a logical situation
With DataBrew, now you can use IF, AND, OR, and CASE logical circumstances to create transformations based mostly on features. With this characteristic, you’ve the flexibleness to make use of customized values or reference different columns throughout the expressions, and may create adaptable transformations for his or her particular use circumstances.
So as to add a logical situation to your transformation recipe, full the next steps:
- On the DataBrew console, select Circumstances.
- Select IF.

- For Matching circumstances, choose Match all circumstances.
- For Supply, select the worth
qtysold. - For Enter a worth, choose Enter a customized worth and enter
2. - For Vacation spot column, enter
alternative. - Select Apply.

The next screenshot reveals the complete recipe that we utilized to our dataset.
Create the DataBrew job
Now that now we have constructed the recipe, we are able to create and run the DataBrew recipe job.
- On the venture particulars web page, select Create job.
- For Job identify, enter
sales-opportunities.
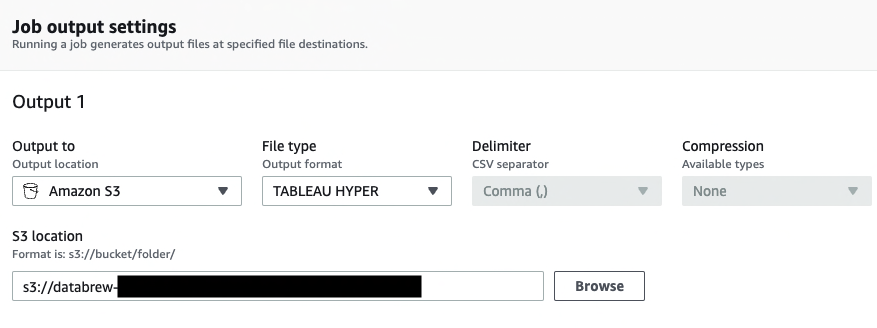
- We select TABLEAU HYPER because the output format.
- For S3 location, enter the beforehand created S3 bucket.
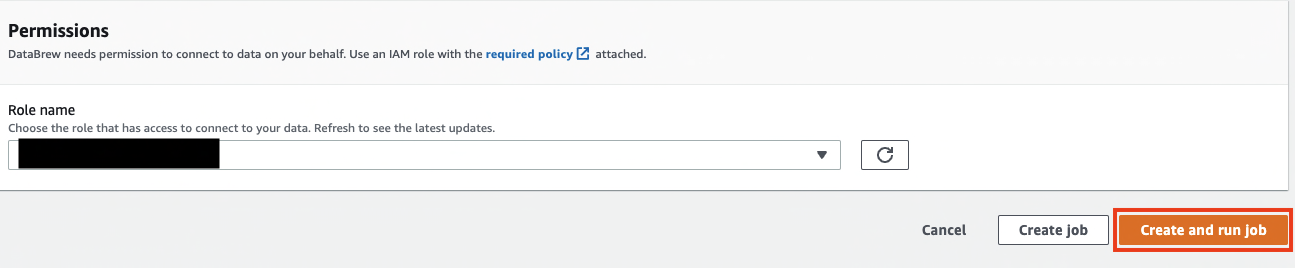
- For Function identify, select an present position created through the stipulations or create a brand new position.
- Select Create and run job.
- Navigate to the Jobs web page and look forward to the
sales-opportunityjob to finish.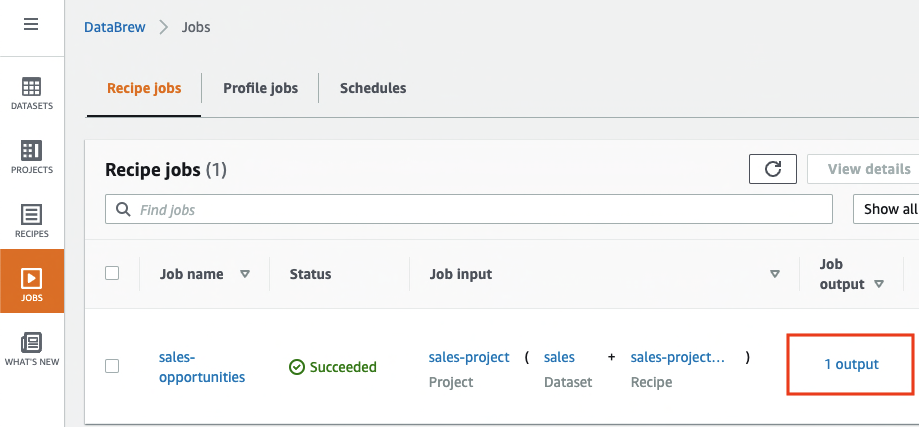
- Select the output hyperlink to navigate to the Amazon S3 console to entry the job output.

Clear up
To keep away from incurring future prices, delete the sources you created:
- Amazon Redshift cluster
- Recipe job
- Job output saved within the S3 bucket
- IAM roles created as a part of this train
- DataBrew venture
sales-projectand its related recipesales-project-recipe - DataBrew datasets
Conclusion
On this submit, we confirmed you ways to connect with an Amazon Redshift cluster and create a DataBrew dataset.
We noticed how straightforward it’s to get information from Amazon Redshift into DataBrew and apply transformations with none coding. We then ran a recipe job to transform this dataset to Tableau Hyper format file and retailer it in Amazon S3 for visualization utilizing Tableau. Be taught extra about all of the merchandise and repair integrations that AWS Glue DataBrew helps.
Concerning the Authors
 Nipun Chagari is a Senior Options Architect at AWS, the place he helps prospects construct extremely out there, scalable, and resilient purposes on the AWS Cloud. He’s at present targeted on serving to prospects leverage serverless know-how to fulfill their enterprise goals.
 Mohit Malik is a Senior Options Architect at Amazon Internet Providers who focuses on compute, networking, and serverless applied sciences. He enjoys serving to prospects learn to function effectively and successfully within the cloud. In his spare time, Mohit enjoys spending time along with his household, studying books, and watching films.
[ad_2]

