


[ad_1]
What’s the quickest we will load knowledge into RocksDB? We had been confronted with this problem as a result of we wished to allow our clients to rapidly check out Rockset on their large datasets. Regardless that the majority load of information in LSM timber is a vital subject, not a lot has been written about it. On this publish, we’ll describe the optimizations that elevated RocksDB’s bulk load efficiency by 20x. Whereas we needed to remedy attention-grabbing distributed challenges as effectively, on this publish we’ll deal with single node optimizations. We assume some familiarity with RocksDB and the LSM tree knowledge construction.
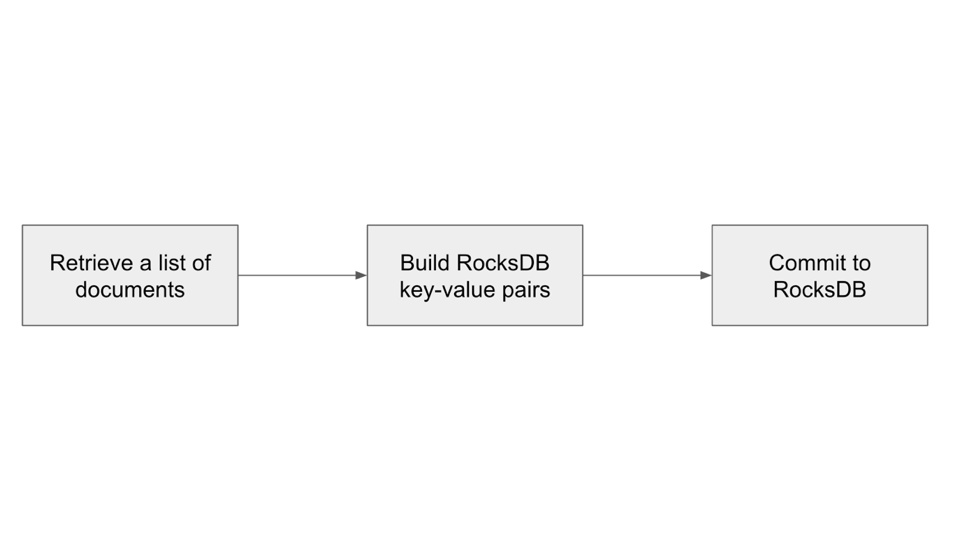
Rockset’s write course of comprises a few steps:
- In step one, we retrieve paperwork from the distributed log retailer. One doc symbolize one JSON doc encoded in a binary format.
- For each doc, we have to insert many key-value pairs into RocksDB. The following step converts the listing of paperwork into an inventory of RocksDB key-value pairs. Crucially, on this step, we additionally must learn from RocksDB to find out if the doc already exists within the retailer. If it does we have to replace secondary index entries.
- Lastly, we commit the listing of key-value pairs to RocksDB.

We optimized this course of for a machine with many CPU cores and the place an affordable chunk of the dataset (however not all) matches in the principle reminiscence. Totally different approaches would possibly work higher with small variety of cores or when the entire dataset matches into foremost reminiscence.
Buying and selling off Latency for Throughput
Rockset is designed for real-time writes. As quickly because the buyer writes a doc to Rockset, we’ve to use it to our index in RocksDB. We don’t have time to construct an enormous batch of paperwork. It is a disgrace as a result of growing the dimensions of the batch minimizes the substantial overhead of per-batch operations. There isn’t any must optimize the person write latency in bulk load, although. Throughout bulk load we enhance the dimensions of our write batch to a whole lot of MB, naturally resulting in a better write throughput.
Parallelizing Writes
In a daily operation, we solely use a single thread to execute the write course of. That is sufficient as a result of RocksDB defers many of the write processing to background threads by way of compactions. A few cores additionally should be out there for the question workload. Through the preliminary bulk load, question workload will not be necessary. All cores must be busy writing. Thus, we parallelized the write course of — as soon as we construct a batch of paperwork we distribute the batch to employee threads, the place every thread independently inserts knowledge into RocksDB. The necessary design consideration right here is to reduce unique entry to shared knowledge buildings, in any other case, the write threads might be ready, not writing.
Avoiding Memtable
RocksDB gives a characteristic the place you’ll be able to construct SST recordsdata by yourself and add them to RocksDB, with out going by way of the memtable, known as IngestExternalFile(). This characteristic is nice for bulk load as a result of write threads don’t should synchronize their writes to the memtable. Write threads all independently kind their key-value pairs, construct SST recordsdata and add them to RocksDB. Including recordsdata to RocksDB is an inexpensive operation because it includes solely a metadata replace.
Within the present model, every write thread builds one SST file. Nevertheless, with many small recordsdata, our compaction is slower than if we had a smaller variety of larger recordsdata. We’re exploring an strategy the place we’d kind key-value pairs from all write threads in parallel and produce one large SST file for every write batch.
Challenges with Turning off Compactions
The most typical recommendation for bulk loading knowledge into RocksDB is to show off compactions and execute one large compaction in the long run. This setup can also be talked about within the official RocksDB Efficiency Benchmarks. In spite of everything, the one cause RocksDB executes compactions is to optimize reads on the expense of write overhead. Nevertheless, this recommendation comes with two crucial caveats.
At Rockset we’ve to execute one learn for every doc write – we have to do one main key lookup to verify if the brand new doc already exists within the database. With compactions turned off we rapidly find yourself with 1000’s of SST recordsdata and the first key lookup turns into the most important bottleneck. To keep away from this we constructed a bloom filter on all main keys within the database. Since we often don’t have duplicate paperwork within the bulk load, the bloom filter permits us to keep away from costly main key lookups. A cautious reader will discover that RocksDB additionally builds bloom filters, but it surely does so per file. Checking 1000’s of bloom filters remains to be costly.
The second drawback is that the ultimate compaction is single-threaded by default. There’s a characteristic in RocksDB that permits multi-threaded compaction with possibility max_subcompactions. Nevertheless, growing the variety of subcompactions for our closing compaction doesn’t do something. With all recordsdata in stage 0, the compaction algorithm can not discover good boundaries for every subcompaction and decides to make use of a single thread as an alternative. We fastened this by first executing a priming compaction — we first compact a small variety of recordsdata with CompactFiles(). Now that RocksDB has some recordsdata in non-0 stage, that are partitioned by vary, it will possibly decide good subcompaction boundaries and the multi-threaded compaction works like a attraction with all cores busy.
Our recordsdata in stage 0 are usually not compressed — we don’t wish to decelerate our write threads and there’s a restricted profit of getting them compressed. Remaining compaction compresses the output recordsdata.
Conclusion
With these optimizations, we will load a dataset of 200GB uncompressed bodily bytes (80GB with LZ4 compression) in 52 minutes (70 MB/s) whereas utilizing 18 cores. The preliminary load took 35min, adopted by 17min of ultimate compaction. With not one of the optimizations the load takes 18 hours. By solely growing the batch dimension and parallelizing the write threads, with no modifications to RocksDB, the load takes 5 hours. Word that every one of those numbers are measured on a single node RocksDB occasion. Rockset parallelizes writes on a number of nodes and may obtain a lot increased write throughput.

Bulk loading of information into RocksDB could be modeled as a big parallel kind the place the dataset doesn’t match into reminiscence, with an extra constraint that we additionally must learn some a part of the information whereas sorting. There may be loads of attention-grabbing work on parallel kind on the market and we hope to survey some methods and take a look at making use of them in our setting. We additionally invite different RocksDB customers to share their bulk load methods.
I’m very grateful to everyone who helped with this mission — our superior interns Jacob Klegar and Aditi Srinivasan; and Dhruba Borthakur, Ari Ekmekji and Kshitij Wadhwa.
[ad_2]

