


[ad_1]
Introduction to Operational Analytics
Operational analytics is a really particular time period for a kind of analytics which focuses on enhancing present operations. Any such analytics, like others, includes the usage of numerous information mining and information aggregation instruments to get extra clear data for enterprise planning. The primary attribute that distinguishes operational analytics from different kinds of analytics is that it’s “analytics on the fly,” which implies that alerts emanating from the assorted elements of a enterprise are processed in real-time to feed again into immediate resolution making for the enterprise. Some individuals confer with this as “steady analytics,” which is one other option to emphasize the continual digital suggestions loop that may exist from one a part of the enterprise to others.
Operational analytics means that you can course of numerous kinds of data from completely different sources after which resolve what to do subsequent: what motion to take, whom to speak to, what speedy plans to make. This type of analytics has turn into well-liked with the digitization development in virtually all business verticals, as a result of it’s digitization that furnishes the info wanted for operational decision-making.
Examples of operational analytics
Let’s talk about some examples of operational analytics.
Software program sport builders
As an example that you’re a software program sport developer and also you need your sport to routinely upsell a sure characteristic of your sport relying on the gamer’s enjoying habits and the present state of all of the gamers within the present sport. That is an operational analytics question as a result of it permits the sport developer to make immediate choices based mostly on evaluation of present occasions.
Product managers
Again within the day, product managers used to do loads handbook work, speaking to clients, asking them how they use the product, what options within the product gradual them down, and many others. Within the age of operational analytics, a product supervisor can collect all these solutions by querying information that information utilization patterns from the product’s person base; and she or he can instantly feed that data again to make the product higher.
Advertising and marketing managers
Equally, within the case of selling analytics, a advertising and marketing supervisor would use to prepare a number of focus teams, check out a number of experiments based mostly on their very own creativity after which implement them. Relying on the outcomes of experimentation, they’d then resolve what to do subsequent. An experiment could take weeks or months. We at the moment are seeing the rise of the “advertising and marketing engineer,” an individual who’s well-versed in utilizing information programs.
These advertising and marketing engineers can run a number of experiments directly, collect outcomes from experiments within the type of information, terminate the ineffective experiments and nurture those that work, all by way of the usage of data-based software program programs. The extra experiments they will run and the faster the turnaround occasions of outcomes, the higher their effectiveness in advertising and marketing their product. That is one other type of operational analytics.
Definition of Operational Analytics Processing
An operational analytics system helps you make immediate choices from reams of real-time information. You acquire new information out of your information sources they usually all stream into your operational information engine. Your user-facing interactive apps question the identical information engine to fetch insights out of your information set in actual time, and also you then use that intelligence to offer a greater person expertise to your customers.
Ah, you would possibly say that you’ve seen this “beast” earlier than. The truth is, you is likely to be very, very acquainted with a system that…
- encompasses your information pipeline that sources information from numerous sources
- deposits it into your information lake or information warehouse
- runs numerous transformations to extract insights, after which…
- parks these nuggets of data in a key-value retailer for quick retrieval by your interactive user-facing functions
And you’ll be completely proper in your evaluation: an equal engine that has your entire set of those above features is an operational analytics processing system!
The definition of an operational analytics processing engine might be expressed within the type of the next six propositions:
- Complicated queries: Assist for queries like joins, aggregations, sorting, relevance, and many others.
- Low information latency: An replace to any information document is seen in question leads to beneath than a number of seconds.
- Low question latency: A easy search question returns in beneath a number of milliseconds.
- Excessive question quantity: In a position to serve no less than a number of hundred concurrent queries per second.
- Dwell sync with information sources: Capacity to maintain itself in sync with numerous exterior sources with out having to jot down exterior scripts. This may be executed by way of change-data-capture of an exterior database, or by tailing streaming information sources.
- Blended sorts: Permits values of various sorts in the identical column. That is wanted to have the ability to ingest new information with no need to wash them at write time.
Let’s talk about every of the above propositions in larger element and talk about why every of the above options is important for an operational analytics processing engine.
Proposition 1: Complicated queries
A database, in any conventional sense, permits the appliance to precise advanced information operations in a declarative means. This permits the appliance developer to not must explicitly perceive information entry patterns, information optimizations, and many others. and frees him/her to concentrate on the appliance logic. The database would assist filtering, sorting, aggregations, and many others. to empower the appliance to course of information effectively and rapidly. The database would assist joins throughout two or extra information units in order that an software may mix the knowledge from a number of sources to extract intelligence from them.
For instance, SQL, HiveQL, KSQL and many others. present declarative strategies to precise advanced information operations on information units. They’ve various expressive powers: SQL helps full joins whereas KSQL doesn’t.
Proposition 2: Low information latency
An operational analytics database, not like a transactional database, doesn’t must assist transactions. The functions that use this kind of a database use it to retailer streams of incoming information; they don’t use the database to document transactions. The incoming information fee is bursty and unpredictable. The database is optimized for high-throughout writes and helps an eventual consistency mannequin the place newly written information turns into seen in a question inside a number of seconds at most.
Proposition 3: Low question latency
An operational analytics database is ready to answer queries rapidly. On this respect, it is rather just like transactional databases like Oracle, PostgreSQL, and many others. It’s optimized for low-latency queries somewhat than throughput. Easy queries end in a number of milliseconds whereas advanced queries scale out to complete rapidly as effectively. This is among the fundamental necessities to have the ability to energy any interactive software.
Proposition 4: Excessive question quantity
A user-facing software usually makes many queries in parallel, particularly when a number of customers are utilizing the appliance concurrently. For instance, a gaming software may need many customers enjoying the identical sport on the similar time. A fraud detection software is likely to be processing a number of transactions from completely different customers concurrently and would possibly must fetch insights about every of those customers in parallel. An operational analytics database is able to supporting a excessive question fee, starting from tens of queries per second (e.g. stay dashboard) to 1000’s of queries per second (e.g. an internet cellular app).
Proposition 5: Dwell sync with information sources
A web-based analytics database means that you can routinely and repeatedly sync information from a number of exterior information sources. With out this characteristic, you’ll create yet one more information silo that’s troublesome to keep up and babysit.
You may have your personal system-of-truth databases, which might be Oracle or DynamoDB, the place you do your transactions, and you’ve got occasion logs in Kafka; however you want a single place the place you wish to herald all these information units and mix them to generate insights. The operational analytics database has built-in mechanisms to ingest information from quite a lot of information sources and routinely sync them into the database. It could use change-data-capture to repeatedly replace itself from upstream information sources.
Proposition 6: Blended sorts
An analytics system is tremendous helpful when it is ready to retailer two or extra various kinds of objects in the identical column. With out this characteristic, you would need to clear up the occasion stream earlier than you may write it to the database. An analytics system can present low information latency provided that cleansing necessities when new information arrives is lowered to a minimal. Thus, an operational analytics database has the potential to retailer objects of blended sorts throughout the similar column.
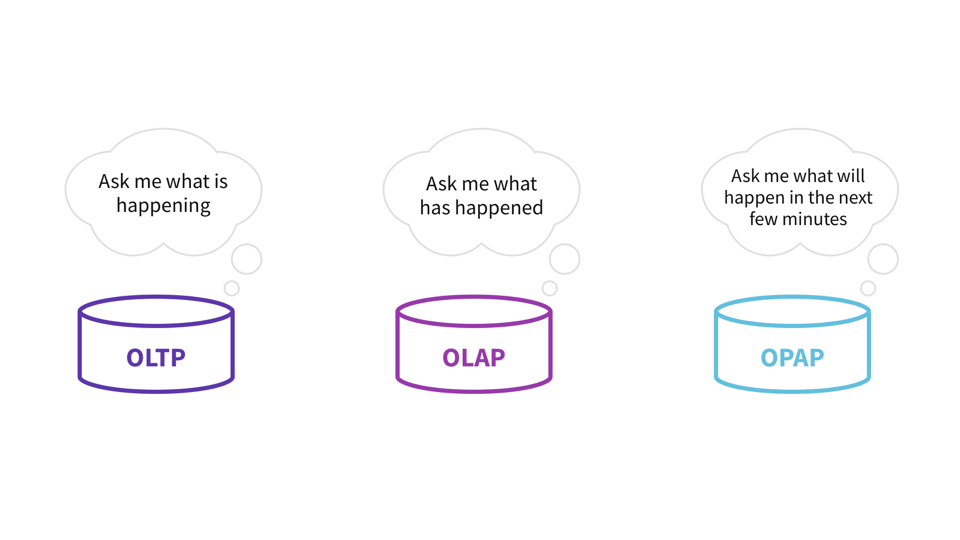
The six above traits are distinctive to an OPerational Analytics Processing (OPAP) system.

Architectural Uniqueness of an OPAP System
The Database LOG
The Database is the LOG; it durably shops information. It’s the “D” in ACID programs. Let’s analyze the three kinds of information processing programs so far as their LOG is worried.
The first use of an OLTP system is to ensure some types of sturdy consistency between updates and reads. In these circumstances the LOG is behind the database server(s) that serves queries. For instance, an OLTP system like PostgreSQL has a database server; updates arrive on the database server, which then writes it to the LOG. Equally, Amazon Aurora‘s database server(s) receives new writes, appends transactional data (like sequence quantity, transaction quantity, and many others.) to the write after which persists it within the LOG. On each of those circumstances, the LOG is hidden behind the transaction engine as a result of the LOG must retailer metadata in regards to the transaction.

Equally, many OLAP programs assist some fundamental type of transactions as effectively. For instance, the OLAP Snowflake Information Warehouse explicitly states that it’s designed for bulk updates and trickle inserts (see Part 3.3.2 titled Concurrency Management). They use a copy-on-write method for complete datafiles and a world key-value retailer because the LOG. The database servers fronting the LOG implies that streaming write charges are solely as quick because the database servers can deal with.
Alternatively, an OPAP system’s major aim is to assist a excessive replace fee and low question latency. An OPAP system doesn’t have the idea of a transaction. As such, an OPAP system has the LOG in entrance of the database servers, the reason is that the log is required just for sturdiness. Making the database be fronted by the log is advantageous: the log can function a buffer for big write volumes within the face of sudden bursty write storms. A log can assist a a lot greater write fee as a result of it’s optimized for writes and never for random reads.

Sort binding at question time and never at write time
OLAP databases affiliate a hard and fast kind for each column within the database. Which means that each worth saved in that column conforms to the given kind. The database checks for conformity when a brand new document is written to the database. If a discipline of a brand new document doesn’t adhere to the desired kind of the column, the document is both discarded or a failure is signaled. To keep away from these kind of errors, OLAP database are fronted by an information pipeline that cleans and validates each new document earlier than it’s inserted to the database.
Instance
Let’s say {that a} database has a column referred to as ‘zipcode’. We all know that zip code are integers within the US whereas zipcodes within the UK can have each letters and digits. In an OLAP database, now we have to transform each of those to the ‘string’ kind earlier than we are able to retailer them in the identical column. However as soon as we retailer them as strings within the database, we lose the power to make integer comparisons as a part of the question on this column. For instance, a question of the kind choose depend(*) from desk the place zipcode > 1000 will throw an error as a result of we’re doing an integral vary test however the column kind is a string.
Alternatively an OPAP database doesn’t have a hard and fast kind for each column within the database. As an alternative, the kind is related to each particular person worth saved within the column. The ‘zipcode’ discipline in an OPAP database is able to storing each these kind of information in the identical column with out dropping the kind data of each discipline.
Going additional, for the above question choose depend(*) from desk the place zipcode > 1000, the database may examine and match solely these values within the column which might be integers and return a sound outcome set. Equally, a question choose depend(*) from desk the place zipcode=’NW89EU’ may match solely these information which have a price of kind ‘string’ and return a sound outcome set.
Thus, an OPAP database can assist a powerful schema, however implement the schema binding at question time somewhat than at information insertion time. That is what’s termed sturdy dynamic typing.
Comparisons with Different Information Programs
Now that we perceive the necessities of an OPAP database, let’s evaluate and distinction different present information options. Particularly, let’s evaluate its options with an OLTP database, an OLAP information warehouse, an HTAP database, a key-value database, a distributed logging system, a doc database and a time-series database. These are among the well-liked programs which might be in use at the moment.

Evaluate with an OLTP database
An OLTP system is used to course of transactions. Typical examples of transactional programs are Oracle, Spanner, PostgreSQL, and many others. The programs are designed for low-latency updates and inserts, and these writes are throughout failure domains in order that the writes are sturdy. The first design focus of those programs is to not lose a single replace and to make it sturdy. A single question usually processes a number of kilobytes of knowledge at most. They’ll maintain a excessive question quantity, however not like an OPAP system, a single question will not be anticipated to course of megabytes or gigabytes of knowledge in milliseconds.
Evaluate with an OLAP information warehouse
- An OLAP information warehouse can course of very advanced queries on giant datasets and is just like an OPAP system on this regard. Examples of OLAP information warehouses are Amazon Redshift and Snowflake. However that is the place the similarity ends.
- An OLAP system is designed for general system throughput whereas OPAP is designed for the bottom of question latencies.
- An OLAP information warehouse can have an general excessive write fee, however not like a OPAP system, writes are batched and inserted into the database periodically.
- An OLAP database requires a strict schema at information insertion time, which primarily implies that schema binding occurs at information write time. Alternatively, an OPAP database natively understands semi-structured schema (JSON, XML, and many others.) and the strict schema binding happens at question time.
- An OLAP warehouse helps a low variety of concurrent queries (e.g. Amazon Redshift helps as much as 50 concurrent queries), whereas a OPAP system can scale to assist giant numbers of concurrent queries.
Evaluate with an HTAP database
An HTAP database is a mixture of each OLTP and OLAP programs. Which means that the variations talked about within the above two paragraphs apply to HTAP programs as effectively. Typical HTAP programs embody SAP HANA and MemSQL.
Evaluate with a key-value retailer
Key-Worth (KV) shops are identified for velocity. Typical examples of KV shops are Cassandra and HBase. They supply low latency and excessive concurrency however that is the place the similarity with OPAP ends. KV shops don’t assist advanced queries like joins, sorting, aggregations, and many others. Additionally, they’re information silos as a result of they don’t assist the auto-sync of knowledge from exterior sources and thus violate Proposition 5.
Evaluate with a logging system
A log retailer is designed for top write volumes. It’s appropriate for writing a excessive quantity of updates. Apache Kafka and Apache Samza are examples of logging programs. The updates reside in a log, which isn’t optimized for random reads. A logging system is sweet at windowing features however doesn’t assist arbitrary advanced queries throughout your entire information set.
Evaluate with a doc database
A doc database natively helps a number of information codecs, usually JSON. Examples of a doc database are MongoDB, Couchbase and Elasticsearch. Queries are low latency and may have excessive concurrency however they don’t assist advanced queries like joins, sorting and aggregations. These databases don’t assist computerized methods to sync new information from exterior sources, thus violating Proposition 5.
Evaluate with a time-series database
A time-series database is a specialised operational analytics database. Queries are low latency and it might probably assist excessive concurrency of queries. Examples of time-series databases are Druid, InfluxDB and TimescaleDB. It might assist a fancy aggregations on one dimension and that dimension is ‘time’. Alternatively, an OPAP system can assist advanced aggregations on any data-dimension and never simply on the ‘time’ dimension. Time sequence database will not be designed to affix two or extra information units whereas OPAP programs can be a part of two or extra datasets as a part of a single question.
References
- Techopedia: https://www.techopedia.com/definition/29495/operational-analytics
- Andreessen Horowitz: https://a16z.com/2019/05/16/everyone-is-an-analyst-opportunities-in-operational-analytics/
- Forbes: https://www.forbes.com/websites/forbestechcouncil/2019/06/11/from-good-to-great-how-operational-analytics-can-give-businesses-a-real-time-edge/
- Gartner: https://www.gartner.com/en/newsroom/press-releases/2019-02-18-gartner-identifies-top-10-data-and-analytics-technolo
- Tech Republic: https://www.techrepublic.com/article/how-data-scientists-can-help-operational-analytics-succeed/
- Quora: https://www.quora.com/What-is-Operations-Analytics
[ad_2]

