



[ad_1]
Apache Hudi is an open-source transactional information lake framework that significantly simplifies incremental information processing and information pipeline improvement. It does this by offering transaction assist and record-level insert, replace, and delete capabilities on information lakes on Amazon Easy Storage Service (Amazon S3) or Apache HDFS. Apache Hudi is built-in with open-source large information analytics frameworks, equivalent to Apache Spark, Apache Hive, Presto, and Trino. Moreover, Apache Hudi allows you to keep information in Amazon S3 or Apache HDFS in open codecs equivalent to Apache Parquet and Apache Avro.
Widespread use circumstances the place we see clients use Apache Hudi are as follows:
- To simplify information ingestion pipelines that take care of late-arriving or up to date information from streaming and batch information sources.
- To ingest information utilizing Change Information Seize (CDC) from transactional techniques.
- To implement data-deletion pipelines to adjust to information privateness laws, e.g., GDPR (Normal Information Safety Regulation) compliance. Conforming to GDPR is a necessity of at this time’s trendy information architectures, which incorporates the options of “proper to erasure” or “proper to be forgotten”, and it may be applied utilizing Apache Hudi capabilities instead of deletes and updates.
We’re excited to announce that Apache Hudi 0.9.0 is on the market on Amazon EMR 5.34 and EMR 6.5.0. This can be a main launch, which incorporates Spark SQL DML and DDL assist as its spotlight, together with a number of different author/reader aspect enhancements. The 3x question efficiency enchancment that we observe over Hudi 0.6.0 is very outstanding so in case you are trying to implement a transactional information lake with document degree upserts and deletes or are utilizing an older model of Hudi, this can be a nice model to make use of. On this put up, we’ll give attention to the next new options and enhancements that include the 0.9.0 launch:
- Spark SQL DML and DDL Help: Discover Spark SQL DML and DDL assist.
- Efficiency Enhancements: Discover the efficiency enhancements and new efficiency associated options launched on the author and question aspect.
- Extra Options: Discover further helpful options, equivalent to Amazon DynamoDB-based locks for Optimistic Concurrency Management (OCC), delete partitions operation, and many others.
Spark SQL DML and DDL assist
Probably the most thrilling new function is that Apache Hudi 0.9.0 provides assist for DDL/DMLs utilizing Spark SQL. This takes an enormous step towards making Hudi extra simply accessible, operable by all individuals (non-engineers, analysts, and many others.). Furthermore, it allows current datasets to be simply migrated to Apache Hudi tables, and it takes a step nearer to a low-code paradigm utilizing Spark SQL DML and DDL therefore eliminating the necessity to write scala/python code.
Customers can now create tables utilizing CREATE TABLE....USING HUDI and CREATE TABLE .. AS SELECT SQL statements to immediately handle tables in AWS Glue catalog.
Then, customers can use INSERT, UPDATE, MERGE INTO, and DELETE SQL statements to govern information. The INSERT OVERWRITE assertion can be utilized to overwrite current information within the desk or partition for current batch ETL pipelines.
Let’s run by way of a fast instance the place we create a Hudi desk amazon_customer_review_hudi resembling the schema of Amazon Buyer critiques Public Dataset and carry out the next actions:
- Pre-requisite: Create Amazon Easy Storage Service (S3) Buckets
s3://EXAMPLE-BUCKETands3://EXAMPLE-BUCKET-1 - Create a partitioned Hudi desk
amazon_product_review_hudi - Create a supply Hudi desk
amazon_customer_review_parquet_merge_sourcewith contents that shall be merged with theamazon_product_review_hudidesk - Insert information into
amazon_customer_review_parquet_merge_sourceandamazon_product_review_hudiin addition to carry out a merge operation by studying the information fromamazon_customer_review_parquet_merge_sourceand merging with the Hudi deskamazon_product_review_hudi - Carry out a delete operation on
amazon_customer_review_hudiover the beforehand inserted information
Configure Spark Session
We use the next script by way of EMR studio pocket book, to configure Spark Session to work with Apache Hudi DML and DDL assist. The next examples display launch the interactive Spark shell, use Spark submit, or use Amazon EMR Notebooks to work with Hudi on Amazon EMR. We suggest launching your EMR cluster with the next Apache Livy configuration:
The above configuration allows you to immediately discuss with the native /usr/lib/hudi/hudi-spark-bundle.jar on the EMR chief node whereas configuring the Spark session. Alternatively, you can even copy /usr/lib/hudi/hudi-spark-bundle.jar over to an HDFS location and discuss with that whereas initializing Spark session. Here’s a command for initializing the Spark session from a pocket book:
Create a Desk
Let’s create the next Apache Hudi tables amazon_customer_review_hudi and amazon_customer_review_parquet_merge_source
For comparability if, amazon_customer_review_hudi was to be created utilizing programmatic strategy the PySpark pattern code is as follows.
Insert information into the Hudi tables
Let’s insert information into the desk amazon_customer_review_parquet_merge_source for use for the merge operation. This consists of inserting a row for contemporary insert, replace, and delete.
Now let’s insert information into the amazon_customer_review_hudi desk used because the vacation spot desk for the merge operation.
Merge into
Let’s carry out the merge from amazon_customer_review_parquet_merge_source into amazon_customer_review_hudi.
Issues and Limitations
- The merge-on situation can solely be utilized on major key as of now.
-- The merge situation is feasible solely on major keyson track.review_id = supply.review_id - Help for partial updates is supported for the Copy on Write (CoW) desk, however it isn’t supported for the Merge on Learn (MoR) tables.
- The goal desk’s fields can not be the right-value of the replace expression for the MoR desk:
-- The replace will lead to an error as goal columns are current on proper hand aspect of the expressionreplace set goal.star_rating = goal.star_rating +1
Delete a File
Now let’s delete the inserted document.
Schema Evolution
Hudi helps frequent schema evolution eventualities, equivalent to including a nullable area or selling the datatype of a area. Let’s add a brand new column ssid (kind int) to current amazon_customer_review_hudi desk, and insert a document with further column. Hudi permits for querying each previous and new information with the up to date desk schema.
Spark Efficiency Enhancements
Question Facet Enhancements
Apache Hudi tables at the moment are registered with the metastore as Spark Information Supply tables. This permits Spark SQL queries on Hudi tables to make use of Spark’s native Parquet Reader in case of Copy on Write tables, and Hudi’s customized MergeOnReadSnapshotRelation in case of Merge on Learn tables. Due to this fact, it now not is determined by Hive Enter Format fallback inside Spark, which isn’t as maintained and environment friendly as Spark’s native readers. This unlocks many optimizations, equivalent to using Spark’s native parquet readers, and implementing Hudi’s personal Spark FileIndex implementation. The File Index helps enhance file itemizing efficiency by way of optimized caching, assist for partition pruning, in addition to the flexibility to record recordsdata by way of Hudi metadata desk (as an alternative of itemizing immediately from Amazon S3). As well as, Hudi now helps time journey question by way of Spark information supply, which helps you to question snapshot of the dataset as of a historic time on the spot.
Different essential issues to notice are:
- Configurations equivalent to
spark.sql.hive.convertMetastoreParquet=falseandmapreduce.enter.pathFilter.class=org.apache.hudi.hadoop.HoodieROTablePathFilterare now not wanted whereas querying by way of Spark SQL. - Now you should utilize a non-globbed question path when querying Hudi datasets by way of Information Supply API. This allows you to question the desk by way of base path with out having to specify
*within the question path.
We ran a efficiency benchmark derived from the three TB scale TPC-DS benchmark to find out the question efficiency enhancements for Hudi 0.9.0 on EMR 6.5.0, relative to Hudi 0.6.0 on EMR 6.2.0 (at first of 2021) for Copy on Write tables. The queries have been run on 5-node c5.9xlarge EMR clusters.
When it comes to Geometric Imply, the queries with Hudi 0.9.0 are thrice sooner than they have been with Hudi 0.6.0. The next graphs examine the full combination runtime and geometric imply of runtime for the entire queries within the TPC-DS 3 TB question dataset between the 2 Amazon EMR/Hudi releases (decrease is best):
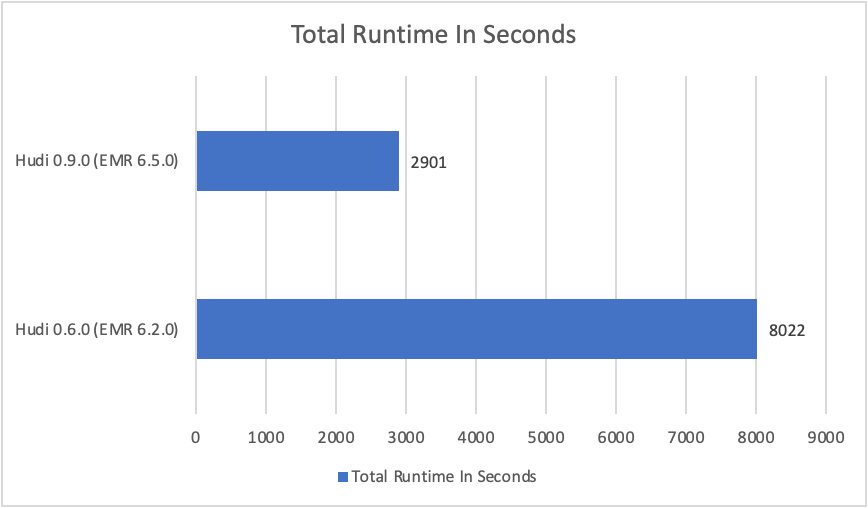

When it comes to Geometric Imply the queries with Hudi 0.9.0 are 3 instances sooner than they have been with Hudi 0.6.0.
Author aspect enhancements
Digital Keys Help
Apache Hudi maintains metadata by including further columns to the datasets. This lets it assist upsert/delete operations and numerous capabilities round it, equivalent to incremental queries, compaction, and many others. These metadata columns (specifically _hoodie_commit_time, _hoodie_record_key, _hoodie_partition_path, _hoodie_file_name and _hoodie_commit_seqno) let Hudi uniquely determine a document, the partition/file through which a document exists, and the newest commit that up to date a document.
Nevertheless, producing and sustaining these metadata columns will increase the storage footprint for Hudi tables on disk. A few of these columns, equivalent to _hoodie_record_key and _hoodie_partition_path, could be constructed from different information columns already saved within the datasets. Apache Hudi 0.9.0 has launched assist for Digital Keys. This lets customers disable the technology of those metadata columns, and as an alternative rely upon precise information columns to assemble the document key/partition paths dynamically utilizing applicable key turbines. This helps in decreasing the storage footprint, in addition to enhancing ingestion time. Nevertheless, this function comes with the next caveats:
- That is solely meant for use for Append Solely / Immutable information. It could actually’t be used to be used circumstances requiring upserts and deletes, which requires metadata columns equivalent to
_hoodie_record_keyand_hoodie_partition_pathfor bloom indexes to work. - Incremental queries won’t be supported, as a result of they want
_hoodie_commit_timeto filter information written/up to date at a particular time. - As soon as this function is enabled, it might’t be turned off for an current desk.
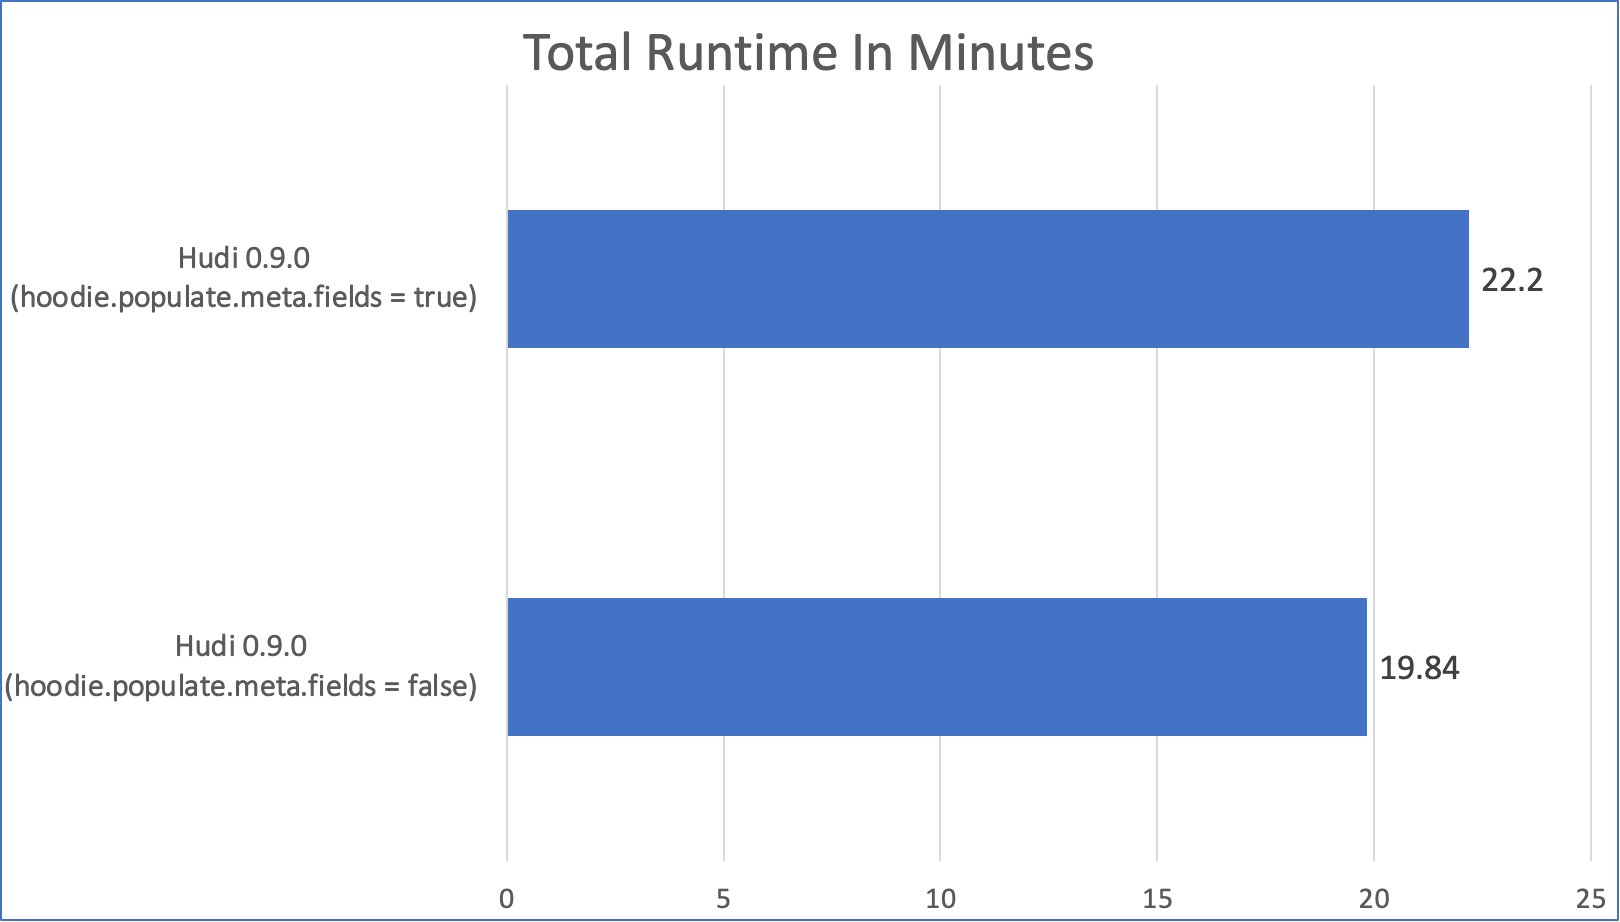
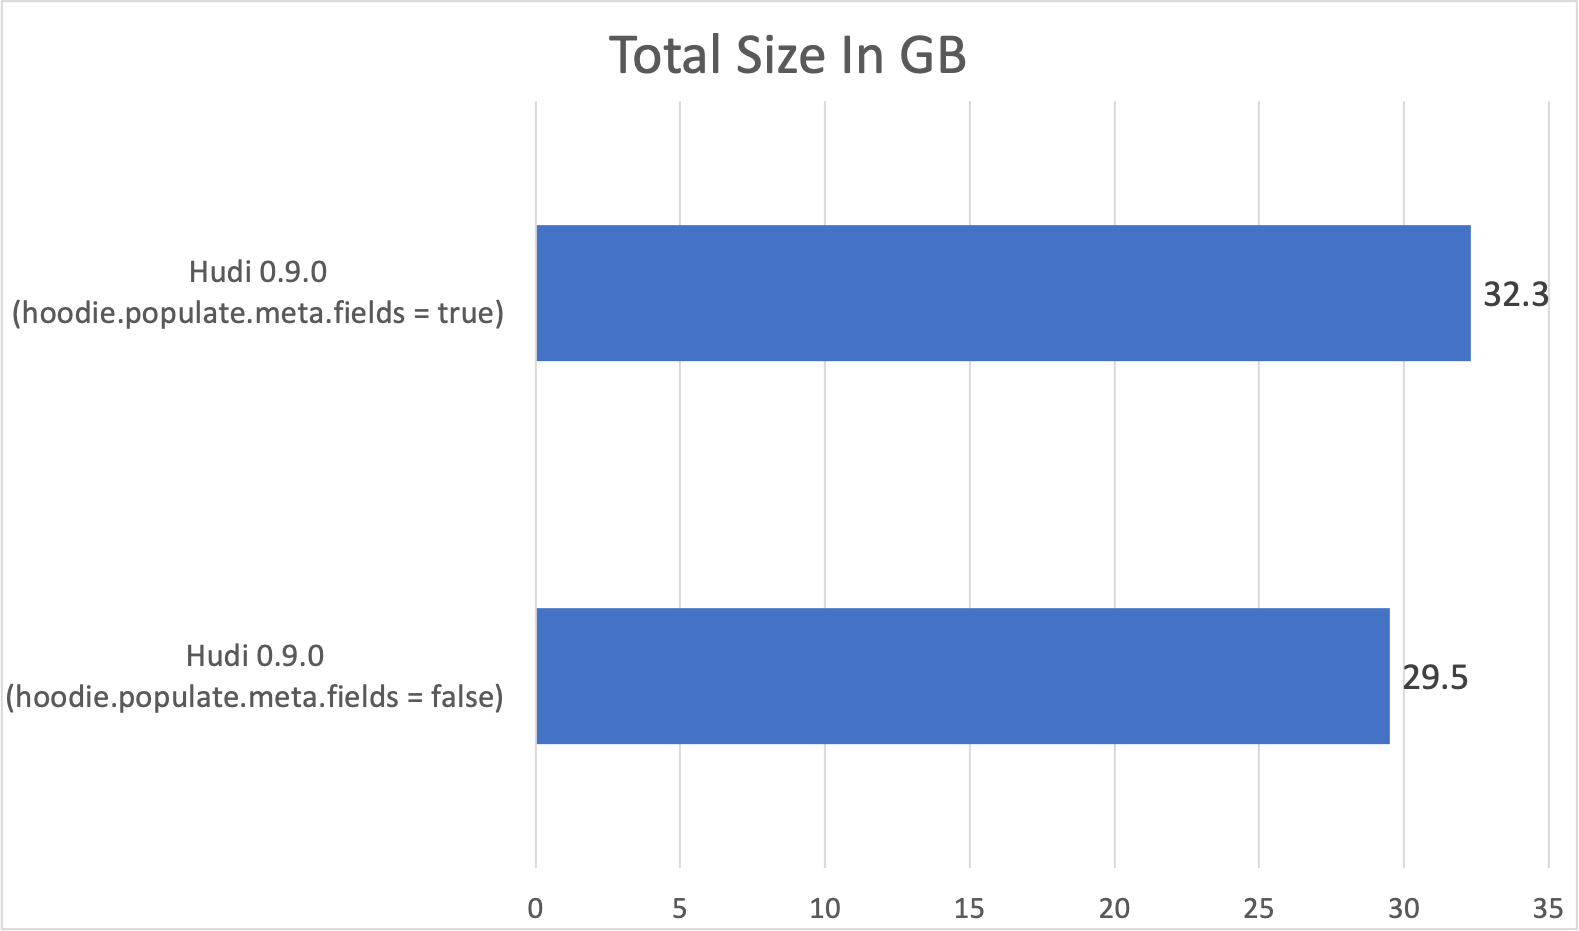
The function is turned off by default, and it may be enabled by setting hoodie.populate.meta.fields to false. We measured the write efficiency and storage footprint enhancements utilizing Bulk Insert with public Amazon Buyer Critiques dataset. Right here is the code snippet that we used:
The experiment was run on a 4 node c4.2xlarge EMR cluster (one chief, three core). We noticed a 10.63% enchancment within the write runtime efficiency, and a 8.67% discount in storage footprint with digital keys enabled. The next graph compares the majority insert runtime and desk measurement with and with out digital keys (decrease is best):
Timeline Server-based Marker Mechanism
Apache Hudi helps the automated cleansing up of uncommitted information written throughout write operations. This cleansing is supported by producing marker recordsdata corresponding to every information file, which serves as a technique to trace information recordsdata of curiosity slightly than having to scan the whole desk by itemizing the entire recordsdata. Though the present marker mechanism is rather more environment friendly than scanning the whole desk for uncommitted information recordsdata, it might nonetheless have a efficiency affect for Amazon S3 information lakes. For instance, writing a big variety of marker recordsdata (one per-data file) after which deleting them following a profitable commit may take a non-trivial period of time, typically within the order of a number of minutes. As well as, it has the potential to hit Amazon S3 throttling limits when a big variety of information/marker recordsdata are being written concurrently.
Apache Hudi 0.9.0 introduces a brand new timeline server primarily based implementation of this marker mechanism. This makes it extra environment friendly for Amazon S3 workloads by enhancing the general write efficiency, in addition to considerably lowering the likelihood of hitting Amazon S3 throttle limits. The brand new mechanism makes use of Hudi’s timeline server part as a central place for processing the entire marker creation/deletion requests (from all executors), which permits for batching of those requests and decreasing the variety of requests to Amazon S3. Due to this fact, customers with Amazon S3 information lakes can leverage this to enhance write operations efficiency and keep away from throttling attributable to marker recordsdata administration. It could be particularly impactful for eventualities the place a big variety of information recordsdata (e.g., 10k or extra) are being written.
This new mechanism is not enabled by default, and it may be enabled by setting hoodie.write.markers.kind to timeline_server_based, for the write operation. For extra particulars in regards to the function, discuss with this weblog put up by the Apache Hudi neighborhood.
Extra Enhancements
DynamoDB-based Locking
Optimistic Concurrency Management was one of many main options launched with Apache Hudi 0.8.0 to permit a number of concurrent writers to ingest information into the identical Hudi desk. The function requires buying locks for which both Zookeeper (default on EMR) or Hive Metastore could possibly be used. Nevertheless, these lock suppliers require the entire writers to be working on the identical cluster on which the Zookeeper/Hive Metastore is working.
Apache Hudi 0.9.0 on Amazon EMR has launched DynamoDB as a lock supplier. This may let a number of writers working throughout completely different clusters ingest information into the identical Hudi desk. This function was initially added to Hudi 0.9.0 on Amazon EMR, and it contributed again to open supply Hudi in model 0.10.0. To configure this, the next properties ought to be set:
| Configuration | Worth | Description | Required |
| hoodie.write.lock.supplier | org.apache.hudi.shopper. |
Lock Supplier implementation for use | Sure |
| hoodie.write.lock.dynamodb. desk |
<String> | DynamoDB desk identify for use for buying locks. If the desk doesn’t exist, it will likely be created. The identical desk can be utilized throughout all your Hudi jobs working on the identical or completely different tables | Sure |
| hoodie.write.lock.dynamodb. partition_key |
<String> | String Worth for use for the locks desk partition key attribute. It should be a string that uniquely identifies a Hudi desk, such because the Hudi desk identify | No. Default: Hudi Desk Title |
| hoodie.write.lock.dynamodb. area |
<String> | AWS Area through which the DynamoDB locks desk exists, or should be created. |
No. Default:
|
| hoodie.write.lock.dynamodb. billing_mode |
<String> | DynamoDB billing mode for use for the locks desk whereas creating. If the desk already exists, then this doesn’t have an impact | No. Default:PAY_PER_REQUEST |
| hoodie.write.lock.dynamodb. read_capacity |
<Integer> | DynamoDB learn capability for use for the locks desk whereas creating. If the desk already exists, then this doesn’t have an impact | No. Default: 20 |
| hoodie.write.lock.dynamodb. write_capacity |
<Integer> | DynamoDB write capability for use for the locks desk whereas creating. If the desk already exists, then this doesn’t have an impact | No. Default: 10 |
Moreover, Optimistic Concurrency Management should be enabled by way of the next:
You possibly can seamlessly configure these properties on the cluster degree, utilizing EMR Configurations API with hudi-defaults classification, to keep away from having to configure it with each job.
Delete partitions
Apache Hudi 0.9.0 introduces a DELETE_PARTITION operation for its Spark Information Supply API that may be leveraged to delete partitions. Here’s a scala instance of leverage this operation:
Nevertheless, there’s a recognized problem:
- Hive Sync fails when carried out together with DELETE_PARTITION operation due to a bug. Hive Sync will succeed for any future insert/upsert/delete operation carried out following the delete partition operation. This bug has been fastened in Hudi launch 0.10.0.
Asynchronous Clustering
Apache Hudi 0.9.0 introduces assist for asynchronous clustering by way of Spark structured streaming sink and Delta Streamer. This lets customers proceed ingesting information into the information lake, whereas the clustering service continues to run within the background to reorganize information for improved question efficiency and optimum file sizes. That is made doable with the Optimistic Concurrency Management function launched in Hudi 0.8.0. At present, clustering can solely be scheduled for partitions that aren’t receiving any concurrent updates. Extra particulars on get began with this function could be discovered on this weblog put up.
Conclusion
On this put up, we shared among the new and thrilling options in Hudi 0.9.0 accessible on Amazon EMR variations 5.34 and 6.5.0 and later. These new options allow the flexibility for information pipelines to be constructed solely with SQL statements, thereby making it simpler to construct transactional information lakes on Amazon S3.
As a subsequent step, for a arms on expertise on Hudi 0.9.0 on EMR, check out the pocket book right here on EMR Studio utilizing Amazon EMR model 6.5.0 and tell us your suggestions.
In regards to the Authors
 Kunal Gautam is a Senior Massive Information Architect at Amazon Internet Companies. Having expertise in constructing his personal Startup and working together with enterprises, he brings a singular perspective to get individuals, enterprise and expertise work in tandem for patrons. He’s enthusiastic about serving to clients of their digital transformation journey and allows them to construct scalable information and advance analytics options to achieve well timed insights and make crucial enterprise choices. In his spare time, Kunal enjoys Marathons, Tech Meetups and Meditation retreats.
 Gabriele Cacciola is a Senior Information Architect working for the Skilled Service crew with Amazon Internet Companies. Coming from a strong Startup expertise, he at the moment helps enterprise clients throughout EMEA implement their concepts, innovate utilizing the newest tech and construct scalable information and analytics options to make crucial enterprise choices. In his free time, Gabriele enjoys soccer and cooking.
 Udit Mehrotra is a software program improvement engineer at Amazon Internet Companies and an Apache Hudi PMC member/committer. He works on cutting-edge options of Amazon EMR and can also be concerned in open-source tasks equivalent to Apache Hudi, Apache Spark, Apache Hadoop, and Apache Hive. In his spare time, he likes to play guitar, journey, binge watch, and hang around with buddies.
[ad_2]

