


[ad_1]
Earlier than an information scientist can write a report on analytics or practice a machine studying (ML) mannequin, they should perceive the form and content material of their information. This exploratory information evaluation is iterative, with every stage of the cycle typically involving the identical primary strategies: visualizing information distributions and computing abstract statistics like row depend, null depend, imply, merchandise frequencies, and many others. Sadly, manually producing these visualizations and statistics is cumbersome and error inclined, particularly for big datasets. To deal with this problem and simplify exploratory information evaluation, we’re introducing information profiling capabilities within the Databricks Pocket book.
Profiling information within the Pocket book
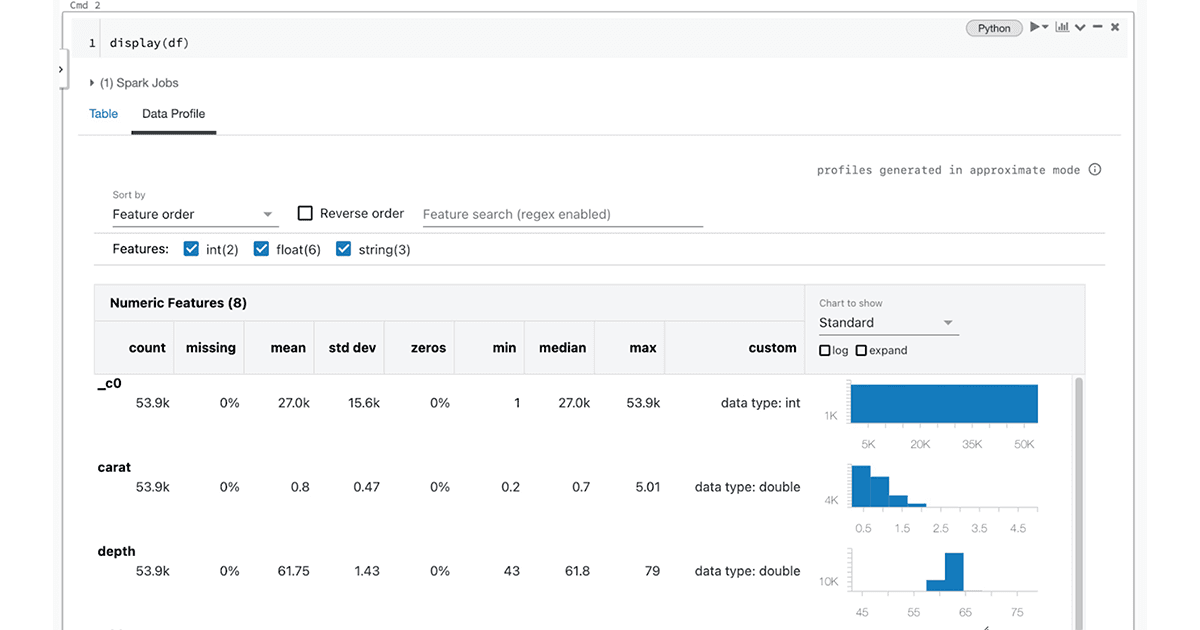
Information groups engaged on a cluster operating DBR 9.1 or newer have two methods to generate information profiles within the Pocket book: by way of the cell output UI and by way of the dbutils library. When viewing the contents of an information body utilizing the Databricks show perform (AWS|Azure|Google) or the outcomes of a SQL question, customers will see a “Information Profile” tab to the fitting of the “Desk” tab within the cell output. Clicking on this tab will robotically execute a brand new command that generates a profile of the info within the information body. The profile will embrace abstract statistics for numeric, string, and date columns in addition to histograms of the worth distributions for every column. Word that this command will profile your entire information set within the information body or SQL question outcomes, not simply the portion displayed within the desk (which could be truncated).

Underneath the hood, the pocket book UI points a brand new command to compute an information profile, which is carried out by way of an robotically generated Apache Spark™ question for every dataset. This performance can also be accessible via the dbutils API in Python, Scala, and R, utilizing the dbutils.information.summarize(df) command. For extra info, see the documentation (AWS|Azure|Google).
Check out information profiles right this moment when previewing Dataframes in Databricks notebooks!
[ad_2]

