


[ad_1]
MongoDB is the hottest NoSQL database right this moment, by some measures, even taking up conventional SQL databases like MySQL, which have been the de facto commonplace for a few years. MongoDB’s doc mannequin and versatile schemas permit for speedy iteration in functions. MongoDB is designed to scale out to large datasets and workloads, so builders know they won’t be restricted by their database. MongoDB helps quite a lot of indexes, which speed up selective queries in a lot the identical means as a SQL database.
Nonetheless, there comes a degree within the lifetime of an utility when a secondary index or reproduction of the manufacturing database is required. As a NoSQL database, MongoDB shouldn’t be constructed to carry out for JOINs, and can’t run SQL queries. If you wish to run analytical queries that mixture a considerable amount of knowledge, operating them on the first manufacturing database dangers interrupting the efficiency of that database for utility serving queries. A secondary database, designed for serving giant analytic queries, can obviate that danger.
Exterior Indexing Utilizing Rockset
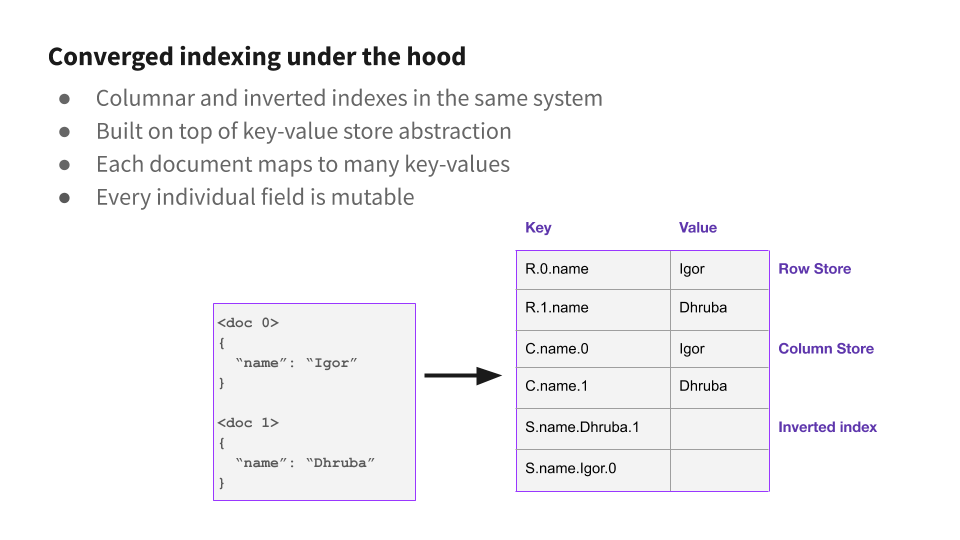
Rockset just lately partnered with MongoDB to construct an integration that enables Rockset for use as an exterior indexing layer. Rockset makes use of Converged Indexing to speed up queries with minimal configuration. Each doc is listed on each subject, even nested fields inside arrays or objects. Rockset indexes each subject routinely so customers don’t must construct indexes to make queries quick – queries are listed by default. There is no such thing as a restrict to the variety of fields which could be ingested and listed. Rockset is designed to scale effectively for paperwork with hundreds of fields or extra.

Our distinctive strategy to indexing usually leaves folks with questions. How can we keep indexes on each subject when paperwork can keep hundreds and even thousands and thousands of fields? What kind of queries can make the most of these indexes? By design, it isn’t obligatory to grasp Rockset’s indexing engine as a way to use Rockset. Nonetheless, it may be useful to grasp how Rockset indexes knowledge, and the way Rockset indexes examine to different techniques, particularly indexing in MongoDB, when transitioning to Rockset.
Single Discipline Indexes
In MongoDB, you possibly can create a single subject index on a subject to shortly choose all paperwork with a specific worth of a subject, or a contiguous vary of values.
Rockset indexes are very related, however they’re created routinely for each subject, and there’s no restrict to the variety of indexes you possibly can have. When Rockset ingests a doc, each scalar subject is routinely added to an inverted index. This consists of fields inside arrays or objects. For every subject, we retailer a map from every worth to the set of paperwork which comprise that worth. To guage a question with an equality predicate (say SELECT * FROM folks WHERE title="Ben"), Rockset finds the inverted index entry for desired worth (Ben), finds the paperwork which match and appears up the entire different fields for that doc.
Compound Indexes
You should utilize compound indexes in MongoDB if you wish to search a group with constraints on two subject concurrently. Compound indexes are nice for equality predicates and sure vary predicates, however don’t help all combos of predicates and type orders.
Rockset makes use of a extra versatile strategy just like MongoDB’s index intersection. For each subject, we retailer the listing of paperwork which comprise every distinct worth. When you have predicates on a number of fields, we retrieve the set of paperwork which match every predicate from the index, and take the intersection (AND) or the union (OR). Whereas this strategy requires minimal configuration and is quick for many queries, in some circumstances a real compound index can outperform index intersection. If Rockset customers need the performance of a compound index, they’ll specify a subject mapping to mix the fields they wish to index on to create a brand new subject, and use an index on that mixed subject.
Rockset can intersect the consequence units of various indexes effectively as a result of inside every worth, the paperwork are all sorted in the identical order. Subsequently we are able to intersect two units in streaming trend, which is each quick and reminiscence environment friendly. For evaluating vary predicates, we use a knowledge construction known as a static vary tree. We group numeric values and timestamps into buckets at numerous ranges of granularity so we are able to discover paperwork with a spread of values by combing a small variety of distinct units.
Multikey Indexes
MongoDB multikey indexes permit customers to index values inside arrays. This accelerates a question to seek out all paperwork the place an array comprises a worth. As an illustration, if every person has an inventory of pursuits, you need to use a multikey index to seek out all customers who’re focused on a given subject shortly.
Rockset routinely indexes each ingredient of each array, so queries like SELECT * FROM folks WHERE ARRAY_CONTAINS(pursuits, 'databases') are accelerated by an index with no configuration.
Textual content Indexes
Textual content indexes are helpful for textual content search – discovering all paperwork the place a string comprises a time period or set of phrases. MongoDB textual content index and Rockset textual content indexes are very related. Strings are first damaged down into tokens and normalized to the basis phrase primarily based on the language locale. then you possibly can rating strings primarily based on what number of search phrases they comprise.
Rockset textual content indexes are a little bit completely different from different indexes in that the person should perform a little work to create them explicitly. Rockset textual content search operates on an array of strings (phrases) somewhat than a single string. Rockset will routinely carry out this tokenization at ingest time when you arrange an applicable subject mapping. As soon as your knowledge is ingested, you need to use the SEARCH perform to make use of Rockset textual content search. This question will discover all candidates whose resumes comprise both the time period “rockset” or “sql”, and present those who comprise extra matches first:
SELECT
    *
FROM
    candidates
WHERE
    search(
        has_term(resume, 'rockset'),
        has_term(resume, 'sql')
    )
ORDER BY
    rating() DESC
Wildcard Indexes
In MongoDB, a wildcard index creates an index on all nested paths inside an object. That is helpful if the schema of the article is dynamic, and also you wish to routinely index new fields, or the article has many fields and also you wish to index all of them. Customers create a wildcard index by operating the next command:
db.assortment.createIndex( { "subject.$**" : 1 } )
At Rockset, we expect indexing knowledge routinely is a superb concept, so we construct indexes routinely on each subject, even deeply nested fields inside objects. Rockset basically has a wildcard index on the complete doc. In contrast to wildcard indexes in MongoDB, even nested geographical fields are listed. Whereas MongoDB restricts customers to a complete of 64 indexes, Rockset permits collections to have a vast variety of indexes.
2dsphere Indexes
MongoDB and Rockset each help quick queries for geographical shapes – close by factors, factors inside a polygon, and so on. Any knowledge which comprises latitudes and longitudes can doubtless profit from a geospatial index. In actual fact, each MongoDB and Rockset use the Google S2 library for storing and manipulating geographical objects. All you must do to begin utilizing Rockset’s geospatial index is to ingest geographically typed knowledge. For be taught extra about how Rockset geospatial indexes work and the way you need to use them, try Outdoors Lands, Airbnb Costs, and Rockset’s Geospatial Queries.
second and geoHaystack Indexes
MongoDB has 2dsphere indexes for indexing spherical geometry (i.e. the floor of the Earth) and second and geoHaystack indexes for indexing objects in flat, Euclidean geometry.
Sadly, Rockset doesn’t help second indexes in Euclidean area. As a workaround, you possibly can specify the 2 coordinates as separate fields, and write a question which makes use of each fields. As an illustration, if you wish to discover all (x, y) factors close to (1, 1), you could possibly run the next question, and it might intersect the set of factors with x in (0, 2) and y in (0, 2):
SELECT * FROM factors WHERE x > 0 AND x < 2 AND y > 0 AND y < 2
Another choice is to transform your factors into latitude/longitude coordinates in a small vary (say -1 to 1), and use Rockset’s geospatial index. Whereas outcomes gained’t be precise because of the curvature of a sphere, inside a small vary the floor of a sphere approximates a aircraft.
Hashed Indexes
When you create a hashed index on a subject x in MongoDB, it creates a mapping from the hash of x to all of the paperwork which comprise that worth of x (a posting listing). Hashed indexes are helpful for equality predicates. Rockset’s inverted index is comparable, in that we retailer a posting listing for each distinct worth, so it may be used to speed up an equality predicate. The Rockset inverted index doesn’t hash the values although, so it can be used to speed up vary predicates by merging the posting lists for all values in a spread.
Hashed indexes in MongoDB can be used to shard a group primarily based on a given hash key. Rockset doesn’t permit customers to manage sharding. As a substitute, paperwork are routinely sharded evenly to make sure writes and reads are balanced throughout all replicas. This maximizes parallelism and efficiency.
Getting the Most Out of Rockset’s Indexes
Rockset is designed to attenuate the quantity of person configuration to get quick queries, however there are nonetheless steps you possibly can take to make your queries quicker. You’ll be able to run EXPLAIN on the question in query to see how the question is being executed. When you see index filter, the question is being accelerated by a number of indexes.
api.rs2.usw2.rockset.com> EXPLAIN SELECT * from folks WHERE age > 18;
+----------------------------------------------------------------------------------------------------------------+
| EXPLAIN                                                                                                        |
|----------------------------------------------------------------------------------------------------------------|
| choose *:$2                                                                                                    |
|   reshuffle on_final                                                                                           |
|     index filter on commons.folks: fields($2=*, $1=age), question($1:float(18,inf], int(18,9223372036854775807]) |
+----------------------------------------------------------------------------------------------------------------+
Listed below are just a few frequent causes your question could not use an index:
- When you’re looking out by a LIKE sample or common expression with a wildcard at first (i.e.,
WHERE haystack LIKE %needle%), we can not use an index. If you’re looking for a specific phrase or token, you need to attempt making a textual content index with a subject mapping, and use textual content search as a substitute of LIKE. - A question which selects paperwork primarily based on the output of a perform (i.e.
WHERE DATE_PARSE(creation_date, '%Y/%m/%d') = DATE(2020, 7, 13)) Rockset can not apply the index. You’ll be able to both rewrite the predicate to use on to a subject (WHERE creation_date="2020/07/13") or create a subject mapping with the output of the perform, then apply a predicate on that. - The place doable, categorical predicates as ranges. As an illustration, if you wish to discover all strings which begin with an higher case letter, use
WHERE my_string >= 'A' AND my_string <= '['somewhat thanWHERE UPPER(SUBSTR(my_string, 1, 1)) = SUBSTR(my_string, 1, 1).
You could find extra recommendation on accelerating your queries within the question efficiency information.
Different MongoDB assets:
[ad_2]

