


[ad_1]
It is a visitor publish co-written by Erik Franco at Ibotta.
Ibotta is a free money again rewards and funds app that offers shoppers actual money for on a regular basis purchases once they store and pay by means of the app. Ibotta offers hundreds of the way for shoppers to earn money on their purchases by partnering with greater than 1,500 manufacturers and retailers.
At Ibotta, we course of terabytes of information every single day. Our imaginative and prescient is to permit for these datasets to be simply utilized by information scientists, decision-makers, machine studying engineers, and enterprise intelligence analysts to offer enterprise insights and regularly enhance the buyer and saver expertise. This technique of information democratization has confirmed to be a key pillar within the explosive progress Ibotta has skilled lately.
This progress has additionally led us to rethink and rebuild our inside know-how stacks. For instance, as our datasets started to double in dimension yearly mixed with complicated, nested JSON information buildings, it grew to become obvious that our information warehouse was not assembly the wants of our analytics groups. To unravel this, Ibotta adopted a knowledge lake resolution. The info lake proved to be an enormous success as a result of it was a scalable, cost-effective resolution that continued to meet the mission of information democratization.
The fast progress that was the impetus for the transition to a knowledge lake has now additionally pressured upstream engineers to transition away from the monolith structure to a microservice structure. We now use event-driven microservices to construct fault-tolerant and scalable techniques that may react to occasions as they happen. For instance, we’ve a microservice answerable for funds. Every time a fee happens, the service emits a PaymentCompleted occasion. Different providers could pay attention to those PaymentCompleted occasions to set off different actions, corresponding to sending a thanks e-mail.
On this publish, we share how Ibotta constructed a self-service information lake utilizing AWS Glue. AWS Glue is a serverless information integration service that makes it simple to find, put together, and mix information for analytics, machine studying, and software improvement.
Problem: Becoming versatile, semi-structured schemas into relational schemas
The transfer to an event-driven structure, whereas extremely invaluable, introduced a number of challenges. Our analytics groups use these occasions to be used circumstances the place low-latency entry to real-time information is anticipated, corresponding to fraud detection. These real-time techniques have fostered a brand new space of progress for Ibotta and complement effectively with our present batch-based information lake structure. Nevertheless, this transformation introduced two challenges:
- Our occasions are semi-structured and deeply nested JSON objects that don’t translate effectively to relational schemas. Occasions are additionally versatile in nature. This flexibility permits our upstream engineering groups to make adjustments as wanted and thereby permits Ibotta to maneuver shortly with a view to capitalize on market alternatives. Sadly, this flexibility makes it very troublesome to maintain schemas updated.
- Including to those challenges, within the final 3 years, our analytics and platform engineering groups have doubled in dimension. Our information processing staff, nonetheless, has stayed the identical dimension largely because of problem in hiring certified information engineers who possess specialised abilities in growing scalable pipelines and business demand. This meant that our information processing staff couldn’t sustain with the requests from our analytics groups to onboard new information sources.
Answer: A self-service information lake
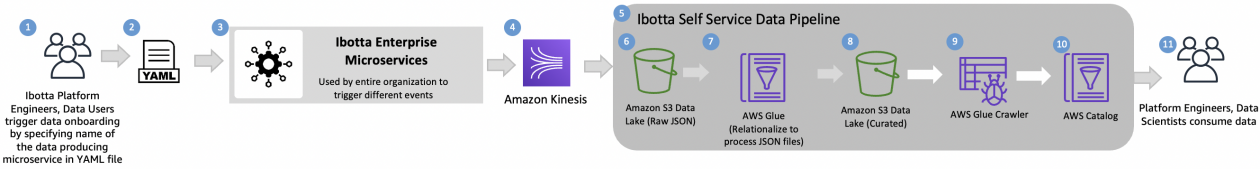
To unravel these points, we determined that it wasn’t sufficient for the information lake to offer self-service information consumption options. We additionally wanted self-service information pipelines. These would offer each the platform engineering and analytics groups with a path to make their information obtainable inside the information lake and with minimal to no information engineering intervention crucial. The next diagram illustrates our self-service information ingestion pipeline.
The pipeline consists of the next elements:
- Ibotta information stakeholders – Our inside information stakeholders needed the potential to mechanically onboard datasets. This person base consists of platform engineers, information scientists, and enterprise analysts.
- Configuration file – Our information stakeholders replace a YAML file with particular particulars on what dataset they should onboard. Sources for these datasets embody our enterprise microservices.
- Ibotta enterprise microservices – Microservices make up the majority of our Ibotta platform. Many of those microservices make the most of occasions to asynchronously talk essential info. These occasions are additionally invaluable for deriving analytics insights.
- Amazon Kinesis – After the configuration file is up to date, information is straight away streamed to Amazon Kinesis. Amazon Kinesis makes it simple to gather, course of, and analyze real-time, streaming information so you may get well timed insights and react shortly to new info. Streaming the information by means of Kinesis Information Streams and Kinesis Information Firehose offers us the pliability to research the information in actual time whereas additionally permitting us to retailer the information in Amazon Easy Storage Service (Amazon S3).
- Ibotta self-service information pipeline – That is the place to begin of our information processing. We use Apache Airflow to orchestrate our pipelines as soon as each hour.
- Amazon S3 uncooked information – Our information lands in Amazon S3 with none transformation. The complicated nature of the JSON is retained for future processing or validation.
- AWS Glue – Our purpose now could be to take the complicated nested JSON and create an easier construction. AWS Glue offers a set of built-in transforms that we use to course of this information. One of many transforms is Relationalize—an AWS Glue rework that takes semi-structured information and transforms it right into a format that may be extra simply analyzed by engines like Presto. This characteristic signifies that our analytics groups can proceed to make use of the analytics engines they’re comfy with and thereby reduce the influence of transitioning from relational information sources to semi-structured occasion information sources. The Relationalize operate can flatten nested buildings and create a number of dynamic frames. We use 80 traces of code to transform any JSON-based microservice message to a consumable desk. We have now supplied this code base right here as a reference and never for reuse.
- Amazon S3 curated – We then retailer the relationalized buildings as Parquet format in Amazon S3.
- AWS Glue crawler – AWS Glue crawlers enable us to mechanically uncover schema and catalogs within the AWS Glue Information Catalog. This characteristic is a core part of our self-service information pipelines as a result of it removes the requirement of getting a knowledge engineer manually create or replace the schemas. Beforehand, if a change wanted to happen, it flowed by means of a communication path that included platform engineers, information engineers, and analytics. AWS Glue crawlers successfully take away the information engineers from this communication path. This implies new datasets or adjustments to datasets are made obtainable shortly inside the information lake. It additionally frees up our information engineers to proceed engaged on enhancements to our self-service information pipelines and different information paved roadmap options.
- AWS Glue Information Catalog – A standard drawback in rising information lakes is that the datasets can grow to be tougher and tougher to work with. A standard motive for it is a lack of discoverability of information inside the information lake in addition to a scarcity of clear understanding of what the datasets are conveying. The AWS Glue Catalog is a characteristic that works along with AWS Glue crawlers to offer information lake customers with searchable metadata for various information lake datasets. As AWS Glue crawlers uncover new datasets or updates, they’re recorded into the Information Catalog. You’ll be able to then add descriptions on the desk or fields ranges for these datasets. This cuts down on the extent of tribal data that exists between varied information lake shoppers and makes it simple for these customers to self-serve from the information lake.
- Finish-user information consumption – The top-users are the identical as our inside stakeholders known as out in Step 1.
Advantages
The AWS Glue capabilities we described make it a core part of constructing our self-service information pipelines. After we initially adopted AWS Glue, we noticed a three-fold lower in our OPEX prices as in comparison with our earlier information pipelines. This was additional enhanced when AWS Glue moved to per-second billing. Up to now, AWS Glue has allowed us to appreciate a five-fold lower in OPEX prices. Additionally, AWS Glue requires little to no handbook intervention to ingest and course of our over 200 complicated JSON objects. This enables Ibotta to make the most of AWS Glue every day as a key part in offering actionable information to the group’s rising analytics and platform engineering groups.
We took away the next learnings in constructing self-service information platforms:
Conclusion and subsequent steps
With the self-service information lake we’ve established, our enterprise groups are realizing the advantages of pace and agility. As subsequent steps, we’re going to enhance our self-service pipeline with the next options:
- AWS Glue streaming – Use AWS Glue streaming for real-time relationalization. With AWS Glue streaming, we are able to simplify our self-service pipelines by doubtlessly eliminating our orchestration layer whereas additionally getting information into the information lake sooner.
- Help for ACID transactions – Implement information codecs within the information lake that enable for ACID transactions. A advantage of this ACID layer is the power to merge streaming information into information lake datasets.
- Simplify information transport layers – Unify the information transport layers between the upstream platform engineering domains and the information area. From the time we first applied an event-driven structure at Ibotta to right this moment, AWS has supplied new providers corresponding to Amazon EventBridge and Amazon Managed Streaming for Apache Kafka (Amazon MSK) which have the potential to simplify sure aspects of our self-service and information pipelines.
We hope that this weblog publish will encourage your group to construct a self-service information lake utilizing serverless applied sciences to speed up what you are promoting objectives.
Concerning the Authors
Erik Franco is a Information Architect at Ibotta and is main Ibotta’s implementation of its next-generation information platform. Erik enjoys fishing and is an avid hiker. You’ll be able to usually discover him climbing one of many many trails in Colorado along with his beautiful spouse Marlene and fantastic canine Sammy.
Shiv Narayanan is International Enterprise Growth Supervisor for Information Lakes and Analytics options at AWS. He works with AWS prospects throughout the globe to strategize, construct, develop and deploy trendy information platforms. Shiv loves music, journey, meals and making an attempt out new tech.
Matt Williams is a Senior Technical Account Supervisor for AWS Enterprise Help. He’s enthusiastic about guiding prospects on their cloud journey and constructing modern options for complicated issues. In his spare time, Matt enjoys experimenting with know-how, all issues open air, and visiting new locations.
[ad_2]

