


[ad_1]
This can be a visitor put up by Kanti Chalasani, Division Director at Georgia Information Analytics Heart (GDAC). GDAC is housed inside the Georgia Workplace of Planning and Finances to facilitate ruled knowledge sharing between numerous state companies and departments.
The Workplace of Planning and Finances (OPB) established the Georgia Information Analytics Heart (GDAC) with the intent to offer knowledge accountability and transparency in Georgia. GDAC strives to assist the state’s authorities companies, educational establishments, researchers, and taxpayers with their knowledge wants. Georgia’s fashionable knowledge analytics heart will assist to securely harvest, combine, anonymize, and mixture knowledge.
On this put up, we share how GDAC created an analytics platform from scratch utilizing AWS providers and the way GDAC collaborated with the AWS Information Lab to speed up this challenge from design to construct in report time. The pre-planning periods, technical immersions, pre-build periods, and post-build periods helped us give attention to our goals and tangible deliverables. We constructed a prototype with a contemporary knowledge structure and shortly ingested extra knowledge into the information lake and the information warehouse. The aim-built knowledge and analytics providers allowed us to shortly ingest extra knowledge and ship knowledge analytics dashboards. It was extraordinarily rewarding to formally launch the GDAC public web site inside solely 4 months.
A mixture of clear route from OPB government stakeholders, enter from the educated and pushed AWS group, and the GDAC group’s drive and dedication to studying performed an enormous function on this success story. GDAC’s associate companies helped tremendously via well timed knowledge supply, knowledge validation, and evaluate.
We had a two-tiered engagement with the AWS Information Lab. Within the first tier, we participated in a Design Lab to debate our near-to-long-term necessities and create a best-fit structure. We mentioned the professionals and cons of varied providers that may assist us meet these necessities. We additionally had significant engagement with AWS material consultants from numerous AWS providers to dive deeper into one of the best practices.
The Design Lab was adopted by a Construct Lab, the place we took a smaller cross part of the larger structure and applied a prototype in 4 days. Throughout the Construct Lab, we labored in GDAC AWS accounts, utilizing GDAC knowledge and GDAC sources. This not solely helped us construct the prototype, but additionally helped us acquire hands-on expertise in constructing it. This expertise additionally helped us higher keep the product after we went reside. We had been capable of frequently construct on this hands-on expertise and share the information with different companies in Georgia.
Our Design and Construct Lab experiences are detailed beneath.
Step 1: Design Lab
We needed to face up a platform that may meet the information and analytics wants for the Georgia Information Analytics Heart (GDAC) and probably function a gold customary for different authorities companies in Georgia. Our goal with the AWS Information Design Lab was to provide you with an structure that meets preliminary knowledge wants and supplies ample scope for future growth, as our consumer base and knowledge quantity elevated. We needed every element of the structure to scale independently, with tighter controls on knowledge entry. Our goal was to allow simple exploration of knowledge with sooner response occasions utilizing Tableau knowledge analytics in addition to construct knowledge capital for Georgia. This may permit us to empower our policymakers to make data-driven choices in a well timed method and permit State companies to share knowledge and definitions inside and throughout companies via knowledge governance. We additionally burdened on knowledge safety, classification, obfuscation, auditing, monitoring, logging, and compliance wants. We needed to make use of purpose-built instruments meant for specialised goals.
Over the course of the 2-day Design Lab, we outlined our general structure and picked a scaled-down model to discover. The next diagram illustrates the structure of our prototype.
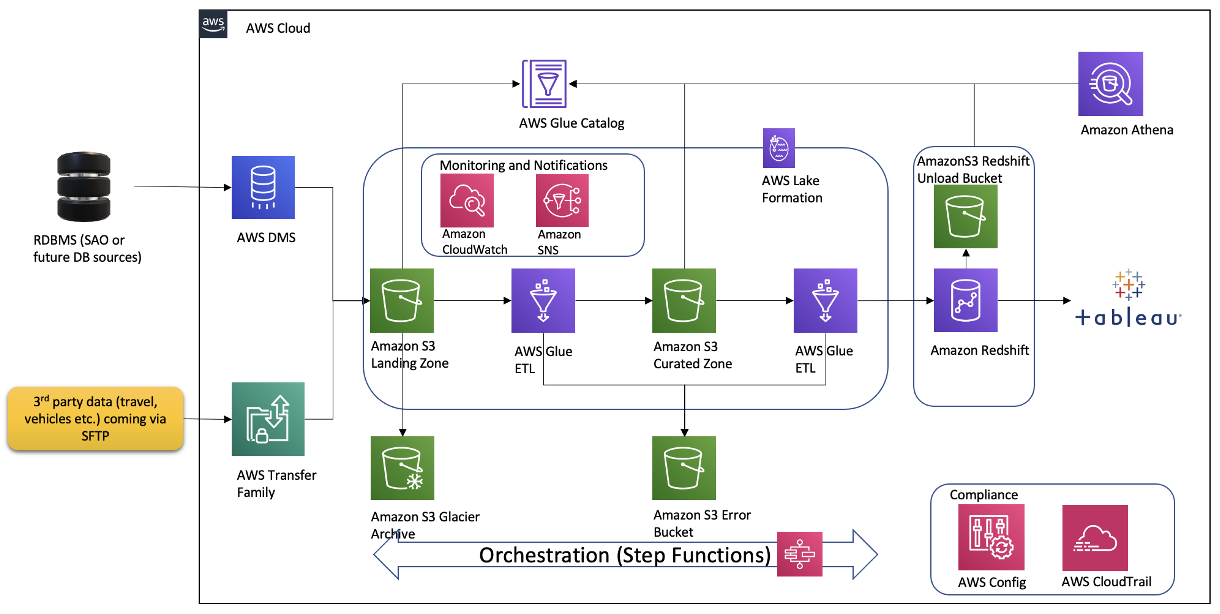
The structure accommodates the next key elements:
- Amazon Easy Storage Service (Amazon S3) for uncooked knowledge touchdown and curated knowledge staging.
- AWS Glue for extract, remodel, and cargo (ETL) jobs to maneuver knowledge from the Amazon S3 touchdown zone to Amazon S3 curated zone in optimum format and format. We used an AWS Glue crawler to replace the AWS Glue Information Catalog.
- AWS Step Capabilities for AWS Glue job orchestration.
- Amazon Athena as a robust device for a fast and in depth SQL knowledge evaluation and to construct a logical layer on the touchdown zone.
- Amazon Redshift to create a federated knowledge warehouse with conformed dimensions and star schemas for consumption by Tableau knowledge analytics.
Step 2: Pre-Construct Lab
We began with planning periods to construct foundational elements of our infrastructure: AWS accounts, Amazon Elastic Compute Cloud (Amazon EC2) cases, an Amazon Redshift cluster, a digital personal cloud (VPC), route tables, safety teams, encryption keys, entry guidelines, web gateways, a bastion host, and extra. Moreover, we arrange AWS Id and Entry Administration (IAM) roles and insurance policies, AWS Glue connections, dev endpoints, and notebooks. Recordsdata had been ingested through safe FTP, or from a database to Amazon S3 utilizing AWS Command Line Interface (AWS CLI). We crawled Amazon S3 through AWS Glue crawlers to construct Information Catalog schemas and tables for fast SQL entry in Athena.
The GDAC group participated in Immersion Days for coaching in AWS Glue, AWS Lake Formation, and Amazon Redshift in preparation for the Construct Lab.
We outlined the next because the success standards for the Construct Lab:
- Create ETL pipelines from supply (Amazon S3 uncooked) to focus on (Amazon Redshift). These ETL pipelines ought to create and cargo dimensions and details in Amazon Redshift.
- Have a mechanism to check the accuracy of the information loaded via our pipelines.
- Arrange Amazon Redshift in a personal subnet of a VPC, with applicable customers and roles recognized.
- Join from AWS Glue to Amazon S3 to Amazon Redshift with out going over the web.
- Arrange row-level filtering in Amazon Redshift based mostly on consumer login.
- Information pipelines orchestration utilizing Step Capabilities.
- Construct and publish Tableau analytics with connections to our star schema in Amazon Redshift.
- Automate the deployment utilizing AWS CloudFormation.
- Arrange column-level safety for the information in Amazon S3 utilizing Lake Formation. This enables for differential entry to knowledge based mostly on consumer roles to customers utilizing each Athena and Amazon Redshift Spectrum.
Step 3: 4-day Construct Lab
Following a sequence of implementation periods with our architect, we shaped the GDAC knowledge lake and arranged downstream knowledge pulls for the information warehouse with ruled knowledge entry. Information was ingested within the uncooked knowledge touchdown lake after which curated right into a staging lake, the place knowledge was compressed and partitioned in Parquet format.
It was empowering for us to construct PySpark Extract Remodel Masses (ETL) AWS Glue jobs with our meticulous AWS Information Lab architect. We constructed reusable glue jobs for the information ingestion and curation utilizing the code snippets supplied. The times had been rigorous and lengthy, however we had been thrilled to see our centralized knowledge repository come into fruition so quickly. Cataloging knowledge and utilizing Athena queries proved to be a quick and cost-effective manner for knowledge exploration and knowledge wrangling.
The serverless orchestration with Step Capabilities allowed us to place AWS Glue jobs right into a easy readable knowledge workflow. We frolicked designing for efficiency and partitioning knowledge to attenuate value and improve effectivity.
Database entry from Tableau and SQL Workbench/J had been arrange for my group. Our pleasure solely grew as we started constructing knowledge analytics and dashboards utilizing our dimensional knowledge fashions.
Step 4: Put up-Construct Lab
Throughout our post-Construct Lab session, we closed a number of unfastened ends and constructed extra AWS Glue jobs for preliminary and historic masses and append vs. overwrite methods. These methods had been picked based mostly on the character of the information in numerous tables. We returned for a second Construct Lab to work on constructing knowledge migration duties from Oracle Database through VPC peering, file processing utilizing AWS Glue DataBrew, and AWS CloudFormation for automated AWS Glue job era. When you’ve got a group of 4–8 builders on the lookout for a quick and straightforward basis for a whole knowledge analytics system, I might extremely advocate the AWS Information Lab.
Conclusion
All in all, with a really small group we had been capable of arrange a sustainable framework on AWS infrastructure with elastic scaling to deal with future capability with out compromising high quality. With this framework in place, we’re transferring quickly with new knowledge feeds. This may not have been potential with out the help of the AWS Information Lab group all through the challenge lifecycle. With this fast win, we determined to maneuver ahead and construct AWS Management Tower with a number of accounts in our touchdown zone. We introduced in professionals to assist arrange infrastructure and knowledge compliance guardrails and safety insurance policies. We’re thrilled to repeatedly enhance our cloud infrastructure, providers and knowledge engineering processes. This sturdy preliminary basis has paved the pathway to limitless knowledge initiatives in Georgia.
In regards to the Writer
 Kanti Chalasani serves because the Division Director for the Georgia Information Analytics Heart (GDAC) on the Workplace of Planning and Finances (OPB). Kanti is chargeable for GDAC’s knowledge administration, analytics, safety, compliance, and governance actions. She strives to work with state companies to enhance knowledge sharing, knowledge literacy, and knowledge high quality via this contemporary knowledge engineering platform. With over 26 years of expertise in IT administration, hands-on knowledge warehousing, and analytics expertise, she thrives for excellence.
 Vishal Pathak is an AWS Information Lab Options Architect. Vishal works with clients on their use circumstances, architects options to resolve their enterprise issues, and helps them construct scalable prototypes. Previous to his journey with AWS, Vishal helped clients implement BI, knowledge warehousing, and knowledge lake initiatives within the US and Australia.
[ad_2]

