


[ad_1]
This publish is authored by Giridhar G Jorapur, GE Aviation Digital Expertise.
Upkeep and overhauling of plane engines are important for GE Aviation to extend time on wing features and cut back store go to prices. Engine wash analytics present visibility into the numerous time on wing features that may be achieved by way of efficient water wash, foam wash, and different instruments. This empowers GE Aviation with digital insights that assist optimize water and foam wash procedures and maximize gasoline financial savings.
This publish demonstrates how we automated our engine wash analytics course of to deal with the complexity of ingesting knowledge from a number of knowledge sources and the way we chosen the correct programming paradigm to scale back the general time of the analytics job. Previous to automation, analytics jobs took roughly 2 days to finish and ran solely on an as-needed foundation. On this publish, we discover ways to course of large-scale knowledge utilizing AWS Glue and by integrating with different AWS providers reminiscent of AWS Lambda and Amazon EventBridge. We additionally talk about how you can obtain optimum AWS Glue job efficiency by making use of numerous methods.
Challenges
Once we thought of automating and growing the engine wash analytics course of, we noticed the next challenges:
- A number of knowledge sources – The analytics course of requires knowledge from totally different sources reminiscent of foam wash occasions from IoT programs, flight parameters, and engine utilization knowledge from a knowledge lake hosted in an AWS account.
- Massive dataset processing and sophisticated calculations – We wanted to run analytics for seven business product traces. One of many product traces has roughly 280 million data, which is rising at a charge of 30% yr over yr. We wanted analytics to run towards 1 million wash occasions and carry out over 2,000 calculations, whereas processing roughly 430 million flight data.
- Scalable framework to accommodate new product traces and calculations – As a result of dynamics of the use case, we wanted an extensible framework so as to add or take away new or present product traces with out affecting the present course of.
- Excessive efficiency and availability – We wanted to run analytics every day to replicate the most recent updates in engine wash occasions and modifications in flight parameter knowledge.
- Safety and compliance – As a result of the analytics processes contain flight and engine-related knowledge, the info distribution and entry want to stick to the stringent safety and compliance rules of the aviation trade.
Answer overview
The next diagram illustrates the structure of our wash analytics resolution utilizing AWS providers.
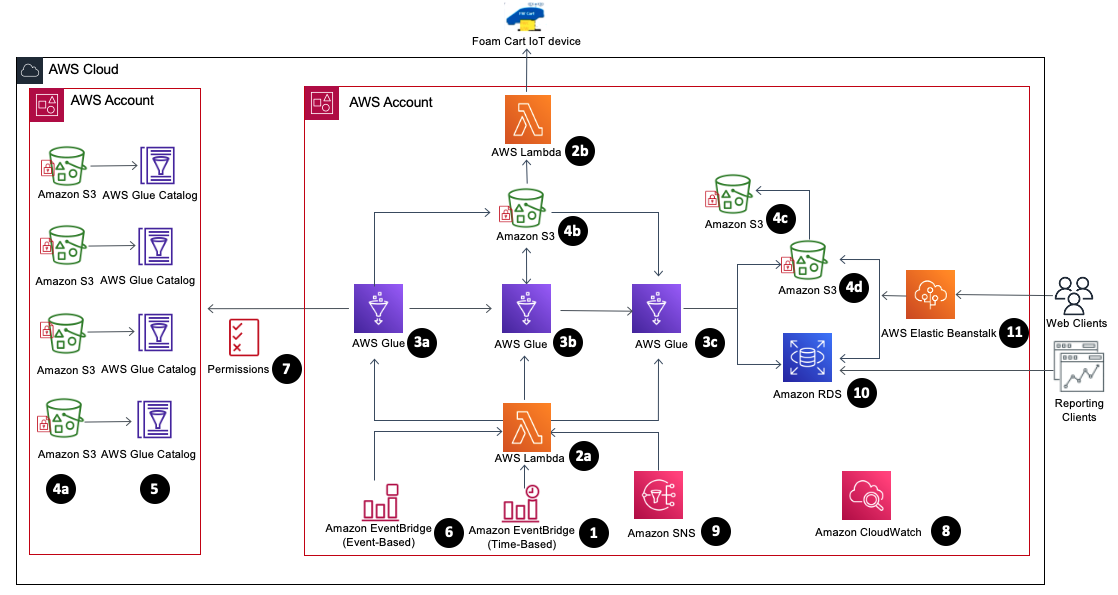
The answer consists of the next parts:
- EventBridge (1) – We use an EventBridge (time-based) to schedule the every day course of to seize the delta modifications between the runs.
- Lambda (2a) – Lambda orchestrates the AWS Glue jobs initiation, backup, and restoration on failure for every stage, using EventBridge (event-based) for the alerting of those occasions.
- Lambda (2b) – Foam cart occasions from IoT units are loaded into staging buckets in Amazon Easy Storage Service (Amazon S3) every day.
- AWS Glue (3) – The wash analytics have to deal with a small subset of information every day, however the preliminary historic load and transformation is large. As a result of AWS Glue is serverless, it’s simple to arrange and run with no upkeep.
- Copy job (3a) – We use an AWS Glue copy job to repeat solely the required subset of information from throughout AWS accounts by connecting to AWS Glue Information Catalog tables utilizing a cross-account AWS Identification and Entry Administration (IAM) position.
- Enterprise transformation jobs (3b, 3c) – When the copy job is full, Lambda triggers subsequent AWS Glue jobs. As a result of our jobs are each compute and reminiscence intensive, we use G2.x employee nodes. We will use Amazon CloudWatch metrics to fine-tune our jobs to make use of the correct employee nodes. To deal with advanced calculations, we cut up giant jobs up into a number of jobs by pipelining the output of 1 job as enter to a different job.
- Supply S3 buckets (4a) – Flights, wash occasions, and different engine parameter knowledge is on the market in supply buckets in a unique AWS account uncovered through Information Catalog tables.
- Stage S3 bucket (4b) – Information from one other AWS account is required for calculations, and all of the intermediate outputs from the AWS Glue jobs are written to the staging bucket.
- Backup S3 bucket (4c) – Every single day earlier than beginning the AWS Glue job, the day before today’s output from the output bucket is backed up within the backup bucket. In case of any job failure, the info is recovered from this bucket.
- Output S3 bucket (4d) – The ultimate output from the AWS Glue jobs is written to the output bucket.
Persevering with our evaluation of the structure parts, we additionally use the next:
- AWS Glue Information Catalog tables (5) – We catalog flights, wash occasions, and different engine parameter knowledge utilizing Information Catalog tables, that are accessed by AWS Glue copy jobs from one other AWS account.
- EventBridge (6) – We use EventBridge (event-based) to observe for AWS Glue job state modifications (SUCEEDED, FAILED, TIMEOUT, and STOPPED) and orchestrate the workflow, together with backup, restoration, and job standing notifications.
- IAM position (7) – We arrange cross-account IAM roles to repeat the info from one account to a different from the AWS Glue Information Catalog tables.
- CloudWatch metrics (8) – You possibly can monitor many alternative CloudWatch metrics. The next metrics may help you determine on horizontal or vertical scaling when fine-tuning the AWS Glue jobs:
- CPU load of the driving force and executors
- Reminiscence profile of the driving force
- ETL knowledge motion
- Information shuffle throughout executors
- Job run metrics, together with energetic executors, accomplished levels, and most wanted executors
- Amazon SNS (9) – Amazon Easy Notification Service (Amazon SNS) routinely sends notifications to the assist group on the error standing of jobs, to allow them to take corrective motion upon failure.
- Amazon RDS (10) – The ultimate reworked knowledge is saved in Amazon Relational Database Service (Amazon RDS) for PostgreSQL (along with Amazon S3) to assist legacy reporting instruments.
- Net software (11) – An online software is hosted on AWS Elastic Beanstalk, and is enabled with Auto Scaling uncovered for shoppers to entry the analytics knowledge.
Implementation technique
Implementing our resolution included the next concerns:
- Safety – The info required for operating analytics is current in several knowledge sources and totally different AWS accounts. We wanted to craft well-thought-out role-based entry insurance policies for accessing the info.
- Deciding on the correct programming paradigm – PySpark does lazy analysis whereas working with knowledge frames. For PySpark to work effectively with AWS Glue, we created knowledge frames with required columns upfront and carried out column-wise operations.
- Choosing the proper persistence storage – Writing to Amazon S3 allows a number of consumption patterns, and writes are a lot sooner because of parallelism.
If we’re writing to Amazon RDS (for supporting legacy programs), we have to be careful for database connectivity and buffer lock points whereas writing from AWS Glue jobs.
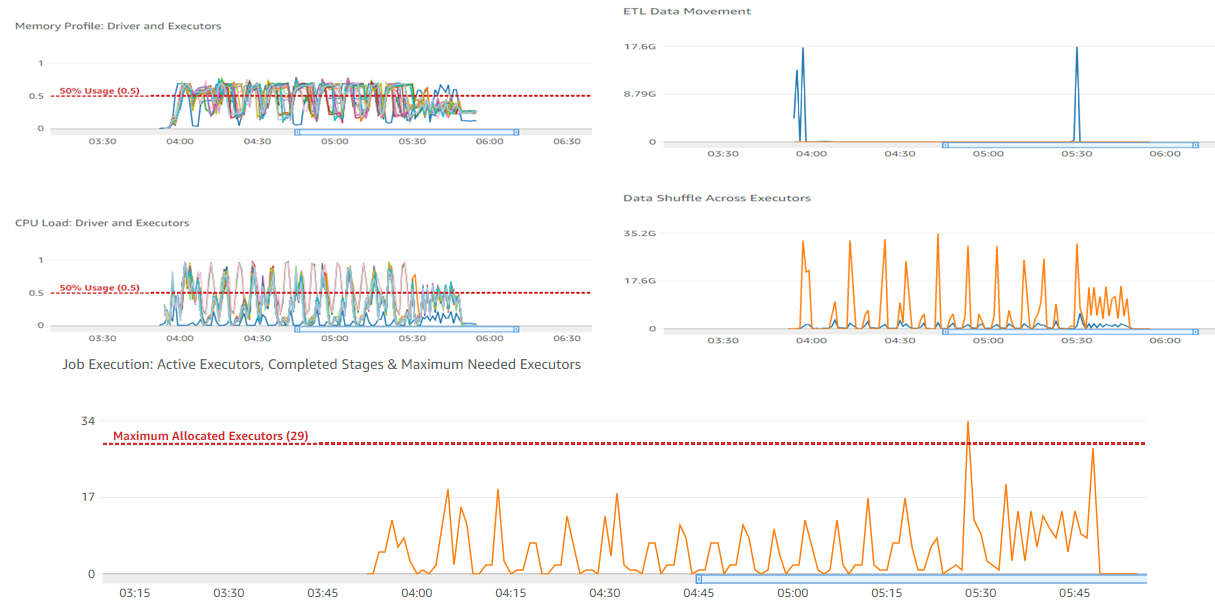
- Information partitioning – Figuring out the correct key mixture is essential for partitioning the info for Spark to carry out optimally. Our preliminary runs (with out knowledge partition) with 30 employees of kind G2.x took 2 hours and 4 minutes to finish.
The next screenshot reveals our CloudWatch metrics.
After a number of dry runs, we had been in a position to arrive at partitioning by a selected column (df.repartition(columnKey)) and with 24 employees of kind G2.x, the job accomplished in 2 hours and seven minutes. The next screenshot reveals our new metrics.
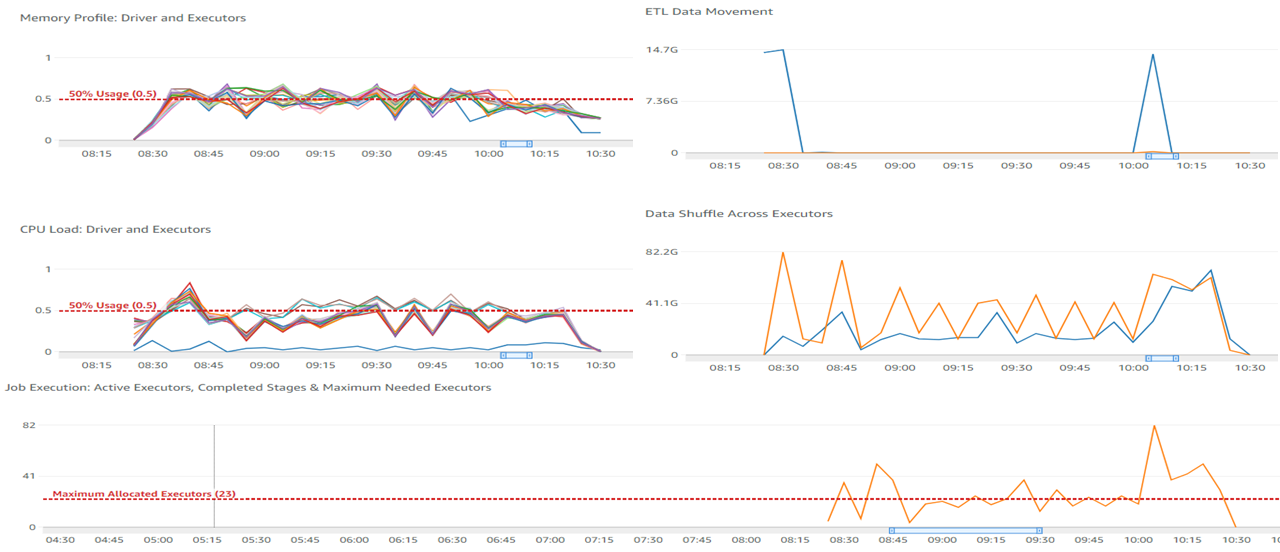
We will observe a distinction in CPU and reminiscence utilization—operating with even fewer nodes reveals a smaller CPU utilization and reminiscence footprint.
The next desk reveals how we achieved the ultimate transformation with the methods we mentioned.
| Iteration | Run Time | AWS Glue Job Standing | Technique |
| 1 | ~12 hours | Unsuccessful/Stopped | Preliminary iteration |
| 2 | ~9 hours | Unsuccessful/Stopped | Altering code to PySpark methodology |
| 3 | 5 hours, 11 minutes | Partial success | Splitting a fancy giant job into a number of jobs |
| 4 | 3 hours, 33 minutes | Success | Partitioning by column key |
| 5 | 2 hours, 39 minutes | Success | Altering CSV to Parquet file format whereas storing the copied knowledge from one other AWS account and intermediate leads to the stage S3 bucket |
| 6 | 2 hours, 9 minutes | Success | Infra scaling: horizontal and vertical scaling |
Conclusion
On this publish, we noticed how you can construct a cheap, maintenance-free resolution utilizing serverless AWS providers to course of large-scale knowledge. We additionally discovered how you can achieve optimum AWS Glue job efficiency with key partitioning, utilizing the Parquet knowledge format whereas persisting in Amazon S3, splitting advanced jobs into a number of jobs, and utilizing the correct programming paradigm.
As we proceed to solidify our knowledge lake resolution for knowledge from numerous sources, we are able to use Amazon Redshift Spectrum to serve numerous future analytical use instances.
Concerning the Authors
 Giridhar G Jorapur is a Workers Infrastructure Architect at GE Aviation. On this position, he’s accountable for designing enterprise functions, migration and modernization of functions to the cloud. Aside from work, Giri enjoys investing himself in religious wellness. Join him on LinkedIn.
[ad_2]

