


[ad_1]
ENGIE—one of many largest utility suppliers in France and a world participant within the zero-carbon power transition—produces, transports, and offers electrical energy, gasoline, and power providers. With 160,000 workers worldwide, ENGIE is a decentralized group and operates 25 enterprise items with a excessive degree of delegation and empowerment. ENGIE’s decentralized world buyer base had collected a number of information, and it required a wiser, distinctive method and answer to align its initiatives and supply information that’s ingestible, organizable, governable, sharable, and actionable throughout its world enterprise items.
In 2018, the corporate’s enterprise management determined to speed up its digital transformation via information and innovation by turning into a data-driven firm. Yves Le Gélard, chief digital officer at ENGIE, explains the corporate’s objective: “Sustainability for ENGIE is the alpha and the omega of every thing. That is our raison d’être. We assist massive firms and the most important cities on earth of their makes an attempt to transition to zero carbon as rapidly as doable as a result of it’s truly the primary query for humanity right now.”
ENGIE, as with all different huge enterprise, is utilizing a number of extract, rework, and cargo (ETL) instruments to ingest information into their information lake on AWS. Nonetheless, they normally have costly licensing plans. “The corporate wanted a uniform technique of gathering and analyzing information to assist clients handle their worth chains,” says Gregory Wolowiec, the Chief Expertise Officer who leads ENGIE’s information program. ENGIE needed a free-license software, properly built-in with a number of applied sciences and with a steady integration, steady supply (CI/CD) pipeline to extra simply scale all their ingestion course of.
ENGIE began utilizing Amazon Managed Workflows for Apache Airflow (Amazon MWAA) to unravel this difficulty and began shifting numerous information sources from on-premise purposes and ERPs, AWS providers like Amazon Redshift, Amazon Relational Database Service (Amazon RDS), Amazon DynamoDB, exterior providers like Salesforce, and different cloud suppliers to a centralized information lake on high of Amazon Easy Storage Service (Amazon S3).
Amazon MWAA is utilized in explicit to gather and retailer harmonized operational and company information from completely different on-premises and software program as a service (SaaS) information sources right into a centralized information lake. The aim of this information lake is to create a “group efficiency cockpit” that allows an environment friendly, data-driven evaluation and considerate decision-making by the Engie Administration board.
On this put up, we share how ENGIE created a CI/CD pipeline for an Amazon MWAA mission template utilizing an AWS CodeCommit repository and plugged it into AWS CodePipeline to construct, take a look at, and package deal the code and customized plugins. On this use case, we developed a customized plugin to ingest information from Salesforce primarily based on the Airflow Salesforce open-source plugin.
Answer overview
The next diagrams illustrate the answer structure defining the carried out Amazon MWAA atmosphere and its related pipelines. It additionally describes the client use case for Salesforce information ingestion into Amazon S3.
The next diagram reveals the structure of the deployed Amazon MWAA atmosphere and the carried out pipelines.
The previous structure is absolutely deployed through infrastructure as code (IaC). The implementation contains the next:
- Amazon MWAA atmosphere – A customizable Amazon MWAA atmosphere packaged with plugins and necessities and configured in a safe method.
- Provisioning pipeline – The admin staff can handle the Amazon MWAA atmosphere utilizing the included CI/CD provisioning pipeline. This pipeline features a CodeCommit repository plugged into CodePipeline to repeatedly replace the atmosphere and its plugins and necessities.
- Challenge pipeline – This CI/CD pipeline comes with a CodeCommit repository that triggers CodePipeline to repeatedly construct, take a look at and deploy DAGs developed by customers. As soon as deployed, these DAGs are made out there within the Amazon MWAA atmosphere.
The next diagram reveals the info ingestion workflow, which incorporates the next steps:
- The DAG is triggered by Amazon MWAA manually or primarily based on a schedule.
- Amazon MWAA initiates information assortment parameters and calculates batches.
- Amazon MWAA distributes processing duties amongst its employees.
- Information is retrieved from Salesforce in batches.
- Amazon MWAA assumes an AWS Id and Entry Administration (IAM) position with the mandatory permissions to retailer the collected information into the goal S3 bucket.

This AWS Cloud Growth Package (AWS CDK) assemble is carried out with the next safety greatest practices:
- With the precept of least privilege, you grant permissions to solely the sources or actions that customers must carry out duties.
- S3 buckets are deployed with safety compliance guidelines: encryption, versioning, and blocking public entry.
- Authentication and authorization administration is dealt with with AWS Single Signal-On (AWS SSO).
- Airflow shops connections to exterior sources in a safe method both in Airflow’s default secrets and techniques backend or an alternate secrets and techniques backend resembling AWS Secrets and techniques Supervisor or AWS Methods Supervisor Parameter Retailer.
For this put up, we step via a use case utilizing the info from Salesforce to ingest it into an ENGIE information lake with a view to rework it and construct enterprise stories.
Conditions for deployment
For this walkthrough, the next are conditions:
- Primary information of the Linux working system
- Entry to an AWS account with administrator or energy consumer (or equal) IAM position insurance policies hooked up
- Entry to a shell atmosphere or optionally with AWS CloudShell
Deploy the answer
To deploy and run the answer, full the next steps:
- Set up AWS CDK.
- Bootstrap your AWS account.
- Outline your AWS CDK atmosphere variables.
- Deploy the stack.
Set up AWS CDK
The described answer is absolutely deployed with AWS CDK.
AWS CDK is an open-source software program growth framework to mannequin and provision your cloud software sources utilizing acquainted programming languages. If you wish to familiarize your self with AWS CDK, the AWS CDK Workshop is a superb place to begin.
Set up AWS CDK utilizing the next instructions:
Bootstrap your AWS account
First, it’s worthwhile to be sure the atmosphere the place you’re planning to deploy the answer to has been bootstrapped. You solely want to do that one time per atmosphere the place you wish to deploy AWS CDK purposes. For those who’re not sure whether or not your atmosphere has been bootstrapped already, you may all the time run the command once more:
Outline your AWS CDK atmosphere variables
On Linux or MacOS, outline your atmosphere variables with the next code:
On Home windows, use the next code:
Deploy the stack
By default, the stack deploys a primary Amazon MWAA atmosphere with the related pipelines described beforehand. It creates a brand new VPC with a view to host the Amazon MWAA sources.
The stack could be custom-made utilizing the parameters listed within the following desk.
To cross a parameter to the assemble, you need to use the AWS CDK runtime context. For those who intend to customise your atmosphere with a number of parameters, we advocate utilizing the cdk.json context file with model management to keep away from sudden adjustments to your deployments. All through our instance, we cross just one parameter to the assemble. Due to this fact, for the simplicity of the tutorial, we use the the --context or -c choice to the cdk command, as within the following instance:
| Parameter | Description | Default | Legitimate values |
| vpcId | VPC ID the place the cluster is deployed. If none, creates a brand new one and wishes the parameter cidr in that case. |
None | VPC ID |
| cidr | The CIDR for the VPC that’s created to host Amazon MWAA sources. Used provided that the vpcId shouldn’t be outlined. |
172.31.0.0/16 | IP CIDR |
| subnetIds | Comma-separated checklist of subnets IDs the place the cluster is deployed. If none, appears for personal subnets in the identical Availability Zone. | None | Subnet IDs checklist (coma separated) |
| envName | Amazon MWAA atmosphere identify | MwaaEnvironment |
String |
| envTags | Amazon MWAA atmosphere tags | None | See the next JSON instance: '{"Setting":"MyEnv", "Utility":"MyApp", "Cause":"Airflow"}' |
| environmentClass | Amazon MWAA atmosphere class | mw1.small | mw1.small, mw1.medium, mw1.massive |
| maxWorkers | Amazon MWAA most employees | 1 | int |
| webserverAccessMode | Amazon MWAA atmosphere entry mode (personal or public) | PUBLIC_ONLY |
PUBLIC_ONLY, PRIVATE_ONLY |
| secretsBackend | Amazon MWAA atmosphere secrets and techniques backend | Airflow | SecretsManager |
Clone the GitHub repository:
Deploy the stack utilizing the next command:
The next screenshot reveals the stack deployment:

The next screenshot reveals the deployed stack:
Create answer sources
For this walkthrough, you need to have the next conditions:
For those who don’t have a Salesforce account, you may create a SalesForce developer account:
- Join a developer account.
- Copy the host from the e-mail that you simply obtain.
- Log in into your new Salesforce account
- Select the profile icon, then Settings.
- Select Reset my Safety Token.
- Verify your electronic mail and duplicate the safety token that you simply obtain.
After you full these conditions, you’re able to create the next sources:
- An S3 bucket for Salesforce output information
- An IAM position and IAM coverage to write down the Salesforce output information on Amazon S3
- A Salesforce connection on the Airflow UI to have the ability to learn from Salesforce
- An AWS connection on the Airflow UI to have the ability to write on Amazon S3
- An Airflow variable on the Airflow UI to retailer the identify of the goal S3 bucket
Create an S3 bucket for Salesforce output information
To create an output S3 bucket, full the next steps:
- On the Amazon S3 console, select Create bucket.
The Create bucket wizard opens.
- For Bucket identify, enter a DNS-compliant identify in your bucket, resembling
airflow-blog-post. - For Area, select the Area the place you deployed your Amazon MWAA atmosphere, for instance, US East (N. Virginia) us-east-1.
- Select Create bucket.
For extra info, see Making a bucket.
Create an IAM position and IAM coverage to write down the Salesforce output information on Amazon S3
On this step, we create an IAM coverage that permits Amazon MWAA to write down in your S3 bucket.
- On the IAM console, within the navigation pane, select Insurance policies.
- Select Create coverage.
- Select the JSON tab.
- Enter the next JSON coverage doc, and exchange
airflow-blog-posttogether with your bucket identify: - Select Subsequent: Tags.
- Select Subsequent: Overview.
- For Title, select a reputation in your coverage (for instance,
airflow_data_output_policy). - Select Create coverage.
Let’s connect the IAM coverage to a brand new IAM position that we use in our Airflow connections.
- On the IAM console, select Roles within the navigation pane after which select Create position.
- Within the Or choose a service to view its use instances part, select S3.
- For Choose your use case, select S3.
- Seek for the identify of the IAM coverage that we created within the earlier step (
airflow_data_output_role) and choose the coverage. - Select Subsequent: Tags.
- Select Subsequent: Overview.
- For Position identify, select a reputation in your position (
airflow_data_output_role). - Overview the position after which select Create position.
You’re redirected to the Roles part.
- Within the search field, enter the identify of the position that you simply created and select it.
- Copy the position ARN to make use of later to create the AWS connection on Airflow.
Create a Salesforce connection on the Airflow UI to have the ability to learn from Salesforce
To learn information from Salesforce, we have to create a connection utilizing the Airflow consumer interface.
- On the Airflow UI, select Admin.
- Select Connections, after which the plus signal to create a brand new connection.
- Fill within the fields with the required info.
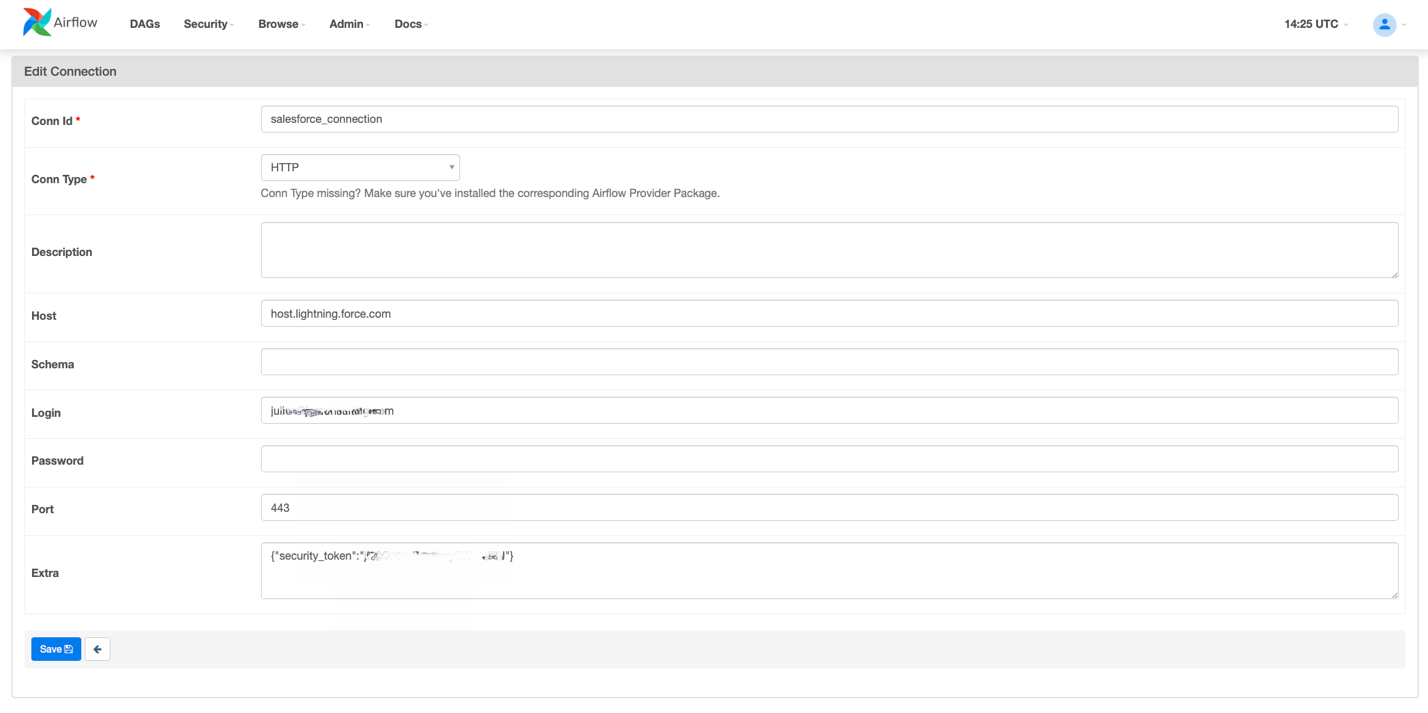
The next desk offers extra details about every worth.
| Discipline | Obligatory | Description | Values |
|---|---|---|---|
| Conn Id | Sure | Connection ID to outline and for use later within the DAG | For instance, salesforce_connection |
| Conn Sort | Sure | Connection sort | HTTP |
| Host | Sure | Salesforce host identify | host-dev-ed.my.salesforce.com or host.lightning.pressure.com. Change the host together with your Salesforce host and don’t add the http:// as prefix. |
| Login | Sure | The Salesforce consumer identify. The consumer should have learn entry to the salesforce objects. | admin@instance.com |
| Password | Sure | The corresponding password for the outlined consumer. | MyPassword123 |
| Port | No | Salesforce occasion port. By default, 443. | 443 |
| Further | Sure | Specify the additional parameters (as a JSON dictionary) that can be utilized within the Salesforce connection. security_token is the Salesforce safety token for authentication. To get the Salesforce safety token in your electronic mail, you will need to reset your safety token. |
{"security_token":"AbCdE..."} |
Create an AWS connection within the Airflow UI to have the ability to write on Amazon S3
An AWS connection is required to add information into Amazon S3, so we have to create a connection utilizing the Airflow consumer interface.
- On the Airflow UI, select Admin.
- Select Connections, after which select the plus signal to create a brand new connection.
- Fill within the fields with the required info.

The next desk offers extra details about the fields.
| Discipline | Obligatory | Description | Worth |
|---|---|---|---|
| Conn Id | Sure | Connection ID to outline and for use later within the DAG | For instance, aws_connection |
| Conn Sort | Sure | Connection sort | Amazon Internet Companies |
| Further | Sure | It’s required to specify the Area. You additionally want to supply the position ARN that we created earlier. |
Create an Airflow variable on the Airflow UI to retailer the identify of the goal S3 bucket
We create a variable to set the identify of the goal S3 bucket. This variable is utilized by the DAG. So, we have to create a variable utilizing the Airflow consumer interface.
- On the Airflow UI, select Admin.
- Select Variables, then select the plus signal to create a brand new variable.

- For Key, enter
bucket_name. - For Val, enter the identify of the S3 bucket that you simply created in a earlier step (
airflow-blog-post).
Create and deploy a DAG in Amazon MWAA
To have the ability to ingest information from Salesforce into Amazon S3, we have to create a DAG (Directed Acyclic Graph). To create and deploy the DAG, full the next steps:
- Create an area Python DAG.
- Deploy your DAG utilizing the mission CI/CD pipeline.
- Run your DAG on the Airflow UI.
- Show your information in Amazon S3 (with S3 Choose).
Create an area Python DAG
The supplied SalesForceToS3Operator permits you to ingest information from Salesforce objects to an S3 bucket. Seek advice from normal Salesforce objects for the total checklist of objects you may ingest information from with this Airflow operator.
On this use case, we ingest information from the Alternative Salesforce object. We retrieve the final 6 months’ information in month-to-month batches and we filter on a selected checklist of fields.
The DAG supplied within the pattern in GitHub repository imports the final 6 months of the Alternative object (one file by month) by filtering the checklist of retrieved fields.
This operator takes two connections as parameters:
- An AWS connection that’s used to add ingested information into Amazon S3.
- A Salesforce connection to learn information from Salesforce.
The next desk offers extra details about the parameters.
| Parameter | Sort | Obligatory | Description |
|---|---|---|---|
| sf_conn_id | string | Sure | Title of the Airflow connection that has the next info:
|
| sf_obj | string | Sure | Title of the related Salesforce object (Account, Lead, Alternative) |
| s3_conn_id | string | Sure | The vacation spot S3 connection ID |
| s3_bucket | string | Sure | The vacation spot S3 bucket |
| s3_key | string | Sure | The vacation spot S3 key |
| sf_fields | string | No | The (optionally available) checklist of fields that you simply wish to get from the article (Id, Title, and so forth).If none (the default), then this will get all fields for the article. |
| fmt | string | No | The (optionally available) format that the S3 key of the info ought to be in. Potential values embody CSV (default), JSON, and NDJSON. |
| from_date | date format | No | A particular date-time (optionally available) formatted enter to run queries from for incremental ingestion. Evaluated towards the SystemModStamp attribute.Not suitable with the question parameter and ought to be in date-time format (for instance, 2021-01-01T00:00:00Z). Default: None |
| to_date | date format | No | A particular date-time (optionally available) formatted enter to run queries to for incremental ingestion. Evaluated towards the SystemModStamp attribute.Not suitable with the question parameter and ought to be in date-time format (for instance, 2021-01-01T00:00:00Z). Default: None |
| question | string | No | A particular question (optionally available) to run for the given object. This overrides default question creation. Default: None |
| relationship_object | string | No | Some queries require relationship objects to work, and these should not the identical names because the Salesforce object. Specify that relationship object right here (optionally available). Default: None |
| record_time_added | boolean | No | Set this optionally available worth to true if you wish to add a Unix timestamp discipline to the ensuing information that marks when the info was fetched from Salesforce. Default: False |
| coerce_to_timestamp | boolean | No | Set this optionally available worth to true if you wish to convert all fields with dates and datetimes into Unix timestamp (UTC). Default: False |
Step one is to import the operator in your DAG:
Then outline your DAG default ARGs, which you need to use in your frequent activity parameters:
Lastly, you outline the duties to make use of the operator.
The next examples illustrate some use instances.
Salesforce object full ingestion
This activity ingests all of the content material of the Salesforce object outlined in sf_obj. This selects all the article’s out there fields and writes them into the outlined format in fmt. See the next code:
Salesforce object partial ingestion primarily based on fields
This activity ingests particular fields of the Salesforce object outlined in sf_obj. The chosen fields are outlined within the optionally available sf_fields parameter. See the next code:
Salesforce object partial ingestion primarily based on time interval
This activity ingests all of the fields of the Salesforce object outlined in sf_obj. The time interval could be relative utilizing from_date or to_date parameters or absolute by utilizing each parameters.
The next instance illustrates relative ingestion from the outlined date:
The from_date and to_date parameters assist Salesforce date-time format. It may be both a selected date or literal (for instance TODAY, LAST_WEEK, LAST_N_DAYS:5). For extra details about date codecs, see Date Codecs and Date Literals.
For the total DAG, discuss with the pattern in GitHub repository.
This code dynamically generates duties that run queries to retrieve the info of the Alternative object within the type of 1-month batches.
The sf_fields parameter permits us to extract solely the chosen fields from the article.
Save the DAG domestically as salesforce_to_s3.py.
Deploy your DAG utilizing the mission CI/CD pipeline
As a part of the CDK deployment, a CodeCommit repository and CodePipeline pipeline have been created with a view to repeatedly construct, take a look at, and deploy DAGs into your Amazon MWAA atmosphere.
To deploy the brand new DAG, the supply code ought to be dedicated to the CodeCommit repository. This triggers a CodePipeline run that builds, checks, and deploys your new DAG and makes it out there in your Amazon MWAA atmosphere.
- Register to the CodeCommit console in your deployment Area.
- Underneath Supply, select Repositories.
You must see a brand new repository mwaaproject.
- Push your new DAG within the
mwaaprojectrepository belowdags. You may both use the CodeCommit console or the Git command line to take action:- CodeCommit console:
- Select the mission CodeCommit repository identify
mwaaprojectand navigate belowdags. - Select Add file after which Add file and add your new DAG.
- Select the mission CodeCommit repository identify
- Git command line:
- To have the ability to clone and entry your CodeCommit mission with the Git command line, be sure Git consumer is correctly configured. Seek advice from Organising for AWS CodeCommit.
- Clone the repository with the next command after changing <area> together with your mission Area:
- Copy the DAG file below
dagsand add it with the command: - Commit your new file with a message:
- Push the native file to the CodeCommit repository:
- CodeCommit console:
The brand new commit triggers a brand new pipeline that builds, checks, and deploys the brand new DAG. You may monitor the pipeline on the CodePipeline console.
- On the CodePipeline console, select Pipeline within the navigation pane.
- On the Pipelines web page, you need to see
mwaaproject-pipeline. - Select the pipeline to show its particulars.

After checking that the pipeline run is profitable, you may confirm that the DAG is deployed to the S3 bucket and due to this fact out there on the Amazon MWAA console.
- On the Amazon S3 console, search for a bucket beginning with
mwaairflowstack-mwaaenvstackneand go belowdags.
You must see the brand new DAG.
- On the Amazon MWAA console, select DAGs.
You must have the ability to see the brand new DAG.
Run your DAG on the Airflow UI
Go to the Airflow UI and toggle on the DAG.
This triggers your DAG robotically.
Later, you may proceed manually triggering it by selecting the run icon.
Select the DAG and Graph View to see the run of your DAG.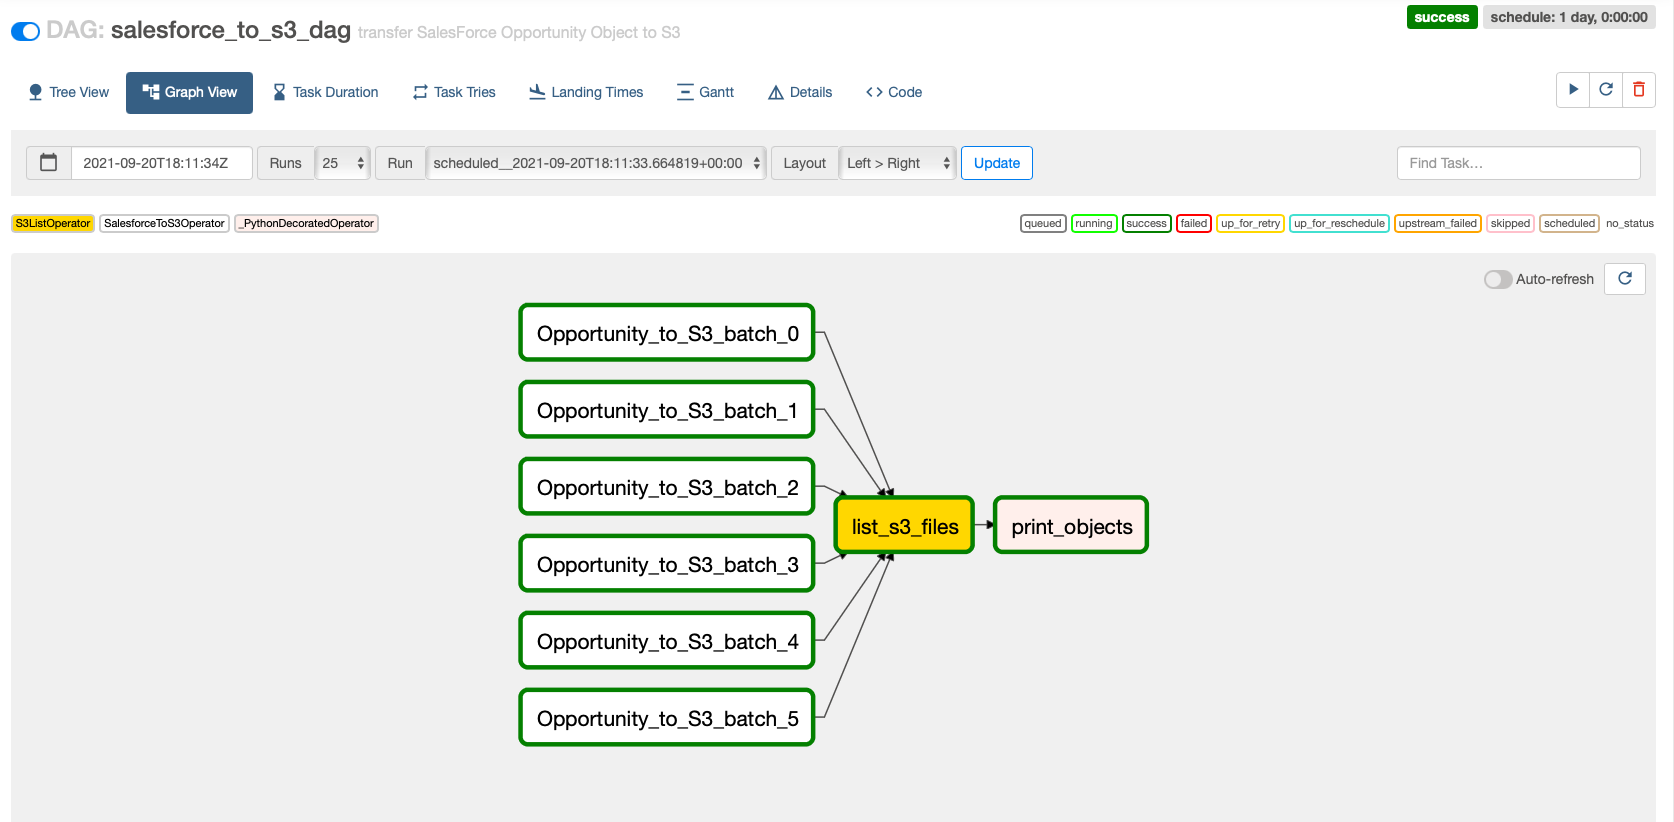
When you’ve got any difficulty, you may examine the logs of the failed duties from the duty occasion context menu.
Show your information in Amazon S3 (with S3 Choose)
To show your information, full the next steps:
- On the Amazon S3 console, within the Buckets checklist, select the identify of the bucket that comprises the output of the Salesforce information (
airflow-blog-post). - Within the Objects checklist, select the identify of the folder that has the article that you simply copied from Salesforce (
alternative). - Select the uncooked folder and the
dtfolder with the most recent timestamp. - Choose any file.
- On the Actions menu, select Question with S3 Choose.
- Select Run SQL question to preview the info.

Clear up
To keep away from incurring future expenses, delete the AWS CloudFormation stack and the sources that you simply deployed as a part of this put up.
- On the AWS CloudFormation console, delete the stack
MWAAirflowStack.
To wash up the deployed sources utilizing the AWS Command Line Interface (AWS CLI), you may merely run the next command:
Be sure to are within the root path of the mission if you run the command.
After confirming that you simply wish to destroy the CloudFormation stack, the answer’s sources are deleted out of your AWS account.
The next screenshot reveals the method of deploying the stack:
The next screenshot confirms the stack is undeployed.
- Navigate to the Amazon S3 console and find the 2 buckets containing
mwaairflowstack-mwaaenvstackandmwaairflowstack-mwaaprojthat have been created throughout the deployment. - Choose every bucket delete its contents, then delete the bucket.
- Delete the IAM position created to write down on the S3 buckets.
Conclusion
ENGIE found important worth by utilizing Amazon MWAA, enabling its world enterprise items to ingest information in additional productive methods. This put up offered how ENGIE scaled their information ingestion pipelines utilizing Amazon MWAA. The primary a part of the put up described the structure parts and the right way to efficiently deploy a CI/CD pipeline for an Amazon MWAA mission template utilizing a CodeCommit repository and plug it into CodePipeline to construct, take a look at, and package deal the code and customized plugins. The second half walked you thru the steps to automate the ingestion course of from Salesforce utilizing Airflow with an instance. For the Airflow configuration, you used Airflow variables, however it’s also possible to use Secrets and techniques Supervisor with Amazon MWAA utilizing the secretsBackend parameter when deploying the stack.
The use case mentioned on this put up is only one instance of how you need to use Amazon MWAA to make it simpler to arrange and function end-to-end information pipelines within the cloud at scale. For extra details about Amazon MWAA, try the Person Information.
In regards to the Authors
 Anouar Zaaber is a Senior Engagement Supervisor in AWS Skilled Companies. He leads inner AWS, exterior accomplice, and buyer groups to ship AWS cloud providers that allow the shoppers to understand their enterprise outcomes.
 Amine El Mallem is a Information/ML Ops Engineer in AWS Skilled Companies. He works with clients to design, automate, and construct options on AWS for his or her enterprise wants.
 Armando Segnini is a Information Architect with AWS Skilled Companies. He spends his time constructing scalable huge information and analytics options for AWS Enterprise and Strategic clients. Armando additionally likes to journey along with his household all around the globe and take photos of the locations he visits.
 Mohamed-Ali Elouaer is a DevOps Advisor with AWS Skilled Companies. He’s a part of the AWS ProServe staff, serving to enterprise clients remedy complicated issues associated to automation, safety, and monitoring utilizing AWS providers. In his free time, he likes to journey and watch films.
 Julien Grinsztajn is an Architect at ENGIE. He’s a part of the Digital & IT Consulting ENGIE IT staff engaged on the definition of the structure for complicated initiatives associated to information integration and community safety. In his free time, he likes to journey the oceans to fulfill sharks and different marine creatures.
[ad_2]

