


[ad_1]
It is a visitor authored publish by Jaison Dominic, Product Proprietor, and Kerby Johnson, Distinguished Software program Engineer, at Amgen.
Amgen, the world’s largest unbiased biotech firm, has lengthy been synonymous with innovation. For 40 years, we’ve pioneered new drug-making processes and developed life-saving medicines, positively impacting the lives of hundreds of thousands all over the world. In an effort to proceed fulfilling our mission to finest serve sufferers, we lately launched into one other journey of innovation: an entire digital transformation.
Within the technique of reimagining the right way to leverage our knowledge for higher outcomes throughout the enterprise — from enhancing R&D productiveness to optimizing provide chains and commercialization — it shortly grew to become apparent that the sorts of issues our knowledge groups have been trying to clear up had drastically modified within the final handful of years. Moreover, these issues have been not remoted by skillset, division or operate. As an alternative, probably the most impactful issues have been cross-functional in nature and required bringing collectively individuals with totally different, distinctive experience to assault issues in a novel means. In our quest to modernize, we selected the Databricks Lakehouse Platform as the inspiration for our digital transformation journey. Consequently, we have been capable of unlock the potential of our knowledge throughout numerous organizations, streamlining operational effectivity and accelerating drug discovery.
Right now, we’re sharing our success story within the hopes that others can be taught from our journey and apply it to their very own enterprise methods.
From knowledge warehouse to knowledge lake – and the issues inside
Inside three core verticals of Amgen – medical trials, manufacturing, and commercialization – lies a wealth of worthwhile knowledge. However growing volumes of knowledge offered challenges when it got here to really utilizing that knowledge effectively.
We have been unable to actually weave collectively the varied facets of our enterprise, which impacted operational effectivity as we scaled each internally and in our variety of prospects. The important thing was to not solely make it simple to entry and course of knowledge however to take action in a collaborative method that ties in several personas which have totally different viewpoints on the information — a related knowledge cloth that allows higher cross-functional collaboration. For those who’re solely taking a look at it from one or two views, you’re going to overlook worthwhile key factors from others.
For instance, take into account the query: How do you granularly forecast demand so you possibly can produce the correct amount of therapeutics for sufferers in want?
For those who’re trying on the reply from a provide chain and manufacturing perspective, you’re lacking business gross sales forecast knowledge. Alternatively, you don’t need to take the business gross sales forecast because the gospel of the quantity of manufacturing wanted as a result of what in the event that they blow their gross sales numbers out of the water, which is all the time the hope, and also you’ve underestimated what manufacturing wants to provide?
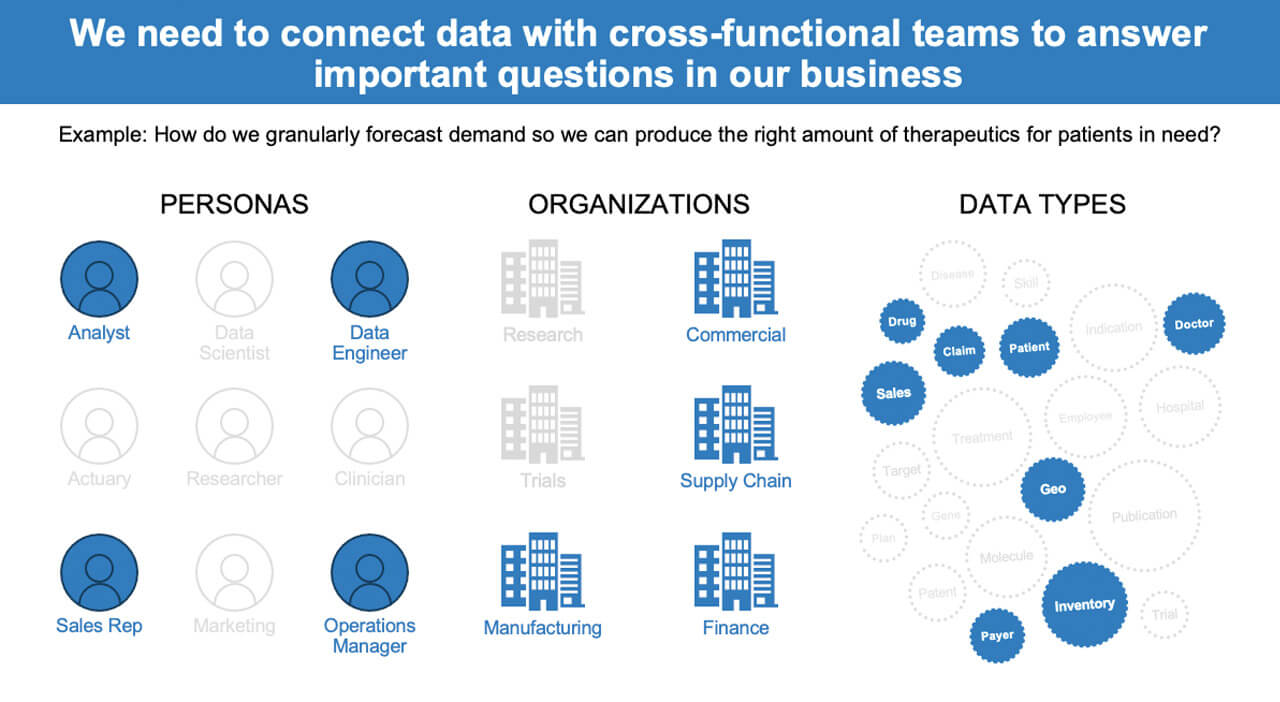
In an effort to clear up right this moment’s issues, companies must concentrate on totally different knowledge relationships and connections in order that they’ll take a look at the identical knowledge from a number of lenses — however how can they permit this? At Amgen, we’ve damaged the inspiration of recent knowledge necessities down as follows:
- Knowledge must be organized and simple to make use of.
- Sharing knowledge and re-using that of others in a pure means is a should.
- Analytics ought to be capable to function off a trusted shared view of knowledge.
- Completely different types of analytics from descriptive (BI) to predictive (ML) helps facilitate new discoveries and predictions on one model of the information.
- Knowledge wants to have the ability to evolve as new sorts are introduced in, modifications from one system to a different happen, new domains are added, and so forth. however the core of all of it ought to stay constant.
The necessity for this to be the case is probably going identified by most organizations, however seeing it come to life has been significantly troublesome for enterprises with counter-intuitive processes: every staff proudly owning, managing and organizing their knowledge in a different way, requiring yet one more mission in the event that they merely need to share it. We too struggled with not solely a number of years of accumulating extra knowledge than we knew what to do with, but additionally with the shortage of course of and infrastructure to make sure everybody was capable of work off the identical knowledge.
To attempt to handle our early knowledge wants, we transitioned from a legacy know-how infrastructure over to a Hadoop-based knowledge lake a number of years again. With a Hadoop knowledge lake, we have been capable of hold structured and unstructured knowledge in a single place, however vital knowledge challenges remained, each on the technical aspect and when it got here to processes, value and group. The shared clusters brought on “Noisy Neighbor” downside and have been troublesome and dear to scale.
For my function, as a product proprietor of the platform, managing a single shared cluster was a nightmare. It was all the time on, there was by no means a superb time to improve variations, and we had distributed prices which meant, for instance, determining the right way to cost one group for top storage and low compute and one other group for top compute and low storage.
This strategy additionally required stitching collectively quite a lot of totally different instruments as a way to meet the wants of every particular person group, which created vital collaboration challenges. And like so many others, we had quite a lot of ways in which end-users have been consuming knowledge: Jupyter Notebooks, R Studio, Spotfire and Tableau, which solely added to the complexity and problem of creating knowledge available to people who want it.
How the lakehouse structure solves our issues
Adopting the Databricks Lakehouse Platform has enabled quite a lot of groups and personas to do extra with our knowledge. With this unifying and collaborative platform, we’ve been capable of make the most of a single surroundings for all sorts of customers and their most popular instruments, protecting operations backed by a constant set of knowledge.

We’re leveraging Delta Lake to allow ACID compliance, historic lookback, and decrease the barrier to entry for builders to start coding by offering a typical knowledge layer for knowledge analysts and knowledge scientists alike to make use of knowledge to optimize provide chains and enhance operations. We’re additionally leveraging AWS Glue to attach totally different Databricks environments collectively so it’s one knowledge lake – whether or not the information is saved in a single AWS account or 10 totally different accounts. It’s all related.
This has enabled us to offer adequate flexibility for quite a lot of wants whereas standardizing on Apache Spark™ for knowledge and analytics. The unified knowledge layer inside the lakehouse permits Amgen to reliably course of knowledge of any kind and measurement, whereas offering the appliance groups with the flexibleness to maneuver the enterprise ahead.
What measurement clusters would you like? How a lot do you need to spend? Is it extra necessary to get your experiences an hour quicker, or to chop prices? Selections like these can now be made by particular person groups. Collectively, this standardization of instruments and languages, and a single supply of fact for knowledge scientists, analysts, and engineers, is what began enabling related groups.
Our present knowledge structure makes use of an Amazon S3 as the only supply of fact for all knowledge, Delta Lake because the frequent knowledge layer, the Glue knowledge catalog because the centralized metastore for Databricks, an ELK stack for monitoring with Kibana, Airflow for orchestration, and consumption, whether or not it’s analysts or knowledge scientists, all working off the Databricks Lakehouse Platform.
This frequent knowledge structure, and integrating these architectural patterns has enabled us to shift our focus from platform upkeep to essentially digging into what the enterprise really needs and what our customers care about. The important thing has been our capacity to leverage the lakehouse strategy to unify our knowledge throughout our numerous knowledge groups whereas aligning with our enterprise targets.
With knowledge on the prepared, numerous knowledge groups from engineering to knowledge science to analysts can entry and collaborate on knowledge. Databricks’ collaborative notebooks help their programming language of alternative to simply discover and begin leveraging the information for downstream analytics and ML. As we begin to use Databricks SQL, our analysts can discover and discover the newest and freshest knowledge with out having to maneuver it into an information warehouse. They’ll run queries with out sacrificing efficiency, and simply visualize outcomes with their instruments of alternative — both by way of built-in visualizations and dashboards or Tableau, which is primarily utilized by enterprise companions all through the corporate.
Our knowledge scientists additionally profit from utilizing Databricks Machine Studying to simplify all facets of ML. And since Databricks ML is constructed on the lakehouse basis with Delta Lake and MLflow, our knowledge scientists can put together and course of knowledge, streamline cross-team collaboration and standardize the complete lifecycle from experimentation to manufacturing with out relying on knowledge engineering help. This improved strategy to managing ML has had a direct impression on reducing the time it takes to enroll in medical trials.
Enhancing affected person outcomes with related knowledge and groups
The implementation of the Databricks Lakehouse Platform has in the end helped us proceed to attain our targets of serving sufferers and enhancing the drug improvement lifecycle in a contemporary world. Our knowledge ingestion charges have elevated considerably, enhancing processing instances by 75% leading to 2x quicker supply of insights to the enterprise, all whereas decreasing compute prices by ~25% over static Hadoop clusters.
With Databricks, we will take a contemporary strategy to ship on a myriad of use instances by specializing in the information, the relationships, and the connections somewhat than simply the know-how. Since partnering with Databricks in 2017, we’ve seen huge progress adoption throughout the corporate. Thus far, 2,000+ knowledge customers from knowledge engineering to analysts have accessed 400TB of knowledge by way of Databricks to help 40+ knowledge lake tasks and 240 knowledge science tasks.

What this appears like in follow is simple to make use of, simple to seek out knowledge that allows a variety of use instances throughout the corporate:
- Genomic exploration and analysis at scale: Harnessing the ability of genomic knowledge has allowed us to speed up the drug discovery course of this might considerably enhance our probabilities to seek out new medication to treatment grievous sicknesses.
- Optimized medical trial designs: Now we will usher in quite a lot of knowledge from bought knowledge to real-world proof, and leverage insights from this large number of medical knowledge to enhance the probability of success and probably save tens of hundreds of thousands of {dollars}.
- Provide chain and stock optimization: Manufacturing effectivity and stock administration is a problem for each manufacturing trade, and drug manufacturing isn’t any exception. Environment friendly manufacturing and optimized provide chain administration may help save hundreds of thousands of {dollars} to the enterprise, and assist get the appropriate medication to the appropriate sufferers on the proper time.

As Amgen’s success demonstrates, novel options to age-old issues require a refresh of a enterprise’s platforms, instruments, and strategies of innovation. And as adoption continues to rise at Amgen, we’ll discover new methods to make the most of the lakehouse strategy to foster collaboration and transparency with instruments like Delta Sharing. One other intriguing device that might present worth is Delta Reside Tables, which might assist us simplify ETL improvement and administration much more, in addition to profit our downstream knowledge shoppers. Finally, Databricks has helped us to maneuver the beginning line for superior analytics, so we will spend extra time-solving issues that may profit the sufferers who want remedies, and fewer time rebuilding the foundational infrastructure that allows it.
Subsequent Steps
[ad_2]

