


[ad_1]
Intro
As options architects, we work carefully with clients every single day to assist them get the perfect efficiency out of their jobs on Databricks –and we regularly find yourself giving the identical recommendation. It’s not unusual to have a dialog with a buyer and get double, triple, or much more efficiency with only a few tweaks. So what’s the key? How are we doing this? Listed below are the highest 5 issues we see that may make a big impact on the efficiency clients get from Databricks.
Right here’s a TLDR:
- Use bigger clusters. It could sound apparent, however that is the primary downside we see. It’s truly not any dearer to make use of a big cluster for a workload than it’s to make use of a smaller one. It’s simply quicker. If there’s something you need to take away from this text, it’s this. Learn part 1. Actually.
- Use Photon, Databricks’ new, super-fast execution engine. Learn part 2 to be taught extra. You received’t remorse it.
- Clear out your configurations. Configurations carried from one Apache Spark™ model to the following could cause large issues. Clear up! Learn part 3 to be taught extra.
- Use Delta Caching. There’s a great probability you’re not utilizing caching appropriately, if in any respect. See Part 4 to be taught extra.
- Concentrate on lazy analysis. If this doesn’t imply something to you and also you’re writing Spark code, leap to part 5.
- Bonus tip! Desk design is tremendous necessary. We’ll go into this in a future weblog, however for now, try the information on Delta Lake greatest practices.
1. Give your clusters horsepower!
That is the primary mistake clients make. Many shoppers create tiny clusters of two employees with 4 cores every, and it takes endlessly to do something. The priority is at all times the identical: they don’t wish to spend an excessive amount of cash on bigger clusters. Right here’s the factor: it’s truly not any dearer to make use of a big cluster for a workload than it’s to make use of a smaller one. It’s simply quicker.
The bottom line is that you just’re renting the cluster for the size of the workload. So, in the event you spin up that two employee cluster and it takes an hour, you’re paying for these employees for the total hour. Nonetheless, in the event you spin up a 4 employee cluster and it takes solely half an hour, the fee is definitely the identical! And that pattern continues so long as there’s sufficient work for the cluster to do.
Right here’s a hypothetical state of affairs illustrating the purpose:
| Variety of Staff | Value Per Hour | Size of Workload (hours) | Value of Workload |
|---|---|---|---|
| 1 | $1 | 2 | $2 |
| 2 | $2 | 1 | $2 |
| 4 | $4 | 0.5 | $2 |
| 8 | $8 | 0.25 | $2 |
Discover that the full price of the workload stays the identical whereas the real-world time it takes for the job to run drops considerably. So, bump up your Databricks cluster specs and velocity up your workloads with out spending any extra money. It could actually’t actually get any less complicated than that.
2. Use Photon
Our colleagues in engineering have rewritten the Spark execution engine in C++ and dubbed it Photon. The outcomes are spectacular!
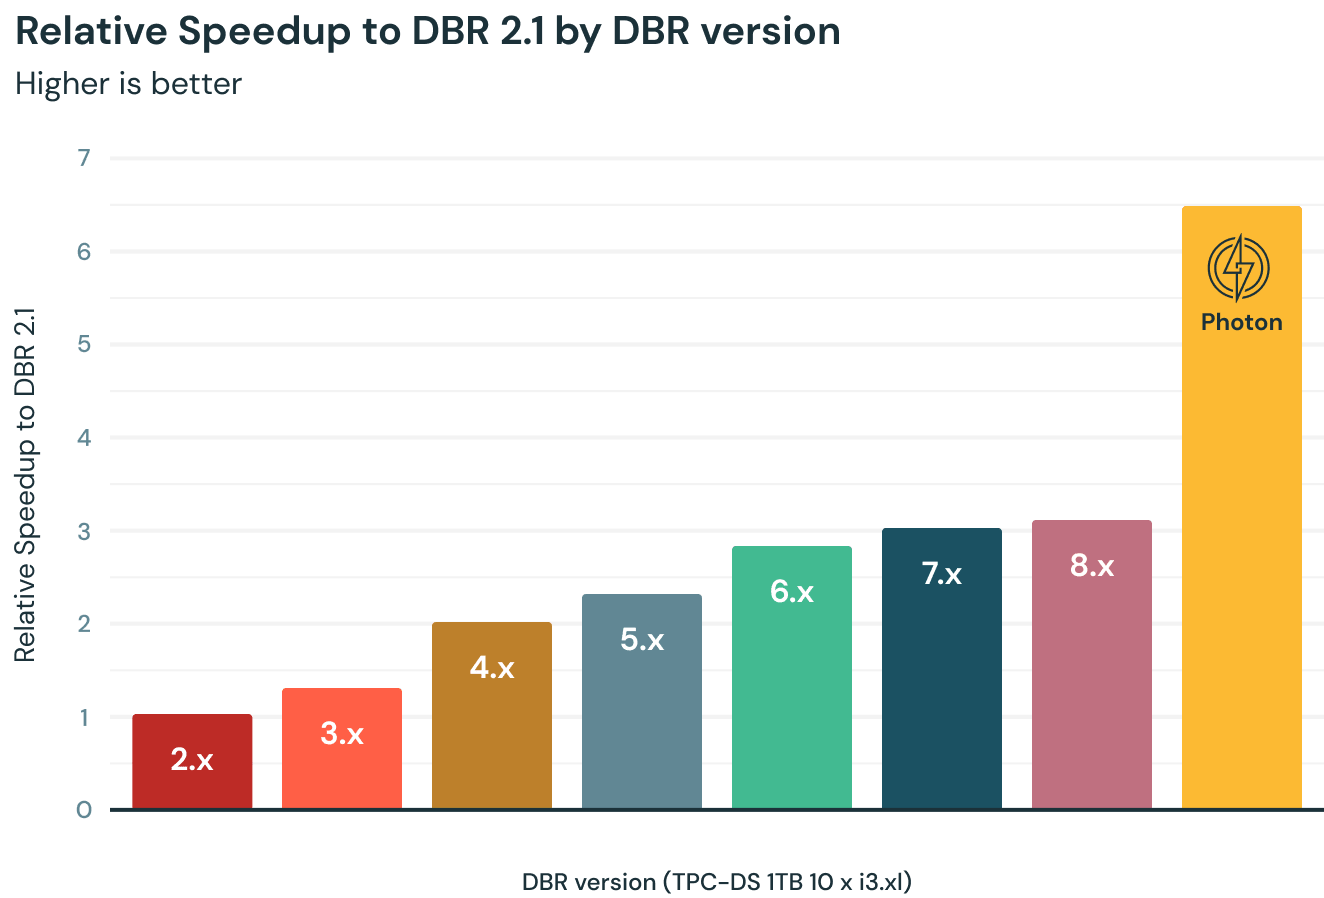
Past the apparent enhancements resulting from operating the engine in native code, they’ve additionally made use of CPU-level efficiency options and higher reminiscence administration. On high of this, they’ve rewritten the Parquet author in C++. So this makes writing to Parquet and Delta (based mostly on Parquet) tremendous quick as nicely!
However let’s even be clear about what Photon is rushing up. It improves computation velocity for any built-in features or operations, in addition to writes to Parquet or Delta. So joins? Yep! Aggregations? Positive! ETL? Completely! That UDF (user-defined perform) you wrote? Sorry, nevertheless it received’t assist there. The job that’s spending most of its time studying from an historical on-prem database? Gained’t assist there both, sadly.
The excellent news is that it helps the place it may possibly. So even when a part of your job can’t be sped up, it should velocity up the opposite elements. Additionally, most jobs are written with the native operations and spend loads of time writing to Delta, and Photon helps so much there. So give it a strive. You could be amazed by the outcomes!
3. Clear out outdated configurations
You recognize these Spark configurations you’ve been carrying alongside from model to model and nobody is aware of what they do anymore? They will not be innocent. We’ve seen jobs go from operating for hours all the way down to minutes just by cleansing out outdated configurations. There might have been a quirk in a specific model of Spark, a efficiency tweak that has not aged nicely, or one thing pulled off some weblog someplace that by no means actually made sense. On the very least, it’s price revisiting your Spark configurations in the event you’re on this scenario. Usually the default configurations are the perfect, they usually’re solely getting higher. Your configurations could also be holding you again.
4. The Delta Cache is your good friend
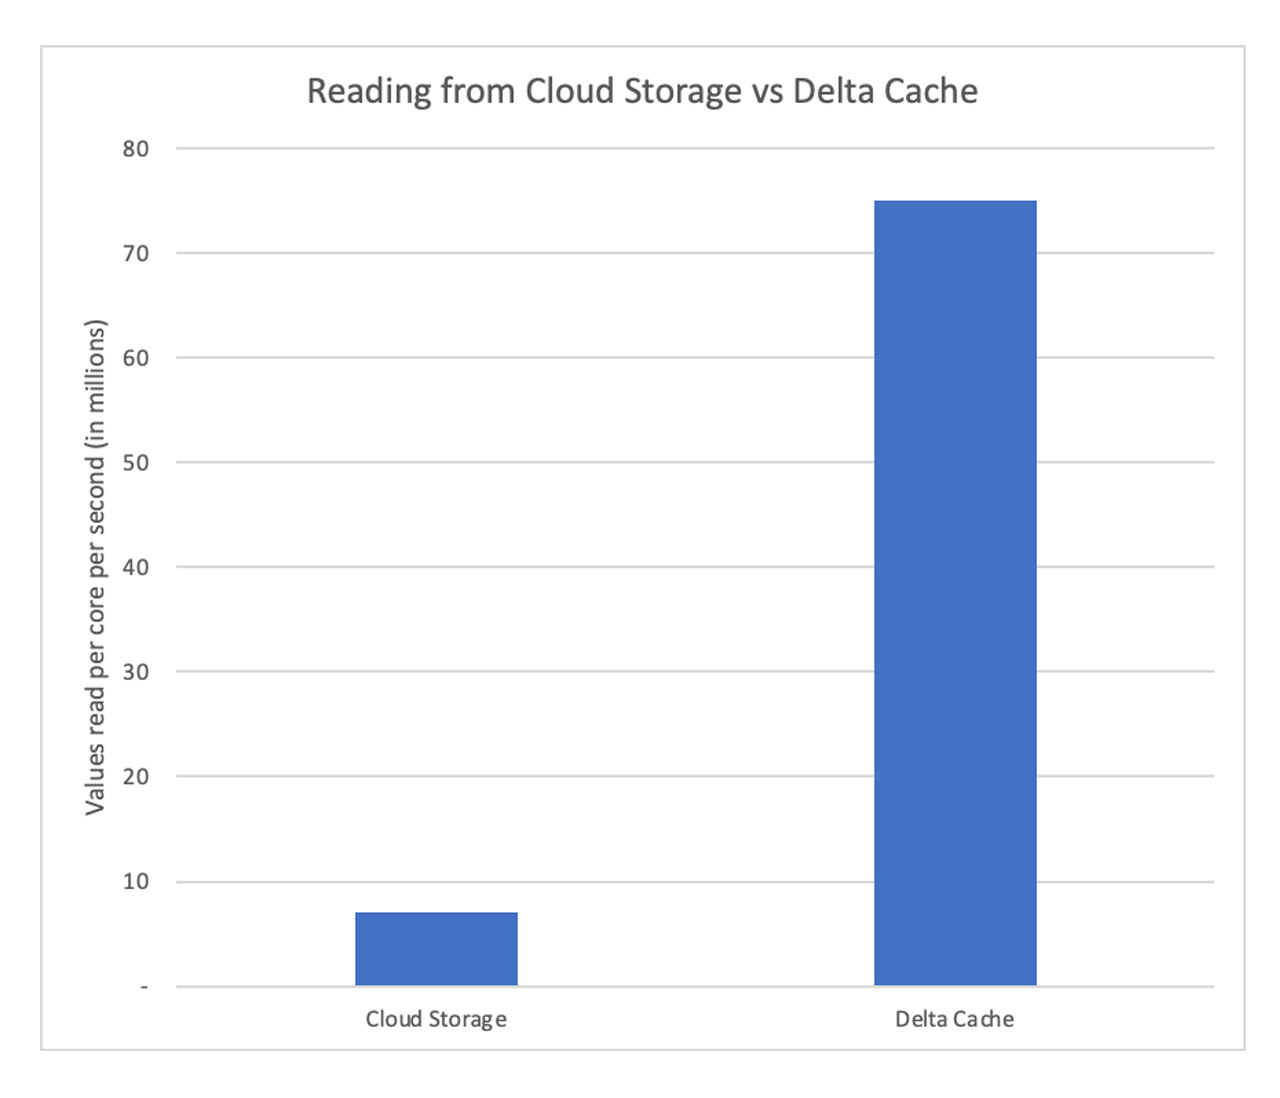
This may occasionally appear apparent, however you’d be shocked how many individuals should not utilizing the Delta Cache, which hundreds knowledge off of cloud storage (S3, ADLS) and retains it on the employees’ SSDs for quicker entry.
In case you’re utilizing Databricks SQL Endpoints you’re in luck. These have caching on by default. Actually, we advocate utilizing CACHE SELECT * FROM desk to preload your “sizzling” tables once you’re beginning an endpoint. This may guarantee blazing quick speeds for any queries on these tables.
In case you’re utilizing common clusters, be sure you use the i3 sequence on Amazon Internet Providers (AWS), L sequence or E sequence on Azure Databricks, or n2 in GCP. These will all have quick SSDs and caching enabled by default.
After all, your mileage might range. In case you’re doing BI, which includes studying the identical tables again and again, caching provides a tremendous enhance. Nonetheless, in the event you’re merely studying a desk as soon as and writing out the outcomes as in some ETL jobs, it’s possible you’ll not get a lot profit. You recognize your jobs higher than anybody. Go forth and conquer.
5. Concentrate on lazy analysis
In case you’re a knowledge analyst or knowledge scientist solely utilizing SQL or doing BI you’ll be able to skip this part. Nonetheless, in the event you’re in knowledge engineering and writing pipelines or doing processing utilizing Databricks / Spark, learn on.
Once you’re writing Spark code like choose, groupBy, filter, and many others, you’re actually constructing an execution plan. You’ll discover the code returns virtually instantly once you run these features. That’s as a result of it’s not truly doing any computation. So even in case you have petabytes of knowledge it should return in lower than a second.
Nonetheless, when you go to jot down your outcomes out you’ll discover it takes longer. This is because of lazy analysis. It’s not till you attempt to show or write outcomes that your execution plan is definitely run.
—-------- # Construct an execution plan. # This returns in lower than a second however does no work df2 = (df .be part of(...) .choose(...) .filter(...) ) # Now run the execution plan to get outcomes df2.show() —------Nonetheless, there’s a catch right here. Each time you attempt to show or write out outcomes it runs the execution plan once more. Let’s have a look at the identical block of code however prolong it and do a couple of extra operations.
—-------- # Construct an execution plan. # This returns in lower than a second however does no work df2 = (df .be part of(...) .choose(...) .filter(...) ) # Now run the execution plan to get outcomes df2.show() # Sadly this can run the plan once more, together with filtering, becoming a member of, and many others df2.show() # So will this… df2.rely() —------The developer of this code might very nicely be considering that they’re simply printing out outcomes thrice, however what they’re actually doing is kicking off the identical processing thrice. Oops. That’s loads of further work. This can be a quite common mistake we run into. So why is there lazy analysis, and what will we do about it?
In brief, processing with lazy analysis is approach quicker than with out it. Databricks / Spark seems on the full execution plan and finds alternatives for optimization that may scale back processing time by orders of magnitude. In order that’s nice, however how will we keep away from the additional computation? The reply is fairly easy: save computed outcomes you’ll reuse.
Let’s have a look at the identical block of code once more, however this time let’s keep away from the recomputation:
# Construct an execution plan. # This returns in lower than a second however does no work df2 = (df .be part of(...) .choose(...) .filter(...) ) # put it aside df2.write.save(path) # load it again in df3 = spark.learn.load(path) # now use it df3.show() # this isn't doing any further computation anymore. No joins, filtering, and many others. It’s already finished and saved. df3.show() # neither is this df3.rely()This works particularly nicely when Delta Caching is turned on. In brief, you profit tremendously from lazy analysis, nevertheless it’s one thing loads of clients journey over. So concentrate on its existence and save outcomes you reuse in an effort to keep away from pointless computation.
Subsequent weblog: Design your tables nicely!
That is an extremely necessary matter, nevertheless it wants its personal weblog. Keep tuned. Within the meantime, try this information on Delta Lake greatest practices.
[ad_2]

