



[ad_1]
Extract, rework, and cargo (ETL) serverless orchestration structure functions have gotten standard with many purchasers. These functions presents higher extensibility and ease, making it simpler to take care of and simplify ETL pipelines. A main good thing about this structure is that we simplify an present ETL pipeline with AWS Step Capabilities and instantly name the Amazon Redshift Knowledge API from the state machine. In consequence, the complexity for the ETL pipeline is decreased.
As a knowledge engineer or an software developer, it’s possible you’ll wish to work together with Amazon Redshift to load or question knowledge with a easy API endpoint with out having to handle persistent connections. The Amazon Redshift Knowledge API lets you work together with Amazon Redshift with out having to configure JDBC or ODBC connections. This function lets you orchestrate serverless knowledge processing workflows, design event-driven internet functions, and run an ETL pipeline asynchronously to ingest and course of knowledge in Amazon Redshift, with using Step Capabilities to orchestrate your entire ETL or ELT workflow.
This publish explains the best way to use Step Capabilities and the Amazon Redshift Knowledge API to orchestrate the completely different steps in your ETL or ELT workflow and course of knowledge into an Amazon Redshift knowledge warehouse.
AWS Lambda is usually used with Step Capabilities as a consequence of its versatile and scalable compute advantages. An ETL workflow has a number of steps, and the complexity could fluctuate inside every step. Nevertheless, there’s another method with AWS SDK service integrations, a function of Step Capabilities. These integrations mean you can name over 200 AWS companies’ API actions instantly out of your state machine. This method is perfect for steps with comparatively low complexity in comparison with utilizing Lambda since you not have to take care of and check operate code. Lambda capabilities have a most timeout of quarter-hour; if you’ll want to look ahead to longer-running processes, Step Capabilities normal workflows permits a most runtime of 1 yr.
You’ll be able to change steps that embody a single course of with a direct integration between Step Capabilities and AWS SDK service integrations with out utilizing Lambda. For instance, if a step is barely used to name a Lambda operate that runs a SQL assertion in Amazon Redshift, it’s possible you’ll take away the Lambda operate with a direct integration to the Amazon Redshift Knowledge API’s SDK API motion. You may as well decouple Lambda capabilities with a number of actions into a number of steps. An implementation of that is out there later on this publish.
We created an instance use case within the GitHub repo ETL Orchestration utilizing Amazon Redshift Knowledge API and AWS Step Capabilities that gives an AWS CloudFormation template for setup, SQL scripts, and a state machine definition. The state machine instantly reads SQL scripts saved in your Amazon Easy Storage Service (Amazon S3) bucket, runs them in your Amazon Redshift cluster, and performs an ETL workflow. We don’t use Lambda on this use case.
Answer overview
On this situation, we simplify an present ETL pipeline that makes use of Lambda to name the Knowledge API. AWS SDK service integrations with Step Capabilities mean you can instantly name the Knowledge API from the state machine, lowering the complexity in working the ETL pipeline.
Your complete workflow performs the next steps:
- Arrange the required database objects and generate a set of pattern knowledge to be processed.
- Run two dimension jobs that carry out SCD1 and SCD2 dimension load, respectively.
- When each jobs have run efficiently, the load job for the actual fact desk runs.
- The state machine performs a validation to make sure the gross sales knowledge was loaded efficiently.

The next structure diagram highlights the end-to-end answer: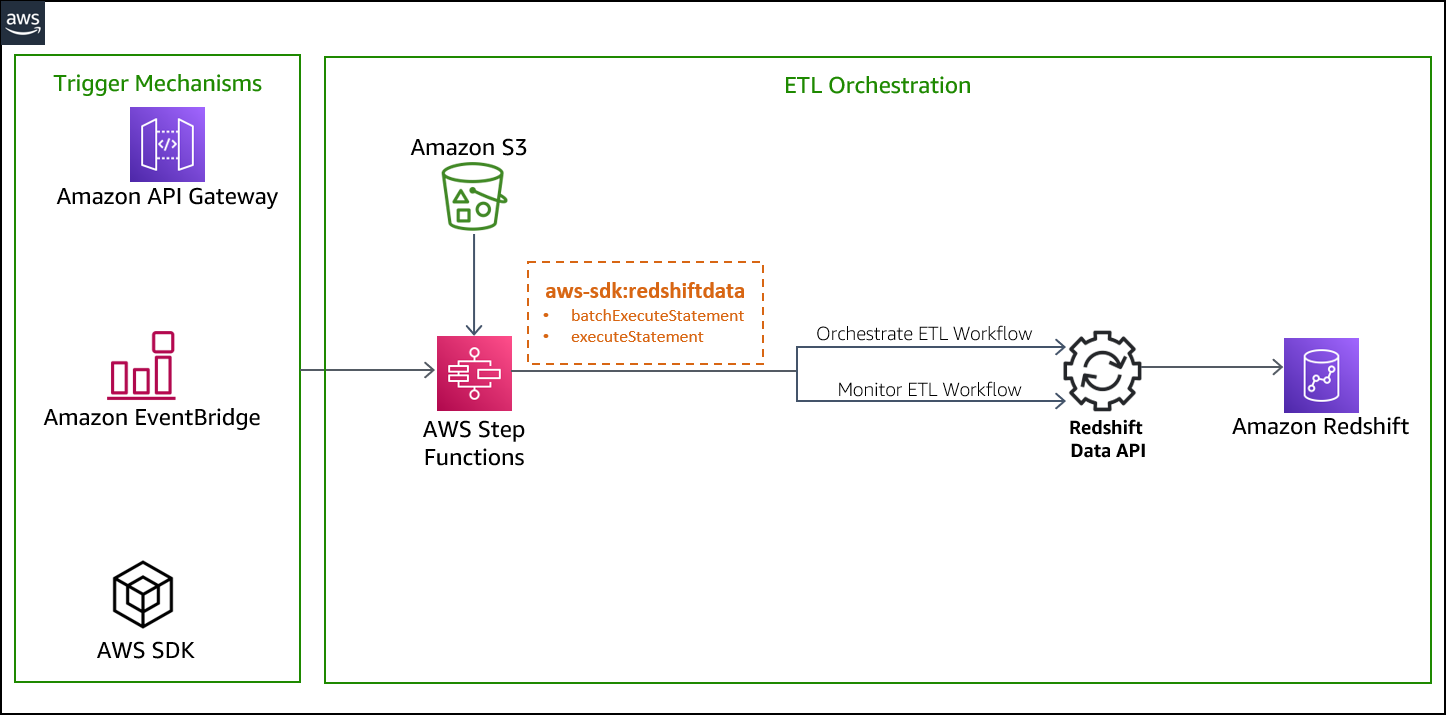
We run the state machine through the Step Capabilities console, however you’ll be able to run this answer in a number of methods:
You’ll be able to deploy the answer with the offered CloudFormation template, which creates the next sources:
- Database objects within the Amazon Redshift cluster:
- 4 saved procedures:
- sp_setup_sales_data_pipeline() – Creates the tables and populates them with pattern knowledge
- sp_load_dim_customer_address() – Runs the SCD1 course of on
customer_addressdata - sp_load_dim_item() – Runs the SCD2 course of on
merchandisedata - sp_load_fact_sales (p_run_date date) – Processes gross sales from all shops for a given day
- 5 Amazon Redshift tables:
buyercustomer_addressdate_dimmerchandisestore_sales
- 4 saved procedures:
- The AWS Id and Entry Administration (IAM) function
StateMachineExecutionRolefor Step Capabilities to permit the next permissions:- Federate to the Amazon Redshift cluster by
getClusterCredentialspermission avoiding password credentials - Run queries within the Amazon Redshift cluster by Knowledge API calls
- Listing and retrieve objects from Amazon S3
- Federate to the Amazon Redshift cluster by
- The Step Capabilities state machine
RedshiftETLStepFunction, which comprises the steps used to run the ETL workflow of the pattern gross sales knowledge pipeline
Stipulations
As a prerequisite for deploying the answer, you’ll want to arrange an Amazon Redshift cluster and affiliate it with an IAM function. For extra data, see Authorizing Amazon Redshift to entry different AWS companies in your behalf. Should you don’t have a cluster provisioned in your AWS account, confer with Getting began with Amazon Redshift for directions to set it up.
When the Amazon Redshift cluster is on the market, carry out the next steps:
- Obtain and save the CloudFormation template to an area folder in your pc.
- Obtain and save the next SQL scripts to an area folder in your pc:
- sp_statements.sql – Incorporates the saved procedures together with DDL and DML operations.
- validate_sql_statement.sql – Incorporates two validation queries you’ll be able to run.
- Add the SQL scripts to your S3 bucket. The bucket identify is the designated S3 bucket specified within the
ETLScriptS3Pathenter parameter. - On the AWS CloudFormation console, select Create stack with new sources and add the template file you downloaded within the earlier step (
etl-orchestration-with-stepfunctions-and-redshift-data-api.yaml). - Enter the required parameters and select Subsequent.

- Select Subsequent till you get to the Assessment web page and choose the acknowledgement test field.
- Select Create stack.

- Wait till the stack deploys efficiently.
When the stack is full, you’ll be able to view the outputs, as proven within the following screenshot:
Run the ETL orchestration
After you deploy the CloudFormation template, navigate to the stack element web page. On the Assets tab, select the hyperlink for RedshiftETLStepFunction to be redirected to the Step Capabilities console.
The RedshiftETLStepFunction state machine runs routinely, as outlined within the following workflow:
- read_sp_statement and run_sp_deploy_redshift – Performs the next actions:
- Retrieves the
sp_statements.sqlfrom Amazon S3 to get the saved process. - Passes the saved process to the
batch-execute-statementAPI to run within the Amazon Redshift cluster. - Sends again the identifier of the SQL assertion to the state machine.
- Retrieves the
- wait_on_sp_deploy_redshift – Waits for at the least 5 seconds.
- run_sp_deploy_redshift_status_check – Invokes the Knowledge API’s
describeStatementto get the standing of the API name. - is_run_sp_deploy_complete – Routes the subsequent step of the ETL workflow relying on its standing:
- FINISHED – Saved procedures are created in your Amazon Redshift cluster.
- FAILED – Go to the
sales_data_pipeline_failurestep and fail the ETL workflow. - All different standing – Return to the
wait_on_sp_deploy_redshiftstep to attend for the SQL statements to complete.
- setup_sales_data_pipeline – Performs the next steps:
- Initiates the
setupsaved process that was beforehand created within the Amazon Redshift cluster. - Sends again the identifier of the SQL assertion to the state machine.
- Initiates the
- wait_on_setup_sales_data_pipeline – Waits for at the least 5 seconds.
- setup_sales_data_pipeline_status_check – Invokes the Knowledge API’s
describeStatementto get the standing of the API name. - is_setup_sales_data_pipeline_complete – Routes the subsequent step of the ETL workflow relying on its standing:
- FINISHED – Created two dimension tables (
customer_addressandmerchandise) and one truth desk (gross sales). - FAILED – Go to the
sales_data_pipeline_failurestep and fail the ETL workflow. - All different standing – Return to the
wait_on_setup_sales_data_pipelinestep to attend for the SQL statements to complete.
- FINISHED – Created two dimension tables (
- run_sales_data_pipeline –
LoadItemTableandLoadCustomerAddressTableare two parallel workflows that Step Capabilities runs on the identical time. The workflows run the saved procedures that had been beforehand created. The saved process hundreds the info into themerchandiseandcustomer_addresstables. All different steps within the parallel classes observe the identical idea as described beforehand. When each parallel workflows are full,run_load_fact_salesruns. - run_load_fact_sales – Inserts knowledge into the
store_salesdesk that was created within the preliminary saved process. - Validation – When all of the ETL steps are full, the state machine reads a second SQL file from Amazon S3 (
validate_sql_statement.sql) and runs the 2 SQL statements utilizing thebatch_execute_statementtechnique.
The implementation of the ETL workflow is idempotent. If it fails, you’ll be able to retry the job with none cleanup. For instance, it recreates the stg_store_sales desk every time, then deletes the goal desk store_sales with the info for the actual refresh date every time.
The next diagram illustrates the state machine workflow: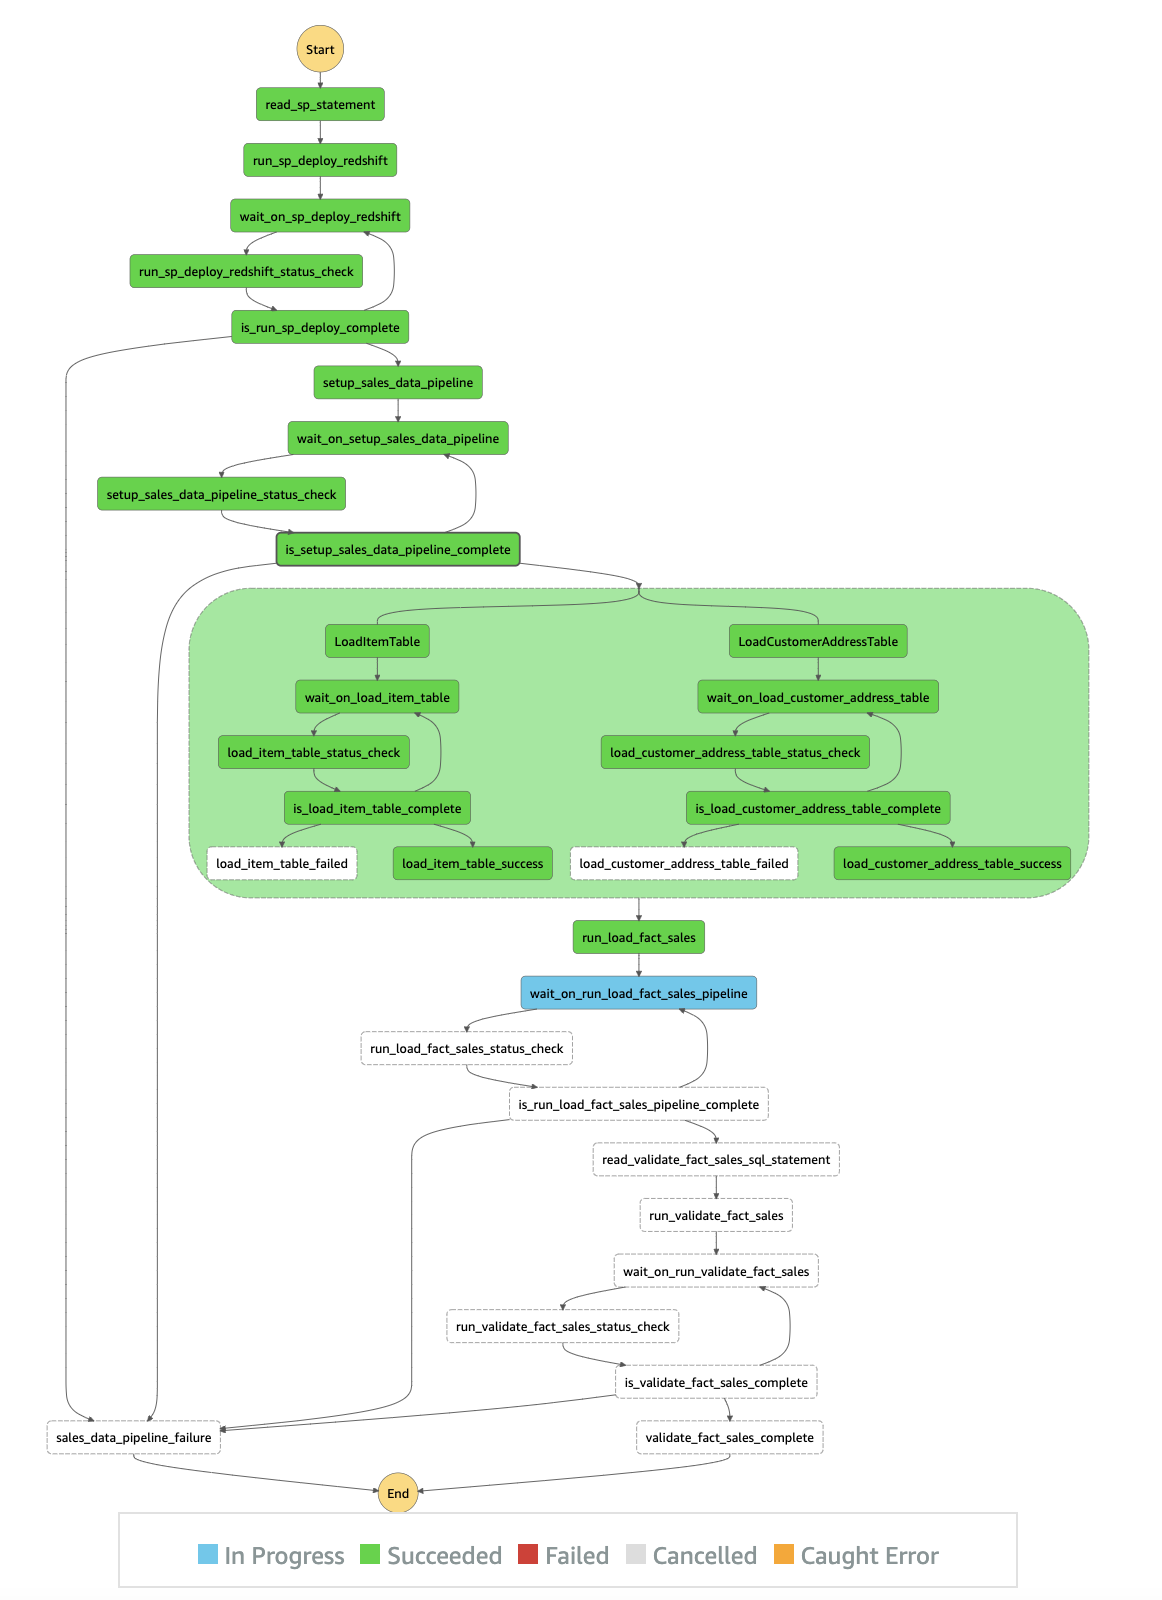
On this instance, we use the duty state useful resource arn:aws:states:::aws-sdk:redshiftdata:[apiAction] to name the corresponding Knowledge API motion. The next desk summarizes the Knowledge API actions and their corresponding AWS SDK integration API actions.
To make use of AWS SDK integrations, you specify the service identify and API name, and, optionally, a service integration sample. The AWS SDK motion is all the time camel case, and parameter names are Pascal case. For instance, you need to use the Step Capabilities motion batchExecuteStatement to run a number of SQL statements in a batch as part of a single transaction on the Knowledge API. The SQL statements may be SELECT, DML, DDL, COPY, and UNLOAD.
Validate the ETL orchestration
Your complete ETL workflow takes roughly 1 minute to run. The next screenshot reveals that the ETL workflow accomplished efficiently.
When your entire gross sales knowledge pipeline is full, it’s possible you’ll undergo your entire execution occasion historical past, as proven within the following screenshot.
Schedule the ETL orchestration
After you validate the gross sales knowledge pipeline, it’s possible you’ll decide to run the info pipeline on a day by day schedule. You’ll be able to accomplish this with Amazon EventBridge.
- On the EventBridge console, create a rule to run the
RedshiftETLStepFunctionstate machine day by day.
- To invoke the
RedshiftETLStepFunctionstate machine on a schedule, select Schedule and outline the suitable frequency wanted to run the gross sales knowledge pipeline.
- Specify the goal state machine as
RedshiftETLStepFunctionand select Create.
You’ll be able to affirm the schedule on the rule particulars web page.
Clear up
Clear up the sources created by the CloudFormation template to keep away from pointless value to your AWS account. You’ll be able to delete the CloudFormation stack by choosing the stack on the AWS CloudFormation console and selecting Delete. This motion deletes all of the sources it provisioned. Should you manually up to date a template-provisioned useful resource, you may even see some points throughout cleanup; you’ll want to clear these up independently.
Limitations
The Knowledge API and Step Capabilities AWS SDK integration presents a sturdy mechanism to construct extremely distributed ETL functions inside minimal developer overhead. Contemplate the next limitations when utilizing the Knowledge API and Step Capabilities:
Conclusion
On this publish, we demonstrated the best way to construct an ETL orchestration utilizing the Amazon Redshift Knowledge API and Step Capabilities with AWS SDK integration.
To study extra concerning the Knowledge API, see Utilizing the Amazon Redshift Knowledge API to work together with Amazon Redshift clusters and Utilizing the Amazon Redshift Knowledge API.
Concerning the Authors
 Jason Pedreza is an Analytics Specialist Options Architect at AWS with over 13 years of knowledge warehousing expertise. Previous to AWS, he constructed knowledge warehouse options at Amazon.com. He makes a speciality of Amazon Redshift and helps clients construct scalable analytic options.
 Bipin Pandey is a Knowledge Architect at AWS. He likes to construct knowledge lake and analytics platforms for his clients. He’s enthusiastic about automating and simplifying buyer issues with using cloud options.
 David Zhang is an AWS Options Architect who helps clients design sturdy, scalable, and data-driven options throughout a number of industries. With a background in software program growth, David is an lively chief and contributor to AWS open-source initiatives. He’s enthusiastic about fixing real-world enterprise issues and constantly strives to work from the client’s perspective. Be at liberty to attach with him on LinkedIn.
[ad_2]

