



[ad_1]
Streaming ETL jobs in AWS Glue can devour knowledge from streaming sources similar to Amazon Kinesis and Apache Kafka, clear and rework these knowledge streams in-flight, in addition to repeatedly load the outcomes into Amazon Easy Storage Service (Amazon S3) knowledge lakes, knowledge warehouses, or different knowledge shops.
The always-on nature of streaming jobs poses a singular problem when dealing with fast-changing reference knowledge that’s used to counterpoint knowledge streams throughout the AWS Glue streaming ETL job. AWS Glue processes real-time knowledge from Amazon Kinesis Knowledge Streams utilizing micro-batches. The foreachbatch methodology used to course of micro-batches handles one knowledge stream.
This put up proposes an answer to counterpoint streaming knowledge with regularly altering reference knowledge in an AWS Glue streaming ETL job.
You possibly can enrich knowledge streams with altering reference knowledge within the following methods:
- Learn the reference dataset with each micro-batch, which may trigger redundant reads and a rise in learn requests. This method is pricey, inefficient, and isn’t lined on this put up.
- Design a technique to inform the AWS Glue streaming job that the reference knowledge has modified and refresh it solely when wanted. This method is cost-effective and extremely obtainable. We suggest utilizing this method.
Resolution overview
This put up makes use of DynamoDB Streams to seize adjustments to reference knowledge, as illustrated within the following structure diagram. For extra details about DynamoDB Streams, see DynamoDB Streams Use Circumstances and Design Patterns.

The workflow incorporates the next steps:
- A person or software updates or creates a brand new merchandise within the DynamoDB desk.
- DynamoDB Streams is used to establish adjustments within the reference knowledge.
- A Lambda perform is invoked each time a change happens within the reference knowledge.
- The Lambda perform captures the occasion containing the modified report, creates a “change file” and locations it in an Amazon S3 bucket.
- The AWS Glue job is designed to observe the stream for this worth in each micro-batch. The second that it sees the change flag, AWS Glue initiates a refresh of the DynamoDB knowledge earlier than processing any additional information within the stream.
This put up is accompanied by an AWS CloudFormation template that creates assets as described within the answer structure:
- A DynamoDB desk named
ProductPrioritywith a couple of gadgets loaded - An S3 bucket named
demo-bucket-<AWS AccountID> - Two Lambda features:
demo-glue-script-creator-lambdademo-reference-data-change-handler
- A Kinesis knowledge stream named
SourceKinesisStream - An AWS Glue Knowledge Catalog database referred to as
my-database - Two Knowledge Catalog tables
- An AWS Glue job referred to as
demo-glue-job-<AWS AccountID>. The code for the AWS Glue job might be discovered at this hyperlink. - Two AWS Identification and Entry Administration (IAM) roles:
- A job for the Lambda features to entry Kinesis, Amazon S3, and DynamoDB Streams
- A job for the AWS Glue job to entry Kinesis, Amazon S3, and DynamoDB
- An Amazon Kinesis Knowledge Generator (KDG) account with a person created by Amazon Cognito to generate a pattern knowledge stream
Conditions
For this walkthrough, it is best to have the next conditions:
- An AWS account
- The IAM person ought to have permissions to create the required roles
- Permission to create a CloudFormation stack and the companies we detailed
Create assets with AWS CloudFormation
To deploy the answer, full the next steps:
- Select Launch Stack:
- Arrange an Amazon Cognito person pool and check if you happen to can entry the KDG URL specified within the stack’s output tab. Moreover, validate if you happen to can log in to KDG utilizing the credentials supplied whereas creating the stack.
It’s best to now have the required assets obtainable in your AWS account.
- Confirm this listing with the assets within the output part of the CloudFormation stack.
Pattern knowledge
Pattern reference knowledge has already been loaded into the reference knowledge retailer. The next screenshot exhibits an instance.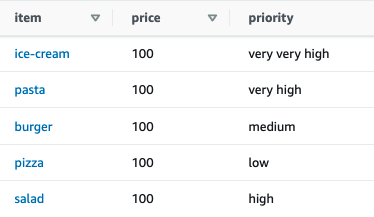
The precedence worth could change regularly based mostly on the time of the day, the day of the week, or different components that drive demand and provide.
The target is to accommodate these adjustments to the reference knowledge seamlessly into the pipeline.
Generate a randomized stream of occasions into Kinesis
Subsequent, we simulate a pattern stream of knowledge into Kinesis. For detailed directions, see Take a look at Your Streaming Knowledge Resolution with the New Amazon Kinesis Knowledge Generator. For this put up, we outline the construction of the simulated orders knowledge utilizing a parameterized template.
- On the KDG console, select the Area the place the supply Kinesis stream is situated.
- Select your supply stream.
- Enter the next template into the Report template discipline:
- Select Take a look at template, then select Ship knowledge.

KDG ought to begin sending a stream of randomly generated orders to the Kinesis knowledge stream.
Run the AWS Glue streaming job
The CloudFormation stack created an AWS Glue job that reads from the Kinesis knowledge stream by a Knowledge Catalog desk, joins with the reference knowledge in DynamoDB, and writes the end result to an S3 bucket. To run the job, full the next steps:
- On the AWS Glue console, below ETL within the navigation pane, select Jobs.
- Choose the job
demo-glue-job-<AWS AccountID>. - On the Actions menu, select Run job.
Along with the enrichment, the job contains an extra test that displays an Amazon S3 prefix for a “Change Flag” file. This file is created by the Lambda perform, which is invoked by the DynamoDB stream at any time when there may be an replace or a brand new reference merchandise.
Examine the goal knowledge in Amazon S3
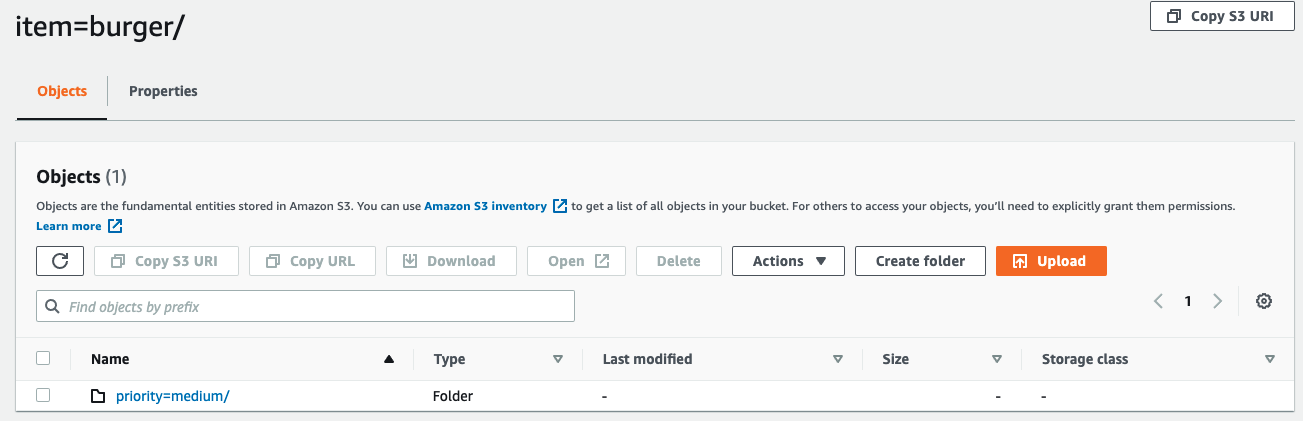
The next is a screenshot of the info being loaded in actual time into the merchandise=burger partition. The precedence was set to medium within the reference knowledge, and the orders go into the corresponding partition.
Replace the reference knowledge
Now we replace the precedence for burgers to excessive within the DynamoDB desk by the console whereas the orders are streaming into the pipeline.
Use the next command to carry out the replace by Amazon CloudShell. Change the Area to the suitable worth.
Confirm that the info acquired up to date.
Navigate to the goal S3 folder to substantiate the contents. The AWS Glue job ought to have began sending the orders for burgers into the excessive partition.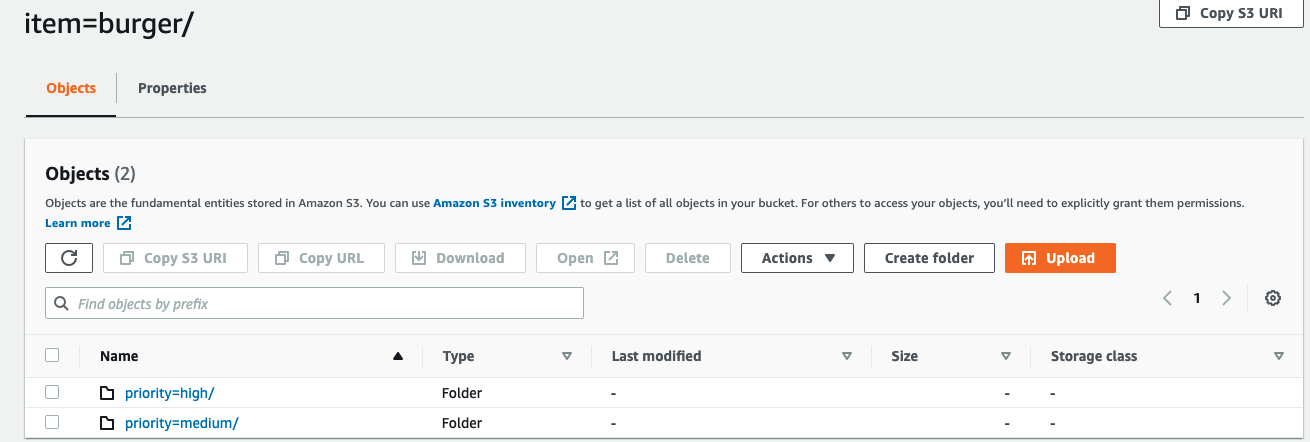
The Lambda perform is invoked by the DynamoDB stream and locations a “Change Flag” file in an Amazon S3 bucket. The AWS Glue job refreshes the reference knowledge and deletes the file to keep away from redundant refreshes.
Utilizing this sample for reference knowledge in Amazon S3
If the reference knowledge is saved in an S3 bucket, create an Amazon S3 occasion notification that identifies adjustments to the prefix the place the reference knowledge is saved. The occasion notification invokes a Lambda perform that inserts the change flag into the info stream.
Cleansing up
To keep away from incurring future prices, delete the assets. You are able to do this by deleting the CloudFormation stack.
Conclusion
On this put up, we mentioned approaches to deal with fast-changing reference knowledge saved in DynamoDB or Amazon S3. We demonstrated a easy use case that implements this sample.
Word that DynamoDB Streams writes stream information in near-real time. When designing your answer, account for a minor delay between the precise replace in DynamoDB and the write into the DynamoDB stream.
In regards to the Authors
 Jerome Rajan is a Lead Knowledge Analytics Guide at AWS. He helps prospects design & construct scalable analytics options and migrate knowledge pipelines and knowledge warehouses into the cloud. In an alternate universe, he’s a World Chess Champion!
 Dipankar Ghosal is a Principal Architect at Amazon Net Providers and relies out of Minneapolis, MN. He has a spotlight in analytics and enjoys serving to prospects resolve their distinctive use circumstances. When he’s not working, he loves going mountain climbing together with his spouse and daughter.
[ad_2]

