


[ad_1]
Knowledge lineage is without doubt one of the most important parts of an information governance technique for knowledge lakes. Knowledge lineage helps make sure that correct, full and reliable knowledge is getting used to drive enterprise selections. Whereas an information catalog gives metadata administration options and search capabilities, knowledge lineage exhibits the complete context of your knowledge by capturing in higher element the true relationships between knowledge sources, the place the information originated from and the way it will get remodeled and converged. Completely different personas within the knowledge lake profit from knowledge lineage:
- For knowledge scientists, the power to view and observe knowledge move because it strikes from supply to vacation spot helps you simply perceive the standard and origin of a specific metric or dataset
- Knowledge platform engineers can get extra insights into the information pipelines and the interdependencies between datasets
- Modifications in knowledge pipelines are simpler to use and validate as a result of engineers can determine a job’s upstream dependencies and downstream utilization to correctly consider service impacts
Because the complexity of information panorama grows, prospects are going through important manageability challenges in capturing lineage in an economical and constant method. On this submit, we stroll you thru three steps in constructing an end-to-end automated knowledge lineage resolution for knowledge lakes: lineage capturing, modeling and storage and eventually visualization.
On this resolution, we seize each coarse-grained and fine-grained knowledge lineage. Coarse-grained knowledge lineage, which regularly targets enterprise customers, focuses on capturing the high-level enterprise processes and general knowledge workflows. Sometimes, it captures and visualizes the relationships between datasets and the way they’re propagated throughout storage tiers, together with extract, remodel and cargo (ETL) jobs and operational data. Tremendous-grained knowledge lineage offers entry to column-level lineage and the information transformation steps within the processing and analytical pipelines.
Answer overview
Apache Spark is without doubt one of the hottest engines for large-scale knowledge processing in knowledge lakes. Our resolution makes use of the Spline agent to seize runtime lineage data from Spark jobs, powered by AWS Glue. We use Amazon Neptune, a purpose-built graph database optimized for storing and querying extremely related datasets, to mannequin lineage knowledge for evaluation and visualization.
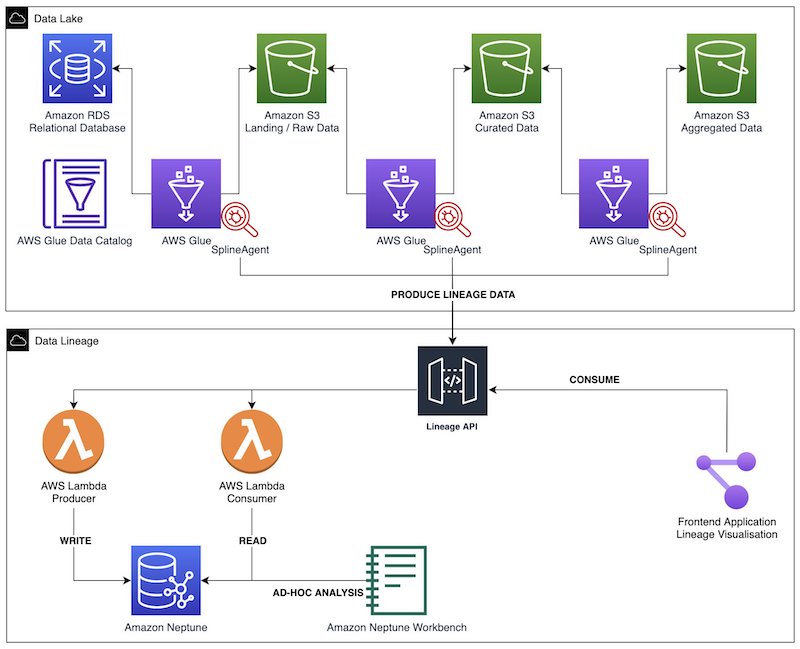
The next diagram illustrates the answer structure. We use AWS Glue Spark ETL jobs to carry out knowledge ingestion, transformation, and cargo. The Spline agent is configured in every AWS Glue job to seize lineage and run metrics, and sends such knowledge to a lineage REST API. This backend consists of producer and shopper endpoints, powered by Amazon API Gateway and AWS Lambda features. The producer endpoints course of the incoming lineage objects earlier than storing them within the Neptune database. We use shopper endpoints to extract particular lineage graphs for various visualizations within the frontend utility. We carry out advert hoc interactive evaluation on the graph by Neptune notebooks.
We offer pattern code and Terraform deployment scripts on GitHub to rapidly deploy this resolution to the AWS Cloud.
Knowledge lineage capturing
The Spline agent is an open-source mission that may harvest knowledge lineage mechanically from Spark jobs at runtime, with out the necessity to modify the present ETL code. It listens to Spark’s question run occasions, extracts lineage objects from the job run plans and sends them to a preconfigured backend (akin to HTTP endpoints). The agent additionally mechanically collects job run metrics such because the variety of output rows. As of this writing, the Spline agent works solely with Spark SQL (DataSet/DataFrame APIs) and never with RDDs/DynamicFrames.
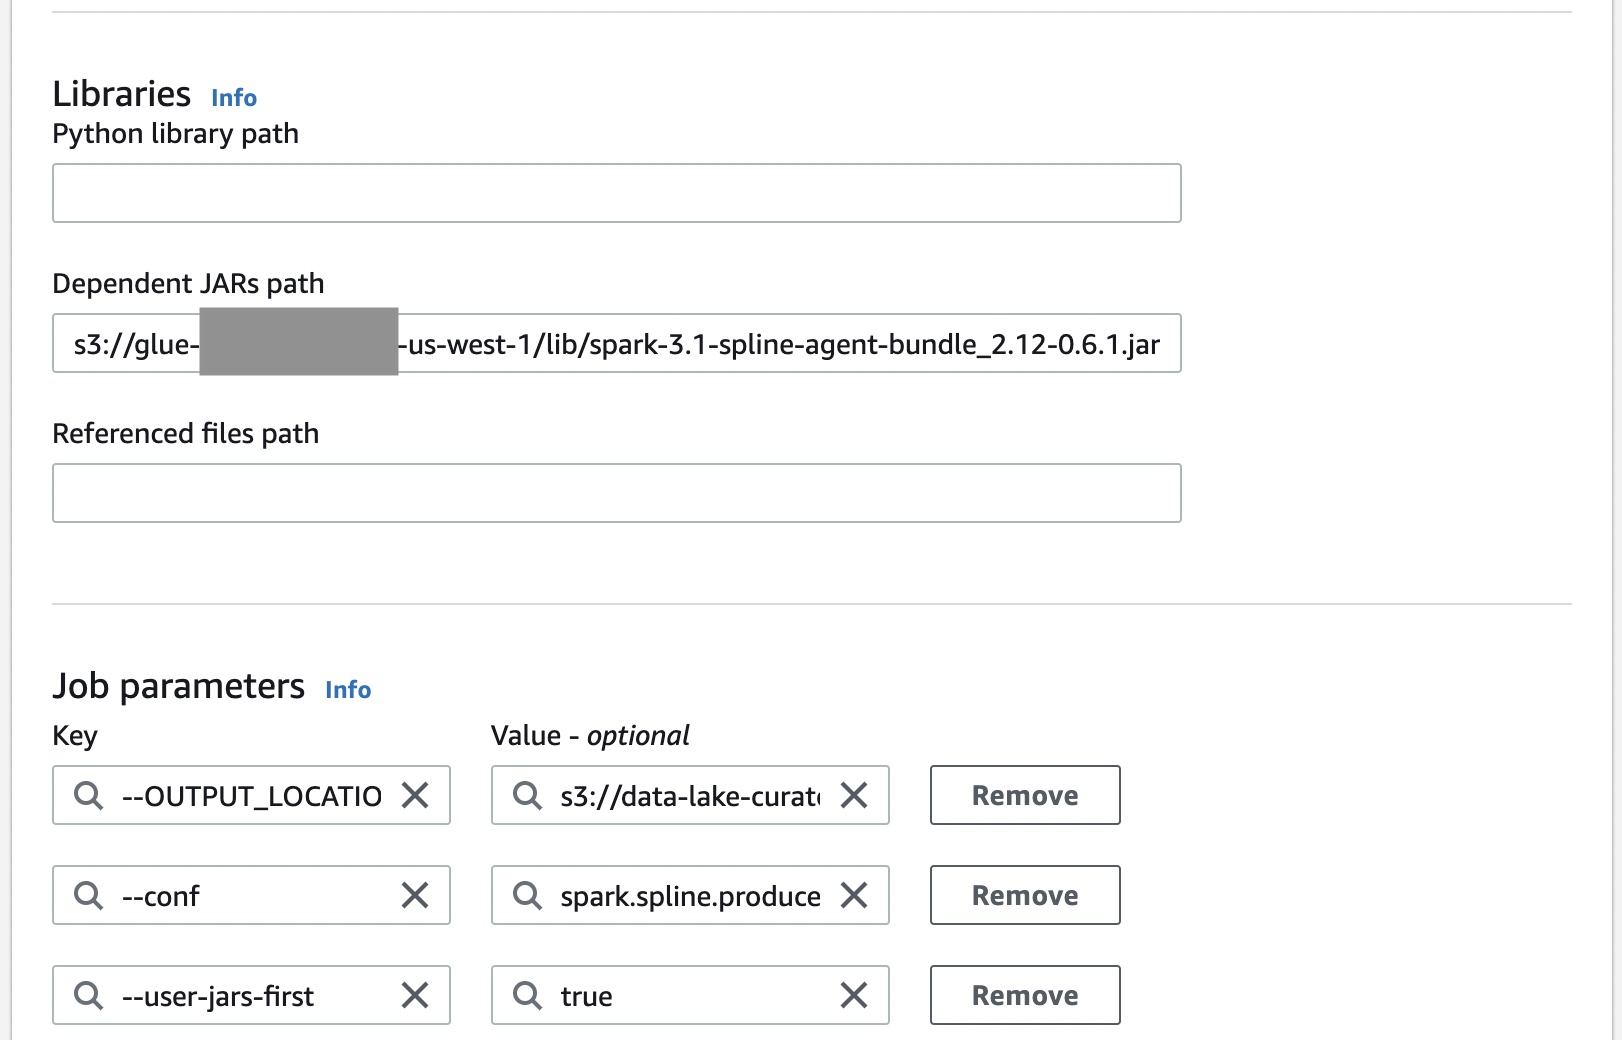
The next screenshot exhibits the best way to combine the Spline agent with AWS Glue Spark jobs. The Spline agent is an uber JAR that must be added to the Java classpath. The next configurations are required to arrange the Spline agent:
spark.sql.queryExecutionListenersconfiguration is used to register a Spline listener throughout its initialization.spark.spline.producer.urlspecifies the deal with of the HTTP server that the Spline agent ought to ship lineage knowledge to.
We construct an information lineage API that’s suitable with the Spline agent. This API facilitates the insertion of lineage knowledge to Neptune database and graph extraction for visualization. The Spline agent requires three HTTP endpoints:
- /standing – For well being checks
- /execution-plans – For sending the captured Spark execution plans after the roles are submitted to run
- /execution-events – For sending the job’s run metrics when the job is full
We additionally create extra endpoints to handle numerous metadata of the information lake, such because the names of the storage layers and dataset classification.
When a Spark SQL assertion is run or a DataFrame motion known as, Spark’s optimization engine, specifically Catalyst, generates totally different question plans: a logical plan, optimized logical plan and bodily plan, which will be inspected utilizing the EXPLAIN assertion. In a job run, the Spline agent parses the analyzed logical plan to assemble a JSON lineage object. The thing consists of the next:
- A novel job run ID
- A reference schema (attribute names and knowledge sorts)
- An inventory of operations
- Different system metadata akin to Spark model and Spline agent model
A run plan specifies the steps the Spark job performs, from studying knowledge sources, making use of totally different transformations, to lastly persisting the job’s output right into a storage location.
To sum up, the Spline agent captures not solely the metadata of the job (akin to job identify and run date and time), the enter and output tables (akin to knowledge format, bodily location and schema) but in addition detailed details about the enterprise logic (SQL-like operations that the job performs, akin to be a part of, filter, mission and mixture).
Knowledge modeling and storage
Knowledge modeling begins with the enterprise necessities and use instances and maps these wants right into a construction for storing and organizing our knowledge. In knowledge lineage for knowledge lakes, the relationships between knowledge belongings (jobs, tables and columns) are as necessary because the metadata of these. Because of this, graph databases are appropriate to mannequin such extremely related entities, making it environment friendly to know the complicated and deep community of relationships throughout the knowledge.
Neptune is a quick, dependable, absolutely managed graph database service that makes it straightforward to construct and run purposes with extremely related datasets. You should utilize Neptune to create subtle, interactive graph purposes that may question billions of relationships in milliseconds. Neptune helps three standard graph question languages: Apache TinkerPop Gremlin and openCypher for property graphs and SPARQL for W3C’s RDF knowledge mannequin. On this resolution, we use the property graph’s primitives (together with vertices, edges, labels and properties) to mannequin the objects and use the gremlinpython library to work together with the graphs.
The target of our knowledge mannequin is to offer an abstraction for knowledge belongings and their relationships throughout the knowledge lake. Within the producer Lambda features, we first parse the JSON lineage objects to kind logical entities akin to jobs, tables and operations earlier than developing the ultimate graph in Neptune.
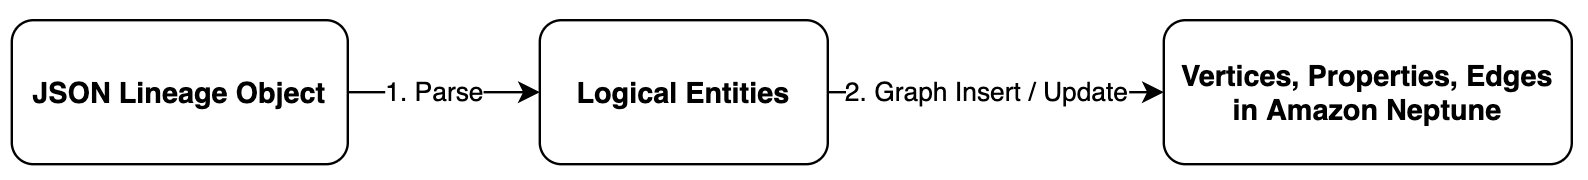
The next diagram exhibits a pattern knowledge mannequin used on this resolution.

This knowledge mannequin permits us to simply traverse the graph to extract coarse-grained and fine-grained knowledge lineage, as talked about earlier.
Knowledge lineage visualization
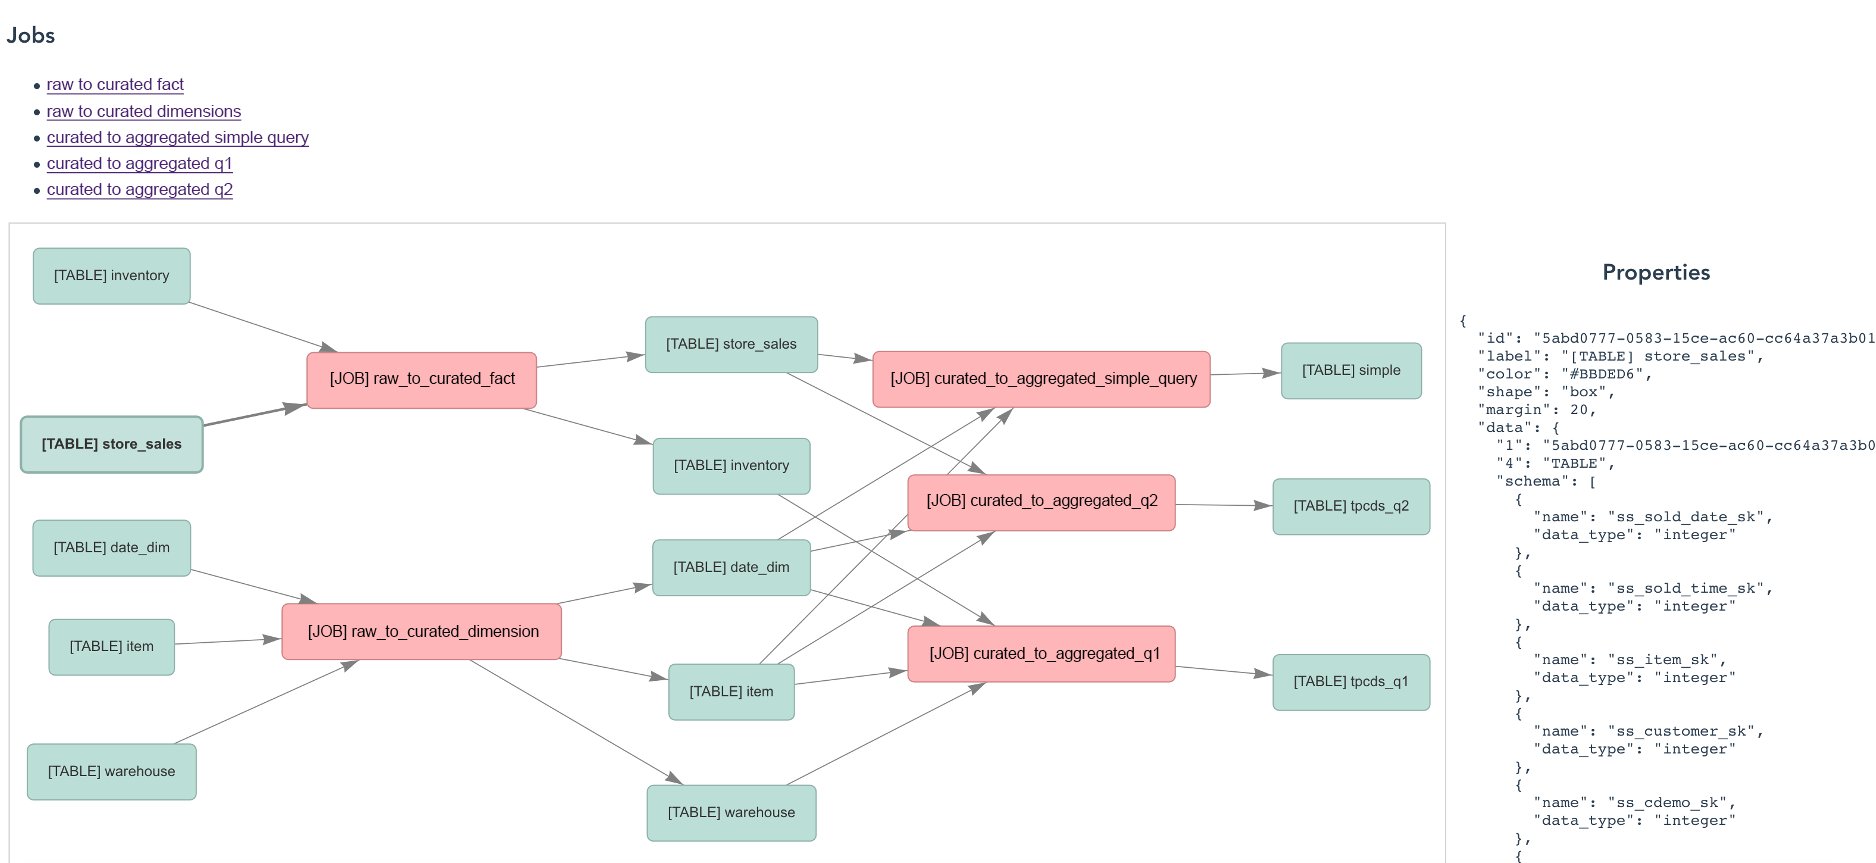
You’ll be able to extract particular views of the lineage graph from Neptune utilizing the buyer endpoints backed by Lambda features. Hierarchical views of lineage at totally different ranges make it straightforward for the end-user to research the knowledge.
The next screenshot exhibits an information lineage view throughout all jobs and tables.
The next screenshot exhibits a view of a particular job plan.

The next screenshot exhibits an in depth look into the operations taken by the job.
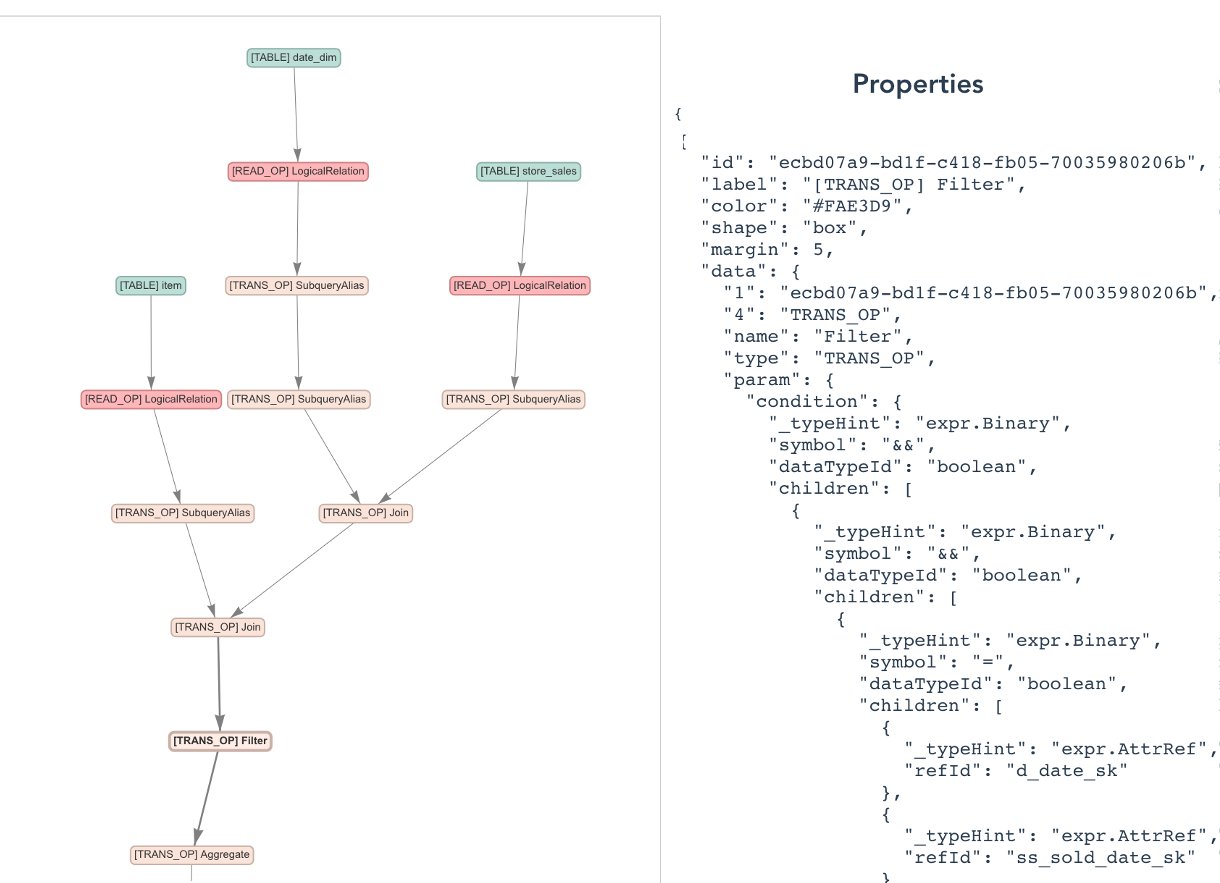
The graphs are visualized utilizing the vis.js community open-source mission. You’ll be able to work together with the graph parts to study extra concerning the entity’s properties, akin to knowledge schema.
Conclusion
On this submit, we confirmed you architectural design choices to mechanically accumulate end-to-end knowledge lineage for AWS Glue Spark ETL jobs throughout an information lake in a multi-account AWS setting utilizing Neptune and the Spline agent. This strategy allows searchable metadata, helps to attract insights and obtain an improved organization-wide knowledge lineage posture. The proposed resolution makes use of AWS managed and serverless providers, that are scalable and configurable for top availability and efficiency.
For extra details about this resolution, see Github. You could modify the code to increase the information mannequin and APIs.
Concerning the Authors
 Khoa Nguyen is a Senior Large Knowledge Architect at Amazon Internet Companies. He works with massive enterprise prospects and AWS companions to speed up prospects’ enterprise outcomes by offering experience in Large Knowledge and AWS providers.
 Krithivasan Balasubramaniyan is a Principal Advisor at Amazon Internet Companies. He allows world enterprise prospects of their digital transformation journey and helps architect cloud native options.
 Rahul Shaurya is a Senior Large Knowledge Architect at Amazon Internet Companies. He helps and works intently with prospects constructing knowledge platforms and analytical purposes on AWS.
[ad_2]

