



[ad_1]
Organizations sometimes accumulate large volumes of knowledge and proceed to generate ever-exceeding information volumes, starting from terabytes to petabytes and at instances to exabytes of knowledge. Such information is often generated in disparate techniques and requires an aggregation right into a single location for evaluation and perception technology. A knowledge lake structure means that you can combination information current in numerous silos, retailer it in a centralized repository, implement information governance, and assist analytics and machine studying (ML) on high of this saved information.
Typical constructing blocks to implement such an structure embody a centralized repository constructed on Amazon Easy Storage Service (Amazon S3) offering the least doable unit value of storage per GB, large information ETL (extract, rework, and cargo) frameworks similar to AWS Glue, and analytics utilizing Amazon Athena, Amazon Redshift, and Amazon EMR notebooks.
Constructing such techniques includes technical challenges. For instance, information residing in S3 buckets can’t be up to date in-place utilizing customary information ingestion approaches. Due to this fact, you should carry out fixed ad-hoc ETL jobs to consolidate information into new S3 recordsdata and buckets.
That is particularly the case with streaming sources, which require fixed assist for growing information velocity to offer quicker insights technology. An instance use case may be an ecommerce firm seeking to construct a real-time date lake. They want their resolution to do the next:
- Ingest steady adjustments (like buyer orders) from upstream techniques
- Seize tables into the info lake
- Present ACID properties on the info lake to assist interactive analytics by enabling constant views on information whereas new information is being ingested
- Present schema flexibility as a result of upstream information structure adjustments and provisions for late arrival of knowledge
To ship on these necessities, organizations must construct customized frameworks to deal with in-place updates (additionally referred as upserts), deal with small recordsdata created because of the steady ingestion of adjustments from upstream techniques (similar to databases), deal with schema evolution, and compromise on offering ACID ensures on its information lake.
A processing framework like Apache Hudi could be a great way resolve such challenges. Hudi means that you can construct streaming information lakes with incremental information pipelines, with assist for transactions, record-level updates, and deletes on information saved in information lakes. Hudi is built-in with numerous AWS analytics companies, like AWS Glue, Amazon EMR, Athena, and Amazon Redshift. This helps you ingest information from a wide range of sources through batch streaming whereas enabling in-place updates to an append-oriented storage system similar to Amazon S3 (or HDFS). On this publish, we focus on a serverless method to combine Hudi with a streaming use case and create an in-place updatable information lake on Amazon S3.
Answer overview
We use Amazon Kinesis Knowledge Generator to ship pattern streaming information to Amazon Kinesis Knowledge Streams. To eat this streaming information, we arrange an AWS Glue streaming ETL job that makes use of the Apache Hudi Connector for AWS Glue to put in writing ingested and remodeled information to Amazon S3, and likewise creates a desk within the AWS Glue Knowledge Catalog.
After the info is ingested, Hudi organizes a dataset right into a partitioned listing construction beneath a base path pointing to a location in Amazon S3. Knowledge structure in these partitioned directories is determined by the Hudi dataset kind used throughout ingestion, similar to Copy on Write (CoW) and Merge on Learn (MoR). For extra details about Hudi storage sorts, see Utilizing Athena to Question Apache Hudi Datasets and Storage Varieties & Views.
CoW is the default storage kind of Hudi. On this storage kind, information is saved in columnar format (Parquet). Every ingestion creates a brand new model of recordsdata throughout a write. With CoW, every time there’s an replace to a document, Hudi rewrites the unique columnar file containing the document with the up to date values. Due to this fact, that is higher fitted to read-heavy workloads on information that adjustments much less ceaselessly.
The MoR storage kind is saved utilizing a mixture of columnar (Parquet) and row-based (Avro) codecs. Updates are logged to row-based delta recordsdata and are compacted to create new variations of columnar recordsdata. With MoR, every time there’s an replace to a document, Hudi writes solely the row for the modified document into the row-based (Avro) format, which is compacted (synchronously or asynchronously) to create columnar recordsdata. Due to this fact, MoR is best fitted to write or change-heavy workloads with a lesser quantity of learn.
For this publish, we use the CoW storage kind as an instance our use case of making a Hudi dataset and serving the identical through a wide range of readers. You possibly can prolong this resolution to assist MoR storage through choosing the particular storage kind throughout ingestion. We use Athena to learn the dataset. We additionally illustrate the capabilities of this resolution when it comes to in-place updates, nested partitioning, and schema flexibility.
The next diagram illustrates our resolution structure.
Create the Apache Hudi connection utilizing the Apache Hudi Connector for AWS Glue
To create your AWS Glue job with an AWS Glue customized connector, full the next steps:
- On the AWS Glue Studio console, select Market within the navigation pane.
- Seek for and select Apache Hudi Connector for AWS Glue.

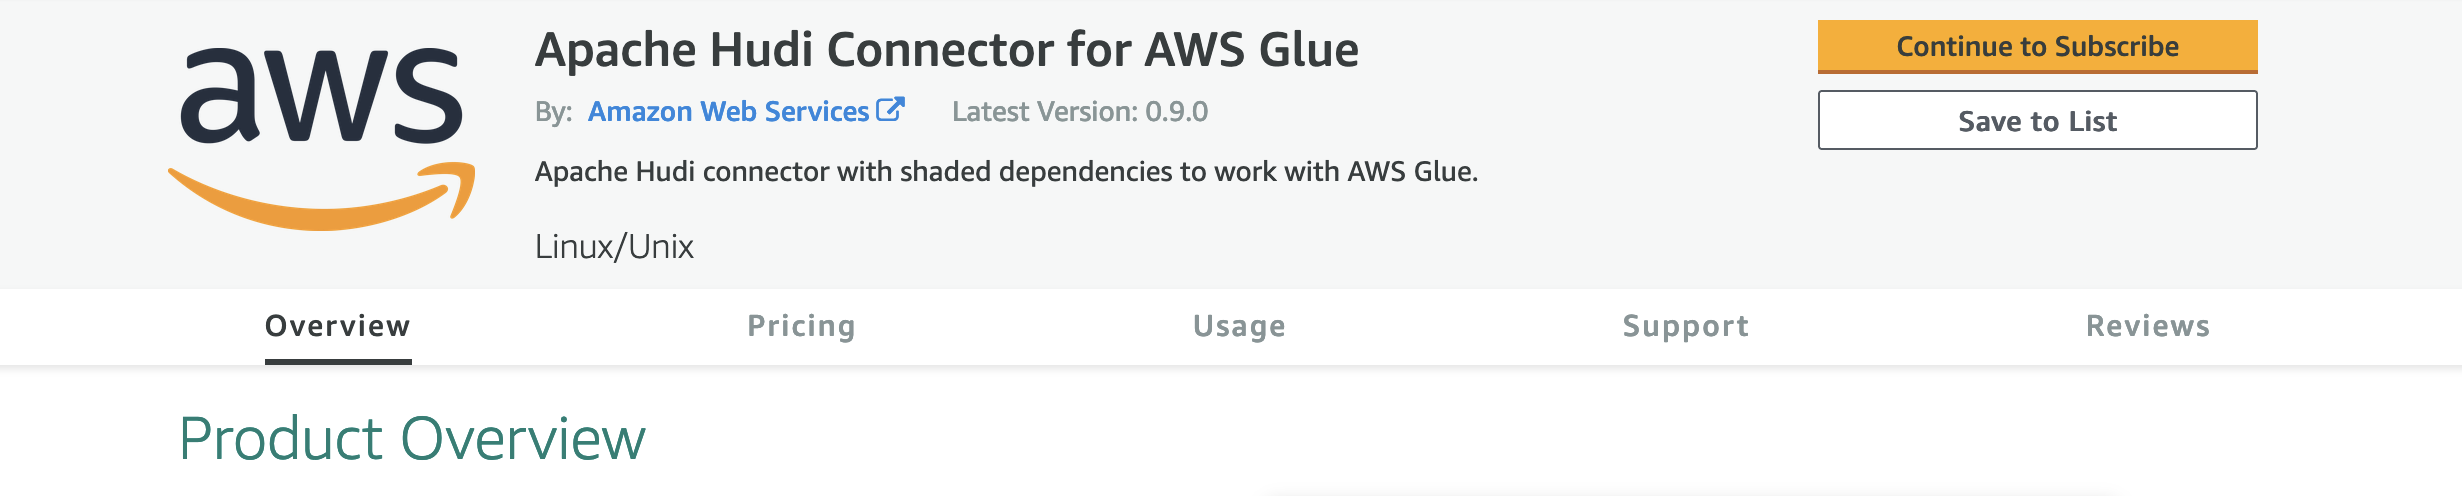
- Select Proceed to Subscribe.
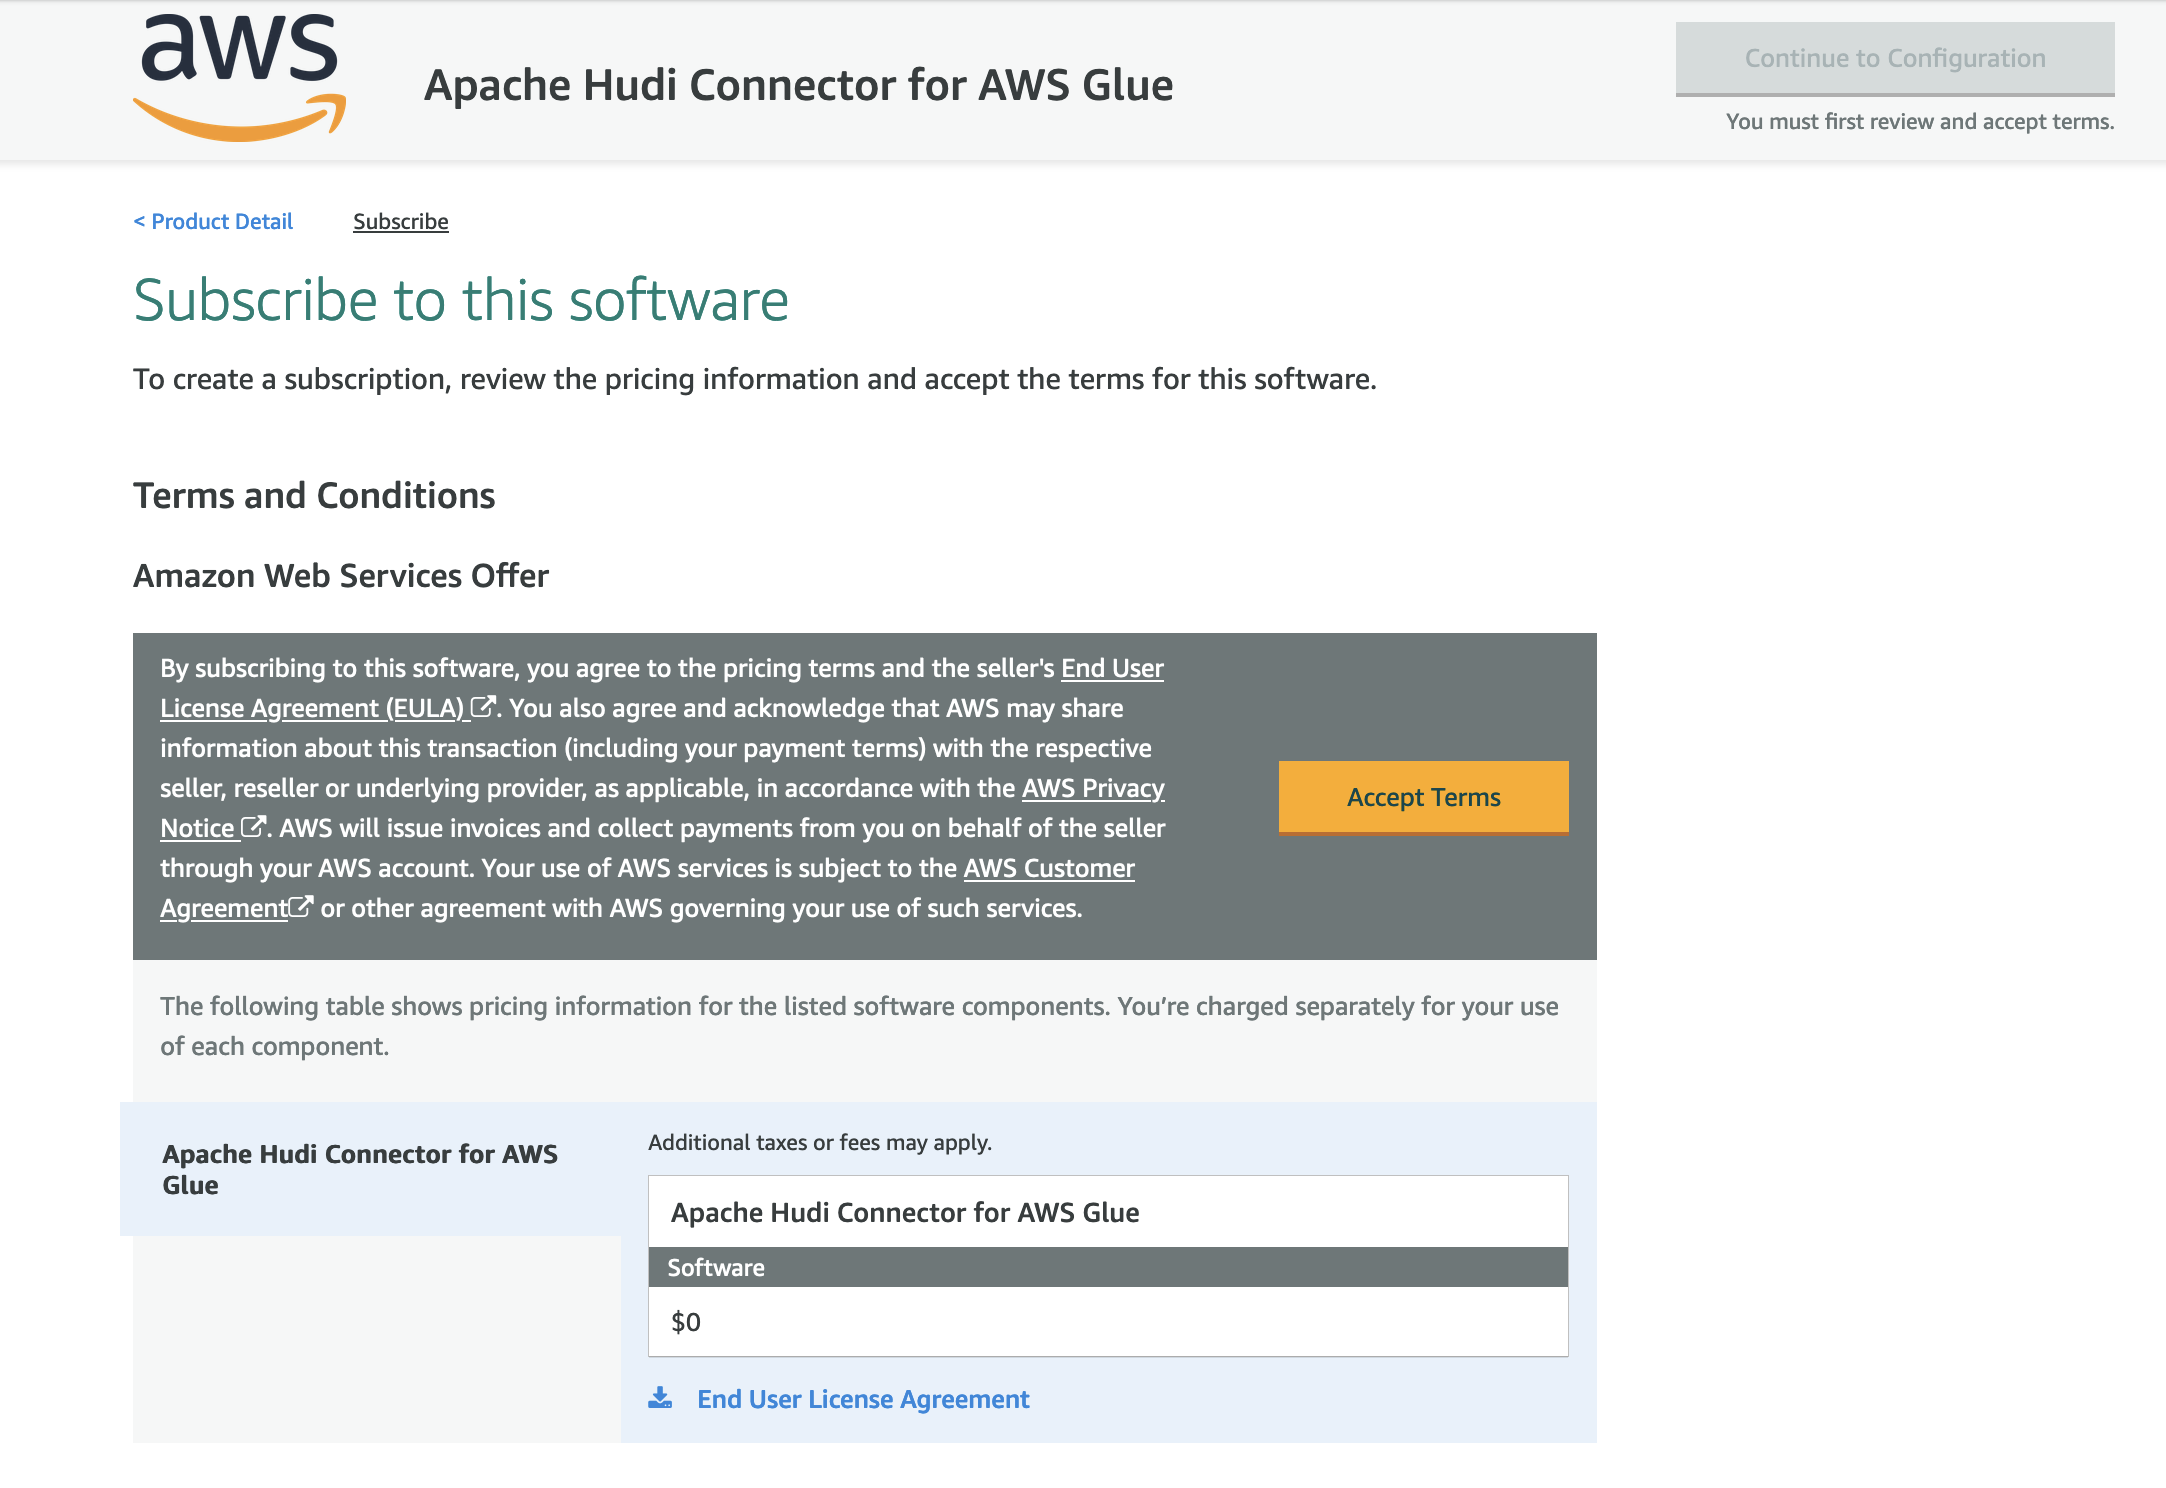
- Overview the phrases and situations and select Settle for Phrases.
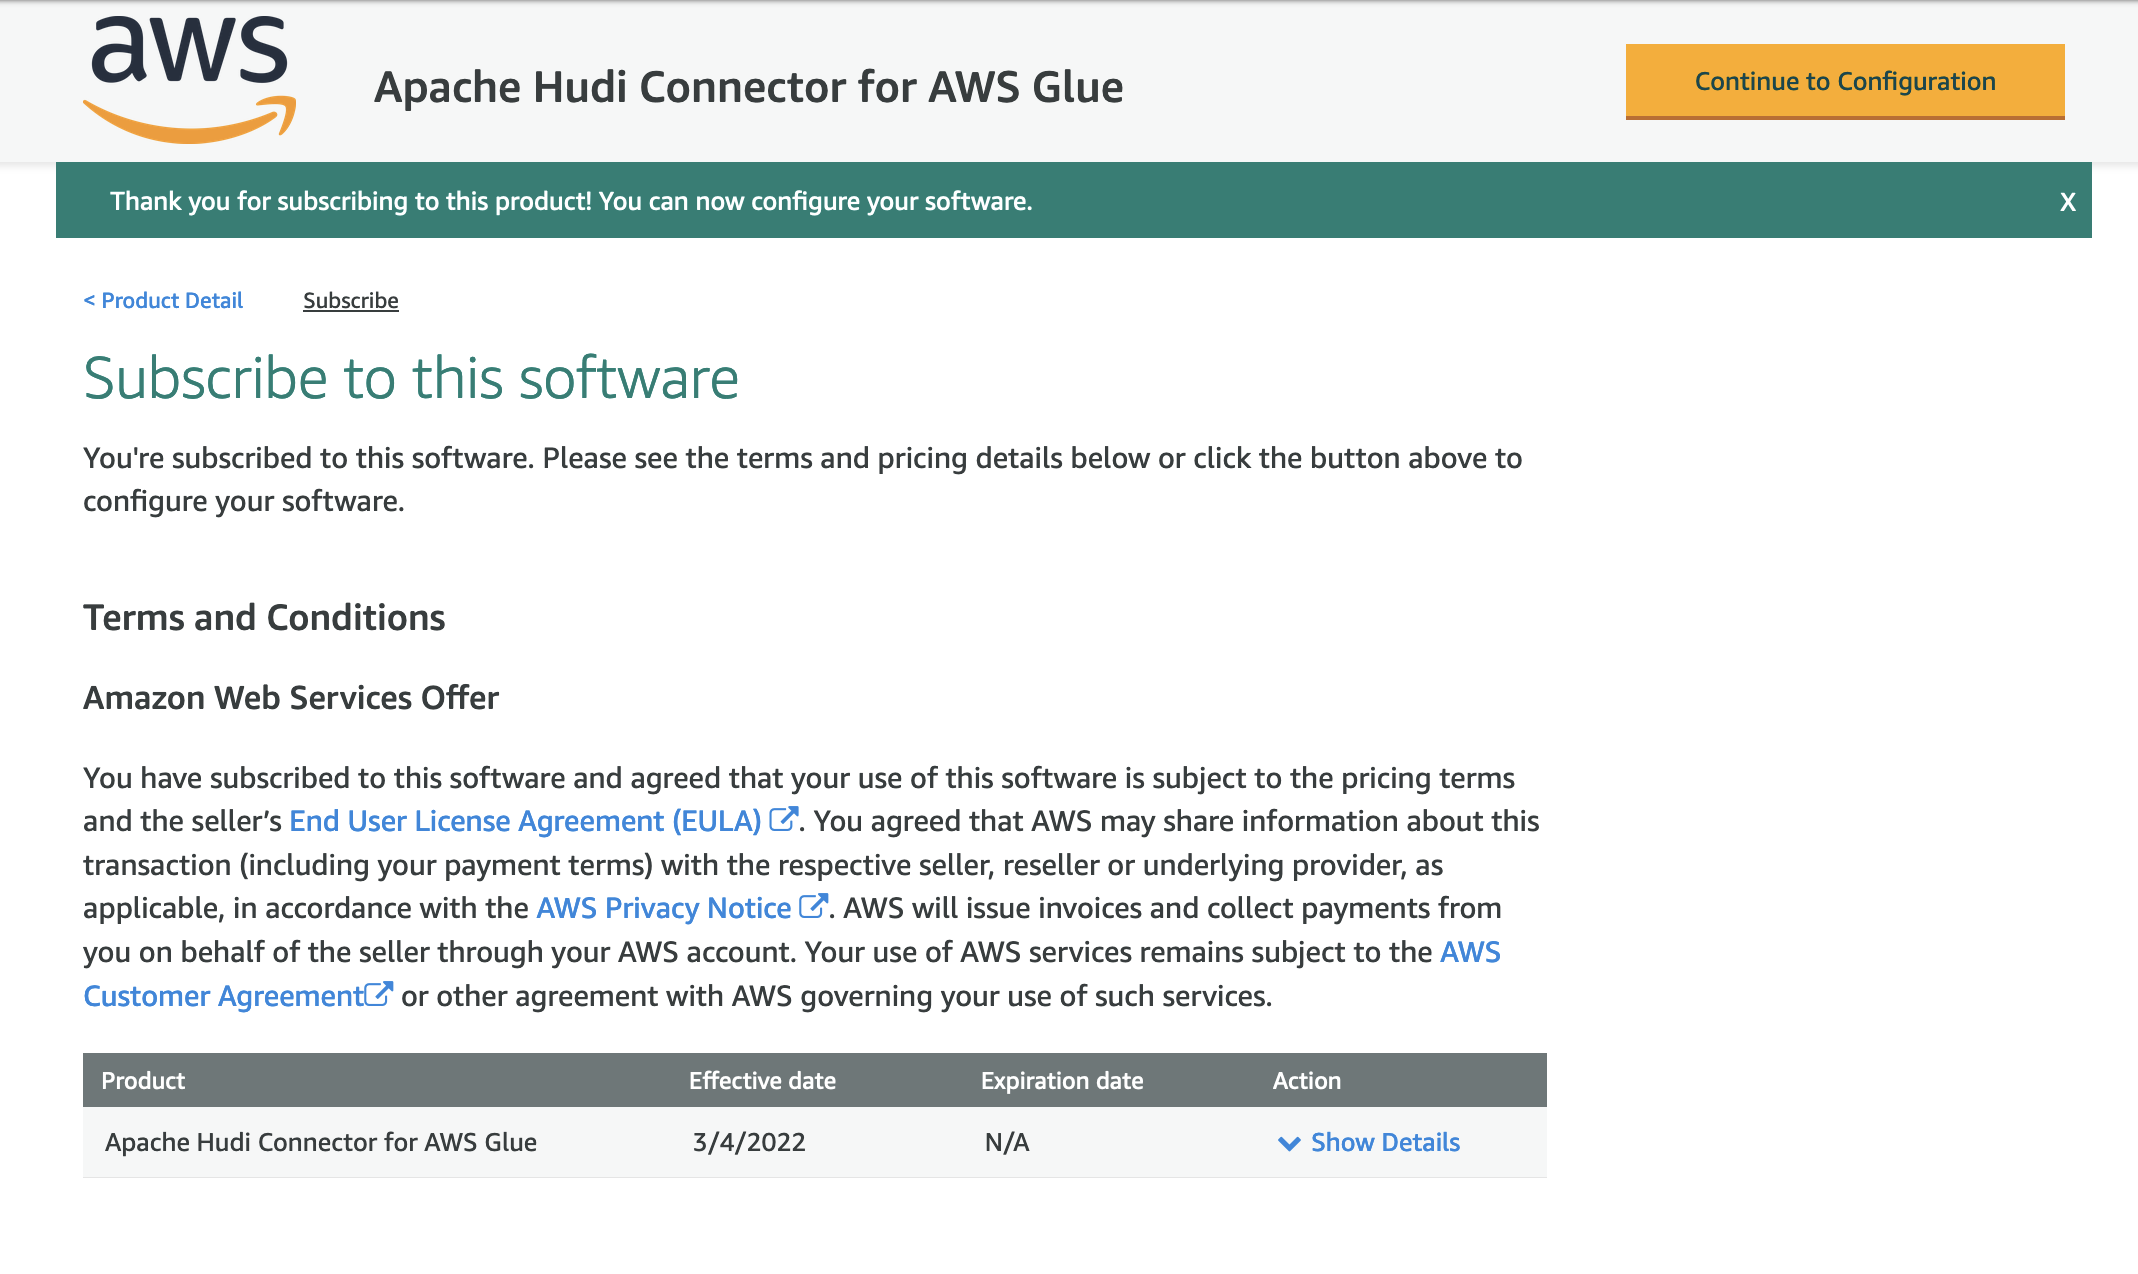
- Make it possible for the subscription is full and also you see the Efficient date populated subsequent to the product, then select Proceed to Configuration.
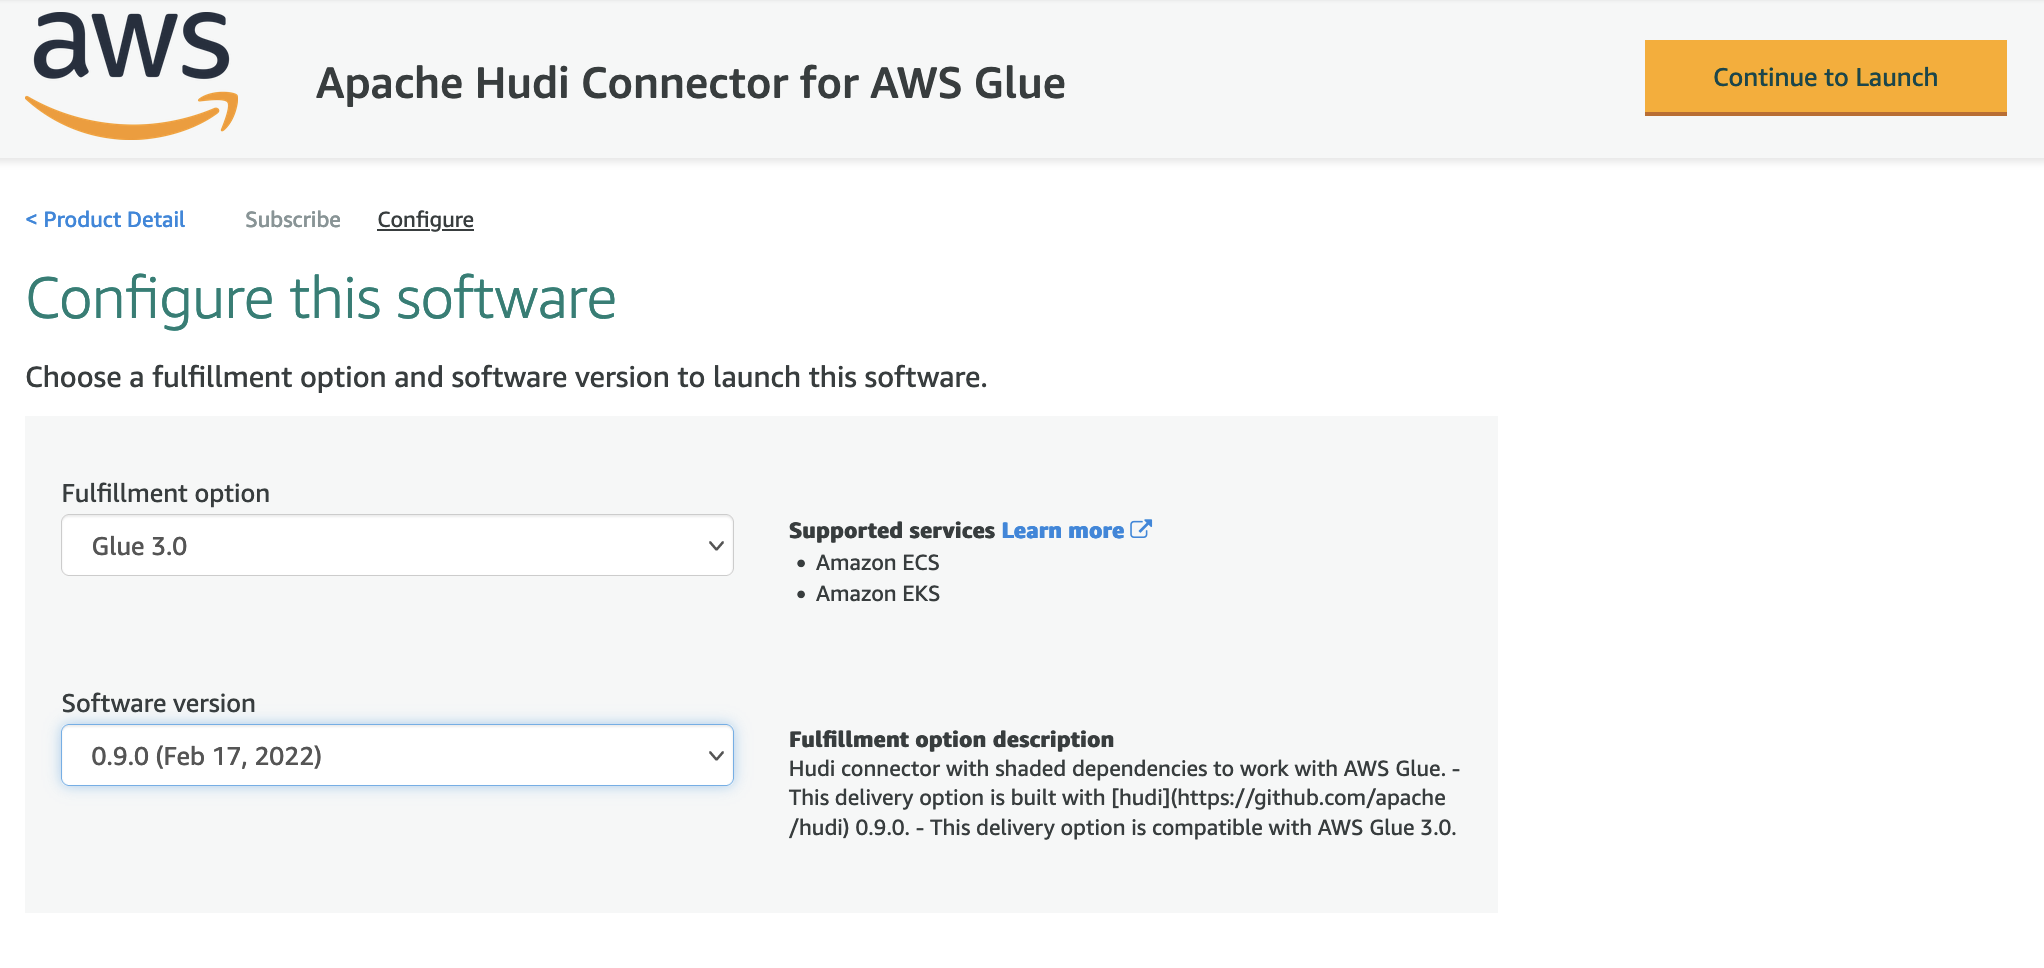
- For Supply Methodology, select Glue 3.0.
- For Software program Model, select the most recent model (as of this writing, 0.9.0 is the most recent model of the Apache Hudi Connector for AWS Glue).
- Select Proceed to Launch.
- Below Launch this software program, select Utilization Directions after which select Activate the Glue connector for Apache Hudi in AWS Glue Studio.

You’re redirected to AWS Glue Studio.
- For Title, enter a reputation on your connection (for instance, hudi-connection).
- For Description, enter an outline.
- Select Create connection and activate connector.

A message seems that the connection was efficiently created, and the connection is now seen on the AWS Glue Studio console.
Configure sources and permissions
For this publish, we offer an AWS CloudFormation template to create the next sources:
- An S3 bucket named
hudi-demo-bucket-<your-stack-id>that accommodates a JAR artifact copied from one other public S3 bucket exterior of your account. This JAR artifact is then used to outline the AWS Glue streaming job. - A Kinesis information stream named
hudi-demo-stream-<your-stack-id>. - An AWS Glue streaming job named
Hudi_Streaming_Job-<your-stack-id>with a devoted AWS Glue Knowledge Catalog namedhudi-demo-db-<your-stack-id>. Consult with the aws-samples github repository for the entire code of the job. - AWS Id and Entry Administration (IAM) roles and insurance policies with acceptable permissions.
- AWS Lambda capabilities to repeat artifacts to the S3 bucket and empty buckets first upon stack deletion.
To create your sources, full the next steps:
- Select Launch Stack:
- For Stack identify, enter
hudi-connector-blog-for-streaming-data. - For HudiConnectionName, use the identify you specified within the earlier part.
- Go away the opposite parameters as default.
- Select Subsequent.

- Choose I acknowledge that AWS CloudFormation may create IAM sources with customized names.
- Select Create stack.
Arrange Kinesis Knowledge Generator
On this step, you configure Kinesis Knowledge Generator to ship pattern information to a Kinesis information stream.
- On the Kinesis Knowledge Generator console, select Create a Cognito Person with CloudFormation.

You’re redirected to the AWS CloudFormation console.
- On the Overview web page, within the Capabilities part, choose I acknowledge that AWS CloudFormation may create IAM sources.
- Select Create stack.
- On the Stack particulars web page, within the Stacks part, confirm that the standing reveals
CREATE_COMPLETE. - On the Outputs tab, copy the URL worth for
KinesisDataGeneratorUrl.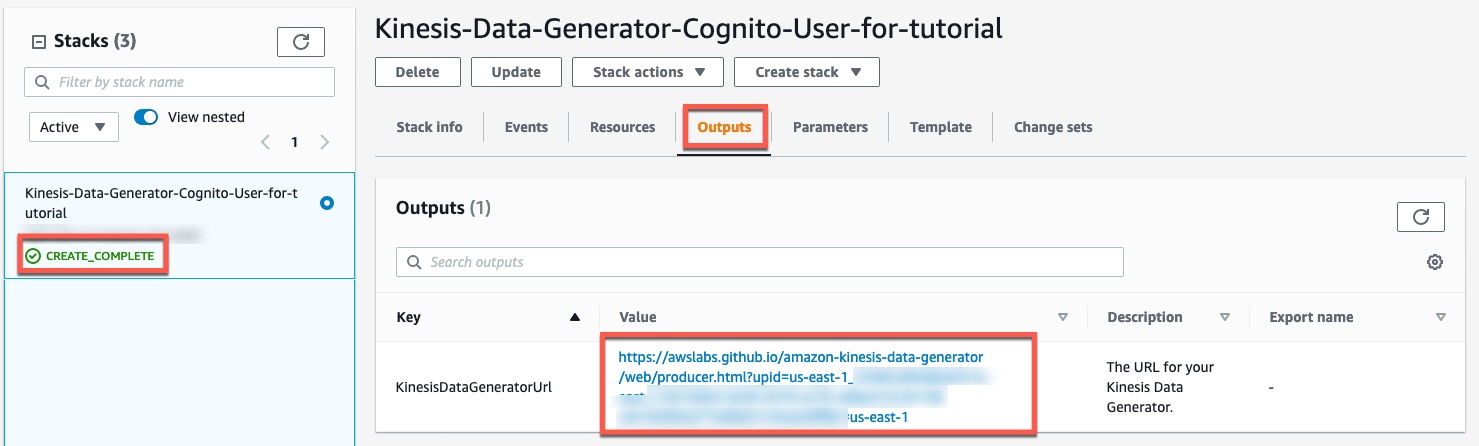
- Navigate to this URL in your browser.
- Enter the consumer identify and password offered and select Signal In.
Begin an AWS Glue streaming job
To begin an AWS Glue streaming job, full the next steps:
- On the AWS CloudFormation console, navigate to the Sources tab of the stack you created.
- Copy the bodily ID akin to the AWS::Glue::Job useful resource.

- On the AWS Glue Studio console, discover the job identify utilizing the bodily ID.
- Select the job to overview the script and job particulars.

- Select Run to start out the job.

- On the Runs tab, validate if the job is efficiently working.

Ship pattern information to a Kinesis information stream
Kinesis Knowledge Generator generates data utilizing random information based mostly on a template you present. Kinesis Knowledge Generator extends faker.js, an open-source random information generator.
On this step, you employ Kinesis Knowledge Generator to ship pattern information utilizing a pattern template utilizing the faker.js documentation to the beforehand created information stream created at one document per second fee. You maintain the ingestion till the tip of this tutorial to realize affordable information for evaluation whereas performing the remaining steps.
- On the Kinesis Knowledge Generator console, for Information per second, select the Fixed tab, and alter the worth to
1. - For File template, select the Template 1 tab, and enter the next code pattern into the textual content field:
- Select Take a look at template.

- Confirm the construction of the pattern JSON data and select Shut.

- Select Ship information.
- Go away the Kinesis Knowledge Generator web page open to make sure sustained streaming of random data into the info stream.
Proceed via the remaining steps when you generate your information.
Confirm dynamically created sources
When you’re producing information for evaluation, you’ll be able to confirm the sources you created.
Amazon S3 dataset
When the AWS Glue streaming job runs, the data from the Kinesis information stream are consumed and saved in an S3 bucket. Whereas creating Hudi datasets in Amazon S3, the streaming job can even create a nested partition construction. That is enabled via the utilization of Hudi configuration properties hoodie.datasource.write.partitionpath.subject and hoodie.datasource.write.keygenerator.class within the streaming job definition.
On this instance, nested partitions have been created by identify, 12 months, month, and day. The values of those properties are set as follows within the script for the AWS Glue streaming job.
For additional particulars on how CustomKeyGenerator works to generate such partition paths, consult with Apache Hudi Key Mills.
The next screenshot reveals the nested partitions created in Amazon S3.
AWS Glue Knowledge Catalog desk
A Hudi desk can also be created within the AWS Glue Knowledge Catalog and mapped to the Hudi datasets on Amazon S3. See the next code within the AWS Glue streaming job.
The next desk gives extra particulars on the configuration choices.
The next screenshot reveals the Hudi desk within the Knowledge Catalog and the related S3 bucket.
Learn outcomes utilizing Athena
Utilizing Hudi with an AWS Glue streaming job permits us to have in-place updates (upserts) on the Amazon S3 information lake. This performance permits for incremental processing, which permits quicker and extra environment friendly downstream pipelines. Apache Hudi permits in-place updates with the next steps:
- Outline an index (utilizing columns of the ingested document).
- Use this index to map each subsequent ingestion to the document storage areas (in our case Amazon S3) ingested beforehand.
- Carry out compaction (synchronously or asynchronously) to permit the retention of the most recent document for a given index.
In reference to our AWS Glue streaming job, the next Hudi configuration choices allow us to realize in-place updates for the generated schema.
The next desk gives extra particulars of the highlighted configuration choices.
To show an in-place replace, think about the next enter data despatched to the AWS Glue streaming job through Kinesis Knowledge Generator. The document identifier highlighted signifies the Hudi document key within the AWS Glue configuration. On this instance, Person3 receives two updates. In first replace, column_to_update_string is about to White; within the second replace, it’s set to Pink.
The streaming job processes these data and creates the Hudi datasets in Amazon S3. You possibly can question the dataset utilizing Athena. Within the following instance, we get the most recent replace.
Schema flexibility
The AWS Glue streaming job permits for automated dealing with of various document schemas encountered throughout the ingestion. That is particularly helpful in conditions the place document schemas might be topic to frequent adjustments. To elaborate on this level, think about the next situation:
- Case 1 – At time t1, the ingested document has the structure
<col 1, col 2, col 3, col 4> - Case 2 – At time t2, the ingested document has an additional column, with new structure
<col 1, col 2, col 3, col 4, col 5> - Case 3 – At time t3, the ingested document dropped the additional column and subsequently has the structure
<col 1, col 2, col 3, col 4>
For Case 1 and a pair of, the AWS Glue streaming job depends on the built-in schema evolution capabilities of Hudi, which permits an replace to the Knowledge Catalog with the additional column (col 5 on this case). Moreover, Hudi additionally provides an additional column within the output recordsdata (Parquet recordsdata written to Amazon S3). This enables for the querying engine (Athena) to question the Hudi dataset with an additional column with none points.
As a result of Case 2 ingestion updates the Knowledge Catalog, the additional column (col 5) is predicted to be current in each subsequent ingested document. If we don’t resolve this distinction, the job fails.
To beat this and obtain Case 3, the streaming job defines a customized perform named evolveSchema, which handles the document structure mismatches. The tactic queries the AWS Glue Knowledge Catalog for every to-be-ingested document and will get the present Hudi desk schema. It then merges the Hudi desk schema with the schema of the to-be-ingested document and enriches the schema of the document earlier than exposing with the Hudi dataset.
For this instance, the to-be-ingested document’s schema <col 1, col 2, col 3, col 4> is modified to <col 1, col 2, col 3, col 4, col 5>, the place the worth of the additional col 5 is about to NULL.
As an example this, we cease the prevailing ingestion of Kinesis Knowledge Generator and modify the document structure to ship an additional column known as new_column:

The Hudi desk within the Knowledge Catalog updates as follows, with the newly added column (Case 2).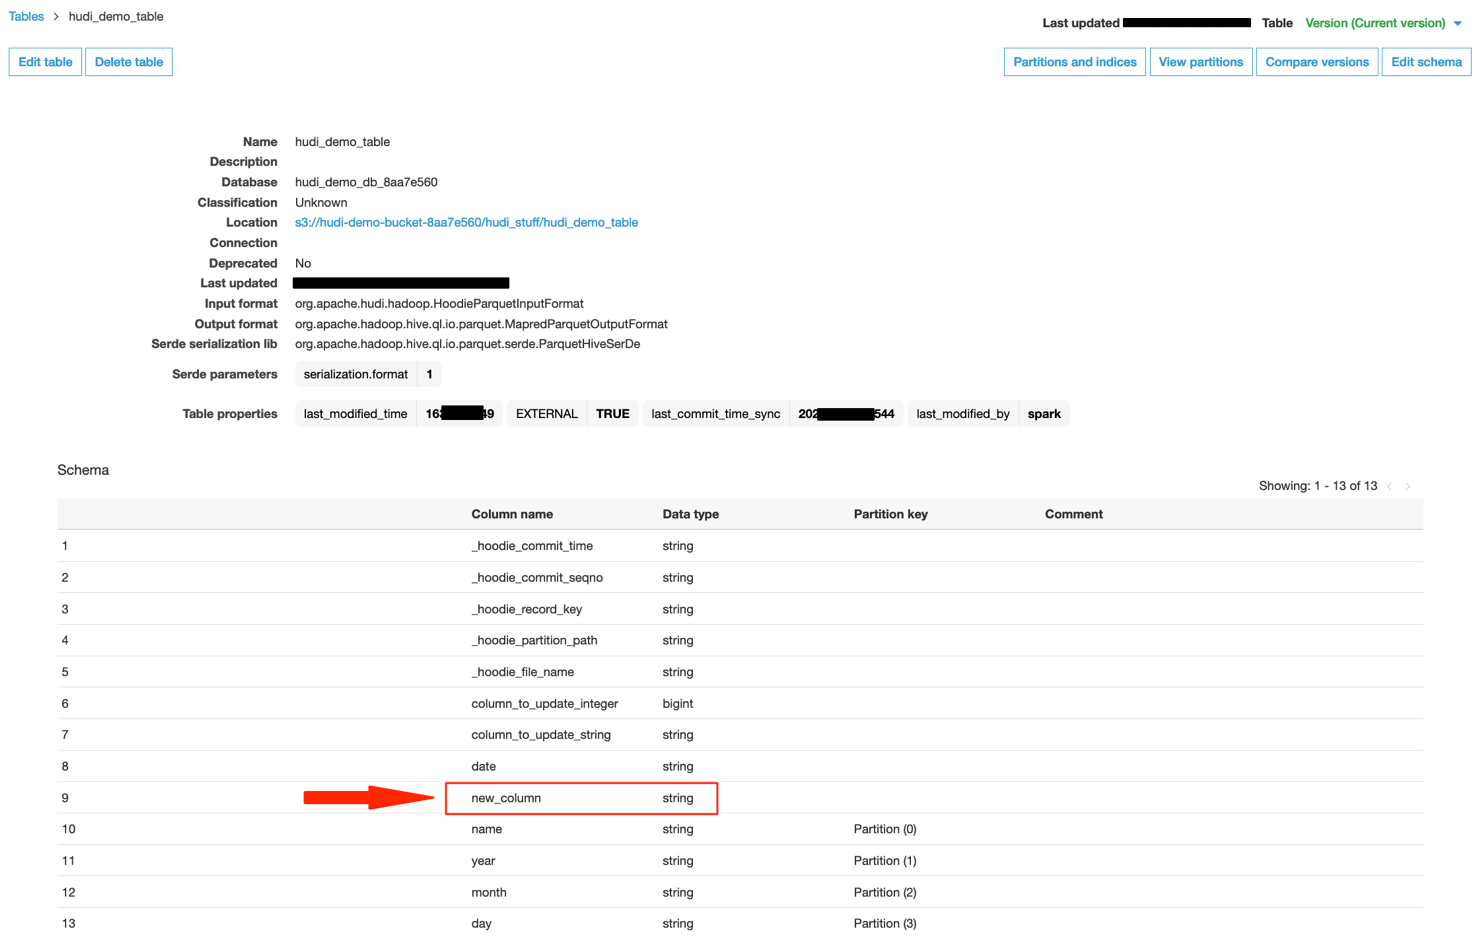
After we question the Hudi dataset utilizing Athena, we will see the presence of a brand new column.
We will now use Kinesis Knowledge Generator to ship data with an previous schema—with out the newly added column (Case 3).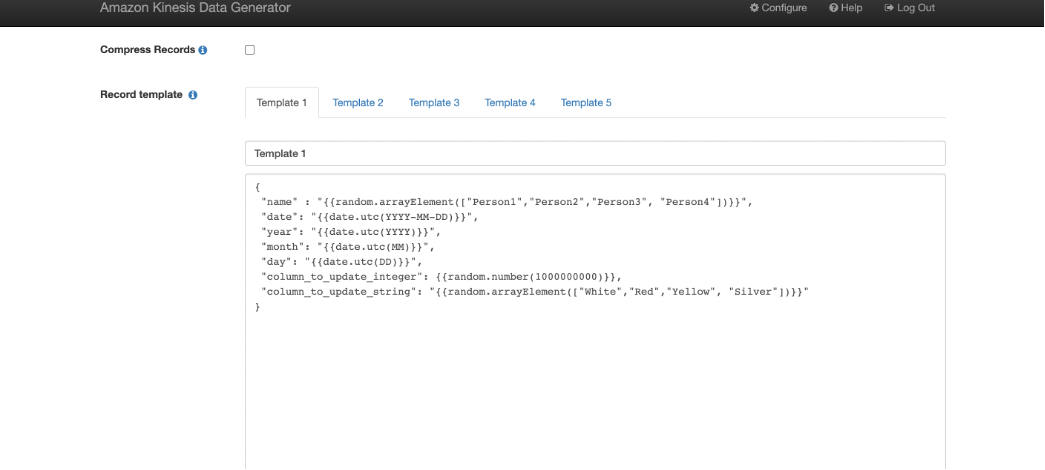
On this situation, our AWS Glue job retains working. After we question utilizing Athena, the additional added column will get populated with NULL values.
If we cease Kinesis Knowledge Generator and begin sending data with a schema containing further columns, the job retains working and the Athena question continues to return the most recent values.
Clear up
To keep away from incurring future fees, delete the sources you created as a part of the CloudFormation stack.
Abstract
This publish illustrated methods to arrange a serverless pipeline utilizing an AWS Glue streaming job with the Apache Hudi Connector for AWS Glue, which runs repeatedly and consumes information from Kinesis Knowledge Streams to create a near-real-time information lake that helps in-place updates, nested partitioning, and schema flexibility.
You too can use Apache Kafka and Amazon Managed Streaming for Apache Kafka (Amazon MSK) because the supply of the same streaming job. We encourage you to make use of this method for organising a near-real-time information lake. As all the time, AWS welcomes suggestions, so please go away your ideas or questions within the feedback.
In regards to the Authors
 Nikhil Khokhar is a Options Architect at AWS. He joined AWS in 2016 and focuses on constructing and supporting information streaming options that assist clients analyze and get worth out of their information. In his free time, he makes use of his 3D printing expertise to unravel on a regular basis issues.
 Dipta S Bhattacharya is a Options Architect Supervisor at AWS. Dipta joined AWS in 2018. He works with giant startup clients to design and develop architectures on AWS and assist their journey on the cloud.
[ad_2]

