



[ad_1]
API (Software Programming Interface) is a design sample used to reveal a platform or utility to a different social gathering. APIs allow applications and functions to speak with platforms and companies, and will be designed to make use of REST (REpresentational State Switch) as a software program structure fashion.
APIs in OLTP (on-line transaction processing) are known as regularly (tens to lots of of occasions per second), delivering small payloads (output) within the order of some bytes to kilobytes. Nonetheless, OLAP (on-line analytical processing) has the ratio flipped. OLAP APIs have a low name quantity however massive payload (100 MB to a number of GBs). This sample provides new challenges, like asynchronous processing, managing compute capability, and scaling.
On this publish, we stroll by organising an utility API utilizing the Amazon Redshift Knowledge API, AWS Lambda, and Amazon API Gateway. The API performs asynchronous processing of consumer requests, sends consumer notifications, saves processed knowledge in Amazon Easy Storage Service (Amazon S3), and returns a presigned URL for the consumer or utility to obtain the dataset over HTTPS. We additionally present an AWS CloudFormation template to assist arrange sources, accessible on the GitHub repo.
Answer overview
In our use case, Acme sells flowers on its web site acmeflowers.com and collects opinions from prospects. The web site maintains a self-service stock, permitting completely different producers to ship flowers and different supplies to acmeflowers.com when their provides are working low.
Acme makes use of Amazon Redshift as their knowledge warehouse. Close to-real-time adjustments and updates to their stock circulate to Amazon Redshift, displaying correct availability of inventory. The desk PRODUCT_INVENTORY accommodates up to date knowledge. Acme desires to reveal stock info to companions in a cheap, safe approach for stock administration course of. If Acme’s companions are utilizing Amazon Redshift, cross-account knowledge sharing might be a possible choice. If companions aren’t utilizing Amazon Redshift, they may use the answer described on this publish.
The next diagram illustrates our answer structure:
The workflow accommodates the next steps:
- The consumer utility sends a request to API Gateway and will get a request ID as a response.
- API Gateway calls the request receiver Lambda operate.
- The request receiver operate performs the next actions:
- Writes the standing to an Amazon DynamoDB management desk.
- Writes a request to Amazon Easy Queue Service (Amazon SQS).
- A second Lambda operate, the request processor, performs following actions:
- Polls Amazon SQS.
- Writes the standing again to the DynamoDB desk.
- Runs a SQL question on Amazon Redshift.
- Amazon Redshift exports the info to an S3 bucket.
- A 3rd Lambda operate, the poller, checks the standing of the leads to the DynamoDB desk.
- The poller operate fetches outcomes from Amazon S3.
- The poller operate sends a presigned URL to obtain the file from the S3 bucket to the requestor by way of Amazon Easy Electronic mail Service (Amazon SES).
- The requestor downloads the file utilizing the URL.
The workflow additionally accommodates the next steps to test the standing of the request at numerous phases:
- The consumer utility or consumer sends a request ID to API Gateway that’s generated in Step 1.
- API Gateway calls the standing test Lambda operate.
- The operate reads the standing from the DynamoDB management desk.
- The standing is returned to the requestor by API Gateway.
Conditions
You want the next stipulations to deploy the instance utility:
Full the next prerequisite steps earlier than deploying the pattern utility:
- Run the next DDL on the Amazon Redshift cluster utilizing the question editor to create the schema and desk:
- Configure AWS Secrets and techniques Supervisor to retailer the Amazon Redshift credentials.
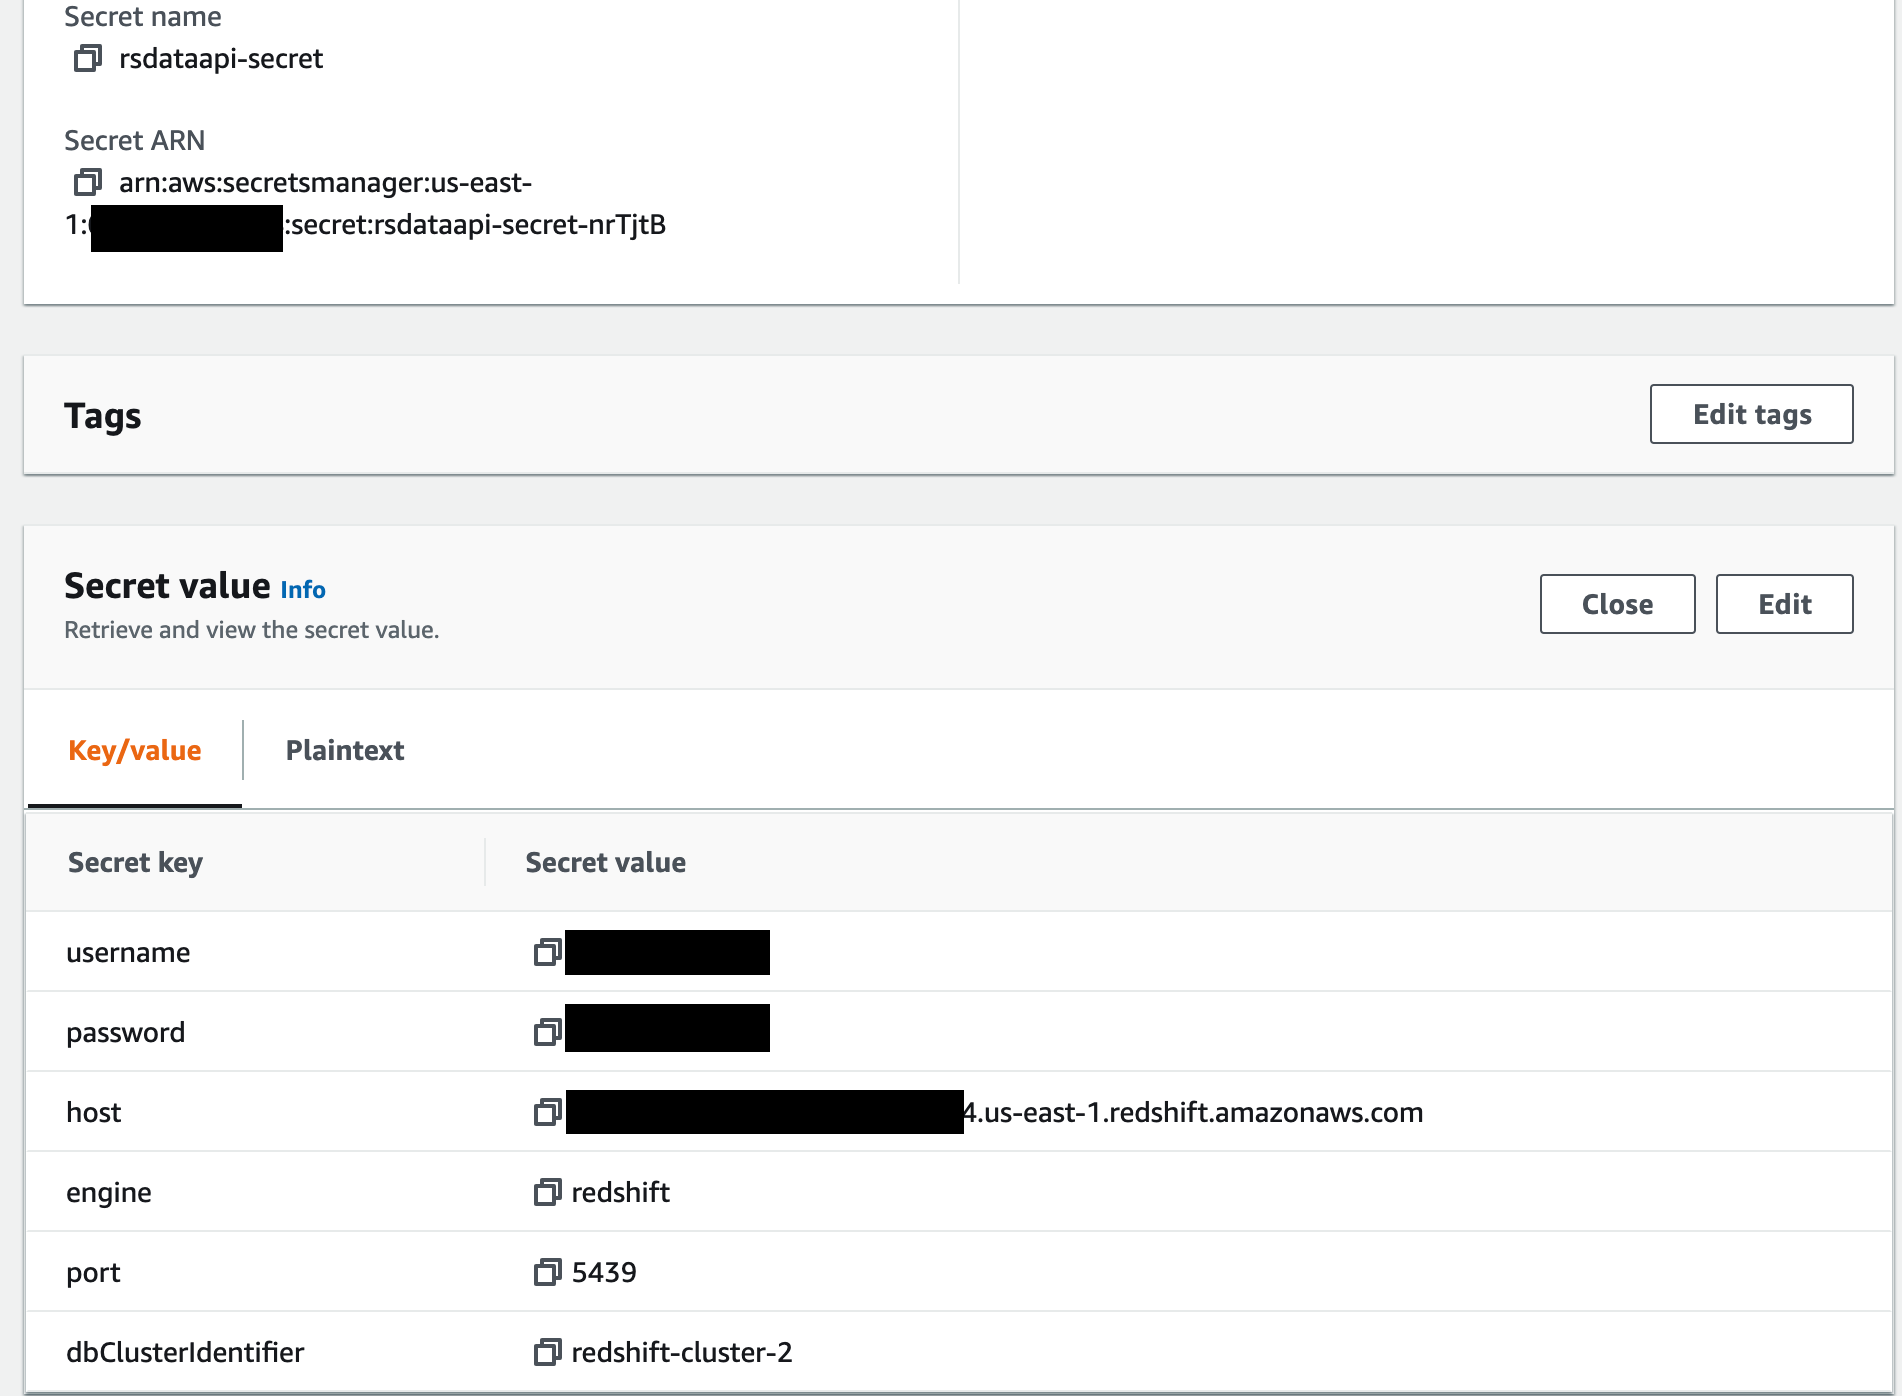
- Configure Amazon SES with an e-mail deal with or distribution record to ship and obtain standing updates.
Deploy the applying
To deploy the applying, full the next steps:
- Clone the repository and obtain the pattern supply code to your setting the place AWS SAM is put in:
- Turn into the challenge listing containing the
template.yamlfile: - Change the API .yaml file to replace your AWS account quantity and the Area the place you’re deploying this answer:
- Construct the applying utilizing AWS SAM:
- Deploy the applying to your account utilizing AWS SAM. Remember to comply with correct Amazon S3 naming conventions, offering globally distinctive names for S3 buckets:


SAM deploy requires you to offer the next parameters for configuration:
| Parameter | Description |
| RSClusterID | The cluster identifier in your current Amazon Redshift cluster. |
| RSDataFetchQ | The question to fetch the info out of your Amazon Redshift tables (for instance, choose * from rsdataapi.product_detail the place sku= the enter handed from the API) |
| RSDataFileS3BucketName | The S3 bucket the place the dataset from Amazon S3 is uploaded. |
| RSDatabaseName | The database in your Amazon Redshift cluster. |
| RSS3CopyRoleArn | The IAM function for Amazon Redshift that has entry to repeat information to and from Amazon Redshift to Amazon S3. This function needs to be related together with your Amazon Redshift cluster. |
| RSSecret | The Secrets and techniques Supervisor ARN in your Amazon Redshift credentials. |
| RSUser | The consumer identify to hook up with the Amazon Redshift cluster. |
| RsFileArchiveBucket | The S3 bucket from the place the zipped dataset is downloaded. This needs to be completely different than your add bucket. |
| RsS3CodeRepo | The S3 bucket the place the packages or .zip file is saved. |
| RsSingedURLExpTime | The expiry time in seconds for the presigned URL to obtain the dataset from Amazon S3. |
| RsSourceEmailAddress | The e-mail deal with of the distribution record for which Amazon SES is configured to make use of because the supply for sending completion standing. |
| RsTargetEmailAddress | The e-mail deal with of the distribution record for which Amazon SES is configured to make use of because the vacation spot for receiving completion standing. |
| RsStatusTableName | The identify of the standing desk for capturing the standing of varied phases from begin to completion of request. |
This template is designed solely to indicate how one can arrange an utility API utilizing the Amazon Redshift Knowledge API, Lambda, and API Gateway. This setup isn’t meant for manufacturing use with out modification.
Take a look at the applying
You should use Postman or every other utility to hook up with API Gateway and go the request to entry the dataset from Amazon Redshift. The APIs are approved by way of IAM customers. Earlier than sending a request, select your authorization kind as AWS SigV4 and enter the values for AccessKey and SecretKey for the IAM consumer.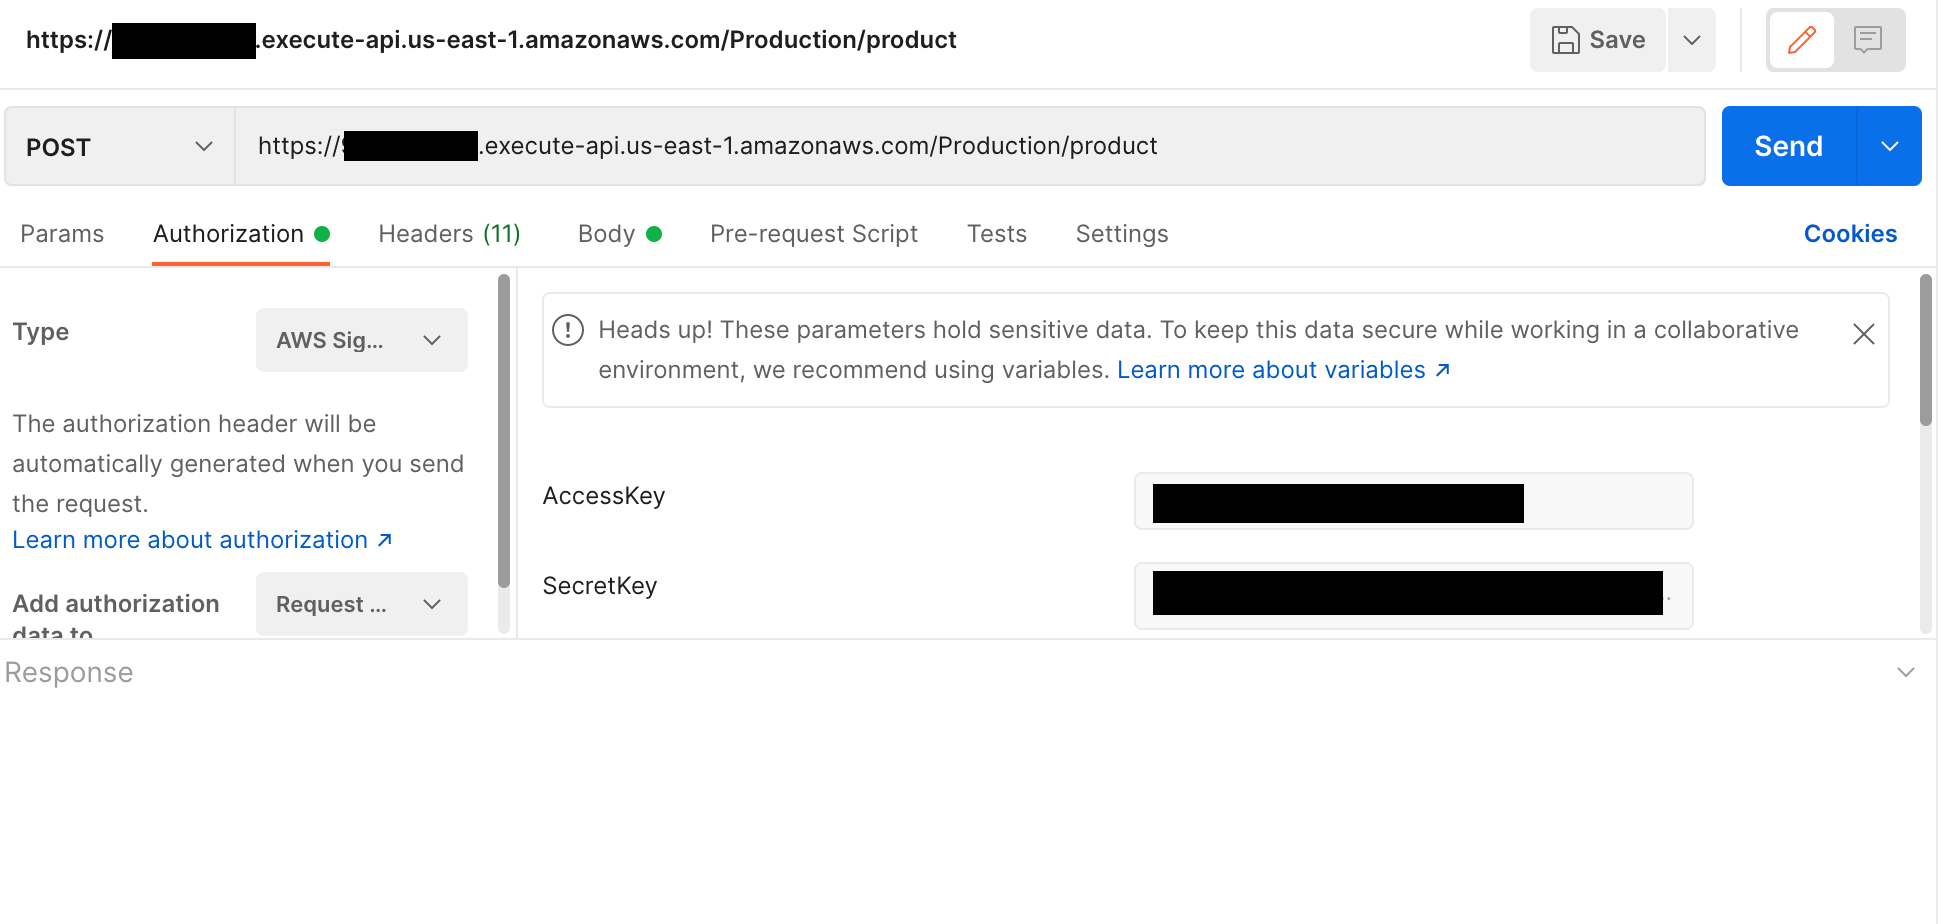
The next screenshot exhibits a pattern request.
The next screenshot exhibits the e-mail response.
The next screenshot exhibits pattern response with the standing of a request. That you must go the request ID and enter all for standing historical past or newest for contemporary standing.

Clear up
While you’re completed testing this answer, bear in mind to scrub up all of the AWS sources that you just created utilizing AWS SAM.
Delete the add and obtain S3 buckets by way of the Amazon S3 console after which run the next on SAM CLI:
For extra info, see sam delete.
Abstract
On this publish, we confirmed you how one can arrange an utility API that makes use of the Amazon Redshift Knowledge API, Lambda, and API Gateway. The API performs asynchronous processing of consumer requests, sends consumer notifications, saves processed knowledge in Amazon S3, and returns a presigned URL for the consumer or utility to obtain the dataset over HTTPs.
Give this answer a attempt to share your expertise with us!
Concerning the Authors
 Jeetesh Srivastva is a Sr. Supervisor Specialist Options Architect at AWS. He makes a speciality of Amazon Redshift and works with prospects to implement scalable options utilizing Amazon Redshift and different AWS Analytic companies. He has labored to ship on-premises and cloud-based analytic options for purchasers in banking and finance and hospitality trade verticals.
 Ripunjaya Pattnaik is an Enterprise Options Architect at AWS. He enjoys problem-solving together with his prospects and being their advisor. In his free time, he likes to strive new sports activities, play ping pong, and watch motion pictures.
[ad_2]

