



[ad_1]
On the subject of time-series knowledge, it’s extra frequent to entry new knowledge than current knowledge, such because the final 4 hours or in the future. Typically, software groups should keep a number of indexes for various knowledge workloads, which carry new necessities to arrange a customized answer to handle the index lifecycles. This turns into tedious because the indexes develop, and it ends in housekeeping overhead.
Amazon OpenSearch Service (successor to Amazon Elasticsearch Service) allows you to automate recurring index administration actions. This avoids having to make use of any further instruments to handle the index lifecycles. Index State Administration (ISM) enables you to create a coverage that automates these operations based mostly on index age, measurement, and different circumstances, all from inside your Amazon OpenSearch Service area.
On this put up, we focus on how one can implement a coverage to automate routine index administration duties and apply them to indexes and index patterns.
Conditions
Earlier than you get began, make sure that to finish the next stipulations:
- Have Elasticsearch 6.8 or later (required to make use of ISM and UltraWarm) or Arrange a brand new Amazon OpenSearch Service area with UltraWarm enabled.
- Register a handbook snapshot repository on your new area.
- Make it possible for your consumer function has enough permissions to entry the Kibana console of the Amazon OpenSearch Service area. If required, validate and configure the entry to your domains.
Use case
Amazon OpenSearch Service helps three storage tiers: the default “scorching” for lively writing and low-latency analytics, UltraWarm for read-only knowledge as much as three petabytes at one-tenth of the new tier price, and chilly for limitless long-term archival. Though scorching storage is used for indexing and offering the quickest entry, UltraWarm enhances the new storage tier by offering cheaper storage for older and less-frequently accessed knowledge. That is completed whereas sustaining the identical interactive analytics expertise. Moderately than hooked up storage, UltraWarm nodes use Amazon Easy Storage Service (Amazon S3) and a complicated caching answer to enhance efficiency.
To display the performance, we current a pattern use case of dealing with time-series knowledge in each day indices. On this use case, we routinely snapshot every index after 24 hours, then we migrate the index from the default scorching state to UltraWarm storage after two days, chilly storage after 30 days, and eventually delete the index after 60 days.
After you create the Amazon OpenSearch Service area and register a snapshot repository, full the next steps:
- Await the area standing to show lively and select the Kibana endpoint.
- Log in utilizing the Kibana UI endpoint.
- On Kibana’s splash web page, add the entire pattern knowledge listed by selecting Attempt our pattern knowledge and selecting Add knowledge.
- After including the information, select Index Administration (the IM icon on the left navigation pane), which lands into the Index Insurance policies web page.
- Select Create coverage.
- For Identify coverage, enter
ism-policy-example. - Change the default coverage with the next coverage:
Be aware that the final part of the coverage, “ism_template”, is used to routinely connect the ISM coverage to any newly created index that matches the index_patterns. You may outline a number of patterns.
Moreover, you should use the ISM API to programmatically work with insurance policies and managed indexes.
- Select Create. Now you can see your index coverage on the Index Insurance policies web page.
- On the Indices web page, seek for
kibana_sample, which ought to checklist the entire pattern knowledge indexes that you just added earlier. - Choose the entire indexes and select Apply coverage.
- From the Coverage ID drop-down menu, select the coverage created within the earlier step.
- Select Apply.
The coverage is now assigned and begins managing the indexes. On the Managed Indices web page, you’ll be able to observe the standing as Initializing.
When initialization is full, the standing modifications to Working.
It’s also possible to set a refresh frequency to refresh the managed indexes’ standing info.
Demystifying the coverage
On this part, we clarify the index coverage and its construction.
Insurance policies are JSON paperwork that outline the next:
- The states an index will be in
- Any actions that you really want the plugin to take when an index enters the state
- Situations that should be met for an index to maneuver or transition into a brand new state
The coverage doc begins with primary metadata comparable to description, the default_state that the index ought to enter, and eventually a collection of state definitions.
A state is the standing that the managed index is at present in. A managed index can solely be in a single state at a time. Every state has related actions which might be run sequentially upon getting into a state, and transitions which might be checked after the entire actions are full.
The primary state is scorching. On this use case, no actions are outlined on this scorching state. Furthermore, the managed indexes land on this state initially, after which transition to snapshot, heat, chilly, and eventually delete. Transitions outline the circumstances that should be met for a state to alter (on this case, change to snapshot after the index crosses 24 hours).
We will shortly confirm the standing within the Index Managemet part of Kibana. Every index may have state particulars listed beneath Coverage managed indices.
It’s also possible to confirm this on the Amazon OpenSearch Service console beneath the Ultrawarm Storage utilization and Chilly Storage utilization columns.
The final state of the coverage doc marks the indexes to delete based mostly on the actions. This coverage state assumes that your index is non-critical and not receiving write requests. Having zero replicas carries some danger of information loss.
Amongst different actions, it’s also possible to configure the notification to ship coverage motion info to Chime, Slack, or a webhook URL. Full particulars will be discovered right here.
The next screenshot exhibits the index standing on the console.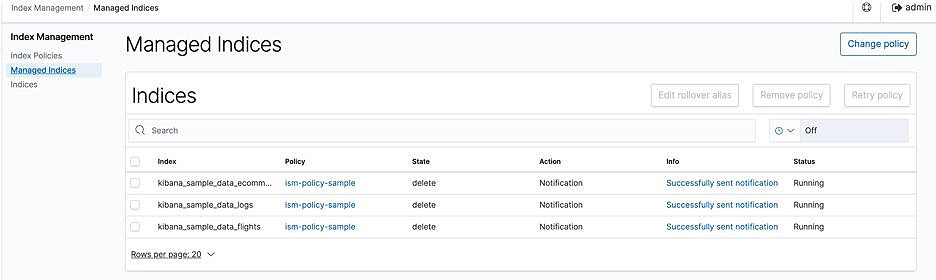
Further info on ISM insurance policies
You probably have an current Amazon OpenSearch Service area with no UltraWarm assist (due to any lacking prerequisites), you should use coverage operations read_only and reduces_replicas to interchange the nice and cozy state. The next code is the coverage template for these two states:
Abstract
On this put up, you discovered the way to use the ISM function with UltraWarm and chilly storage tiers for Amazon OpenSearch Service. The walkthrough illustrated the way to handle indexes utilizing this plugin with a pattern lifecycle coverage.
For extra details about the ISM plugin, see Index State Administration. For those who want enhancements or produce other function requests, then please file an difficulty. To get entangled with the challenge, see Contributing Pointers.
A giant takeaway for me as I evaluated the ISM plugin in Amazon OpenSearch Service was that the ISM plugin is absolutely suitable and works on any deployment of the open supply OpenSearch software program. For extra info, see the Index State Administration in OpenSearch documentation.
In regards to the Writer
 Gene Alpert is a Massive Knowledge and Analytics Advisor with Amazon Internet Providers. He helps AWS clients optimize their cloud knowledge operations.
[ad_2]

