



[ad_1]
Information analytics stays a continuously scorching subject. Increasingly companies are starting to grasp the potential their information has to permit them to serve clients extra successfully and provides them a aggressive benefit. Nonetheless, for a lot of small to medium companies, gaining perception from their information might be difficult as a result of they usually lack in-house information engineering expertise and data.
Information enrichment is one other problem. Companies that target analytics utilizing solely their inner datasets miss the chance to achieve higher insights through the use of dependable and credible public datasets. Small to medium companies aren’t any exception to this shortcoming, the place obstacles similar to not having enough information diminish their skill to make well-informed selections primarily based on correct analytical insights.
On this put up, we show how AWS Glue DataBrew allows companies of all sizes to get began with information analytics with no prior coding data. DataBrew is a visible information preparation software that makes it simple for information analysts and scientists to wash and normalize information in preparation for analytics or machine studying. It contains greater than 350 pre-built transformations for widespread information preparation use circumstances, enabling you to get began with cleansing, making ready, and mixing your datasets with out writing code.
For this put up, we assume the function of a fictitious small Dutch photo voltaic panel distribution and set up firm named OurCompany. We show how this firm can put together, mix, and enrich an inner dataset with publicly accessible information from the Dutch public entity, the Centraal Bureau voor de Statistiek (CBS), or in English, Statistics Netherlands. In the end, OurCompany needs to know the way nicely they’re performing in comparison with the official reported values by the CBS throughout two vital key efficiency indicators (KPIs): the quantity of photo voltaic panel installations, and complete vitality capability in kilowatt (kW) per area.
Resolution overview
The structure makes use of DataBrew for information preparation and transformation, Amazon Easy Storage Service (Amazon S3) because the storage layer of your complete information pipeline, and the AWS Glue Information Catalog for storing the dataset’s enterprise and technical metadata. Following the trendy information structure finest practices, this resolution adheres to foundational logical layers of the Lake Home Structure.
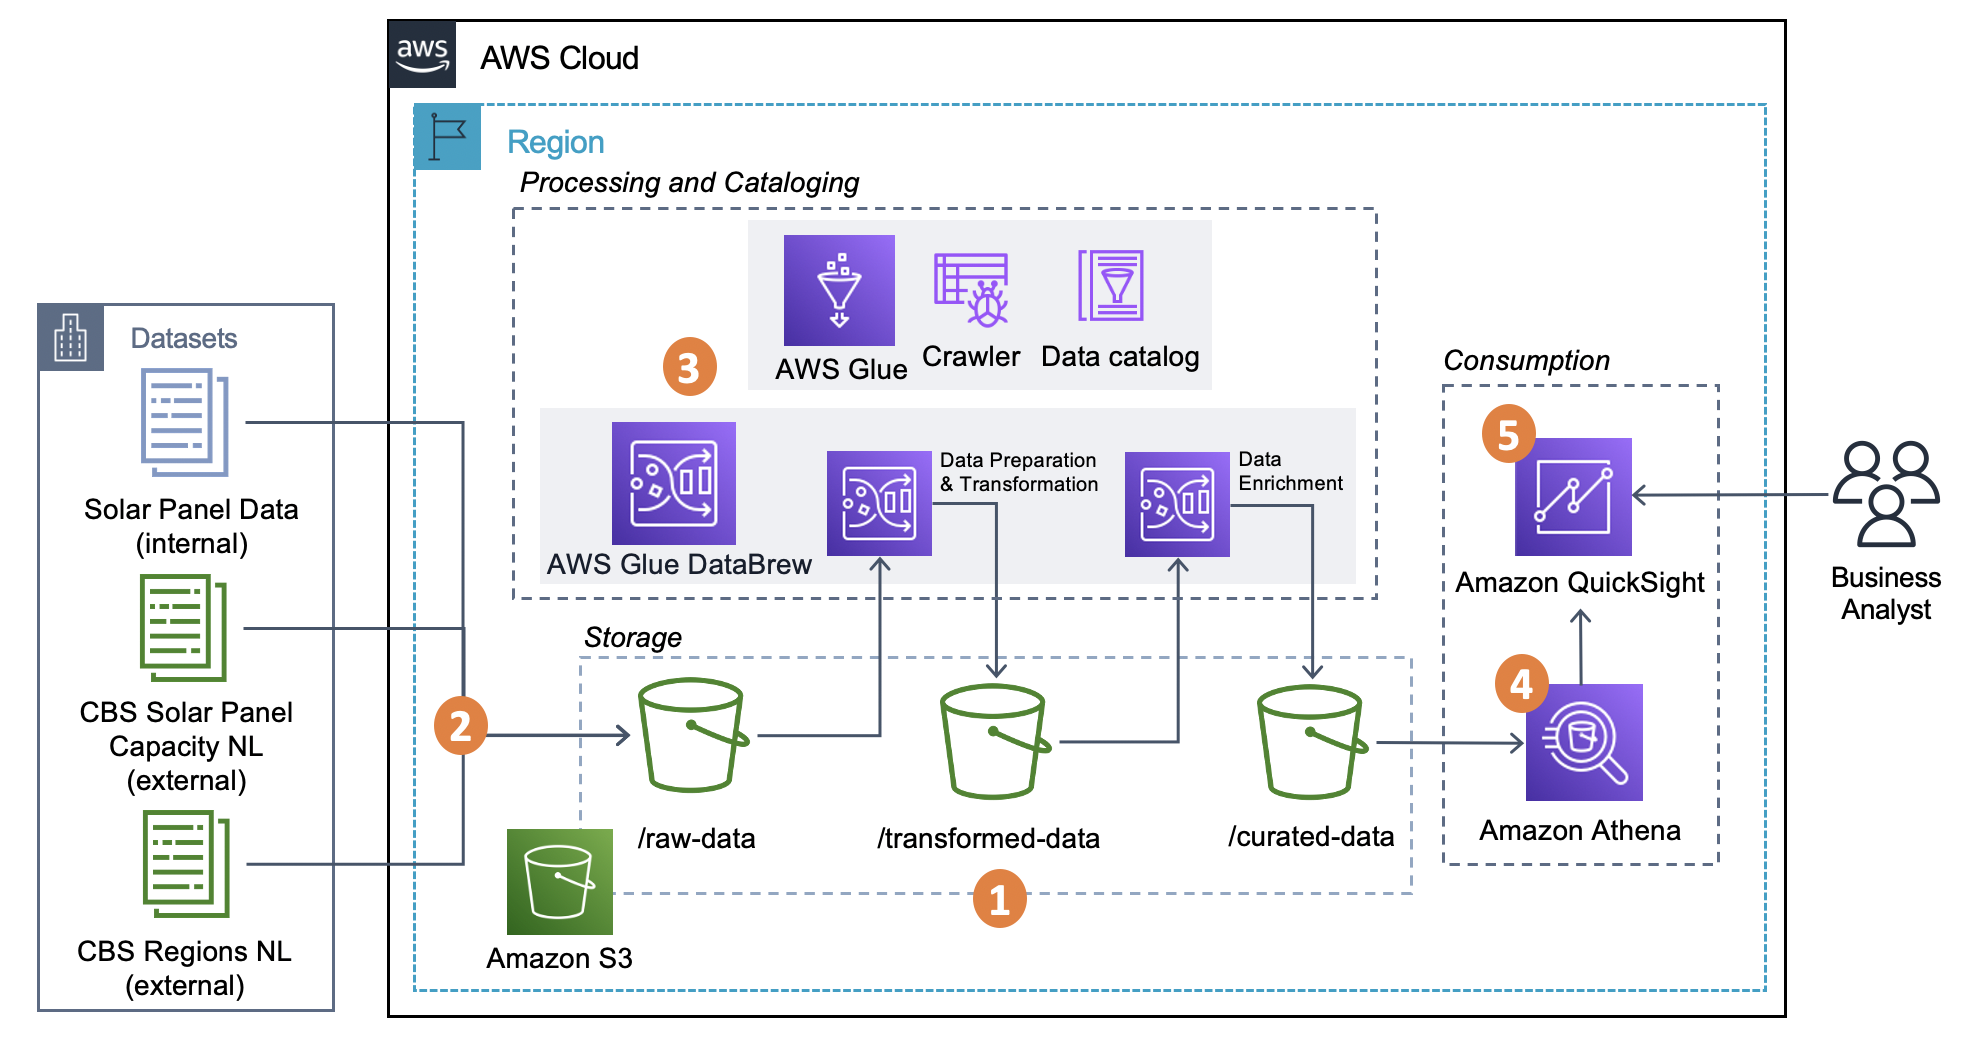
The answer contains the next steps:
- We arrange the storage layer utilizing Amazon S3 by creating the next folders:
raw-data,transformed-data, andcurated-data. We use these folders to trace the completely different phases of our information pipeline consumption readiness. - Three CSV uncooked information information containing unprocessed information of photo voltaic panels in addition to the exterior datasets from the CBS are ingested into the
raw-dataS3 folder. - This a part of the structure incorporates each processing and cataloging capabilities:
- We use AWS Glue crawlers to populate the preliminary schema definition tables for the uncooked dataset mechanically. For the remaining two phases of the info pipeline (
transformed-dataandcurated-data), we make the most of the performance in DataBrew to straight create schema definition tables into the Information Catalog. Every desk gives an up-to-date schema definition of the datasets we retailer on Amazon S3. - We work with DataBrew tasks because the centerpiece of our information evaluation and transformation efforts. In right here, we arrange no-code information preparation and transformation steps, and visualize them by way of a extremely interactive, intuitive consumer interface. Lastly, we outline DataBrew jobs to use these steps and retailer transformation outputs on Amazon S3.
- We use AWS Glue crawlers to populate the preliminary schema definition tables for the uncooked dataset mechanically. For the remaining two phases of the info pipeline (
- To achieve the advantages of granular entry management and simply visualize information from Amazon S3, we make the most of the seamless integration between Amazon Athena and Amazon QuickSight. This gives a SQL interface to question all the data we want from the curated dataset saved on Amazon S3 with out the necessity to create and preserve manifest information.
- Lastly, we assemble an interactive dashboard with QuickSight to depict the ultimate curated dataset alongside our two important KPIs.
Stipulations
Earlier than starting this tutorial, ensure you have the required Identification and Entry Administration (IAM) permissions to create the sources required as a part of the answer. Your AWS account also needs to have an lively subscription to QuickSight to create the visualization on processed information. For those who don’t have a QuickSight account, you’ll be able to join an account.
The next sections present a step-by-step information to create and deploy your complete information pipeline for OurCompany with out the usage of code.
Information preparation steps
We work with the next information:
- CBS Dutch municipalities and provinces (Gemeentelijke indeling op 1 januari 2021) – Holds all of the municipalities and provinces names and codes of the Netherlands. Obtain the file
gemeenten alfabetisch 2021. Open the file and reserve it ascbs_regions_nl.csv. Bear in mind to alter the format to CSV (comma-delimited). - CBS Solar energy dataset (Zonnestroom; vermogen bedrijven en woningen, regio, 2012-2018) – This file comprises the put in capability in kilowatts and complete variety of installations for companies and personal houses throughout the Netherlands from 2012–2018. To obtain the file, go to the dataset web page, select the
Onbewerkte dataset, and obtain the CSV file. Rename the file tocbs_sp_cap_nl.csv. - OurCompany’s photo voltaic panel historic information – Accommodates the reported vitality capability from all photo voltaic panel installations of OurCompany throughout the Netherlands from 2012 till 2018. Obtain the file.
Because of this, the next are the anticipated enter information we use to work with the info analytics pipeline:
cbs_regions_nl.csvcbs_sp_cap_nl.csvsp_data.csv
Arrange the storage Layer
We first must create the storage layer for our resolution to retailer all uncooked, reworked, and curated datasets. We use Amazon S3 because the storage layer of our whole information pipeline.
- Create an S3 bucket within the AWS Area the place you wish to construct this resolution. In our case, the bucket is known as
cbs-solar-panel-data. You should utilize the identical title adopted by a novel identifier.
- Create the next three prefixes (folders) in your S3 bucket by selecting Create folder:
curated-data/raw-data/transformed-data/

- Add the three uncooked information to the
raw-data/prefix. - Create two prefixes throughout the
transformed-data/prefix namedcbs_data/andsp_data/.
Create a Information Catalog database
After we arrange the storage layer of our information pipeline, we have to create the Information Catalog to retailer all of the metadata of the datasets hosted in Amazon S3. To take action, observe these steps:
- Open the AWS Glue console in the identical Area of your newly created S3 bucket.
- Within the navigation pane, select Databases.
- Select Add database.
- Enter the title for the Information Catalog to retailer all of the dataset’s metadata.
- Title the database
sp_catalog_db.
Create AWS Glue information crawlers
Now that we created the catalog database, it’s time to crawl the uncooked information prefix to mechanically retrieve the metadata related to every enter file.
- On the AWS Glue console, select Crawlers within the navigation pane.
- Add a crawler with the title
crawler_rawand select Subsequent. - For S3 path, choose the
raw-datafolder of thecbs-solar-panel-dataprefix.
- Create an IAM function and title it
AWSGlueServiceRole-cbsdata. - Depart the frequency as Run on demand.
- Select the
sp_catalog_dbdatabase created within the earlier part, and enter the prefixraw_to determine the tables that belong to the uncooked information folder. - Evaluation the parameters of the crawler after which select End.
- After the crawler is created, choose it and select Run crawler.
After profitable deployment of the crawler, your three tables are created within the sp_catalog_db database: raw_sp_data_csv, raw_cbs_regions_nl_csv, and raw_cbs_sp_cap_nl_csv.

Create DataBrew uncooked datasets
To make the most of the facility of DataBrew, we have to join datasets that time to the Information Catalog S3 tables we simply created. Comply with these steps to attach the datasets:
- On the DataBrew console, select Datasets within the navigation pane.
- Select Join new dataset.
- Title the dataset
cbs-sp-cap-nl-dataset. - For Hook up with new dataset, select Information Catalog S3 tables.
- Choose the
sp_catalog_dbdatabase and theraw_cbs_sp_cap_nl_csvdesk.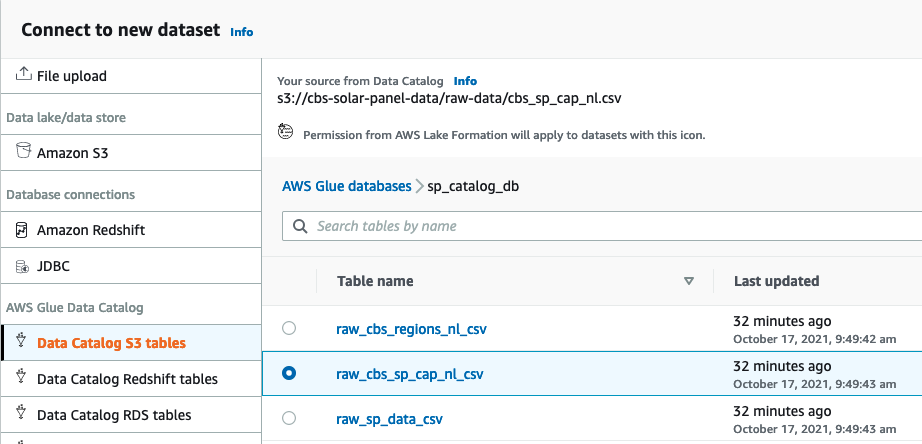
- Select Create dataset.
We have to create to 2 extra datasets following the identical course of. The next desk summarizes the names and tables of the catalog required for the brand new datasets.
| Dataset title | Information catalog desk |
sp-dataset |
raw_sp_data_csv |
cbs-regions-nl-dataset |
raw_cbs_regions_nl_csv |
Import DataBrew recipes
A recipe is a set of information transformation steps. These transformations are utilized to at least one or a number of datasets of your DataBrew challenge. For extra details about recipes, see Creating and utilizing AWS Glue DataBrew recipes.
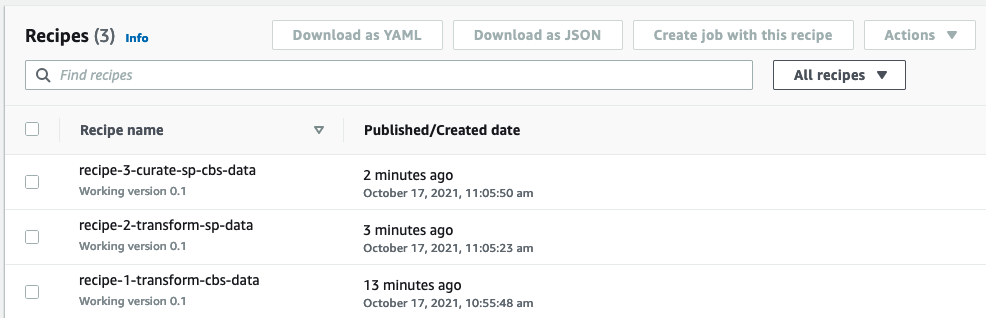
We’ve ready three DataBrew recipes, which comprise the set of information transformation steps we want for this information pipeline. A few of these transformation steps embrace: renaming columns (from Dutch to English), eradicating null or lacking values, aggregating rows primarily based on particular attributes, and mixing datasets within the transformation stage.
To import the recipes, observe these directions:
- On the DataBrew console, select Recipes within the navigation pane.
- Select Add recipe.
- Enter the title of the recipe:
recipe-1-transform-cbs-data. - Add the next JSON recipe.
- Select Create recipe.
Now we have to add two extra recipes that we use for transformation and aggregation tasks in DataBrew.
- Comply with the identical process to import the next recipes:
| Recipe title | Recipe supply file |
recipe-2-transform-sp-data |
Obtain |
recipe-3-curate-sp-cbs-data |
Obtain |
- Ensure that the recipes are listed within the Recipes part filtered by All recipes.
Arrange DataBrew tasks and jobs
After we efficiently create the Information Catalog database, crawlers, DataBrew datasets, and import the DataBrew recipes, we have to create the primary transformation challenge.
CBS exterior information transformation challenge
The primary challenge takes care of reworking, cleansing, and making ready cbs-sp-cap-nl-dataset. To create the challenge, observe these steps:
- On the DataBrew console, select Initiatives within the navigation pane.
- Create a brand new challenge with the title
1-transform-cbs-data. - Within the Recipe particulars part, select Edit present recipe and select the recipe
recipe-1-transform-cbs-data.
- Choose the newly created
cbs-sp-cap-nl-datasetunderneath Choose a dataset. - Within the Permissions part, select Create a brand new IAM function.
- As suffix, enter
sp-project. - Select Create challenge.
After you create the challenge, a preview dataset is displayed because of making use of the chosen recipe. If you select 10 extra recipe steps, the service exhibits your complete set of transformation steps.
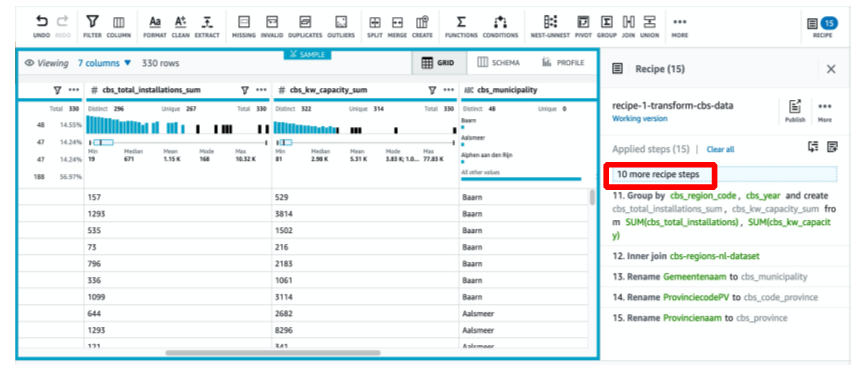
After you create the challenge, it is advisable to grant put and delete S3 object permissions to the created function AWSGlueDataBrewServiceRole-sp-project on IAM. Add an inline coverage utilizing the next JSON and change the useful resource together with your S3 bucket title:
This function additionally wants permissions to entry the Information Catalog. To grant these permissions, add the managed coverage AWSGlueServiceRole to the function.
CBS exterior information transformation job
After we outline the challenge, we have to configure and run a job to use the transformation throughout your complete uncooked dataset saved within the Uncooked-data folder of your S3 bucket. To take action, it is advisable to do the next:
- On the DataBrew challenge web page, select Create job.
- For Job title, enter
1-transform-cbs-data-job. - For Output to, select Information Catalog S3 tables.
- For File sort¸ select Parquet.
- For Database title, select
sp_catalog_db. - For Desk title, select Create new desk.
- For Catalog desk title, enter
transformed_cbs_data. - For S3 location, enter
s3://<your-S3-bucket-name>/transformed-data/cbs_data/.
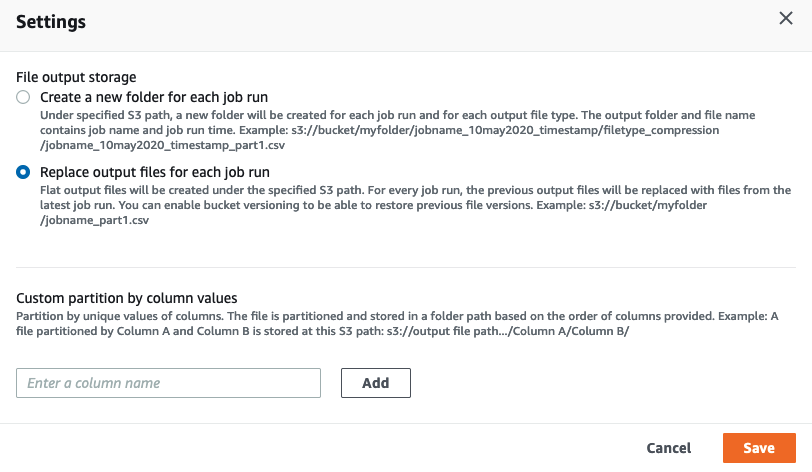
- Within the job output settings part, select Settings.
- Choose Change output information for every job run after which select Save.
- Within the permissions part, select the mechanically created function with the
sp-projectsuffix; for instance,AWSGlueDataBrewServiceRole-sp-project. - Evaluation the job particulars as soon as extra after which select Create and run job.
- Again in the principle challenge view, select Job particulars.
After a couple of minutes, the job standing adjustments from Working to Profitable. Select the output to go to the S3 location the place all of the generated Parquet information are saved.
Photo voltaic panels information transformation stage
We now create the second section of the info pipeline. We create a challenge and a job utilizing the identical process described within the earlier part.
- Create a DataBrew challenge with the next parameters:
- Mission title –
2-transform-sp-data - Imported recipe –
recipe-2-transform-sp-data - Dataset –
sp_dataset - Permissions function –
AWSGlueDataBrewServiceRole-sp-project
- Mission title –
- Create and run one other DataBrew job with the next parameters:
- Job title –
2-transform-sp-data-job - Output to – Information Catalog S3 tables
- File sort – Parquet
- Database title –
sp_catalog_db - Create new desk with desk title –
transformed_sp_data - S3 location –
s3://<your-S3-bucket-name>/transformed-data/sp_data/ - Settings – Change output information for every job run.
- Permissions function –
AWSGlueDataBrewServiceRole-sp-project
- Job title –
- After the job is full, create the DataBrew datasets with the next parameters:
| Dataset title | Information catalog desk |
transformed-cbs-dataset |
awsgluedatabrew_transformed_cbs_data |
transformed-sp-dataset |
awsgluedatabrew_transformed_sp_data |
You need to now see 5 gadgets as a part of your DataBrew dataset.

Information curation and aggregation stage
We now create the ultimate DataBrew challenge and job.
- Create a DataBrew challenge with the next parameters:
- Mission title –
3-curate-sp-cbs-data - Imported recipe –
recipe-3-curate-sp-cbs-data - Dataset –
transformed_sp_dataset - Permissions function –
AWSGlueDataBrewServiceRole-sp-project
- Mission title –
- Create a DataBrew job with the next parameters:
- Job title –
3-curate-sp-cbs-data-job - Output to – Information Catalog S3 tables
- File sort – Parquet
- Database title –
sp_catalog_db - Create new desk with desk title –
curated_data - S3 location –
s3://<your-S3-bucket-name>/curated-data/ - Settings – Change output information for every job run
- Permissions function –
AWSGlueDataBrewServiceRole-sp-project
- Job title –
The final challenge defines a single transformation step; the be part of between the transformed-cbs-dataset and the transformed-sp-dataset primarily based on the municipality code and the yr.
The DataBrew job ought to take a couple of minutes to finish.
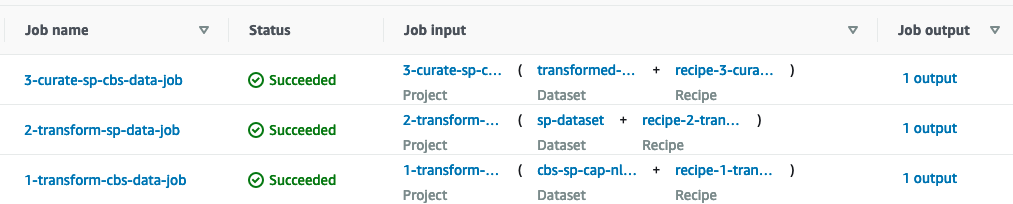
Subsequent, test your sp_catalog_db database. You need to now have uncooked, reworked, and curated tables in your database. DataBrew mechanically provides the prefix awsgluedatabrew_ to each the reworked and curated tables within the catalog.

Devour curated datasets for descriptive analytics
We’re now able to construct the consumption layer for descriptive analytics with QuickSight. On this part, we construct a enterprise intelligence dashboard that displays OurCompany’s photo voltaic panel vitality capability and installations participation in distinction to the reported values by the CBS from 2012–2018.
To finish this part, it is advisable to have the default main workgroup already arrange on Athena in the identical Area the place you applied the info pipeline. If it’s your first time organising workgroups on Athena, observe the directions in Establishing Workgroups.
Additionally guarantee that QuickSight has the proper permissions to entry Athena and your S3 bucket. Then full the next steps:
- On the QuickSight console, select Datasets within the navigation pane.
- Select Create a brand new dataset.
- Choose Athena as the info supply.
- For Information supply title, enter
sp_data_source. - Select Create information supply.

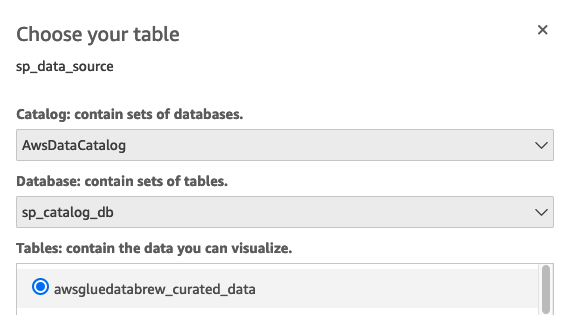
- Select
AWSDataCatalogbecause the catalog andsp_catalog_dbbecause the database. - Choose the desk
curated_data. - Select Choose.
- Within the End dataset creation part, select Instantly question your information and select Visualize.
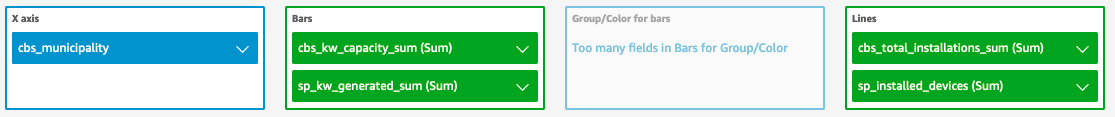
- Select the clustered bar combo chart from the Visible sorts listing.
- Broaden the discipline wells part after which drag and drop the next fields into every part as proven within the following screenshot.
- Rename the visualization as you want, and optionally filter the report by
sp_yearutilizing the Filter choice.
From this graph, we will already benchmark OurCompany in opposition to the regional values reported by the CBS throughout two dimensions: the entire quantity of installations and the entire kW capability generated by photo voltaic panels.
We went one step additional and created two KPI visualizations to empower our descriptive analytics capabilities. The next is our closing dashboard that we will use to reinforce our decision-making course of.

Clear up sources
To scrub all of the sources we created for the info pipeline, full the next steps:
- Take away the QuickSight analyses you created.
- Delete the dataset
curated_data. - Delete all of the DataBrew tasks with their related recipes.
- Delete all of the DataBrew datasets.
- Delete all of the AWS Glue crawlers you created.
- Delete the
sp_catalog_dbcatalog database; this removes all of the tables. - Empty the contents of your S3 bucket and delete it.
Conclusion
On this put up, we demonstrated how one can start your information analytics journey. With DataBrew, you’ll be able to put together and mix the info you have already got with publicly accessible datasets similar to these from the Dutch CBS (Centraal Bureau voor de Statistiek) without having to put in writing a single line of code. Begin utilizing DataBrew as we speak and enrich key datasets in AWS for enhanced descriptive analytics capabilities.
Concerning the Authors
 Daniel Rozo is a Options Architect with Amazon Internet Providers primarily based out of Amsterdam, The Netherlands. He’s dedicated to working with clients and engineering easy information and analytics options on AWS. In his free time, he enjoys taking part in tennis and taking excursions across the lovely Dutch canals.
 Maurits de Groot is an intern Options Architect at Amazon Internet Providers. He does analysis on startups with a concentrate on FinTech. In addition to working, Maurits enjoys snowboarding and taking part in squash.
Phrases of use: Gemeentelijke indeling op 1 januari 2021, Zonnestroom; vermogen bedrijven en woningen, regio (indeling 2018), 2012-2018, and copies of those datasets redistributed by AWS, are licensed underneath the Artistic Commons 4.0 license (CC BY 4.0), sourced from Centraal Bureau voor de Statistiek (CBS). The datasets used on this resolution are modified to rename columns from Dutch to English, take away null or lacking values, combination rows primarily based on particular attributes, and mix the datasets within the closing transformation. Check with the CC BY 4.0 use, adaptation, and attribution necessities for extra data.
[ad_2]

