


[ad_1]
Editor’s observe: As 2021 winds down, we’re celebrating with a 12 Days of Christmas Countdown of the preferred, useful knowledgeable articles on Search Engine Journal this 12 months.
This assortment was curated by our editorial workforce primarily based on every article’s efficiency, utility, high quality, and the worth created for you, our readers.
Every day till December twenty fourth, we’ll repost the most effective columns of the 12 months, beginning at No. 12 and counting right down to No. 1. Our countdown begins at present with our No. 3 column, which was initially revealed on March 18, 2021.
Ruth Everett’s article on using Python libraries for automating and conducting search engine optimisation duties makes a marketer’s work a lot simpler. It’s very simple to learn and excellent for novices and much more skilled search engine optimisation professionals that wish to use Python extra.
Nice work on this, Ruth, and we actually admire your contributions to Search Engine Journal.
Get pleasure from!
Python libraries are a enjoyable and accessible solution to get began with studying and utilizing Python for search engine optimisation.
Commercial
Proceed Studying Under
A Python library is a group of helpful features and code that let you full a variety of duties while not having to put in writing the code from scratch.
There are over 100,000 libraries out there to make use of in Python, which can be utilized for features from information evaluation to creating video video games.
On this article, you’ll discover a number of completely different libraries I’ve used for finishing search engine optimisation initiatives and duties. All of them are beginner-friendly and also you’ll discover loads of documentation and assets that can assist you get began.
Why Are Python Libraries Helpful For search engine optimisation?
Every Python library comprises features and variables of every kind (arrays, dictionaries, objects, and many others.) which can be utilized to carry out completely different duties.
For search engine optimisation, for instance, they can be utilized to automate sure issues, predict outcomes, and supply clever insights.
It’s potential to work with simply vanilla Python, however libraries may be used to make duties a lot simpler and faster to put in writing and full.
Python Libraries For search engine optimisation Duties
There are a selection of helpful Python libraries for search engine optimisation duties together with information evaluation, internet scraping, and visualizing insights.
Commercial
Proceed Studying Under
This isn’t an exhaustive checklist, however these are the libraries I discover myself utilizing probably the most for search engine optimisation functions.
Pandas
Pandas is a Python library used for working with desk information. It permits for high-level information manipulation the place the important thing information construction is a DataFrame.
DataFrames are much like Excel spreadsheets, nonetheless, they aren’t restricted to row and byte limits and are additionally a lot quicker and extra environment friendly.
One of the simplest ways to get began with Pandas is to take a easy CSV of information (a crawl of your web site, for instance) and save this inside Python as a DataFrame.
After you have this saved in Python, you possibly can carry out a variety of completely different evaluation duties together with aggregating, pivoting, and cleansing information.
For instance, if I’ve an entire crawl of my web site and wish to extract solely these pages which are indexable, I’ll use a built-in Pandas perform to incorporate solely these URLs in my DataFrame.
import pandas as pd
df = pd.read_csv('/Customers/rutheverett/Paperwork/Folder/file_name.csv')
df.head
indexable = df[(df.indexable == True)]
indexable
Requests
The subsequent library is named Requests and is used to make HTTP requests in Python.
Requests makes use of completely different request strategies reminiscent of GET and POST to make a request, with the outcomes being saved in Python.
One instance of this in motion is an easy GET request of URL, this can print out the standing code of a web page:
import requests
response = requests.get('https://www.deepcrawl.com') print(response)
You’ll be able to then use this consequence to create a decision-making perform, the place a 200 standing code means the web page is offered however a 404 means the web page shouldn’t be discovered.
if response.status_code == 200:
    print('Success!')
elif response.status_code == 404:
    print('Not Discovered.')
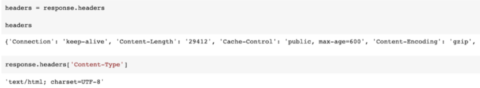
You may as well use completely different requests reminiscent of headers, which show helpful details about the web page just like the content material kind or how lengthy it took to cache the response.
headers = response.headers
print(headers)

response.headers['Content-Type']
There may be additionally the power to simulate a selected consumer agent, reminiscent of Googlebot, so as to extract the response this particular bot will see when crawling the web page.
headers = {'Consumer-Agent': 'Mozilla/5.0 (appropriate; Googlebot/2.1; +http://www.google.com/bot.html)'} ua_response = requests.get('https://www.deepcrawl.com/', headers=headers) print(ua_response)
Lovely Soup
Lovely Soup is a library used to extract information from HTML and XML information.
Commercial
Proceed Studying Under
Enjoyable truth: The BeautifulSoup library was really named after the poem from Alice’s Adventures in Wonderland by Lewis Carroll.
As a library, BeautifulSoup is used to make sense of internet information and is most frequently used for internet scraping, as it will probably rework an HTML doc into completely different Python objects.
For instance, you possibly can take a URL and use Lovely Soup along with the Requests library to extract the title of the web page.
from bs4 import BeautifulSoup
import requests
url="https://www.deepcrawl.com"
req = requests.get(url)
soup = BeautifulSoup(req.textual content, "html.parser")
title = soup.title print(title)

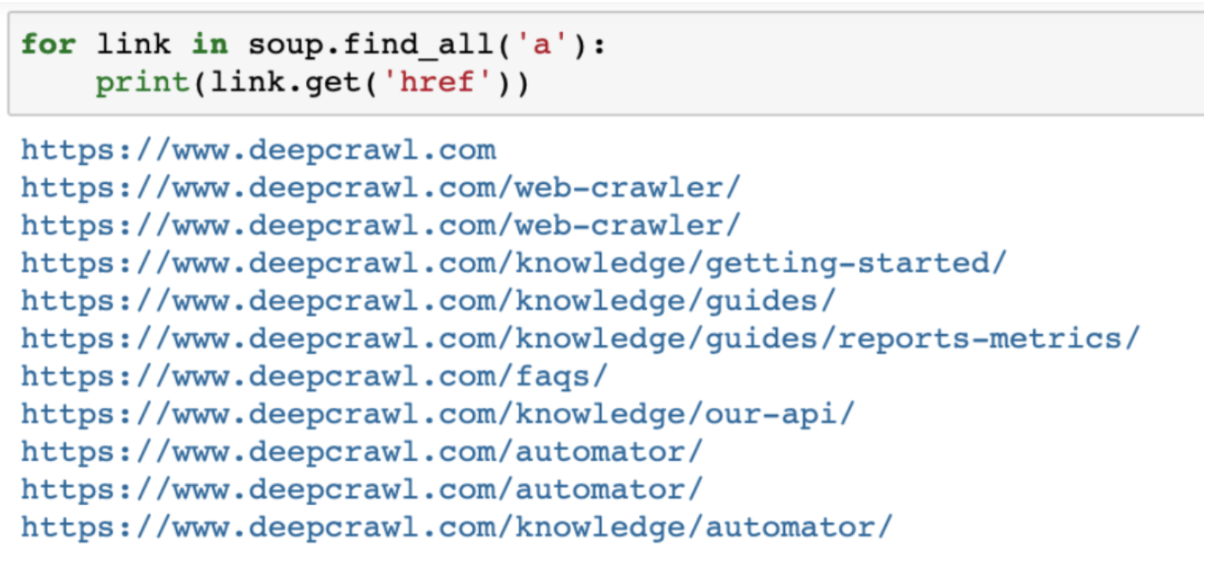
Moreover, utilizing the find_all methodology, BeautifulSoup lets you extract sure components from a web page, reminiscent of all a href hyperlinks on the web page:
Commercial
Proceed Studying Under
url="https://www.deepcrawl.com/data/technical-seo-library/"
req = requests.get(url)
soup = BeautifulSoup(req.textual content, "html.parser")

for hyperlink in soup.find_all('a'):
    print(hyperlink.get('href'))
Placing Them Collectively
These three libraries can be used collectively, with Requests used to make the HTTP request to the web page we wish to use BeautifulSoup to extract data from.
We will then rework that uncooked information right into a Pandas DataFrame to carry out additional evaluation.
URL = 'https://www.deepcrawl.com/weblog/'
req = requests.get(url)
soup = BeautifulSoup(req.textual content, "html.parser")

hyperlinks = soup.find_all('a')

df = pd.DataFrame({'hyperlinks':hyperlinks})
df
Matplotlib And Seaborn
Matplotlib and Seaborn are two Python libraries used for creating visualizations.
Matplotlib lets you create a variety of completely different information visualizations reminiscent of bar charts, line graphs, histograms, and even heatmaps.
Commercial
Proceed Studying Under
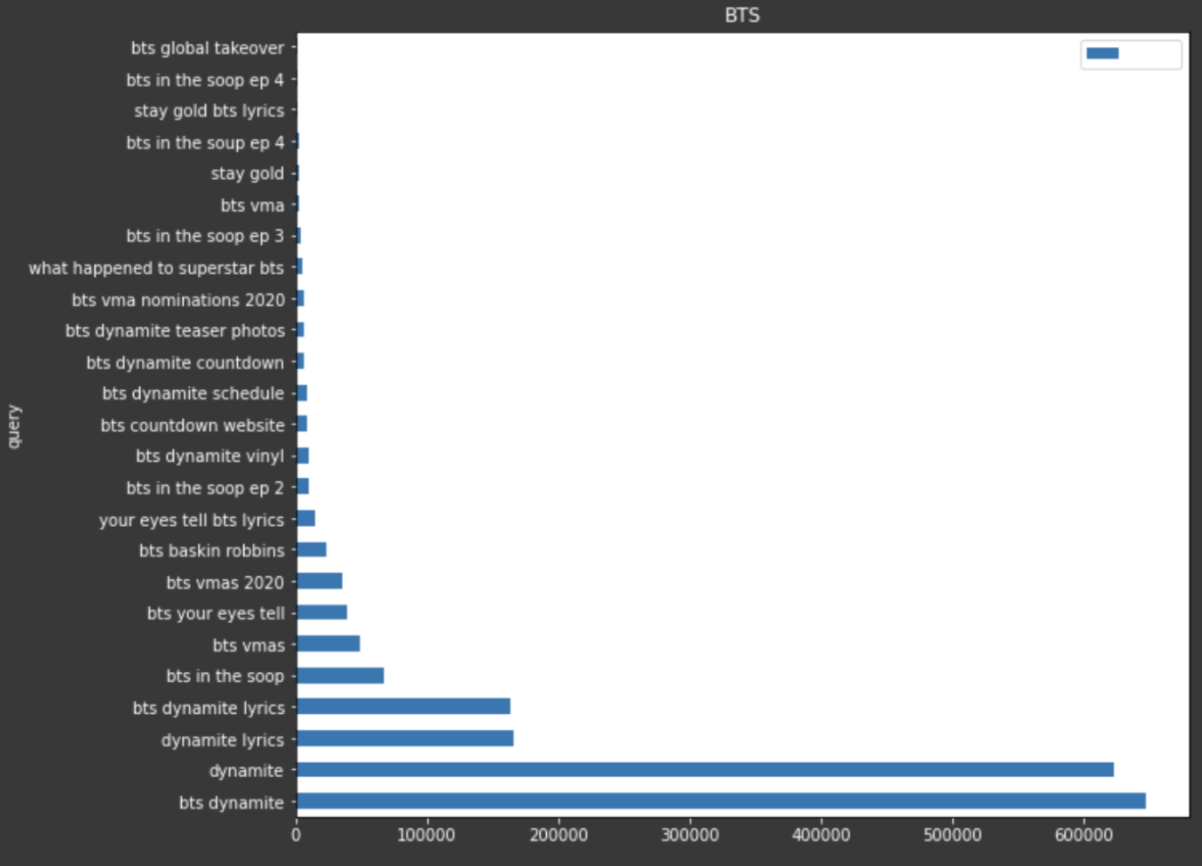
For instance, if I wished to take some Google Developments information to show the queries with probably the most reputation over a interval of 30 days, I may create a bar chart in Matplotlib to visualise all of those.
Seaborn, which is constructed upon Matplotlib, gives much more visualization patterns reminiscent of scatterplots, field plots, and violin plots along with line and bar graphs.
It differs barely from Matplotlib because it makes use of fewer syntax and has built-in default themes.
Commercial
Proceed Studying Under
A technique I’ve used Seaborn is to create line graphs so as to visualize log file hits to sure segments of a web site over time.
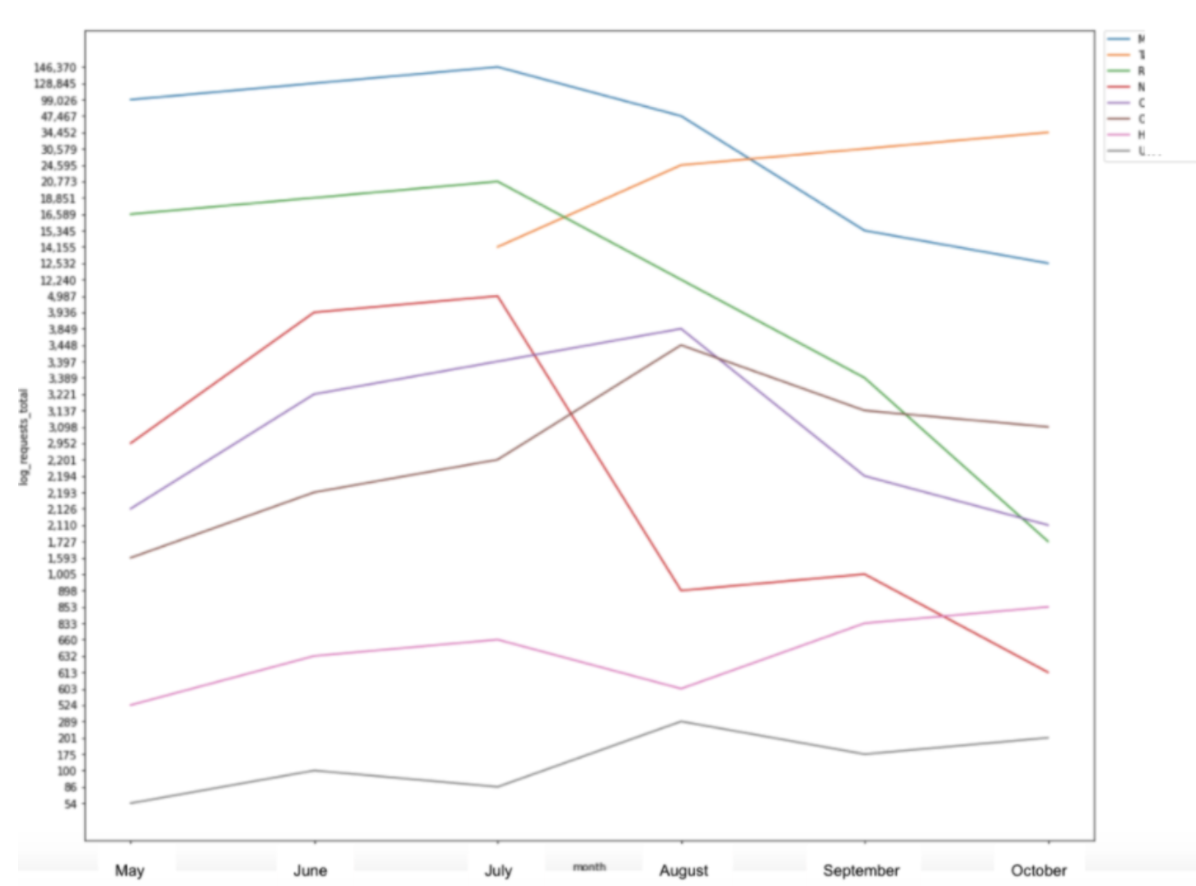
sns.lineplot(x = "month", y = "log_requests_total", hue="class", information=pivot_status)
plt.present()
This specific instance takes information from a pivot desk, which I used to be in a position to create in Python utilizing the Pandas library, and is one other method these libraries work collectively to create an easy-to-understand image from the information.
Advertools
Advertools is a library created by Elias Dabbas that can be utilized to assist handle, perceive, and make choices primarily based on the information we’ve got as search engine optimisation professionals and digital entrepreneurs.
Commercial
Proceed Studying Under
Sitemap Evaluation
This library lets you carry out a variety of completely different duties reminiscent of downloading, parsing, and analyzing XML Sitemaps to extract patterns or analyze how typically content material is added or modified.
Robots.txt Evaluation
One other attention-grabbing factor you are able to do with this library is to make use of a perform to extract a web site’s robots.txt right into a DataFrame, so as to simply perceive and analyze the principles set.
You may as well run a take a look at throughout the library so as to test whether or not a specific user-agent is ready to fetch sure URLs or folder paths.
URL Evaluation
Advertools additionally lets you parse and analyze URLs so as to extract data and higher perceive analytics, SERP, and crawl information for sure units of URLs.
You may as well break up URLs utilizing the library to find out issues such because the HTTP scheme getting used, the principle path, further parameters, and question strings.
Selenium
Selenium is a Python library that’s usually used for automation functions. The commonest use case is testing internet functions.
Commercial
Proceed Studying Under
One in style instance of Selenium automating a circulation is a script that opens a browser and performs a variety of completely different steps in an outlined sequence reminiscent of filling in varieties or clicking sure buttons.
Selenium employs the identical precept as is used within the Requests library that we coated earlier.
Nevertheless, it won’t solely ship the request and anticipate the response but in addition render the webpage that’s being requested.
To get began with Selenium, you’ll need a WebDriver so as to make the interactions with the browser.
Every browser has its personal WebDriver; Chrome has ChromeDriver and Firefox has GeckoDriver, for instance.
These are simple to obtain and arrange along with your Python code. Here’s a helpful article explaining the setup course of, with an instance venture.
Scrapy
The ultimate library I wished to cowl on this article is Scrapy.
Whereas we will use the Requests module to crawl and extract inner information from a webpage, so as to move that information and extract helpful insights we additionally want to mix it with BeautifulSoup.
Commercial
Proceed Studying Under
Scrapy primarily lets you do each of those in a single library.
Scrapy can be significantly quicker and extra highly effective, completes requests to crawl, extracts and parses information in a set sequence, and lets you protect the information.
Inside Scrapy, you possibly can outline a variety of directions such because the title of the area you wish to crawl, the beginning URL, and sure web page folders the spider is allowed or not allowed to crawl.
Scrapy can be utilized to extract all the hyperlinks on a sure web page and retailer them in an output file, for instance.
class SuperSpider(CrawlSpider):
   title="extractor"
   allowed_domains = ['www.deepcrawl.com']
   start_urls = ['https://www.deepcrawl.com/knowledge/technical-seo-library/']
   base_url="https://www.deepcrawl.com"
   def parse(self, response):
       for hyperlink in response.xpath('//div/p/a'):
           yield {
               "hyperlink": self.base_url + hyperlink.xpath('.//@href').get()
           }
You’ll be able to take this one step additional and comply with the hyperlinks discovered on a webpage to extract data from all of the pages that are being linked to from the beginning URL, sort of like a small-scale replication of Google discovering and following hyperlinks on a web page.
from scrapy.spiders import CrawlSpider, Rule


class SuperSpider(CrawlSpider):
    title="follower"
    allowed_domains = ['en.wikipedia.org']
    start_urls = ['https://en.wikipedia.org/wiki/Web_scraping']
    base_url="https://en.wikipedia.org"

    custom_settings = {
        'DEPTH_LIMIT': 1
    }

    def parse(self, response):
        for next_page in response.xpath('.//div/p/a'):
            yield response.comply with(next_page, self.parse)

        for quote in response.xpath('.//h1/textual content()'):
            yield {'quote': quote.extract() }
Study extra about these initiatives, amongst different instance initiatives, right here.
Last Ideas
As Hamlet Batista at all times stated, “one of the simplest ways to study is by doing.”
Commercial
Proceed Studying Under
I hope that discovering a few of the libraries out there has impressed you to get began with studying Python, or to deepen your data.
Python Contributions From The search engine optimisation Business
Hamlet additionally beloved sharing assets and initiatives from these within the Python search engine optimisation group. To honor his ardour for encouraging others, I wished to share a few of the superb issues I’ve seen from the group.
As a beautiful tribute to Hamlet and the search engine optimisation Python group he helped to domesticate, Charly Wargnier has created search engine optimisation Pythonistas to gather contributions of the superb Python initiatives these within the search engine optimisation group have created.
Hamlet’s priceless contributions to the search engine optimisation Neighborhood are featured.
Moshe Ma-yafit created a brilliant cool script for log file evaluation, and on this publish explains how the script works. The visualizations it is ready to show together with Google Bot Hits By System, Every day Hits by Response Code, Response Code % Whole, and extra.
Koray Tuğberk GÜBÜR is at present engaged on a Sitemap Well being Checker. He additionally hosted a RankSense webinar with Elias Dabbas the place he shared a script that information SERPs and Analyses Algorithms.
Commercial
Proceed Studying Under
It primarily information SERPs with common time variations, and you may crawl all of the touchdown pages, mix information and create some correlations.
John McAlpin wrote an article detailing how you need to use Python and Knowledge Studio to spy in your opponents.
JC Chouinard wrote a full information to utilizing the Reddit API. With this, you possibly can carry out issues reminiscent of extracting information from Reddit and posting to a Subreddit.
Rob Could is engaged on a brand new GSC evaluation software and constructing just a few new area/actual websites in Wix to measure in opposition to its higher-end WordPress competitor whereas documenting it.
Masaki Okazawa additionally shared a script that analyzes Google Search Console Knowledge with Python.
🎉 Comfortable #RSTwittorial Thursday with @saksters 🥳
Analyzing Google Search Console Knowledge with #Python 🐍🔥
Right here’s the output 👇 pic.twitter.com/9l5Xc6UsmT
— RankSense (@RankSense) February 25, 2021
2021 SEJ Christmas Countdown:
Commercial
Proceed Studying Under
Featured picture: jakkaje879/Shutterstock
[ad_2]

