



[ad_1]
In recent times, pure language processing fashions have dramatically improved their potential to study general-purpose representations, which has resulted in important efficiency beneficial properties for a variety of pure language technology and pure language understanding duties. Largely, this has been achieved by way of pre-training language fashions on in depth unlabeled textual content corpora.
This pre-training formulation doesn’t make assumptions about enter sign modality, which will be language, imaginative and prescient, or audio, amongst others. A number of current papers have exploited this formulation to dramatically enhance picture technology outcomes by way of pre-quantizing photos into discrete integer codes (represented as pure numbers), and modeling them autoregressively (i.e., predicting sequences one token at a time). In these approaches, a convolutional neural community (CNN) is educated to encode a picture into discrete tokens, every similar to a small patch of the picture. A second stage CNN or Transformer is then educated to mannequin the distribution of encoded latent variables. The second stage can be utilized to autoregressively generate a picture after the coaching. However whereas such fashions have achieved robust efficiency for picture technology, few research have evaluated the discovered illustration for downstream discriminative duties (corresponding to picture classification).
In “Vector-Quantized Picture Modeling with Improved VQGAN”, we suggest a two-stage mannequin that reconceives conventional picture quantization strategies to yield improved efficiency on picture technology and picture understanding duties. Within the first stage, a picture quantization mannequin, known as VQGAN, encodes a picture into lower-dimensional discrete latent codes. Then a Transformer mannequin is educated to mannequin the quantized latent codes of a picture. This strategy, which we name Vector-quantized Picture Modeling (VIM), can be utilized for each picture technology and unsupervised picture illustration studying. We describe a number of enhancements to the picture quantizer and present that coaching a stronger picture quantizer is a key element for enhancing each picture technology and picture understanding.
Vector-Quantized Picture Modeling with ViT-VQGAN
One current, generally used mannequin that quantizes photos into integer tokens is the Vector-quantized Variational AutoEncoder (VQVAE), a CNN-based auto-encoder whose latent area is a matrix of discrete learnable variables, educated end-to-end. VQGAN is an improved model of this that introduces an adversarial loss to advertise top quality reconstruction. VQGAN makes use of transformer-like parts within the type of non-local consideration blocks, which permits it to seize distant interactions utilizing fewer layers.
In our work, we suggest taking this strategy one step additional by changing each the CNN encoder and decoder with ViT. As well as, we introduce a linear projection from the output of the encoder to a low-dimensional latent variable area for lookup of the integer tokens. Particularly, we diminished the encoder output from a 768-dimension vector to a 32- or 8-dimension vector per code, which we discovered encourages the decoder to raised make the most of the token outputs, enhancing mannequin capability and effectivity.
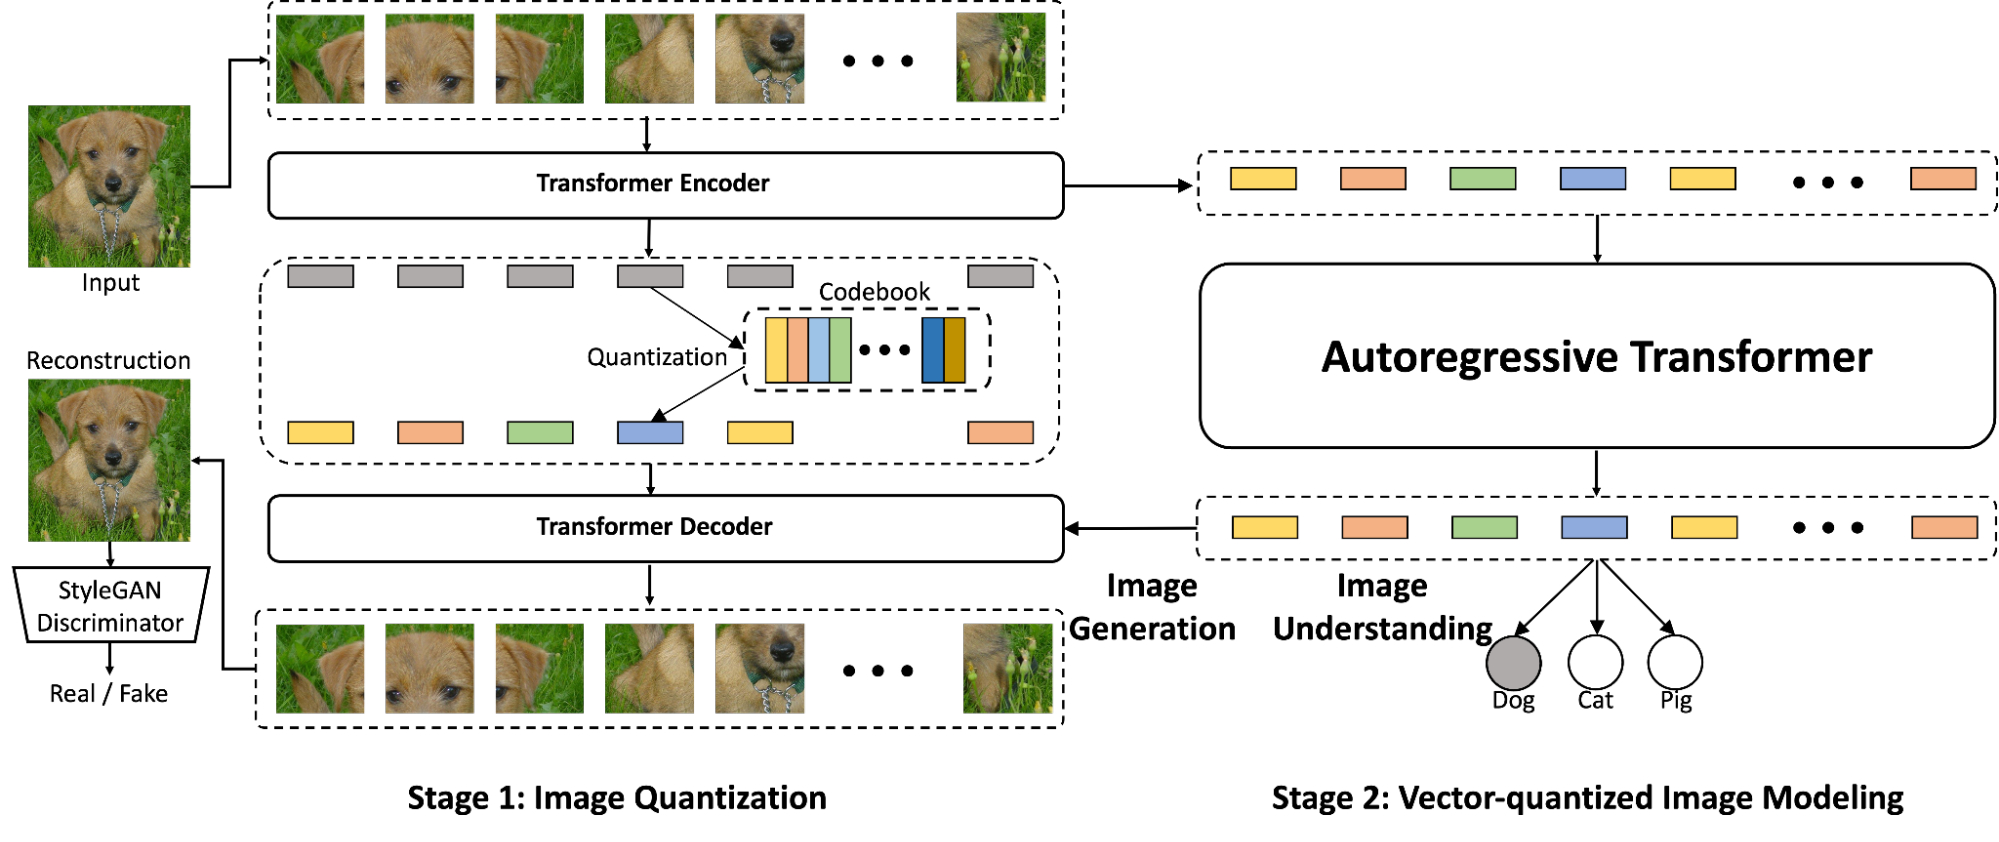 |
| Overview of the proposed ViT-VQGAN (left) and VIM (proper), which, when working collectively, is able to each picture technology and picture understanding. Within the first stage, ViT-VQGAN converts photos into discrete integers, which the autoregressive Transformer (Stage 2) then learns to mannequin. Lastly, the Stage 1 decoder is utilized to those tokens to allow technology of top quality photos from scratch. |
With our educated ViT-VQGAN, photos are encoded into discrete tokens represented by integers, every of which encompasses an 8×8 patch of the enter picture. Utilizing these tokens, we prepare a decoder-only Transformer to foretell a sequence of picture tokens autoregressively. This two-stage mannequin, VIM, is ready to carry out unconditioned picture technology by merely sampling token-by-token from the output softmax distribution of the Transformer mannequin.
VIM can be able to performing class-conditioned technology, corresponding to synthesizing a particular picture of a given class (e.g., a canine or a cat). We lengthen the unconditional technology to class-conditioned technology by prepending a class-ID token earlier than the picture tokens throughout each coaching and sampling.
 |
| Uncurated set of canine samples from class-conditioned picture technology educated on ImageNet. Conditioned lessons: Irish terrier, Norfolk terrier, Norwich terrier, Yorkshire terrier, wire-haired fox terrier, Lakeland terrier. |
To check the picture understanding capabilities of VIM, we additionally fine-tune a linear projection layer to carry out ImageNet classification, a typical benchmark for measuring picture understanding talents. Just like ImageGPT, we take a layer output at a particular block, common over the sequence of token options (frozen) and insert a softmax layer (learnable) projecting averaged options to class logits. This permits us to seize intermediate options that present extra info helpful for illustration studying.
Experimental Outcomes
We prepare all ViT-VQGAN fashions with a coaching batch measurement of 256 distributed throughout 128 CloudTPUv4 cores. All fashions are educated with an enter picture decision of 256×256. On high of the pre-learned ViT-VQGAN picture quantizer, we prepare Transformer fashions for unconditional and class-conditioned picture synthesis and evaluate with earlier work.
We measure the efficiency of our proposed strategies for class-conditioned picture synthesis and unsupervised illustration studying on the extensively used ImageNet benchmark. Within the desk under we display the class-conditioned picture synthesis efficiency measured by the Fréchet Inception Distance (FID). In comparison with prior work, VIM improves the FID to three.07 (decrease is healthier), a relative enchancment of 58.6% over the VQGAN mannequin (FID 7.35). VIM additionally improves the capability for picture understanding, as indicated by the Inception Rating (IS), which matches from 188.6 to 227.4, a 20.6% enchancment relative to VQGAN.
| Fréchet Inception Distance (FID) comparability between totally different fashions for class-conditional picture synthesis and Inception Rating (IS) for picture understanding, each on ImageNet with decision 256×256. The acceptance charge reveals outcomes filtered by a ResNet-101 classification mannequin, just like the method in VQGAN. | ||||
After coaching a generative mannequin, we take a look at the discovered picture representations by fine-tuning a linear layer to carry out ImageNet classification, a typical benchmark for measuring picture understanding talents. Our mannequin outperforms earlier generative fashions on the picture understanding job, enhancing classification accuracy by way of linear probing (i.e., coaching a single linear classification layer, whereas holding the remainder of the mannequin frozen) from 60.3% (iGPT-L) to 73.2%. These outcomes showcase VIM’s robust technology outcomes in addition to picture illustration studying talents.
Conclusion
We suggest Vector-quantized Picture Modeling (VIM), which pretrains a Transformer to foretell picture tokens autoregressively, the place discrete picture tokens are produced from improved ViT-VQGAN picture quantizers. With our proposed enhancements on picture quantization, we display superior outcomes on each picture technology and understanding. We hope our outcomes can encourage future work in the direction of extra unified approaches for picture technology and understanding.
Acknowledgements
We want to thank Xin Li, Han Zhang, Ruoming Pang, James Qin, Alexander Ku, Yuanzhong Xu, Jason Baldridge, Yonghui Wu for the preparation of the VIM paper. We thank Wei Han, Yuan Cao, Jiquan Ngiam, Vijay Vasudevan, Zhifeng Chen and Claire Cui for useful discussions and suggestions, and others on the Google Analysis and Mind Workforce for assist all through this mission.
[ad_2]

