


[ad_1]
As outlined in my first weblog, there’s a paradigm shift in direction of heterogeneous computing. Key drivers being emergence of latest workloads within the AI/ML area requiring better of breed {hardware} and software program framework. Whereas we’re going to concentrate on system structure tendencies and necessities driving the necessity of heterogenous compute, it’s value noting that on the software program aspect related development is occurring. Plethora of code bases from x86/ARM/MIPS/RISCV, system and performance libraries, embedded Kernels, deep studying body works equivalent to Caffe, TensorFlow, PyTorch dominate a software program platform to optimize the execution time.
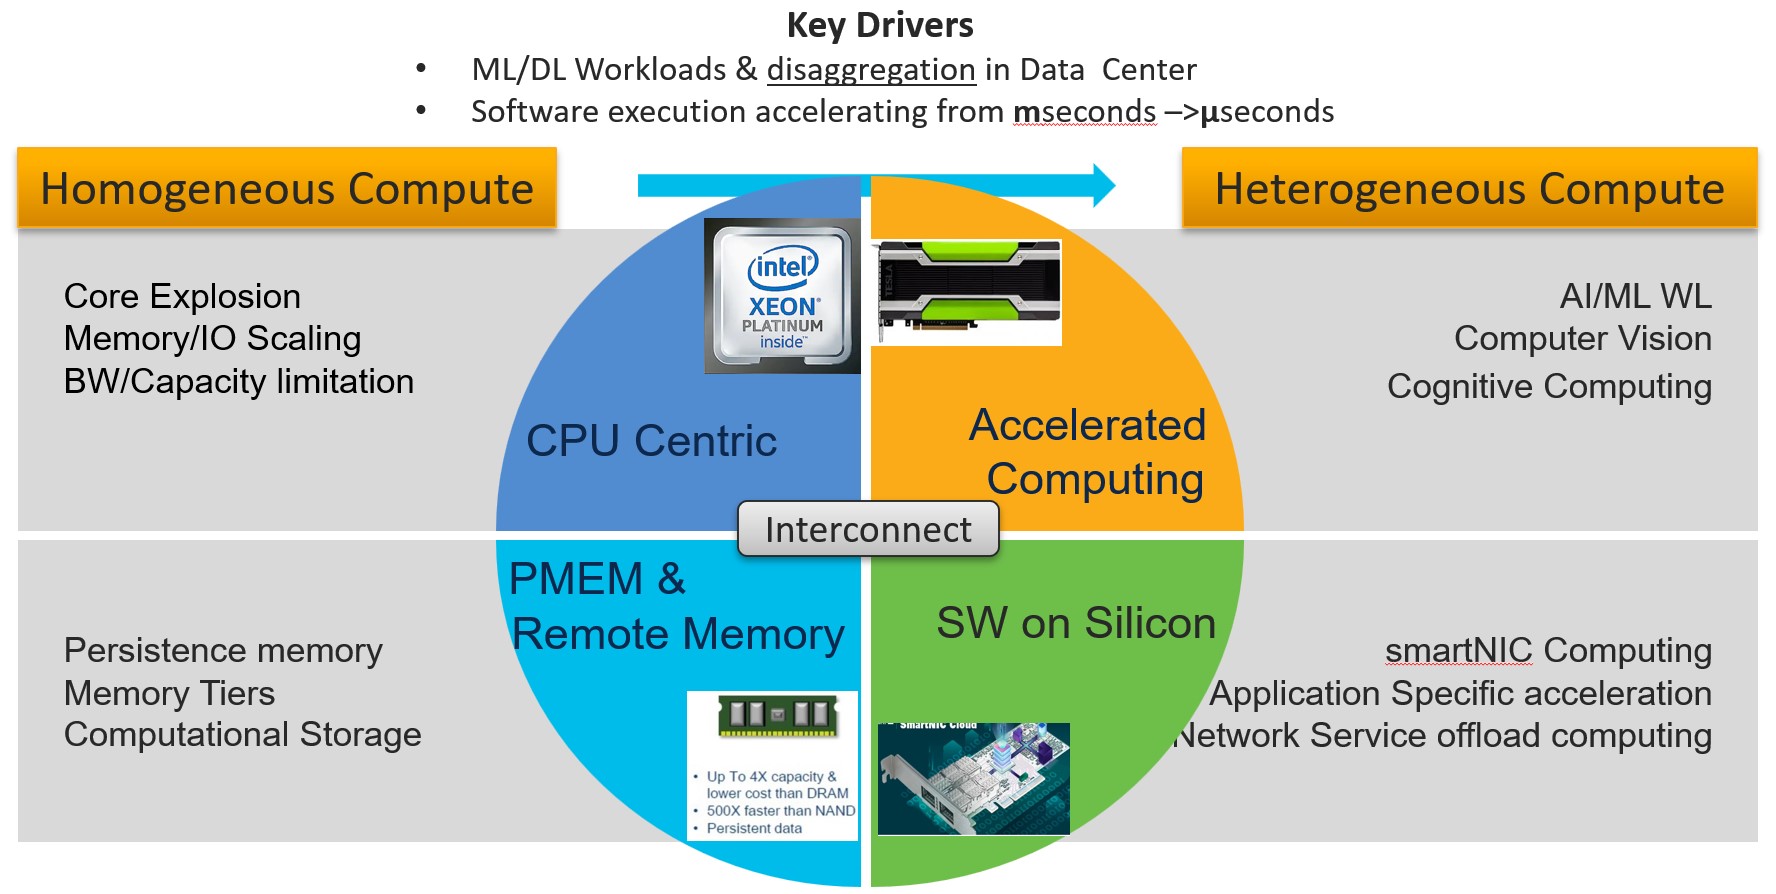
Heterogeneous computing brings the problem of composability facets of assets and IO interconnect that ties all these assets collectively. These assets can vary from accelerated compute farms with specialised GPUs, sNIC computing subsystems and information processing on the fringe of, or close to storage – AKA computational storage. This compute all over the place mannequin if not deliberate correctly can lead to wasted and replicated assets.
Entry stage value of accelerated computing equivalent to GPU may be very costly. So, it’s important from TCO perspective to have assets that may be virtualized, composed and shared on demand. In essence new server structure needs to be dynamic and versatile the place there are not any captive assets & have skill to allow time shifted computing using assets 24/7.
Moreover, peer to look communication between assets for information motion bypasses central CPU eliminating want for redundant information copying . It helps in discount of IO visitors on system bus and improves latency.
So, What IO material will tie heterogeneous subsystems collectively? A Single IO material method could not have the ability to cater to the divergent wants off information middle. A multi-fabric structure method is crucial.
Want for subsequent Era Interconnect
Ethernet is de-facto material within the information middle for information ingestion into server from protocol conscious IO/Storage visitors perspective. Nevertheless, latency and coherency points make it a poor selection at lowest tiers of Load/Retailer IO which often occurs in 10s of nS.
As a way to absolutely notice the potential of heterogeneous computing new IO material should have
- Load/Retailer semantics assuaging want for software program stack overhead in information switch
- Want for decrease latency & excessive bandwidth -32/64/128Gbps and past.
- Peer-peer communication, and coherency
- Seamless failover of assets on the part stage – Reminiscence and/or @subsystem stage
- For instance Community -NIC failover,
- True material stage command construction for disaggregation
Whereas PCIe IO know-how crammed the latency wants early on, it was sluggish to evolve from speeds and have perspective as core explosion led to IO bandwidth points. A number of proprietary and open-source efforts had been made to create a brand new IO interconnect. Nevertheless, none of them discovered traction at scale till the emergence of CXL (Compute Specific Hyperlink) Interconnect. Whereas excessive bandwidth & Lo latency is paramount, it’s the underlying protocol stack that wanted overhaul for OS and functions to take benefit. CXL is based mostly on the ever present PCIe PHY layer and provides a environment friendly protocol stack that has a possible to allow subsystem and part stage disaggregation within the information middle.
Reminiscence Bandwidth (BW)
Maybe largest affect on IO interconnect is coming as a result of challenges in scaling reminiscence bandwidth as core rely will increase.
The quantity of cores in processor is quadrupling from 32 to 128 and past in subsequent couple of years. Nevertheless, no of reminiscence channels & bandwidth will scale @1.5 -2 x inflicting mismatch within the bandwidth per core. As core rely grows past 128, incremental adjustments in reminiscence channel velocity is not going to be enough to take care of bandwidth/core ratio. To make matter worse, there might be spatial limitation past 12 channels per socket in commonplace rack type issue. To beat all these limitations requires de-coupling of reminiscence from CPU. In fact, de-coupling of reminiscence requires order of magnitude extra interconnect bandwidth. Scaling that a lot bandwidth and making reminiscence multi-tenant would require a distinct IO transport than electrical area. Whereas we’re nonetheless not there but however in close to future reminiscence will develop into a community useful resource & with sNIC/DPU computing, community is certainly changing into pc.
UCX X-Collection structure is an amalgamation of latest concepts, tendencies, and a few bets in cohesive trend to allow heterogeneous computing. It solves the present wants and permits clients to undertake and prolong hybrid cloud mannequin as wanted whereas balancing TCO.
In subsequent blogs, we are going to focus on about “The holy grail- case for reminiscence disaggregation” and “Want for non-electrical IO transport” for reminiscence disaggregation.
Sources
UCS X-Collection – The Way forward for Computing Weblog Collection – Half 1 of three
UCS X-Collection – The Way forward for Computing Weblog Collection – Half 2 of three
Share:
[ad_2]

