



[ad_1]
Video recognition is a core activity in laptop imaginative and prescient with functions from video content material evaluation to motion recognition. Nevertheless, coaching fashions for video recognition typically requires untrimmed movies to be manually annotated, which might be prohibitively time consuming. With the intention to cut back the hassle of gathering movies with annotations, studying visible data from movies with weak labels, i.e., the place the annotation is auto-generated with out handbook intervention, has attracted rising analysis curiosity, due to the big quantity of simply accessible video knowledge. Untrimmed movies, for instance, are sometimes acquired by querying with key phrases for lessons that the video recognition mannequin goals to categorise. A key phrase, which we confer with as a weak label, is then assigned to every untrimmed video obtained.
Though large-scale movies with weak labels are simpler to gather, coaching with unverified weak labels poses one other problem in growing sturdy fashions. Latest research have demonstrated that, along with the label noise (e.g., incorrect motion labels on untrimmed movies), there’s temporal noise as a result of lack of correct temporal motion localization — i.e., an untrimmed video might embody different non-targeted content material or might solely present the goal motion in a small proportion of the video.
Lowering noise results for large-scale weakly-supervised pre-training is essential however notably difficult in apply. Latest work signifies that querying quick movies (e.g., ~1 minute in size) to acquire extra correct temporal localization of goal actions or making use of a instructor mannequin to do filtering can yield improved outcomes. Nevertheless, such knowledge pre-processing strategies stop fashions from totally using obtainable video knowledge, particularly longer movies with richer content material.
In “Studying from Weakly-Labeled Net Movies through Exploring Sub-Ideas“, we suggest an answer to those points that makes use of a easy studying framework to conduct efficient pre-training on untrimmed movies. As an alternative of merely filtering the potential temporal noise, this method converts such “noisy” knowledge to helpful supervision by creating a brand new set of significant “center floor” pseudo-labels that increase the unique weak label house, a novel idea we name Sub-Pseudo Label (SPL). The mannequin is pre-trained on this extra “fine-grained” house after which fine-tuned on a goal dataset. Our experiments display that the discovered representations are significantly better than earlier approaches. Furthermore, SPL has been proven to be efficient in bettering the motion recognition mannequin high quality for Google Cloud Video AI, which allows content material producers to simply search by large libraries of their video property to shortly supply content material of curiosity.
 |
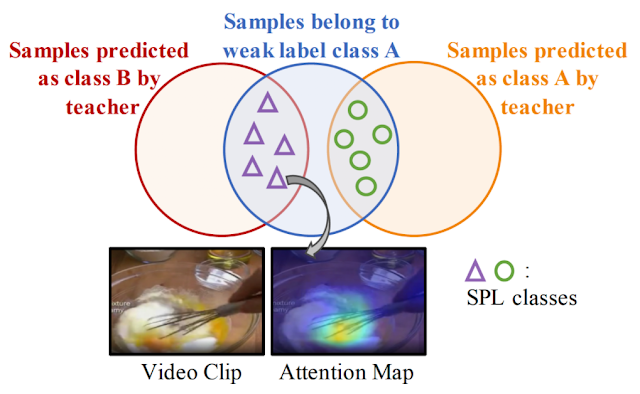 |
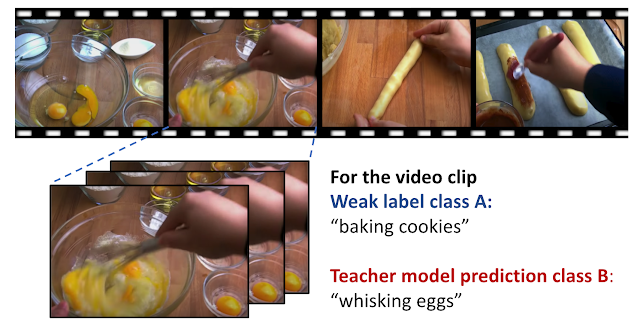
| Sampled coaching clips might characterize a distinct visible motion (whisking eggs) from the question label of the entire untrimmed video (baking cookies). SPL converts the potential label noise to helpful supervision indicators by creating a brand new set of “center floor” pseudo-classes (i.e., sub-concepts) through extrapolating two associated motion lessons. Enriched supervision is offered for efficient mannequin pre-training. |
Sub-Pseudo Label (SPL)
SPL is an easy approach that advances the teacher-student coaching framework, which is thought to be efficient for self-training and to enhance semi-supervised studying. Within the teacher-student framework, a instructor mannequin is skilled on high-quality labeled knowledge after which assigns pseudo-labels to unlabeled knowledge. The scholar mannequin trains on each high-quality labeled knowledge and the unlabeled knowledge that has the teacher-predicted labels. Whereas earlier strategies have proposed quite a lot of methods to enhance the pseudo-label high quality, SPL takes a novel method that mixes data from each weak labels (i.e., question textual content used to amass knowledge) and teacher-predicted labels, which leads to higher pseudo-labels total. This methodology focuses on video recognition the place temporal noise is difficult, however it may be prolonged simply to different domains, like picture classification.
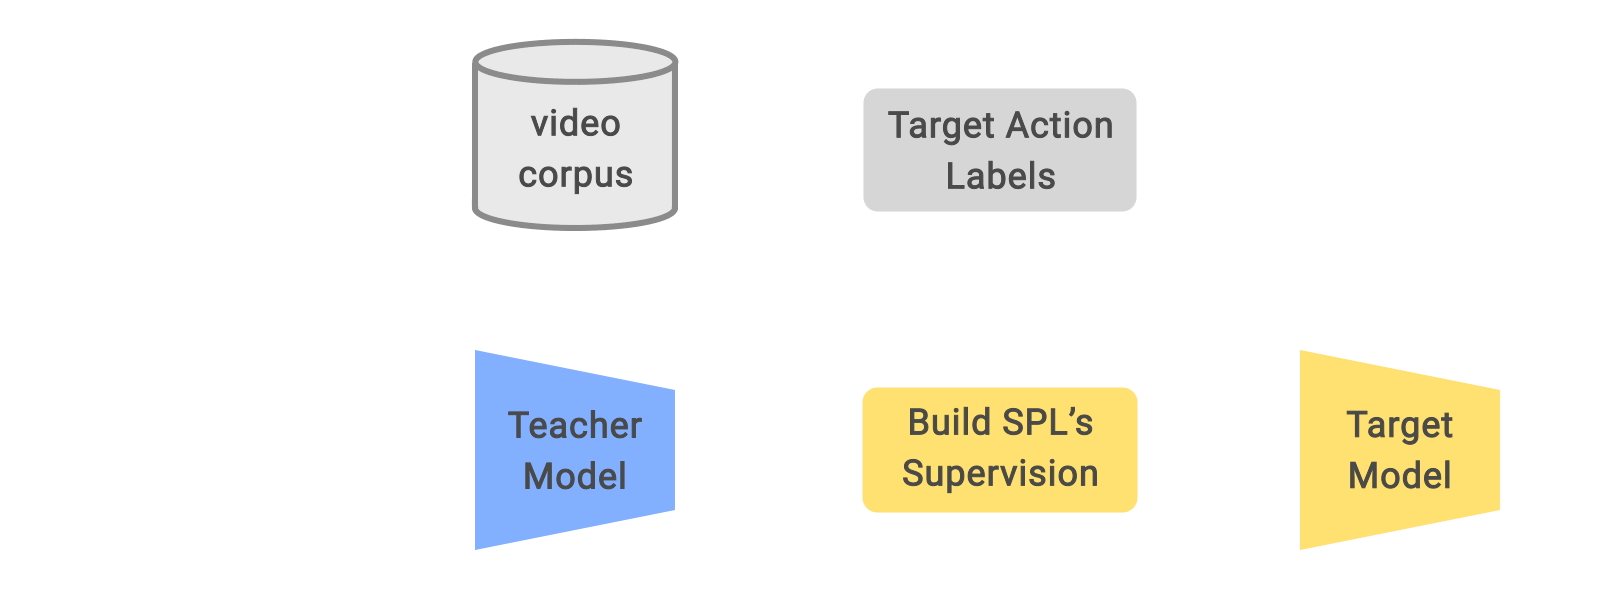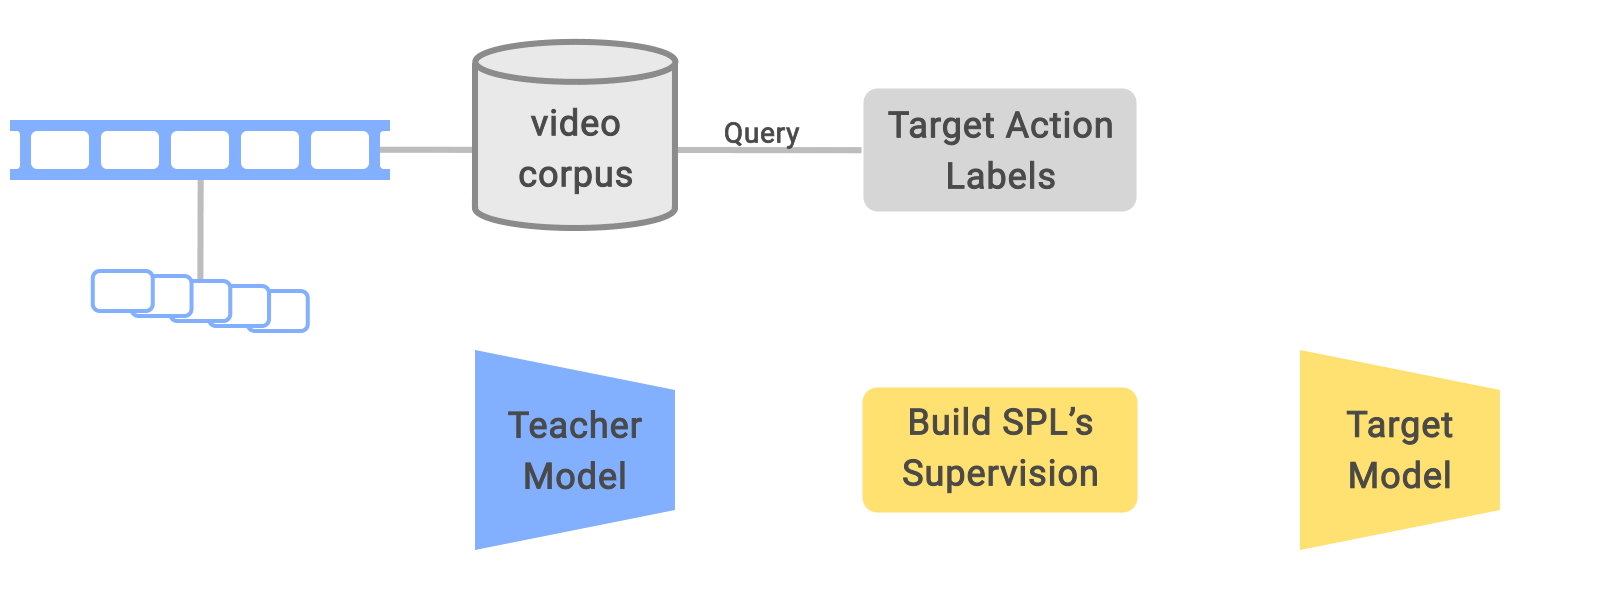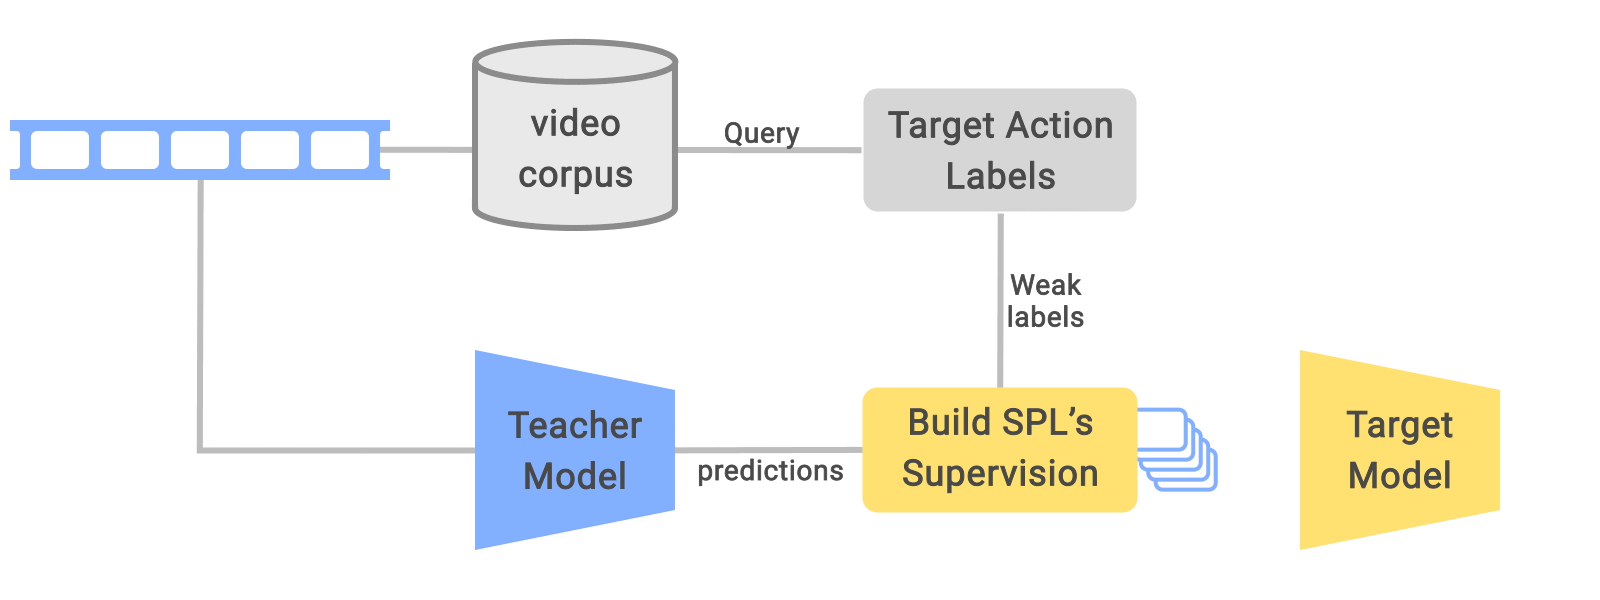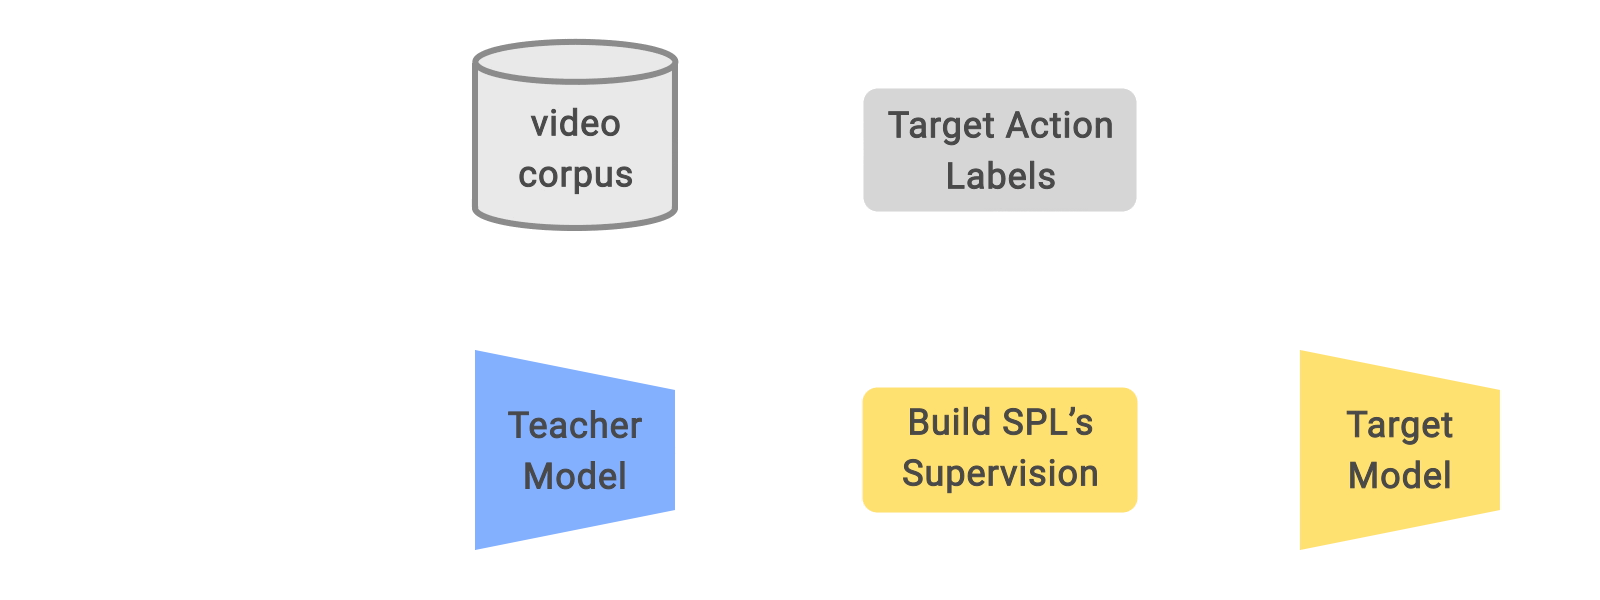 |
| The general pre-training framework for studying from weakly labeled movies through SPLs. Every trimmed video clip is re-labeled utilizing SPL given the teacher-predicted labels and the weak labels used to question the corresponding untrimmed video. |
The SPL methodology is motivated by the remark that inside an untrimmed video “noisy” video clips have semantic relations with the goal motion (i.e., the weak label class), however might also embody important visible parts of different actions, such because the instructor mannequin–predicted class. Our method makes use of the extrapolated SPLs from weak labels along with the distilled labels to seize the enriched supervision indicators, encouraging studying higher representations throughout pre-training that can be utilized for downstream fine-tuning duties.
It’s simple to find out the SPL class for every video clip. We first carry out inference on every video clip utilizing the instructor mannequin skilled from a goal dataset to get a instructor prediction class. Every clip can be labeled by the category (i.e., question textual content) of the untrimmed supply video. A 2-dimensional confusion matrix is used to summarize the alignments between the instructor mannequin inferences and the unique weak annotations. Primarily based on this confusion matrix, we conduct label extrapolation between instructor mannequin predictions and weak labels to acquire the uncooked SPL label house.
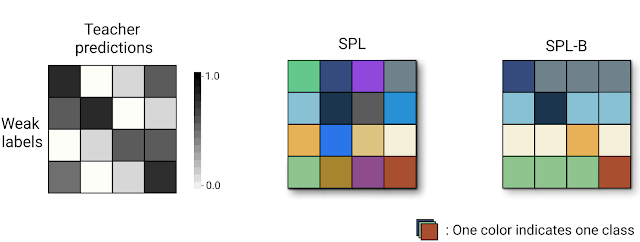 |
| Left: The confusion matrix, which is the premise of the uncooked SPL label house. Center: The ensuing SPL label areas (16 lessons on this instance). Proper: SPL-B, one other SPL model, that reduces the label house by collating agreed and disagreed entries of every row as impartial SPL lessons, which on this instance ends in solely 8 lessons. |
Effectiveness of SPL
We consider the effectiveness of SPL compared to totally different pre-training strategies utilized to a 3D ResNet50 mannequin that’s fine-tuned on Kinetics-200 (K200). One pre-training method merely initializes the mannequin utilizing ImageNet. The opposite pre-training strategies use 670k video clips sampled from an inside dataset of 147k movies, collected following normal processes just like these described for Kinetics-200, that cowl a broad vary of actions. Weak label coaching and instructor prediction coaching use both the weak labels or teacher-predicted labels on the movies, respectively. Settlement filtering makes use of solely the coaching knowledge for which the weak labels and teacher-predicted labels match. We discover that SPL outperforms every of those strategies. Although the dataset used as an instance the SPL method was constructed for this work, in precept the strategy we describe applies to any dataset that has weak labels.
| Pre-training Technique | Prime-1 | Prime-5 | ||
| ImageNet Initialized | 80.6 | 94.7 | ||
| Weak Label Practice | 82.8 | 95.6 | ||
| Trainer Prediction Practice | 81.9 | 95.0 | ||
| Settlement Filtering Practice | 82.9 | 95.4 | ||
| SPL | 84.3 | 95.7 |
We additionally display that sampling extra video clips from a given variety of untrimmed movies can assist enhance the mannequin efficiency. With a enough variety of video clips obtainable, SPL constantly outperforms weak label pre-training by offering enriched supervision.
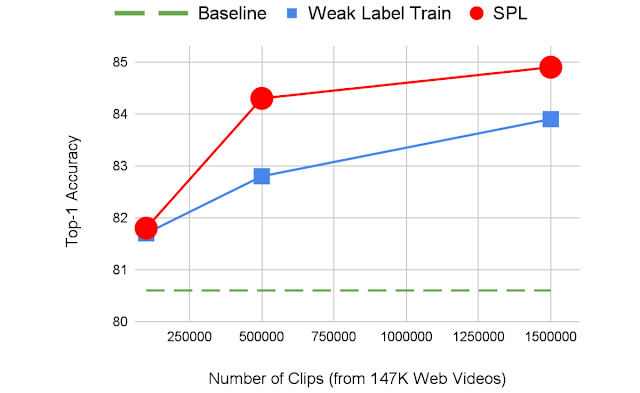 |
| As extra clips are sampled from 147K movies, the label noise is elevated step by step. SPL turns into an increasing number of efficient at using the weakly-labeled clips to realize higher pre-training. |
We visualize the visible ideas discovered from SPL with consideration visualization by making use of Grad-CAM on the skilled mannequin. It’s fascinating to watch some significant “center floor” ideas that may be discovered by SPL.
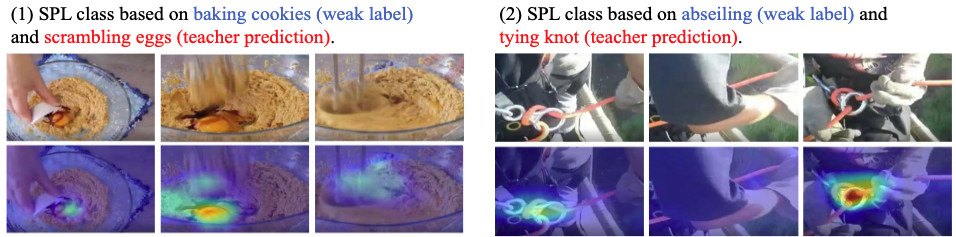 |
| Examples of consideration visualization for SPL lessons. Some significant “center floor” ideas might be discovered by SPL, reminiscent of mixing up the eggs and flour (left) and utilizing the abseiling gear (proper). |
Conclusion
We display that SPLs can present enriched supervision for pre-training. SPL doesn’t improve coaching complexity and might be handled as an off-the-shelf approach to combine with teacher-student–primarily based coaching frameworks. We consider it is a promising path for locating significant visible ideas by bridging weak labels and the data distilled from instructor fashions. SPL has additionally demonstrated promising generalization to the picture recognition area and we anticipate future extensions that apply to duties which have noise in labels. Now we have efficiently utilized SPL for Google Cloud Video AI the place it has improved the accuracy of the motion recognition fashions, serving to customers to raised perceive, search, and monetize their video content material library.
Acknowledgements
We gratefully acknowledge the contributions of different co-authors, together with Kunpeng Li, Xuehan Xiong, Chen-Yu Lee, Zhichao Lu, Yun Fu, Tomas Pfister. We additionally thank Debidatta Dwibedi, David A Ross, Chen Solar, Jonathan C. Stroud, and Wei Hua for his or her priceless feedback and assistance on this work, and Tom Small for determine creation.
[ad_2]

