



[ad_1]
With a worldwide penetration charge of 58.4%, social media gives a wealth of opinions, concepts, and discussions shared each day. This information affords wealthy insights into a very powerful and common dialog matters amongst customers.
In advertising, social media evaluation might help firms perceive and leverage shopper conduct. Two frequent, sensible strategies are:
- Matter modeling, which solutions the query, “What dialog matters do customers discuss?”
- Sentiment evaluation, which solutions the query, “How positively or negatively are customers talking a few subject?”
On this article, we use Python for social media information evaluation and exhibit the right way to collect very important market data, extract actionable suggestions, and establish the product options that matter most to purchasers.
To show the utility of social media evaluation, let’s carry out a product evaluation of varied smartwatches utilizing Reddit information and Python. Python is a powerful selection for information science initiatives, and it affords many libraries that facilitate the implementation of the machine studying (ML) and pure language processing (NLP) fashions that we are going to use.
This evaluation makes use of Reddit information (versus information from Twitter, Fb, or Instagram) as a result of Reddit is the second most trusted social media platform for information and knowledge, based on the American Press Institute. As well as, Reddit’s subforum group produces “subreddits” the place customers advocate and criticize particular merchandise; its construction is right for product-centered information evaluation.
First we use sentiment evaluation to match consumer opinions on common smartwatch manufacturers to find which merchandise are seen most positively. Then, we use subject modeling to slender in on particular smartwatch attributes that customers often talk about. Although our instance is restricted, you possibly can apply the identical evaluation to every other services or products.
Getting ready Pattern Reddit Information
The information set for this instance comprises the title of the put up, the textual content of the put up, and the textual content of all feedback for the newest 100 posts made within the r/smartwatch subreddit. Our dataset comprises the newest 100 full discussions of the product, together with customers’ experiences, suggestions about merchandise, and their professionals and cons.
To gather this data from Reddit, we are going to use PRAW, the Python Reddit API Wrapper. First, create a consumer ID and secret token on Reddit utilizing the OAuth2 information. Subsequent, observe the official PRAW tutorials on downloading put up feedback and getting put up URLs.
Sentiment Evaluation: Figuring out Main Merchandise
To establish main merchandise, we are able to study the constructive and damaging feedback customers make about sure manufacturers by making use of sentiment evaluation to our textual content corpus. Sentiment evaluation fashions are NLP instruments that categorize texts as constructive or damaging primarily based on their phrases and phrases. There may be all kinds of doable fashions, starting from easy counters of constructive and damaging phrases to deep neural networks.
We’ll use VADER for our instance, as a result of it’s designed to optimize outcomes for brief texts from social networks by utilizing lexicons and rule-based algorithms. In different phrases, VADER performs nicely on information units just like the one we’re analyzing.
Use the Python ML pocket book of your selection (for instance, Jupyter) to research this information set. We set up VADER utilizing pip:
pip set up vaderSentiment
First, we add three new columns to our information set: the compound sentiment values for the put up title, put up textual content, and remark textual content. To do that, iterate over every textual content and apply VADER’s polarity_scores technique, which takes a string as enter and returns a dictionary with 4 scores: positivity, negativity, neutrality, and compound.
For our functions, we’ll use solely the compound rating—the general sentiment primarily based on the primary three scores, rated on a normalized scale from -1 to 1 inclusive, the place -1 is essentially the most damaging and 1 is essentially the most constructive—in an effort to characterize the sentiment of a textual content with a single numerical worth:
# Import VADER and pandas
from vaderSentiment.vaderSentiment import SentimentIntensityAnalyzer
import pandas as pd

analyzer = SentimentIntensityAnalyzer()

# Load information
information = pd.read_json("./sample_data/information.json", strains=True)

# Initialize lists to retailer sentiment values
title_compound = []
text_compound = []
comment_text_compound = []

for title,textual content,comment_text in zip(information.Title, information.Textual content, information.Comment_text):
    title_compound.append(analyzer.polarity_scores(title)["compound"])

    text_compound.append(analyzer.polarity_scores(textual content)["compound"])

    comment_text_compound.append(analyzer.polarity_scores(comment_text["compound"])

# Add the brand new columns with the sentiment
information["title_compound"] = title_compound
information["text_compound"] = text_compound
information["comment_text_compound"] = comment_text_compound
Subsequent, we wish to catalog the texts by product and model; this permits us to find out the sentiment scores related to particular smartwatches. To do that, we designate a listing of product strains we wish to analyze, then we confirm which merchandise are talked about in every textual content:
list_of_products = ["samsung", "apple", "xiaomi", "huawei", "amazfit", "oneplus"]

for column in ["Title","Text","Comment_text"]:
    for product in list_of_products:
        l = []
        for textual content in information[column]:
            l.append(product in textual content.decrease())
        information["{}_{}".format(column,product)] = l
Sure texts might point out a number of merchandise (for instance, a single remark may evaluate two smartwatches). We are able to proceed in one among two methods:
- We are able to discard these texts.
- We are able to cut up these texts utilizing NLP methods. (On this case, we’d assign part of the textual content to every product.)
For the sake of code readability and ease, our evaluation discards these texts.
Sentiment Evaluation Outcomes
Now we’re in a position to study our information and decide the common sentiment related to numerous smartwatch manufacturers, as expressed by customers:
for product in list_of_products:
    imply = pd.concat([data[data["Title_{}".format(product)]].title_compound,
                      information[data["Text_{}".format(product)]].text_compound,
                      information[data["Comment_text_{}".format(product)]].comment_text_compound]).imply()
    print("{}: {})".format(product,imply))
We observe the next outcomes:
|
Smartwatch |
Samsung |
Apple |
Xiaomi |
Huawei |
Amazfit |
OnePlus |
|---|---|---|---|---|---|---|
|
Sentiment Compound Rating (Avg.) |
0.4939 |
0.5349 |
0.6462 |
0.4304 |
0.3978 |
0.8413 |
Our evaluation reveals helpful market data. For instance, customers from our information set have a extra constructive sentiment relating to the OnePlus smartwatch over the opposite smartwatches.
Past contemplating common sentiment, companies also needs to think about the components affecting these scores: What do customers love or hate about every model? We are able to use subject modeling to dive deeper into our present evaluation and produce actionable suggestions on services and products.
Matter Modeling: Discovering Necessary Product Attributes
Matter modeling is the department of NLP that makes use of ML fashions to mathematically describe what a textual content is about. We’ll restrict the scope of our dialogue to classical NLP subject modeling approaches, although there are latest advances happening utilizing transformers, similar to BERTopic.
There are a lot of subject modeling algorithms, together with non-negative matrix factorization (NMF), sparse principal elements evaluation (sparse PCA), and latent dirichlet allocation (LDA). These ML fashions use a matrix as enter then scale back the dimensionality of the info. The enter matrix is structured such that:
- Every column represents a phrase.
- Every row represents a textual content.
- Every cell represents the frequency of every phrase in every textual content.
These are all unsupervised fashions that can be utilized for subject decomposition. The NMF mannequin is usually used for social media evaluation, and is the one we are going to use for our instance, as a result of it permits us to acquire simply interpretable outcomes. It produces an output matrix such that:
- Every column represents a subject.
- Every row represents a textual content.
- Every cell represents the diploma to which a textual content discusses a particular subject.
Our workflow follows this course of:

First, we’ll apply our NMF mannequin to research basic matters of curiosity, after which we’ll slender in on constructive and damaging matters.
Analyzing Common Subjects of Curiosity
We’ll take a look at matters for the OnePlus smartwatch, because it had the very best compound sentiment rating. Let’s import the required packages offering NMF performance and customary cease phrases to filter from our textual content:
from sklearn.feature_extraction.textual content import CountVectorizer
from sklearn.feature_extraction.textual content import TfidfTransformer
from sklearn.decomposition import NMF

import nltk
nltk.obtain('stopwords')
from nltk.corpus import stopwords
Now, let’s create a listing with the corpus of texts we are going to use. We use the scikit-learn ML library’s CountVectorizer and TfidfTransformer capabilities to generate our enter matrix:
product = "oneplus"
corpus = pd.concat([data[data["Title_{}".format(product)]].Title,
                      information[data["Text_{}".format(product)]].Textual content,
                      information[data["Comment_text_{}".format(product)]].Comment_text]).tolist()

count_vect = CountVectorizer(stop_words=stopwords.phrases('english'), lowercase=True)
x_counts = count_vect.fit_transform(corpus)

feature_names = count_vect.get_feature_names_out()
tfidf_transformer = TfidfTransformer()
x_tfidf = tfidf_transformer.fit_transform(x_counts)
(Notice that particulars about dealing with n-grams—i.e., different spellings and utilization similar to “one plus”—may be present in my earlier article on subject modeling.)
We’re prepared to use the NMF mannequin and discover the latent matters in our information. Like different dimensionality discount strategies, NMF wants the entire variety of matters to be set as a parameter (dimension). Right here, we select a 10-topic dimensionality discount for simplicity, however you may take a look at totally different values to see what variety of matters yields the very best unsupervised studying end result. Attempt setting dimension to maximise metrics such because the silhouette coefficient or the elbow technique. We additionally set a random state for reproducibility:
import numpy as np

dimension = 10
nmf = NMF(n_components = dimension, random_state = 42)
nmf_array = nmf.fit_transform(x_tfidf)

elements = [nmf.components_[i] for i in vary(len(nmf.components_))]
options = count_vect.get_feature_names_out()
important_words = [sorted(features, key = lambda x: components[j][np.where(features==x)], reverse = True) for j in vary(len(elements))]
important_words comprises lists of phrases, the place every checklist represents one subject and the phrases are ordered inside a subject by significance. It features a mixture of significant and “rubbish” matters; it is a frequent end in subject modeling as a result of it’s tough for the algorithm to efficiently cluster all texts into only a few matters.
Analyzing the important_words output, we discover significant matters round phrases like “price range” or “cost”, which factors to options that matter to customers when discussing OnePlus smartwatches:
['charge', 'battery', 'watch', 'best', 'range', 'days', 'life', 'android', 'bet', 'connectivity']
['budget', 'price', 'euros', 'buying', 'purchase', 'quality', 'tag', 'worth', 'smartwatch', '100']
Since our sentiment evaluation produced a excessive compound rating for OnePlus, we’d assume that this implies it has a decrease price or higher battery life in comparison with different manufacturers. Nonetheless, at this level, we do not know whether or not customers view these components positively or negatively, so let’s conduct an in-depth evaluation to get tangible solutions.
Analyzing Constructive and Unfavorable Subjects
Our extra detailed evaluation makes use of the identical ideas as our basic evaluation, utilized individually to constructive and damaging texts. We’ll uncover which components customers level to when talking positively—or negatively—a few product.
Let’s do that for the Samsung smartwatch. We’ll use the identical pipeline however with a distinct corpus:
- We create a listing of constructive texts which have a compound rating better than 0.8.
- We create a listing of damaging texts which have a compound rating lower than 0.
These numbers have been chosen to pick out the highest 20% of constructive texts scores (>0.8) and high 20% of damaging texts scores (<0), and produce the strongest outcomes for our smartwatch sentiment evaluation:
# First the damaging texts.
product = "samsung"
corpus_negative = pd.concat([data[(data["Title_{}".format(product)]) & (information.title_compound < 0)].Title,
                      information[(data["Text_{}".format(product)]) & (information.text_compound < 0)].Textual content,
                      information[(data["Comment_text_{}".format(product)]) & (information.comment_text_compound < 0)].Comment_text]).tolist()


# Now the constructive texts.
corpus_positive = pd.concat([data[(data["Title_{}".format(product)]) & (information.title_compound > 0.8)].Title,
                      information[(data["Text_{}".format(product)]) & (information.text_compound > 0.8)].Textual content,
                      information[(data["Comment_text_{}".format(product)]) & (information.comment_text_compound > 0.8)].Comment_text]).tolist()

print(corpus_negative)
print(corpus_positive)
We are able to repeat the identical technique of subject modeling that we used for basic matters of curiosity to disclose the constructive and damaging matters. Our outcomes now present far more particular advertising data: For instance, our mannequin’s damaging corpus output features a subject in regards to the accuracy of burned energy, whereas the constructive output is about navigation/GPS and well being indicators like pulse charge and blood oxygen ranges. Lastly, we’ve got actionable suggestions on elements of the smartwatch that the customers love and areas the place the product has room for enchancment.
wordcloud Library
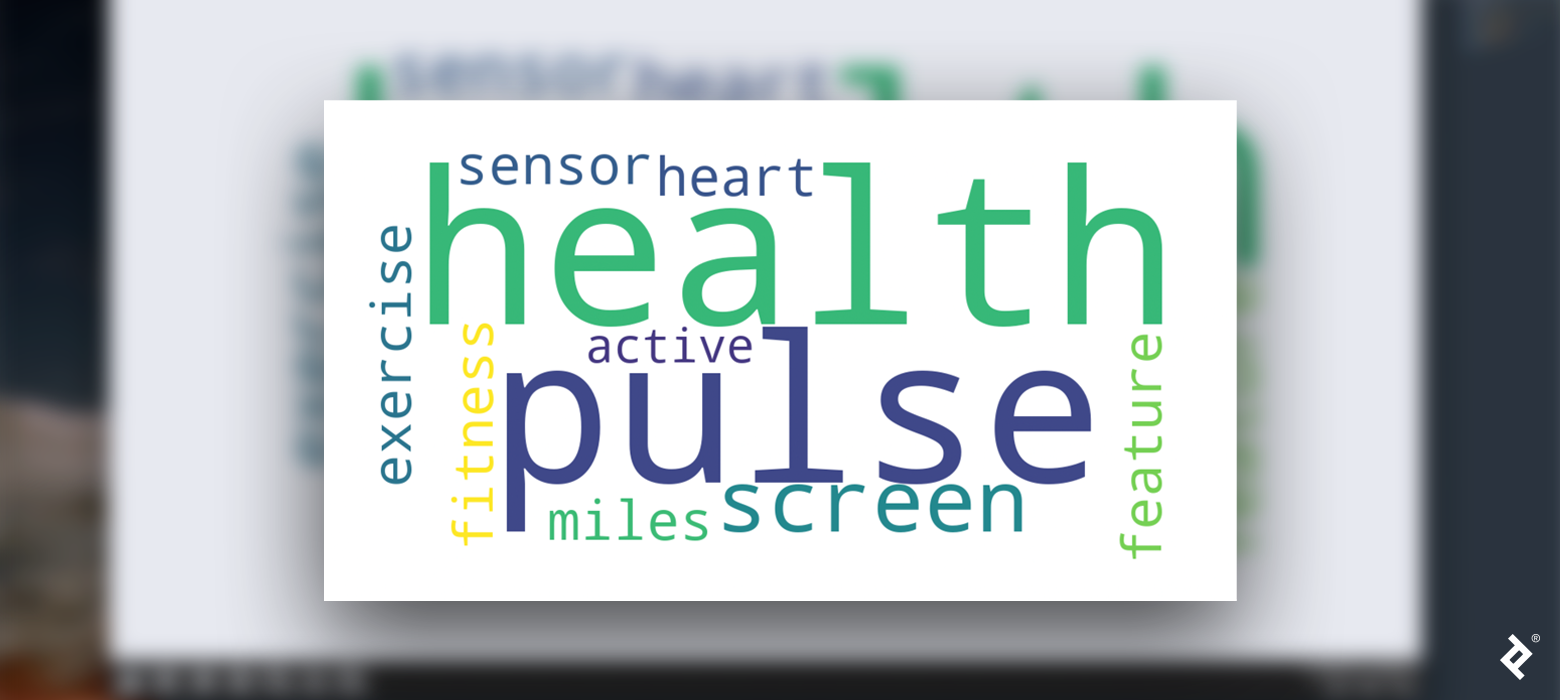
To amplify your information findings, I would advocate making a phrase cloud or one other related visualization of the vital matters recognized in our tutorial.
By way of our evaluation, we perceive what customers consider a goal product and people of its rivals, what customers love about high manufacturers, and what could also be improved for higher product design. Public social media information evaluation permits you to make knowledgeable choices relating to enterprise priorities and improve general consumer satisfaction. Incorporate social media evaluation into your subsequent product cycle for improved advertising campaigns and product design—as a result of listening is all the pieces.
Additional Studying on the Toptal Engineering Weblog:
- Information Mining for Predictive Social Community Evaluation
- Ensemble Strategies: Elegant Strategies to Produce Improved Machine Studying Outcomes
- Getting Began With TensorFlow: A Machine Studying Tutorial
- Adversarial Machine Studying: How one can Assault and Defend ML Fashions
The editorial staff of the Toptal Engineering Weblog extends its gratitude to Daniel Rubio for reviewing the code samples and different technical content material introduced on this article.
[ad_2]

