



[ad_1]
Birds are throughout us, and simply by listening, we will be taught many issues about the environment. Ecologists use birds to know meals techniques and forest well being — for instance, if there are extra woodpeckers in a forest, meaning there’s a variety of useless wooden. As a result of birds talk and mark territory with songs and calls, it’s most effective to determine them by ear. Actually, consultants could determine as much as 10x as many birds by ear as by sight.
Lately, autonomous recording models (ARUs) have made it simple to seize hundreds of hours of audio in forests that may very well be used to raised perceive ecosystems and determine essential habitat. Nevertheless, manually reviewing the audio knowledge could be very time consuming, and consultants in birdsong are uncommon. However an strategy based mostly on machine studying (ML) has the potential to vastly scale back the quantity of knowledgeable evaluation wanted for understanding a habitat.
Nevertheless, ML-based audio classification of fowl species may be difficult for a number of causes. For one, birds usually sing over each other, particularly in the course of the “daybreak refrain” when many birds are most energetic. Additionally, there aren’t clear recordings of particular person birds to be taught from — virtually all the accessible coaching knowledge is recorded in noisy outside situations, the place different sounds from the wind, bugs, and different environmental sources are sometimes current. Because of this, current birdsong classification fashions battle to determine quiet, distant and overlapping vocalizations. Moreover, a number of the commonest species usually seem unlabeled within the background of coaching recordings for much less frequent species, main fashions to low cost the frequent species. These tough instances are crucial for ecologists who wish to determine endangered or invasive species utilizing automated techniques.
To handle the overall problem of coaching ML fashions to routinely separate audio recordings with out entry to examples of remoted sounds, we not too long ago proposed a brand new unsupervised technique referred to as combination invariant coaching (MixIT) in our paper, “Unsupervised Sound Separation Utilizing Combination Invariant Coaching”. Furthermore, in our new paper, “Enhancing Hen Classification with Unsupervised Sound Separation,” we use MixIT coaching to separate birdsong and enhance species classification. We discovered that together with the separated audio within the classification improves precision and classification high quality on three impartial soundscape datasets. We’re additionally completely satisfied to announce the open-source launch of the birdsong separation fashions on GitHub.
Birdsong Audio Separation
MixIT learns to separate single-channel recordings into a number of particular person tracks, and may be skilled solely with noisy, real-world recordings. To coach the separation mannequin, we create a “combination of mixtures” (MoM) by mixing collectively two real-world recordings. The separation mannequin then learns to take the MoM aside into many channels to reduce a loss operate that makes use of the 2 unique real-world recordings as ground-truth references. The loss operate makes use of these references to group the separated channels such that they are often combined again collectively to recreate the 2 unique real-world recordings. Since there’s no strategy to understand how the completely different sounds within the MoM had been grouped collectively within the unique recordings, the separation mannequin has no selection however to separate the person sounds themselves, and thus learns to position every singing fowl in a special output audio channel, additionally separate from wind and different background noise.
We skilled a brand new MixIT separation mannequin utilizing birdsong recordings from Xeno-Canto and the Macaulay Library. We discovered that for separating birdsong, this new mannequin outperformed a MixIT separation mannequin skilled on a considerable amount of normal audio from the AudioSet dataset. We measure the standard of the separation by mixing two recordings collectively, making use of separation, after which remixing the separated audio channels such that they reconstruct the unique two recordings. We measure the signal-to-noise ratio (SNR) of the remixed audio relative to the unique recordings. We discovered that the mannequin skilled particularly for birds achieved 6.1 decibels (dB) higher SNR than the mannequin skilled on AudioSet (10.5 dB vs 4.4 dB). Subjectively, we additionally discovered many examples the place the system labored extremely properly, separating very tough to tell apart calls in real-world knowledge.
The next movies reveal separation of birdsong from two completely different areas (Caples and the Excessive Sierras). The movies present the mel-spectrogram of the combined audio (a 2D picture that exhibits the frequency content material of the audio over time) and spotlight the audio separated into completely different tracks.
Classifying Hen Species
To categorise birds in real-world audio captured with ARUs, we first cut up the audio into five-second segments after which create a mel-spectrogram of every section. We then prepare an EfficientNet classifier to determine fowl species from the mel-spectrogram photos, coaching on audio from Xeno-Canto and the Macaulay Library. We skilled two separate classifiers, one for species within the Sierra Nevada mountains and one for upstate New York. Observe that these classifiers are usually not skilled on separated audio; that’s an space for future enchancment.
We additionally launched some new strategies to enhance classifier coaching. Taxonomic coaching asks the classifier to offer labels for every stage of the species taxonomy (genus, household, and order), which permits the mannequin to be taught groupings of species earlier than studying the sometimes-subtle variations between comparable species. Taxonomic coaching additionally permits the mannequin to profit from knowledgeable details about the taxonomic relationships between completely different species. We additionally discovered that random low-pass filtering was useful for simulating distant sounds throughout coaching: As an audio supply will get additional away, the high-frequency components fade away earlier than the low-frequency components. This was significantly efficient for figuring out species from the Excessive Sierras area, the place birdsongs cowl very lengthy distances, unimpeded by timber.
Classifying Separated Audio
We discovered that separating audio with the brand new MixIT mannequin earlier than classification improved the classifier efficiency on three impartial real-world datasets. The separation was significantly profitable for identification of quiet and background birds, and in lots of instances helped with overlapping vocalizations as properly.
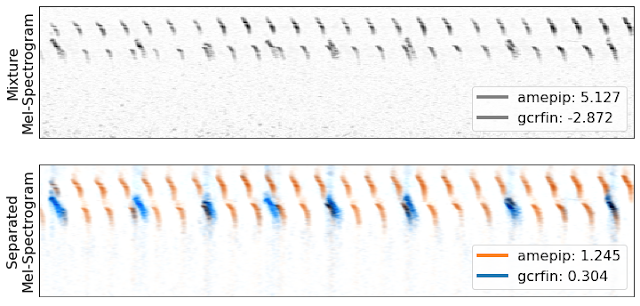 |
| Prime: A mel-spectrogram of two birds, an American pipit (amepip) and gray-crowned rosy finch (gcrfin), from the Sierra Nevadas. The legend exhibits the log-probabilities for the 2 species given by the pre-trained classifiers. Greater values point out extra confidence, and values better than -1.0 are often appropriate classifications. Backside: A mel-spectrogram for the routinely separated audio, with the classifier log possibilities from the separated channels. Observe that the classifier solely identifies the gcrfin as soon as the audio is separated. |
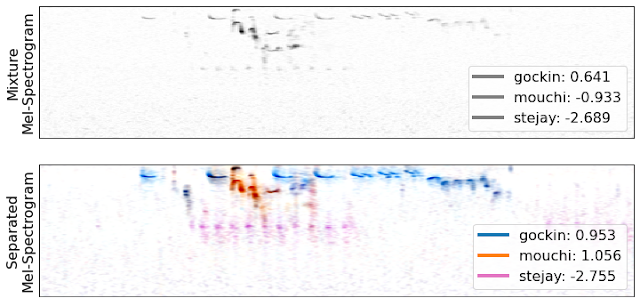 |
| Prime: A fancy combination with three vocalizations: A golden-crowned kinglet (gockin), mountain chickadee (mouchi), and Steller’s jay (stejay). Backside: Separation into three channels, with classifier log possibilities for the three species. We see good visible separation of the Steller’s jay (proven by the distinct pink marks), although the classifier isn’t positive what it’s. |
The separation mannequin does have some potential limitations. Often we observe over-separation, the place a single tune is damaged into a number of channels, which might trigger misclassifications. We additionally discover that when a number of birds are vocalizing, probably the most outstanding tune usually will get a decrease rating after separation. This can be as a result of lack of environmental context or different artifacts launched by separation that don’t seem throughout classifier coaching. For now, we get the very best outcomes by working the classifier on the separated channels and the unique audio, and taking the utmost rating for every species. We count on that additional work will enable us to scale back over-separation and discover higher methods to mix separation and classification. You may see and listen to extra examples of the total system at our GitHub repo.
Future Instructions
We’re at present working with companions on the California Academy of Sciences to know how habitat and species combine modifications after prescribed fires and wildfires, making use of these fashions to ARU audio collected over a few years.
We additionally foresee many potential functions for the unsupervised separation fashions in ecology, past simply birds. For instance, the separated audio can be utilized to create higher acoustic indices, which may measure ecosystem well being by monitoring the whole exercise of birds, bugs, and amphibians with out figuring out explicit species. Related strategies may be tailored to be used underwater to trace coral reef well being.
Acknowledgements
We want to thank Mary Clapp, Jack Dumbacher, and Durrell Kapan from the California Academy of Sciences for offering intensive annotated soundscapes from the Sierra Nevadas. Stefan Kahl and Holger Klinck from the Cornell Lab of Ornithology supplied soundscapes from Sapsucker Woods. Coaching knowledge for each the separation and classification fashions got here from Xeno-Canto and the Macaulay Library. Lastly, we want to thank Julie Cattiau, Lauren Harrell, Matt Harvey, and our co-author, John Hershey, from the Google Bioacoustics and Sound Separation groups.
[ad_2]

