



[ad_1]
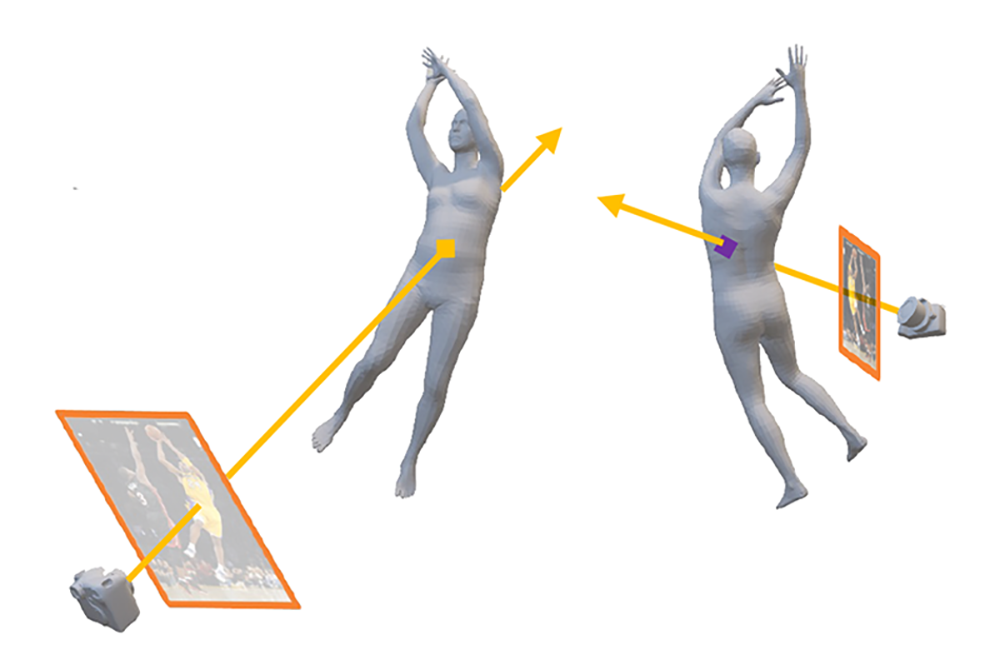
Upon pictures and drawing on their previous experiences, people can typically understand depth in photos which are, themselves, completely flat. Nevertheless, getting computer systems to do the identical factor has proved fairly difficult.
The issue is tough for a number of causes, one being that info is inevitably misplaced when a scene that takes place in three dimensions is diminished to a two-dimensional (2D) illustration. There are some well-established methods for recovering 3D info from a number of 2D photos, however they every have some limitations. A brand new method known as “digital correspondence,” which was developed by researchers at MIT and different establishments, can get round a few of these shortcomings and achieve circumstances the place standard methodology falters.
The usual method, known as “construction from movement,” is modeled on a key facet of human imaginative and prescient. As a result of our eyes are separated from one another, they every supply barely completely different views of an object. A triangle could be fashioned whose sides encompass the road section connecting the 2 eyes, plus the road segments connecting every eye to a typical level on the item in query. Understanding the angles within the triangle and the space between the eyes, it’s potential to find out the space to that time utilizing elementary geometry — though the human visible system, after all, could make tough judgments about distance with out having to undergo arduous trigonometric calculations. This similar primary concept — of triangulation or parallax views — has been exploited by astronomers for hundreds of years to calculate the space to faraway stars.
Triangulation is a key aspect of construction from movement. Suppose you’ve got two photos of an object — a sculpted determine of a rabbit, as an illustration — one taken from the left aspect of the determine and the opposite from the proper. Step one can be to seek out factors or pixels on the rabbit’s floor that each photos share. A researcher might go from there to find out the “poses” of the 2 cameras — the positions the place the photographs had been taken from and the path every digicam was dealing with. Understanding the space between the cameras and the way in which they had been oriented, one might then triangulate to work out the space to a specific level on the rabbit. And if sufficient frequent factors are recognized, it may be potential to acquire an in depth sense of the item’s (or “rabbit’s”) general form.
Appreciable progress has been made with this system, feedback Wei-Chiu Ma, a PhD pupil in MIT’s Division of Electrical Engineering and Laptop Science (EECS), “and other people are actually matching pixels with higher and higher accuracy. As long as we will observe the identical level, or factors, throughout completely different photos, we will use present algorithms to find out the relative positions between cameras.” However the method solely works if the 2 photos have a big overlap. If the enter photos have very completely different viewpoints — and therefore include few, if any, factors in frequent — he provides, “the system might fail.”
Throughout summer season 2020, Ma got here up with a novel method of doing issues that might vastly develop the attain of construction from movement. MIT was closed on the time as a result of pandemic, and Ma was house in Taiwan, enjoyable on the sofa. Whereas trying on the palm of his hand and his fingertips specifically, it occurred to him that he might clearly image his fingernails, despite the fact that they weren’t seen to him.
That was the inspiration for the notion of digital correspondence, which Ma has subsequently pursued together with his advisor, Antonio Torralba, an EECS professor and investigator on the Laptop Science and Synthetic Intelligence Laboratory, together with Anqi Joyce Yang and Raquel Urtasun of the College of Toronto and Shenlong Wang of the College of Illinois. “We wish to incorporate human information and reasoning into our present 3D algorithms” Ma says, the identical reasoning that enabled him to take a look at his fingertips and conjure up fingernails on the opposite aspect — the aspect he couldn’t see.
Construction from movement works when two photos have factors in frequent, as a result of which means a triangle can all the time be drawn connecting the cameras to the frequent level, and depth info can thereby be gleaned from that. Digital correspondence presents a technique to carry issues additional. Suppose, as soon as once more, that one photograph is taken from the left aspect of a rabbit and one other photograph is taken from the proper aspect. The primary photograph would possibly reveal a spot on the rabbit’s left leg. However since mild travels in a straight line, one might use basic information of the rabbit’s anatomy to know the place a light-weight ray going from the digicam to the leg would emerge on the rabbit’s different aspect. That time could also be seen within the different picture (taken from the right-hand aspect) and, if that’s the case, it may very well be used by way of triangulation to compute distances within the third dimension.
Digital correspondence, in different phrases, permits one to take some extent from the primary picture on the rabbit’s left flank and join it with some extent on the rabbit’s unseen proper flank. “The benefit right here is that you simply don’t want overlapping photos to proceed,” Ma notes. “By trying by means of the item and popping out the opposite finish, this system offers factors in frequent to work with that weren’t initially accessible.” And in that method, the constraints imposed on the standard technique could be circumvented.
One would possibly inquire as to how a lot prior information is required for this to work, as a result of if you happen to needed to know the form of every little thing within the picture from the outset, no calculations can be required. The trick that Ma and his colleagues make use of is to make use of sure acquainted objects in a picture — such because the human type — to function a form of “anchor,” and so they’ve devised strategies for utilizing our information of the human form to assist pin down the digicam poses and, in some circumstances, infer depth throughout the picture. As well as, Ma explains, “the prior information and customary sense that’s constructed into our algorithms is first captured and encoded by neural networks.”
The crew’s final purpose is way extra formidable, Ma says. “We wish to make computer systems that may perceive the three-dimensional world similar to people do.” That goal continues to be removed from realization, he acknowledges. “However to transcend the place we’re right this moment, and construct a system that acts like people, we’d like a tougher setting. In different phrases, we have to develop computer systems that may not solely interpret nonetheless photos however can even perceive quick video clips and ultimately full-length motion pictures.”
A scene within the movie “Good Will Searching” demonstrates what he has in thoughts. The viewers sees Matt Damon and Robin Williams from behind, sitting on a bench that overlooks a pond in Boston’s Public Backyard. The following shot, taken from the alternative aspect, presents frontal (although absolutely clothed) views of Damon and Williams with a wholly completely different background. Everybody watching the film instantly is aware of they’re watching the identical two folks, despite the fact that the 2 pictures don’t have anything in frequent. Computer systems can’t make that conceptual leap but, however Ma and his colleagues are working exhausting to make these machines more proficient and — at the least in terms of imaginative and prescient — extra like us.
The crew’s work will probably be offered subsequent week on the Convention on Laptop Imaginative and prescient and Sample Recognition.
[ad_2]

