

[ad_1]
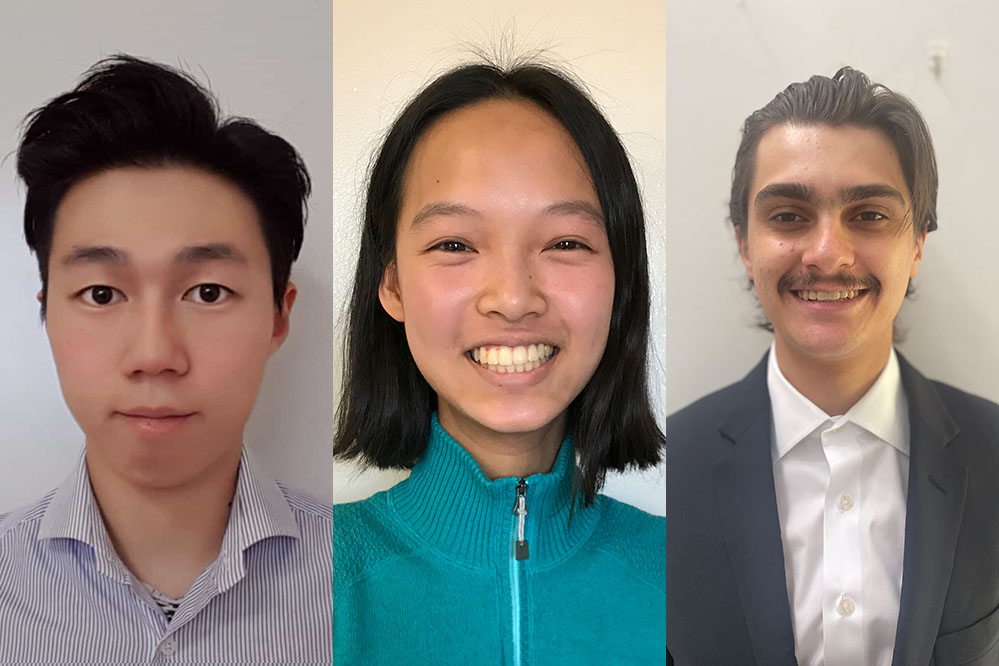
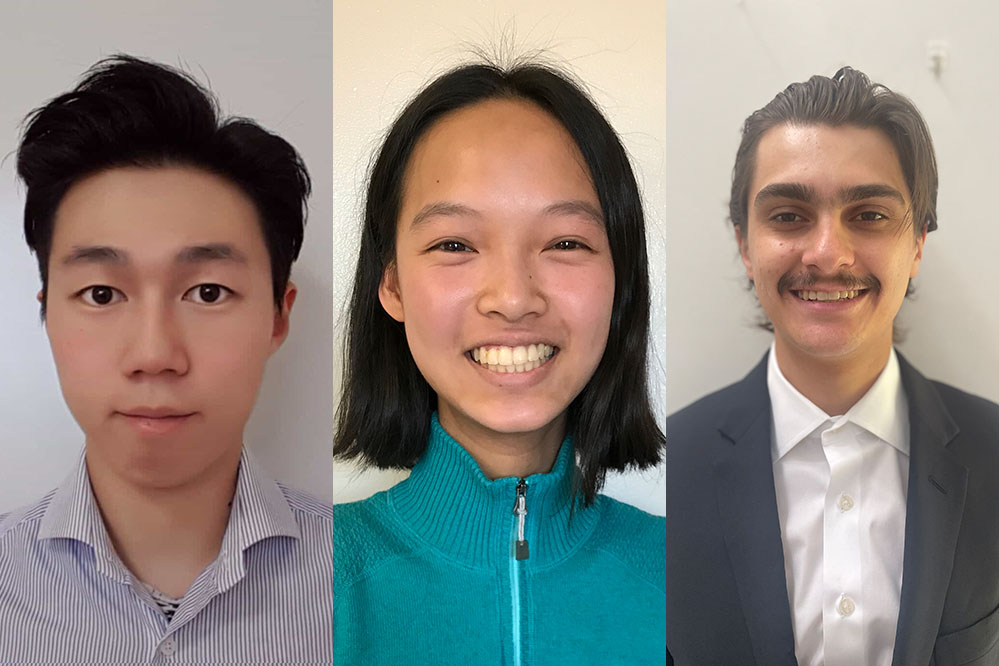
From their early days at MIT, and even earlier than, Emma Liu ’22, MNG ’22, Yo-whan “John” Kim ’22, MNG ’22, and Clemente Ocejo ’21, MNG ’22 knew they wished to carry out computational analysis and discover synthetic intelligence and machine studying. “Since highschool, I’ve been into deep studying and was concerned in initiatives,” says Kim, who participated in a Analysis Science Institute (RSI) summer season program at MIT and Harvard College and went on to work on motion recognition in movies utilizing Microsoft’s Kinect.
As college students within the Division of Electrical Engineering and Laptop Science who just lately graduated from the Grasp of Engineering (MEng) Thesis Program, Liu, Kim, and Ocejo have developed the abilities to assist information application-focused initiatives. Working with the MIT-IBM Watson AI Lab, they’ve improved textual content classification with restricted labeled knowledge and designed machine-learning fashions for higher long-term forecasting for product purchases. For Kim, “it was a really clean transition and … a fantastic alternative for me to proceed working within the subject of deep studying and pc imaginative and prescient within the MIT-IBM Watson AI Lab.”
Modeling video
Collaborating with researchers from academia and trade, Kim designed, skilled, and examined a deep studying mannequin for recognizing actions throughout domains — on this case, video. His group particularly focused using artificial knowledge from generated movies for coaching and ran prediction and inference duties on actual knowledge, which consists of various motion lessons. They wished to see how pre-training fashions on artificial movies, significantly simulations of, or recreation engine-generated, people or humanoid actions stacked as much as actual knowledge: publicly obtainable movies scraped from the web.
The rationale for this analysis, Kim says, is that actual movies can have points, together with illustration bias, copyright, and/or moral or private sensitivity, e.g., movies of a automobile hitting folks can be troublesome to gather, or using folks’s faces, actual addresses, or license plates with out consent. Kim is operating experiments with 2D, 2.5D, and 3D video fashions, with the objective of making domain-specific and even a big, common, artificial video dataset that can be utilized for some switch domains, the place knowledge are missing. As an illustration, for functions to the development trade, this might embrace operating its motion recognition on a constructing website. “I did not count on synthetically generated movies to carry out on par with actual movies,” he says. “I believe that opens up a variety of totally different roles [for the work] sooner or later.”
Regardless of a rocky begin to the mission gathering and producing knowledge and operating many fashions, Kim says he wouldn’t have completed it another approach. “It was wonderful how the lab members inspired me: ‘It is OK. You will have all of the experiments and the enjoyable half coming. Do not stress an excessive amount of.’” It was this construction that helped Kim take possession of the work. “On the finish, they gave me a lot help and wonderful concepts that assist me perform this mission.”
Information labeling
Information shortage was additionally a theme of Emma Liu’s work. “The overarching drawback is that there is all this knowledge on the market on the planet, and for lots of machine studying issues, you want that knowledge to be labeled,” says Liu, “however then you’ve got all this unlabeled knowledge that is obtainable that you simply’re probably not leveraging.”
Liu, with route from her MIT and IBM group, labored to place that knowledge to make use of, coaching textual content classification semi-supervised fashions (and mixing elements of them) so as to add pseudo labels to the unlabeled knowledge, primarily based on predictions and chances about which classes every bit of beforehand unlabeled knowledge matches into. “Then the issue is that there is been prior work that is proven that you may’t all the time belief the chances; particularly, neural networks have been proven to be overconfident a variety of the time,” Liu factors out.
Liu and her group addressed this by evaluating the accuracy and uncertainty of the fashions and recalibrated them to enhance her self-training framework. The self-training and calibration step allowed her to have higher confidence within the predictions. This pseudo labeled knowledge, she says, might then be added to the pool of actual knowledge, increasing the dataset; this course of could possibly be repeated in a collection of iterations.
For Liu, her greatest takeaway wasn’t the product, however the course of. “I discovered quite a bit about being an impartial researcher,” she says. As an undergraduate, Liu labored with IBM to develop machine studying strategies to repurpose medication already available on the market and honed her decision-making capacity. After collaborating with tutorial and trade researchers to amass abilities to ask pointed questions, hunt down specialists, digest and current scientific papers for related content material, and check concepts, Liu and her cohort of MEng college students working with the MIT-IBM Watson AI Lab felt they’d confidence of their data, freedom, and suppleness to dictate their very own analysis’s route. Taking over this key function, Liu says, “I really feel like I had possession over my mission.”
Demand forecasting
After his time at MIT and with the MIT-IBM Watson AI Lab, Clemente Ocejo additionally got here away with a way of mastery, having constructed a powerful basis in AI strategies and timeseries strategies starting along with his MIT Undergraduate Analysis Alternatives Program (UROP), the place he met his MEng advisor. “You actually need to be proactive in decision-making,” says Ocejo, “vocalizing it [your choices] because the researcher and letting folks know that that is what you are doing.”
Ocejo used his background in conventional timeseries strategies for a collaboration with the lab, making use of deep studying to raised predict product demand forecasting within the medical subject. Right here, he designed, wrote, and skilled a transformer, a selected machine studying mannequin, which is usually utilized in natural-language processing and has the power to study very long-term dependencies. Ocejo and his group in contrast goal forecast calls for between months, studying dynamic connections and a focus weights between product gross sales inside a product household. They checked out identifier options, regarding the worth and quantity, in addition to account options about who’s buying the objects or providers.
“One product doesn’t essentially influence the prediction made for an additional product within the second of prediction. It simply impacts the parameters throughout coaching that result in that prediction,” says Ocejo. “As an alternative, we wished to make it have somewhat extra of a direct influence, so we added this layer that makes this connection and learns consideration between the entire merchandise in our dataset.”
In the long term, over a one-year prediction, MIT-IBM Watson AI Lab group was capable of outperform the present mannequin; extra impressively, it did so within the quick run (near a fiscal quarter). Ocejo attributes this to the dynamic of his interdisciplinary group. “A whole lot of the folks in my group weren’t essentially very skilled within the deep studying facet of issues, however they’d a variety of expertise within the provide chain administration, operations analysis, and optimization aspect, which is one thing that I haven’t got that a lot expertise in,” says Ocejo. “They had been giving a variety of good high-level suggestions of what to deal with subsequent and … and figuring out what the sphere of trade wished to see or was seeking to enhance, so it was very useful in streamlining my focus.”
For this work, a deluge of knowledge didn’t make the distinction for Ocejo and his group, however somewhat its construction and presentation. Oftentimes, giant deep studying fashions require thousands and thousands and thousands and thousands of knowledge factors with the intention to make significant inferences; nonetheless, the MIT-IBM Watson AI Lab group demonstrated that outcomes and method enhancements might be application-specific. “It simply exhibits that these fashions can study one thing helpful, in the correct setting, with the correct structure, while not having an extra quantity of knowledge,” says Ocejo. “After which with an extra quantity of knowledge, it’s going to solely get higher.”
[ad_2]

