



[ad_1]
Advances in deep studying over the previous couple of many years have been pushed by a couple of key components. With a small variety of easy however versatile mechanisms (i.e., inductive biases equivalent to convolutions or sequence consideration), more and more giant datasets, and extra specialised {hardware}, neural networks can now obtain spectacular outcomes on a variety of duties, equivalent to picture classification, machine translation, and protein folding prediction.
Nevertheless, using giant fashions and datasets comes on the expense of important computational necessities. But, current works recommend that giant mannequin sizes is perhaps vital for sturdy generalization and robustness, so coaching giant fashions whereas limiting useful resource necessities is changing into more and more vital. One promising strategy entails using conditional computation: relatively than activating the entire community for each single enter, totally different elements of the mannequin are activated for various inputs. This paradigm has been featured within the Pathways imaginative and prescient and up to date works on giant language fashions, whereas it has not been nicely explored within the context of pc imaginative and prescient.
In “Scaling Imaginative and prescient with Sparse Combination of Specialists”, we current V-MoE, a brand new imaginative and prescient structure primarily based on a sparse combination of specialists, which we then use to coach the most important imaginative and prescient mannequin up to now. We switch V-MoE to ImageNet and show matching state-of-the-art accuracy whereas utilizing about 50% fewer assets than fashions of comparable efficiency. We now have additionally open-sourced the code to coach sparse fashions and supplied a number of pre-trained fashions.
Imaginative and prescient Combination of Specialists (V-MoEs)
Imaginative and prescient Transformers (ViT) have emerged as probably the greatest architectures for imaginative and prescient duties. ViT first partitions a picture into equally-sized sq. patches. These are known as tokens, a time period inherited from language fashions. Nonetheless, in comparison with the most important language fashions, ViT fashions are a number of orders of magnitude smaller when it comes to variety of parameters and compute.
To massively scale imaginative and prescient fashions, we substitute some dense feedforward layers (FFN) within the ViT structure with a sparse combination of unbiased FFNs (which we name specialists). A learnable router layer selects which specialists are chosen (and the way they’re weighted) for each particular person token. That’s, totally different tokens from the identical picture could also be routed to totally different specialists. Every token is simply routed to at most Ok (sometimes 1 or 2) specialists, amongst a complete of E specialists (in our experiments, E is often 32). This enables scaling the mannequin’s measurement whereas retaining its computation per token roughly fixed. The determine beneath reveals the construction of the encoder blocks in additional element.
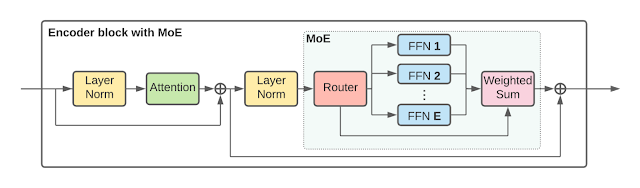 |
| V-MoE Transformer Encoder block. |
Experimental Outcomes
We first pre-train the mannequin as soon as on JFT-300M, a big dataset of photographs. The left plot beneath reveals our pre-training outcomes for fashions of all sizes: from the small S/32 to the large H/14.
We then switch the mannequin to new downstream duties (equivalent to ImageNet), through the use of a brand new head (the final layer in a mannequin). We discover two switch setups: both fine-tuning your complete mannequin on all out there examples of the brand new activity, or freezing the pre-trained community and tuning solely the brand new head utilizing a couple of examples (generally known as few-shot switch). The proper plot within the determine beneath summarizes our switch outcomes to ImageNet, coaching on solely 5 photographs per class (known as 5-shot switch).
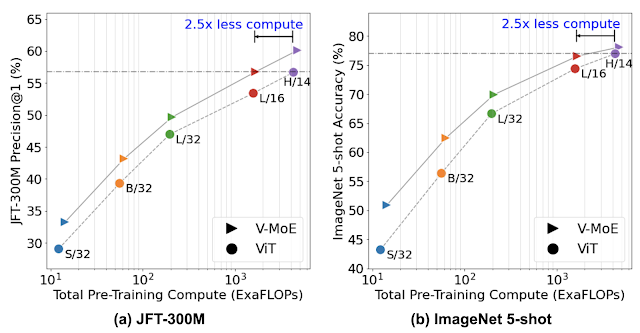 |
| JFT-300M Precision@1 and ImageNet 5-shot accuracy. Colours characterize totally different ViT variants and markers characterize both normal ViT (●), or V-MoEs (▸) with professional layers on the final n even blocks. We set n=2 for all fashions, besides V-MoE-H the place n=5. Increased signifies higher efficiency, with extra environment friendly fashions being to the left. |
In each instances, the sparse mannequin strongly outperforms its dense counterpart at a given quantity of coaching compute (proven by the V-MoE line being above the ViT line), or achieves comparable efficiency a lot sooner (proven by the V-MoE line being to the left of the ViT line).
To discover the bounds of imaginative and prescient fashions, we skilled a 15-billion parameter mannequin with 24 MoE layers (out of 48 blocks) on an prolonged model of JFT-300M. This huge mannequin — the most important up to now in imaginative and prescient so far as we all know — achieved 90.35% check accuracy on ImageNet after fine-tuning, close to the present state-of-the-art.
Precedence Routing
In apply, because of {hardware} constraints, it’s not environment friendly to make use of buffers with a dynamic measurement, so fashions sometimes use a pre-defined buffer capability for every professional. Assigned tokens past this capability are dropped and never processed as soon as the professional turns into “full”. As a consequence, greater capacities yield greater accuracy, however they’re additionally extra computationally costly.
We leverage this implementation constraint to make V-MoEs sooner at inference time. By lowering the whole mixed buffer capability beneath the variety of tokens to be processed, the community is pressured to skip processing some tokens within the professional layers. As an alternative of selecting the tokens to skip in some arbitrary trend (as earlier works did), the mannequin learns to type tokens in response to an significance rating. This maintains top quality predictions whereas saving a number of compute. We check with this strategy as Batch Precedence Routing (BPR), illustrated beneath.
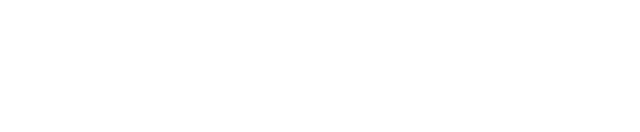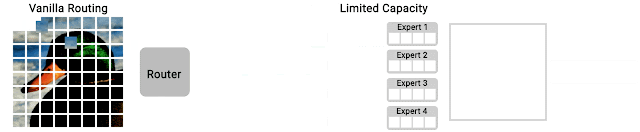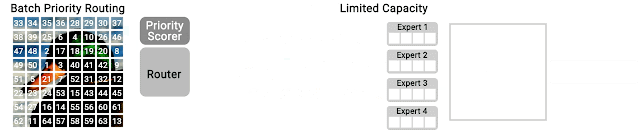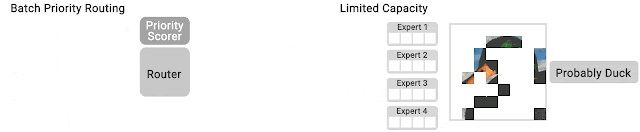 |
| Beneath excessive capability, each vanilla and precedence routing work nicely as all patches are processed. Nevertheless, when the buffer measurement is decreased to save lots of compute, vanilla routing selects arbitrary patches to course of, typically resulting in poor predictions. BPR well prioritizes vital patches leading to higher predictions at decrease computational prices. |
Dropping the best tokens seems to be important to ship high-quality and extra environment friendly inference predictions. When the professional capability decreases, efficiency shortly decreases with the vanilla routing mechanism. Conversely, BPR is far more sturdy to low capacities.
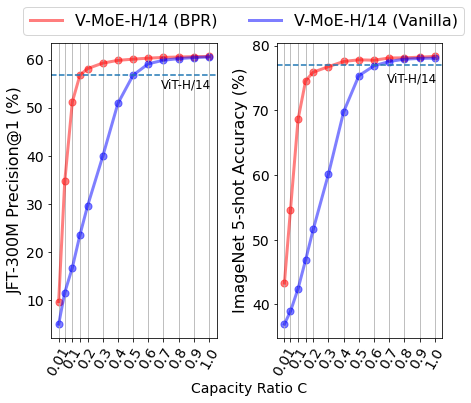 |
| Efficiency versus inference capability buffer measurement (or ratio) C for a V-MoE-H/14 mannequin with Ok=2. Even for giant C’s, BPR improves efficiency; at low C the distinction is kind of important. BPR is aggressive with dense fashions (ViT-H/14) by processing solely 15-30% of the tokens. |
Total, we noticed that V-MoEs are extremely versatile at inference time: as an illustration, one can lower the variety of chosen specialists per token to save lots of time and compute, with none additional coaching on the mannequin weights.
Exploring V-MoEs
As a result of a lot is but to be found in regards to the inner workings of sparse networks, we additionally explored the routing patterns of the V-MoE.
One speculation is that routers would study to discriminate and assign tokens to specialists primarily based on some semantic grounds (the “automobile” professional, the “animal” specialists, and so forth). To check this, beneath we present plots for 2 totally different MoE layers (a really early-on one, and one other nearer to the top). The x-axis corresponds to every of the 32 specialists, and the y-axis reveals the ID of the picture lessons (from 1 to 1000). Every entry within the plot reveals how typically an professional was chosen for tokens equivalent to the precise picture class, with darker colours indicating greater frequency. Whereas within the early layers there’s little correlation, later within the community, every professional receives and processes tokens from solely a handful of lessons. Due to this fact, we are able to conclude that some semantic clustering of the patches emerges within the deeper layers of the community.
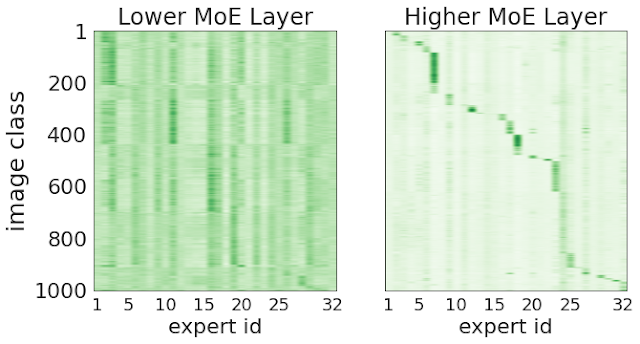 |
| Increased routing selections correlate with picture lessons. We present two MoE layers of a V-MoE-H/14. The x-axis corresponds to the 32 specialists in a layer. The y-axis are the 1000 ImageNet lessons; orderings for each axes are totally different throughout plots (to focus on correlations). For every pair (professional e, class c) we present the typical routing weight for the tokens equivalent to all photographs with class c for that individual professional e. |
Last Ideas
We prepare very giant imaginative and prescient fashions utilizing conditional computation, delivering important enhancements in illustration and switch studying for comparatively little coaching value. Alongside V-MoE, we launched BPR, which requires the mannequin to course of solely essentially the most helpful tokens within the professional layers.
We imagine that is only the start of conditional computation at scale for pc imaginative and prescient; extensions embody multi-modal and multi-task fashions, scaling up the professional depend, and enhancing switch of the representations produced by sparse fashions. Heterogeneous professional architectures and conditional variable-length routes are additionally promising instructions. Sparse fashions can particularly assist in information wealthy domains equivalent to large-scale video modeling. We hope our open-source code and fashions assist appeal to and have interaction researchers new to this discipline.
Acknowledgments
We thank our co-authors: Basil Mustafa, Maxim Neumann, Rodolphe Jenatton, André Susano Pinto, Daniel Keysers, and Neil Houlsby. We thank Alex Kolesnikov, Lucas Beyer, and Xiaohua Zhai for offering steady assist and particulars about scaling ViT fashions. We’re additionally grateful to Josip Djolonga, Ilya Tolstikhin, Liam Fedus, and Barret Zoph for suggestions on the paper; James Bradbury, Roy Frostig, Blake Hechtman, Dmitry Lepikhin, Anselm Levskaya, and Parker Schuh for invaluable help serving to us run our JAX fashions effectively on TPUs; and plenty of others from the Mind crew for his or her help. Lastly, we might additionally wish to thank and acknowledge Tom Small for the superior animated determine used on this publish.
[ad_2]

