



[ad_1]
New analysis developed at Adobe is providing the primary viable and efficient deepfakes technique based mostly on Neural Radiance Fields (NeRF) – maybe the primary actual innovation in structure or method within the 5 years because the emergence of deepfakes in 2017.
The strategy, titled RigNeRF, makes use of 3D morphable face fashions (3DMMs) as an interstitial layer of instrumentality between the specified enter (i.e. the identification to be imposed into the NeRF render) and the neural house, a technique that has been broadly adopted lately by Generative Adversarial Community (GAN) face synthesis approaches, none of which have but produced useful and helpful face-replacement frameworks for video.
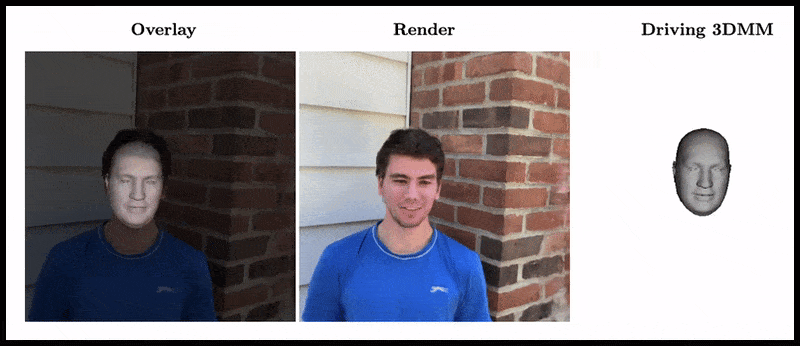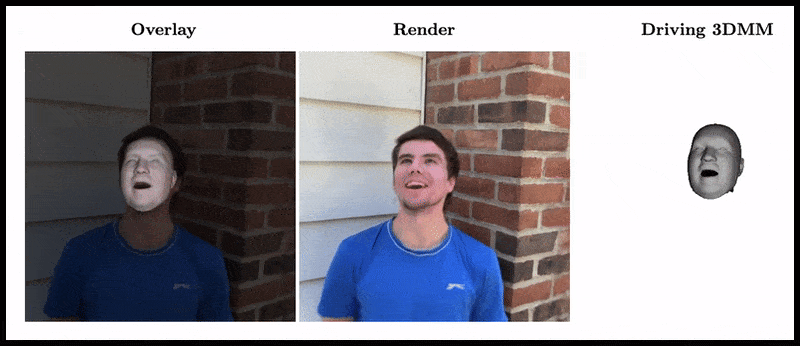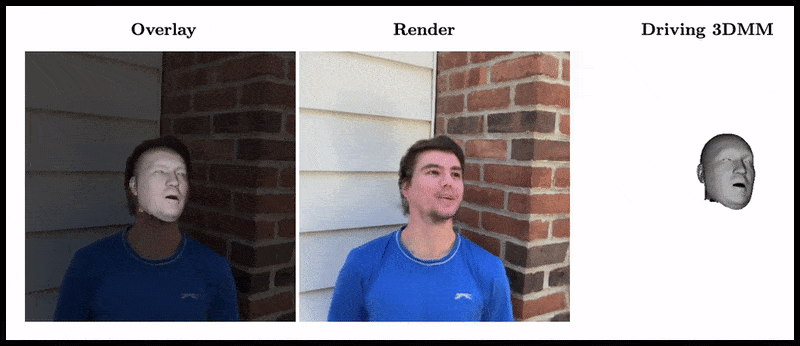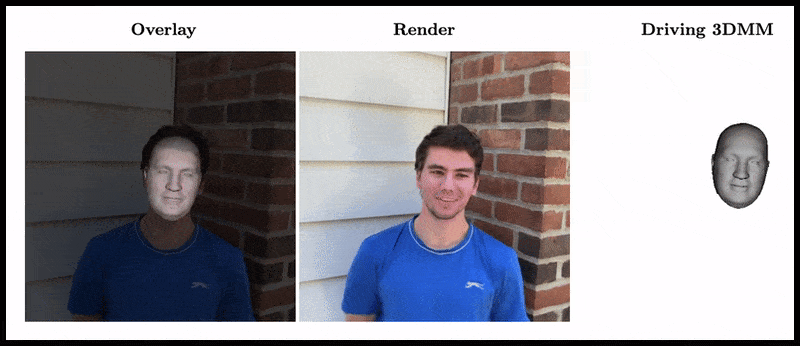
In contrast to conventional deepfake movies, completely not one of the shifting content material pictured right here is ‘actual’, however reasonably is an explorable neural house that was skilled on temporary footage. On the proper we see the 3D morphable face mannequin (3DMM) appearing as an interface between the specified manipulations (‘smile’, ‘look left’, ‘lookup’, and so forth.) and the usually-intractable parameters of a Neural Radiance Discipline visualization. For a high-resolution model of this clip, together with different examples, see the venture web page, or the embedded movies on the finish of this text. Supply: https://shahrukhathar.github.io/2022/06/06/RigNeRF.html
3DMMs are successfully CGI fashions of faces, the parameters of which will be tailored to extra summary picture synthesis techniques, resembling NeRF and GAN, that are in any other case tough to manage.
What you’re seeing within the picture above (center picture, man in blue shirt), in addition to the picture straight beneath (left picture, man in blue shirt), is just not a ‘actual’ video into which a small patch of ‘pretend’ face has been superimposed, however a wholly synthesized scene that exists solely as a volumetric neural rendering – together with the physique and background:
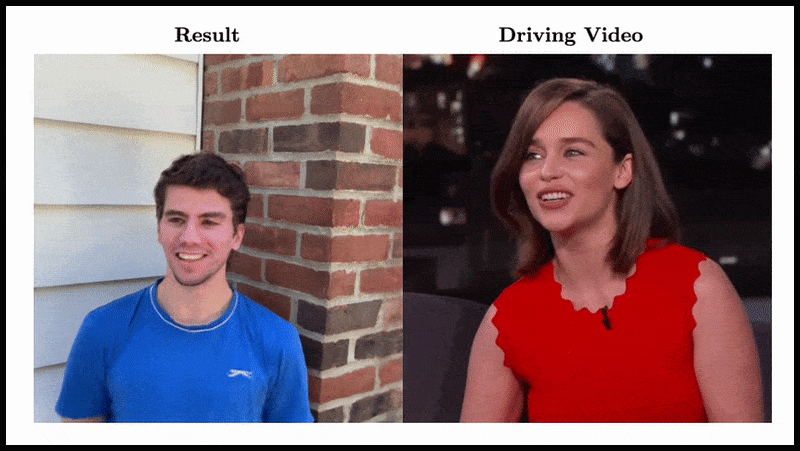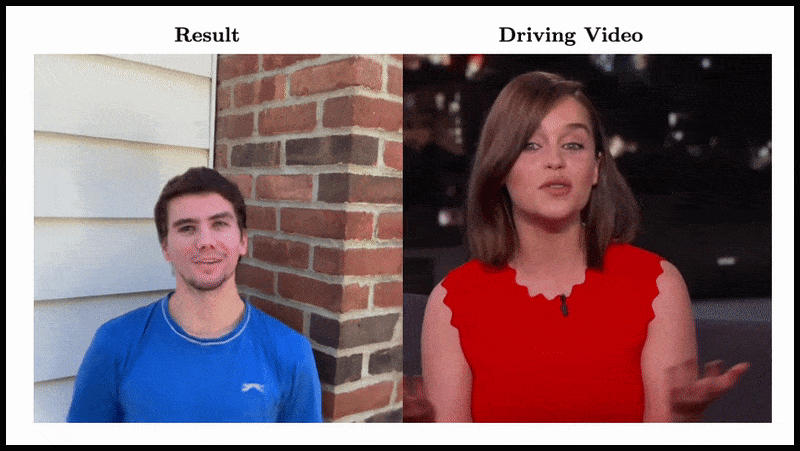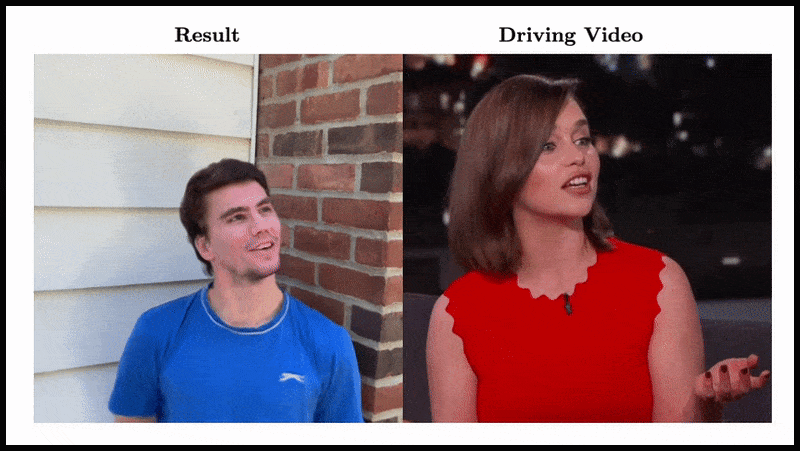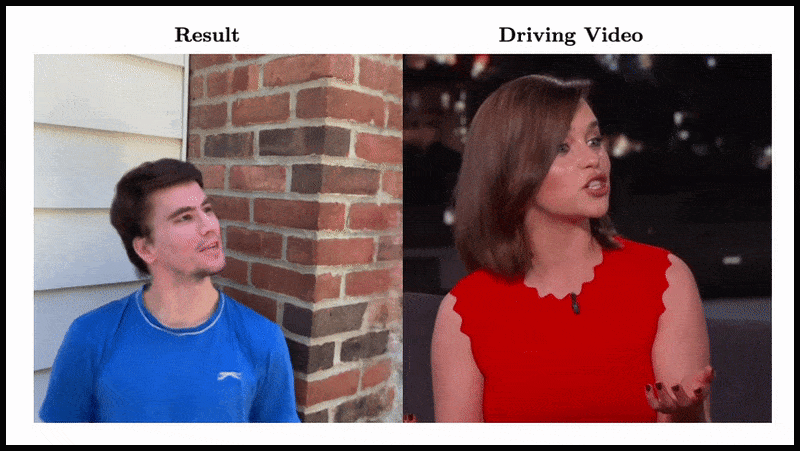
Within the instance straight above, the real-life video on the proper (girl in pink gown) is used to ‘puppet’ the captured identification (man in blue shirt) on the left by way of RigNeRF, which (the authors declare) is the primary NeRF-based system to attain separation of pose and expression whereas with the ability to carry out novel view syntheses.
The male determine on the left within the picture above was ‘captured’ from a 70-second smartphone video, and the enter information (together with the whole scene data) subsequently skilled throughout 4 V100 GPUs to acquire the scene.
Since 3DMM-style parametric rigs are additionally obtainable as entire-body parametric CGI proxies (reasonably than simply face rigs), RigNeRF probably opens up the potential of full-body deepfakes the place actual human motion, texture and expression is handed to the CGI-based parametric layer, which might then translate motion and expression into rendered NeRF environments and movies.
As for RigNeRF – does it qualify as a deepfake technique within the present sense that the headlines perceive the time period? Or is it simply one other semi-hobbled also-ran to DeepFaceLab and different labor-intensive, 2017-era autoencoder deepfake techniques?
The brand new paper’s researchers are unambiguous on this level:
‘Being a technique that’s able to reanimating faces, RigNeRF is liable to misuse by unhealthy actors to generate deep-fakes.’
The brand new paper is titled RigNeRF: Totally Controllable Neural 3D Portraits, and comes from ShahRukh Atha of Stonybrook College, an intern at Adobe throughout RigNeRF’s growth, and 4 different authors from Adobe Analysis.
Past Autoencoder-Primarily based Deepfakes
The vast majority of viral deepfakes which have captured headlines over the previous couple of years are produced by autoencoder-based techniques, derived from the code that was printed on the promptly-banned r/deepfakes subreddit in 2017 – although not earlier than being copied over to GitHub, the place it has at the moment been forked over a thousand occasions, not least into the favored (if controversial) DeepFaceLab distribution, and in addition the FaceSwap venture.
In addition to GAN and NeRF, autoencoder frameworks have additionally experimented with 3DMMs as ‘pointers’ for improved facial synthesis frameworks. An instance of that is the HifiFace venture from July of 2021. Nevertheless, no usable or standard initiatives appear to have developed from this method thus far.
Knowledge for RigNeRF scenes are obtained by capturing brief smartphone movies. For the venture, RigNeRF’s researchers used an iPhone XR or an iPhone 12 for all experiments. For the primary half of the seize, the topic is requested to carry out a variety of facial expressions and speech whereas conserving their head nonetheless because the digital camera is moved round them.
For the second half of the seize, the digital camera maintains a hard and fast place whereas the topic should transfer their head round while evincing a variety of expressions. The resultant 40-70 seconds of footage (round 1200-2100 frames) symbolize the whole dataset that might be used to coach the mannequin.
Chopping Down on Knowledge-Gathering
Against this, autoencoder techniques resembling DeepFaceLab require the comparatively laborious gathering and curation of 1000’s of various pictures, usually taken from YouTube movies and different social media channels, in addition to from motion pictures (within the case of celeb deepfakes).
The resultant skilled autoencoder fashions are sometimes meant for use in quite a lot of conditions. Nevertheless, essentially the most fastidious ‘celeb’ deepfakers could prepare whole fashions from scratch for a single video, even though coaching can take per week or extra.
Regardless of the warning word from the brand new paper’s researchers, the ‘patchwork’ and broadly-assembled datasets that energy AI porn in addition to standard YouTube/TikTok ‘deepfake recastings’ appear unlikely to provide acceptable and constant leads to a deepfake system resembling RigNeRF, which has a scene-specific methodology. Given the restrictions on information seize outlined within the new work, this might show, to some extent, an extra safeguard in opposition to informal misappropriation of identification by malicious deepfakers.
Adapting NeRF to Deepfake Video
NeRF is a photogrammetry-based technique through which a small variety of supply footage taken from varied viewpoints are assembled into an explorable 3D neural house. This method got here to prominence earlier this 12 months when NVIDIA unveiled its On the spot NeRF system, able to slicing the exorbitant coaching occasions for NeRF all the way down to minutes, and even seconds:
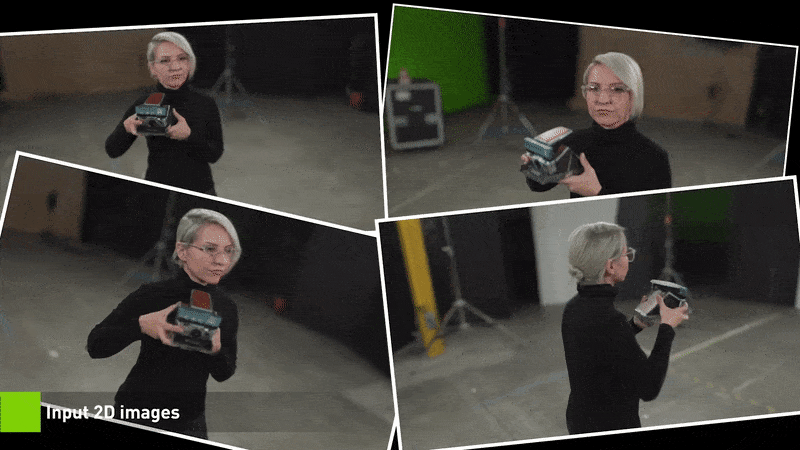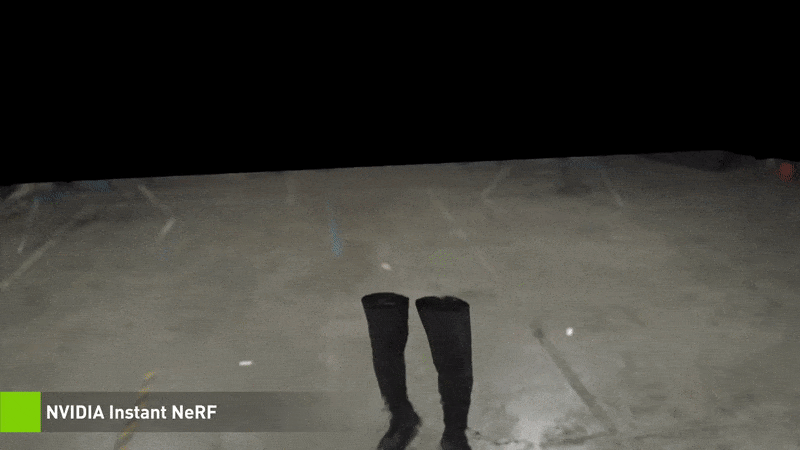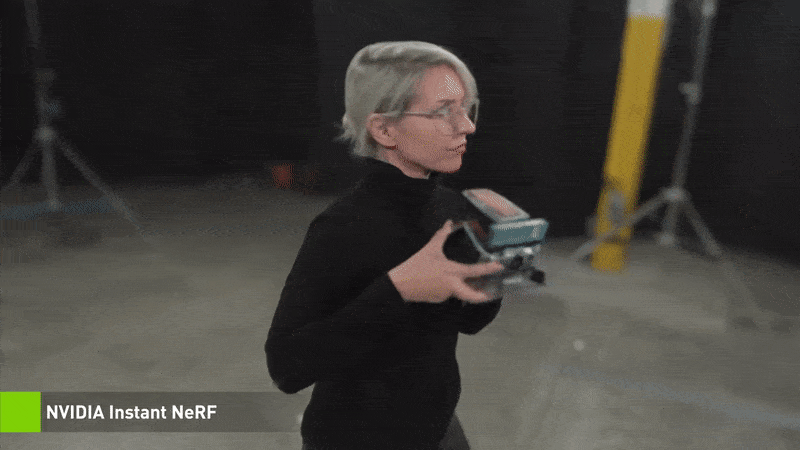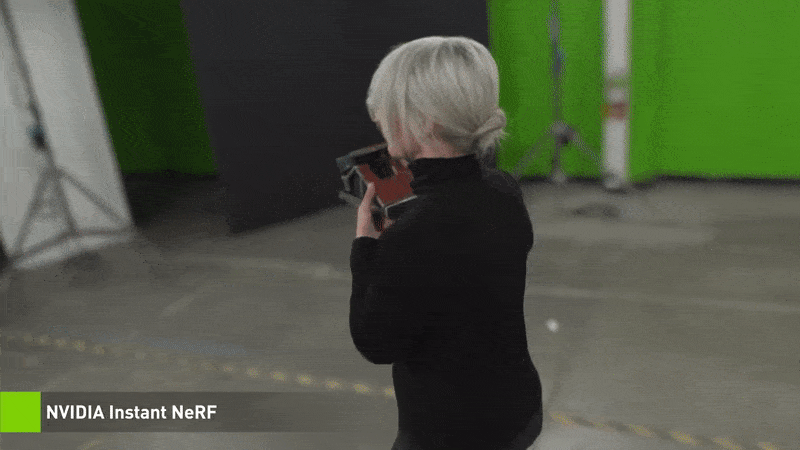
On the spot NeRF. Supply: https://www.youtube.com/watch?v=DJ2hcC1orc4
The ensuing Neural Radiance Discipline scene is basically a static setting which will be explored, however which is tough to edit. The researchers word that two prior NeRF-based initiatives – HyperNeRF + E/P and NerFACE – have taken a stab at facial video synthesis, and (apparently for the sake of completeness and diligence) have set RigNeRF in opposition to these two frameworks in a testing spherical:
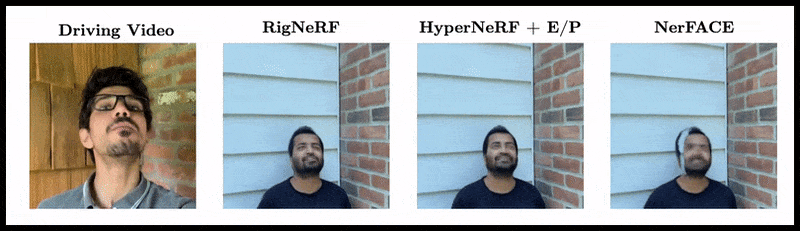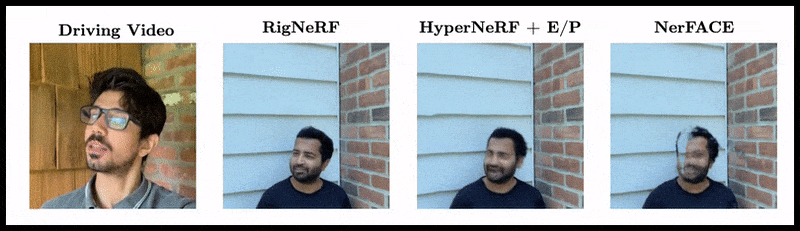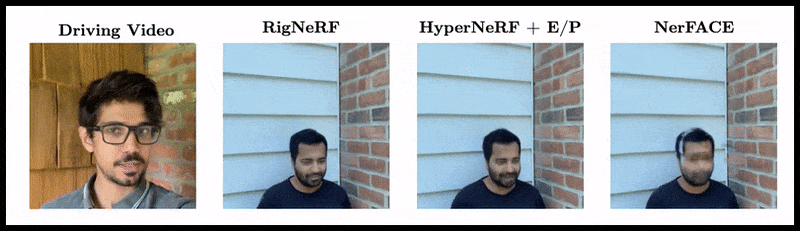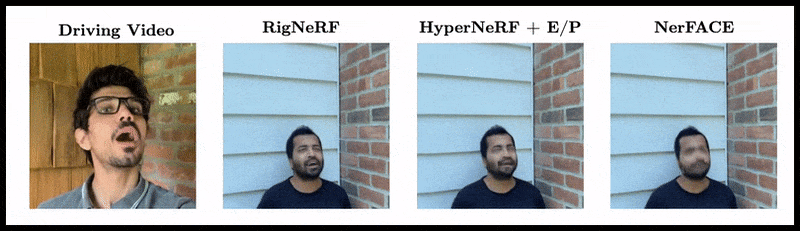

A qualitative comparability between RigNeRF, HyperNeRF, and NerFACE. See the linked supply movies and PDF for higher-quality variations. Static picture supply: https://arxiv.org/pdf/2012.03065.pdf
Nevertheless, on this case the outcomes, which favor RigNeRF, are pretty anomalous, for 2 causes: firstly, the authors observe that ‘there isn’t any current work for an apple-to-apple comparability’; secondly, this has necessitated the limiting of RigNeRF’s capabilities to not less than partially match the extra restricted performance of the prior techniques.
Because the outcomes usually are not an incremental enchancment on prior work, however reasonably symbolize a ‘breakthrough’ in NeRF editability and utility, we’ll depart the testing spherical apart, and as an alternative see what RigNeRF is doing in a different way from its predecessors.
Mixed Strengths
The first limitation of NerFACE, which may create pose/expression management in a NeRF setting, is that it assumes that supply footage might be captured with a static digital camera. This successfully implies that it can not produce novel views that reach past its seize limitations. This produces a system that may create ‘shifting portraits’, however which is unsuitable for deepfake-style video.
HyperNeRF, then again, whereas capable of generate novel and hyper-real views, has no instrumentality that enables it to vary head poses or facial expressions, which once more doesn’t end in any type of competitor for autoencoder-based deepfakes.
RigNeRF is ready to mix these two remoted functionalities by making a ‘canonical house’, a default baseline from which deviations and deformations will be enacted by way of enter from the 3DMM module.

Making a ‘canonical house’ (no pose, no expression), on which the deformations (i.e. poses and expressions) produced by way of the 3DMM can act.
Because the 3DMM system is not going to be precisely matched to the captured topic, it’s essential to compensate for this within the course of. RigNeRF accomplishes this with a deformation discipline prior that’s calculated from a Multilayer Perceptron (MLP) derived from the supply footage.

The digital camera parameters essential to calculate deformations are obtained by way of COLMAP, whereas the expression and form parameters for every body are obtained from DECA.
The positioning is additional optimized via landmark becoming and COLMAP’s digital camera parameters, and, as a consequence of computing useful resource restrictions, the video output is downsampled to 256×256 decision for coaching (a hardware-constrained shrinking course of that additionally plagues the autoencoder deepfaking scene).
After this, the deformation community is skilled on the 4 V100s – formidable {hardware} that’s not more likely to be throughout the attain of informal fanatics (nevertheless, the place machine studying coaching is anxious, it’s usually doable to commerce heft for time, and easily settle for that mannequin coaching might be a matter of days and even weeks).
In conclusion, the researchers state:
‘In distinction to different strategies, RigNeRF, due to using a 3DMM-guided deformation module, is ready to mannequin head-pose, facial expressions and the total 3D portrait scene with excessive constancy, thus giving higher reconstructions with sharp particulars.’
See the embedded movies beneath for additional particulars and outcomes footage.
First printed fifteenth June 2022.
[ad_2]

