



[ad_1]
Type-based doc understanding is a rising analysis matter due to its sensible potential for mechanically changing unstructured textual content information into structured info to achieve perception a couple of doc’s contents. Current sequence modeling, which is a self-attention mechanism that immediately fashions relationships between all phrases in a choice of textual content, has demonstrated state-of-the-art efficiency on pure language duties. A pure method to deal with kind doc understanding duties is to first serialize the shape paperwork (often in a left-to-right, top-to-bottom style) after which apply state-of-the-art sequence fashions to them.
Nonetheless, kind paperwork usually have extra advanced layouts that comprise structured objects, resembling tables, columns, and textual content blocks. Their number of format patterns makes serialization tough, considerably limiting the efficiency of strict serialization approaches. These distinctive challenges in kind doc structural modeling have been largely underexplored in literature.
 |
| An illustration of the shape doc info extraction activity utilizing an instance from the FUNSD dataset. |
In “FormNet: Structural Encoding Past Sequential Modeling in Type Doc Info Extraction”, offered at ACL 2022, we suggest a structure-aware sequence mannequin, referred to as FormNet, to mitigate the sub-optimal serialization of varieties for doc info extraction. First, we design a Wealthy Consideration (RichAtt) mechanism that leverages the 2D spatial relationship between phrase tokens for extra correct consideration weight calculation. Then, we assemble Tremendous-Tokens (tokens that combination semantically significant info from neighboring tokens) for every phrase by embedding representations from their neighboring tokens by way of a graph convolutional community (GCN). Lastly, we exhibit that FormNet outperforms present strategies, whereas utilizing much less pre-training information, and achieves state-of-the-art efficiency on the CORD, FUNSD, and Cost benchmarks.
FormNet for Info Extraction
Given a kind doc, we first use the BERT-multilingual vocabulary and optical character recognition (OCR) engine to determine and tokenize phrases. We then feed the tokens and their corresponding 2D coordinates right into a GCN for graph building and message passing. Subsequent, we use Prolonged Transformer Development (ETC) layers with the proposed RichAtt mechanism to proceed to course of the GCN-encoded structure-aware tokens for schema studying (i.e., semantic entity extraction). Lastly, we use the Viterbi algorithm, which finds a sequence that maximizes the posterior likelihood, to decode and acquire the ultimate entities for output.
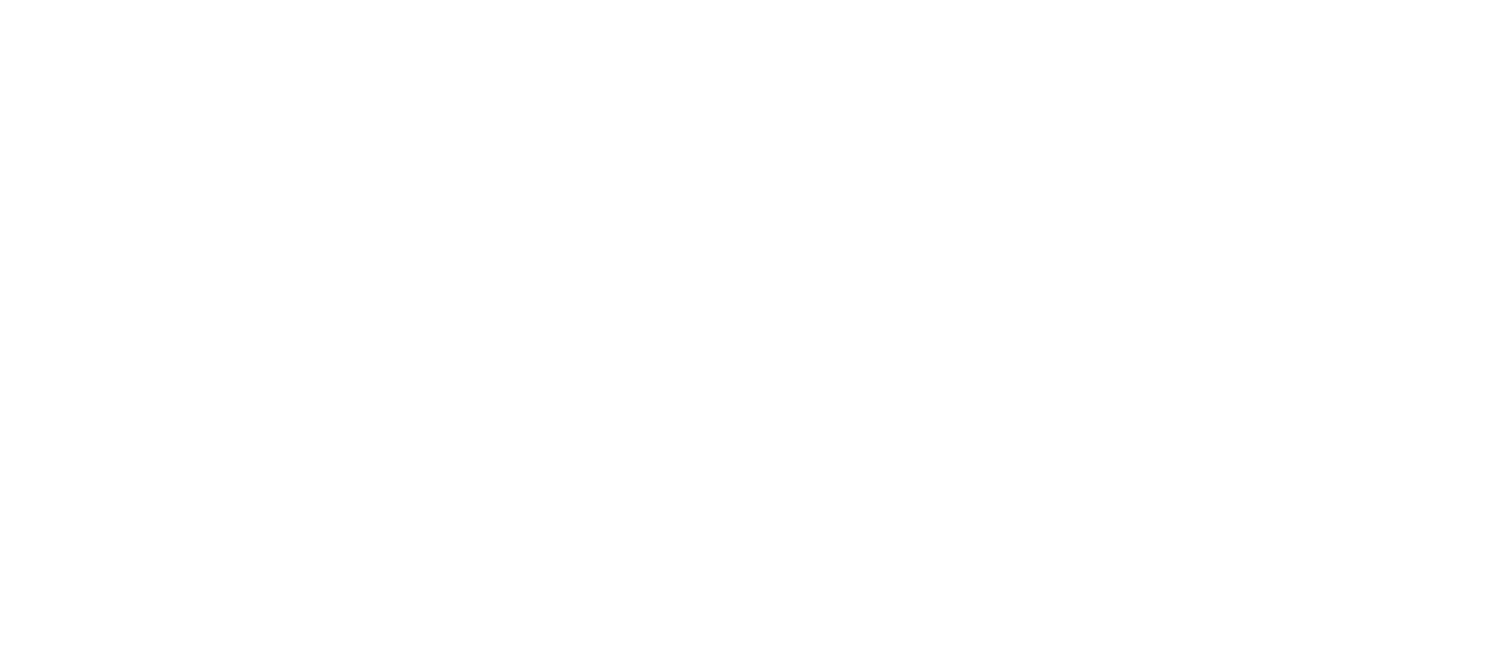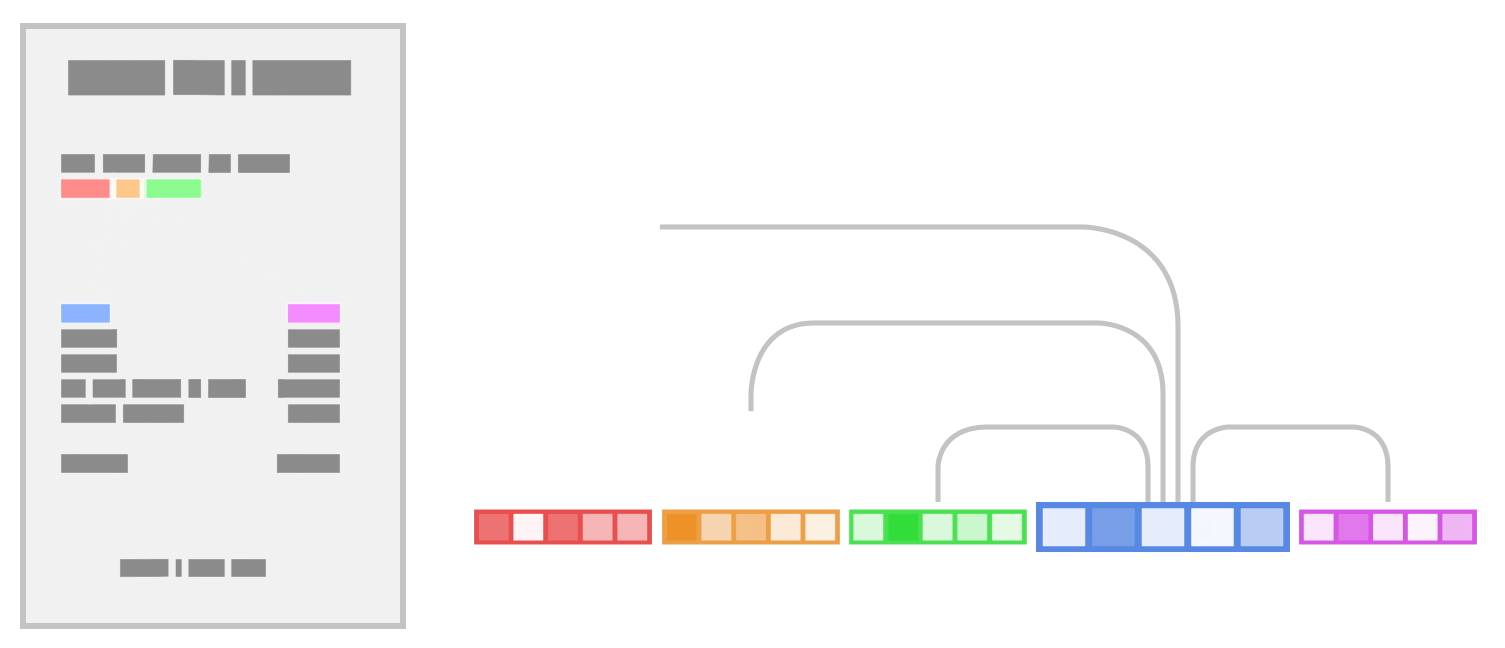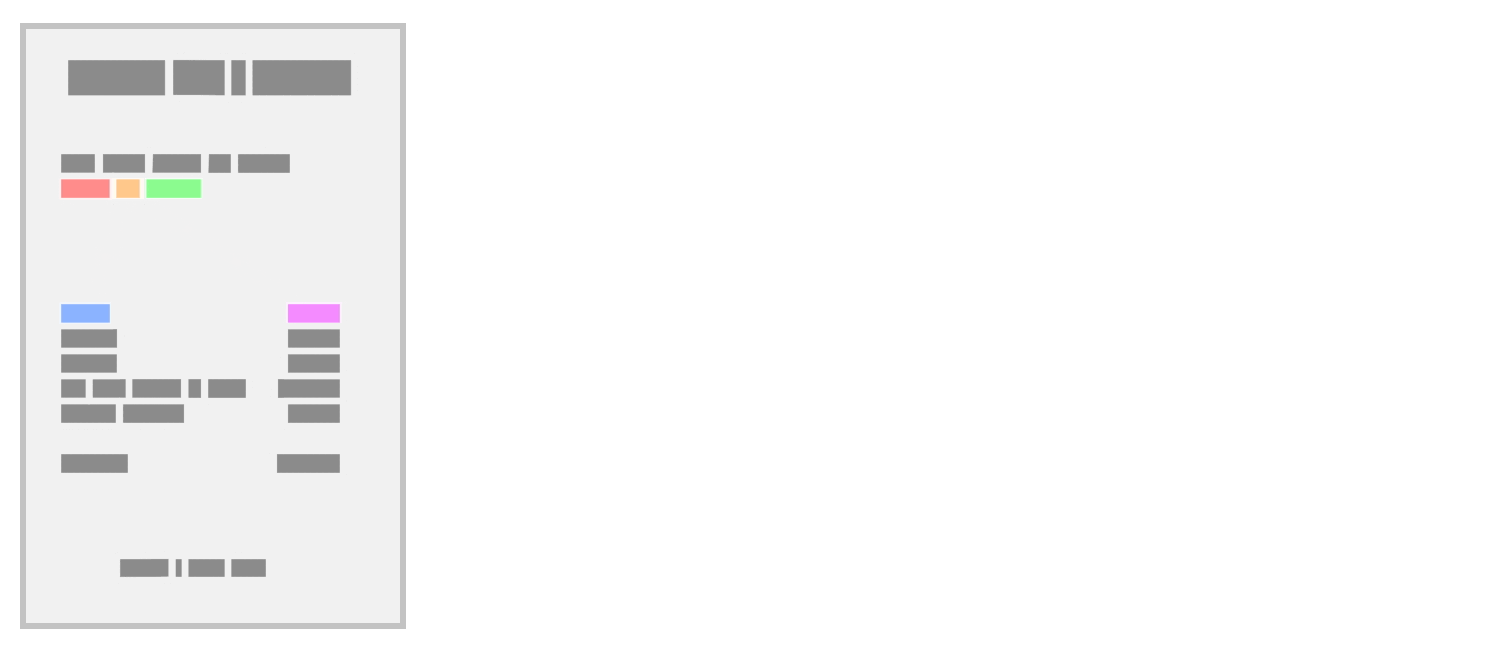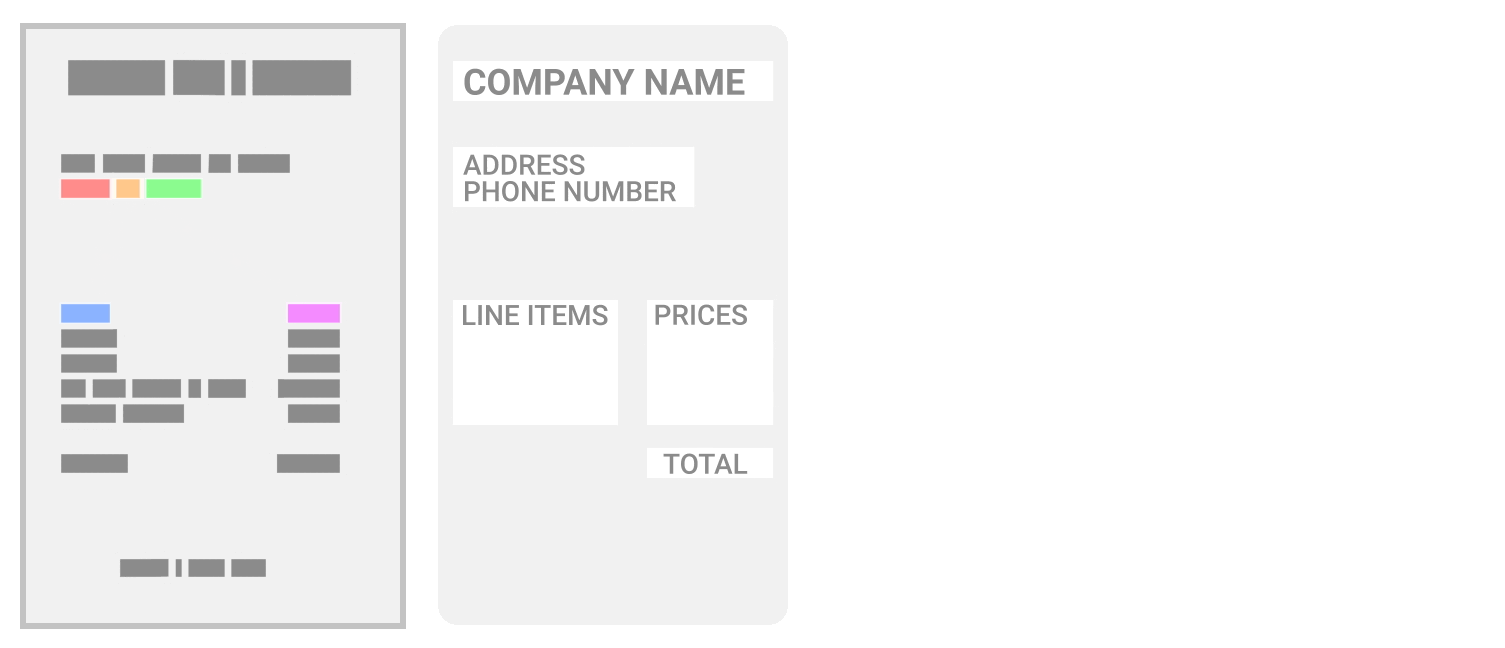 |
Prolonged Transformer Development (ETC)
We undertake ETC because the FormNet mannequin spine. ETC scales to comparatively lengthy inputs by changing customary consideration, which has quadratic complexity, with a sparse global-local consideration mechanism that distinguishes between world and lengthy enter tokens. The worldwide tokens attend to and are attended by all tokens, however the lengthy tokens attend solely domestically to different lengthy tokens inside a specified native radius, decreasing the complexity in order that it’s extra manageable for lengthy sequences.
Wealthy Consideration
Our novel structure, RichAtt, avoids the deficiencies of absolute and relative embeddings by avoiding embeddings fully. As an alternative, it computes the order of and log distance between pairs of tokens with respect to the x and y axes on the format grid, and adjusts the pre-softmax consideration scores of every pair as a direct operate of those values.
In a conventional consideration layer, every token illustration is linearly reworked right into a Question vector, a Key vector, and a Worth vector. A token “seems to be” for different tokens from which it would wish to soak up info (i.e., attend to) by discovering those with Key vectors that create comparatively excessive scores when matrix-multiplied (referred to as Matmul) by its Question vector after which softmax-normalized. The token then sums collectively the Worth vectors of all different tokens within the sentence, weighted by their rating, and passes this up the community, the place it would usually be added to the token’s unique enter vector.
Nonetheless, different options past the Question and Key vectors are sometimes related to the choice of how strongly a token ought to attend to a different given token, such because the order they’re in, what number of different tokens separate them, or what number of pixels aside they’re. With a purpose to incorporate these options into the system, we use a trainable parametric operate paired with an error community, which takes the noticed function and the output of the parametric operate and returns a penalty that reduces the dot product consideration rating.
 |
| The community makes use of the Question and Key vectors to think about what worth some low-level function (e.g., distance) ought to take if the tokens are associated, and penalizes the eye rating based mostly on the error. |
At a excessive stage, for every consideration head at every layer, FormNet examines every pair of token representations, determines the ideally suited options the tokens ought to have if there’s a significant relationship between them, and penalizes the eye rating in accordance with how totally different the precise options are from the best ones. This enables the mannequin to be taught constraints on consideration utilizing logical implication.
 |
| A visualization of how RichAtt may act on a sentence. There are three adjectives that the phrase “crow” may attend to. “Lazy” is to the precise, so it in all probability doesn’t modify “crow” and its consideration edge is penalized. “Sly” is many tokens away, so its consideration edge can also be penalized. “Crafty” receives no vital penalties, so by means of elimination, it’s the greatest candidate for consideration. |
Moreover, if one assumes that the softmax-normalized consideration scores symbolize a likelihood distribution, and the distributions for the noticed options are recognized, then this algorithm — together with the precise selection of parametric capabilities and error capabilities — falls out algebraically, which means FormNet has a mathematical correctness to it that’s missing from many alternate options (together with relative embeddings).
Tremendous-Tokens by Graph Studying
The important thing to sparsifying consideration mechanisms in ETC for lengthy sequence modeling is to have each token solely attend to tokens which can be close by within the serialized sequence. Though the RichAtt mechanism empowers the transformers by taking the spatial format buildings under consideration, poor serialization can nonetheless block vital consideration weight calculation between associated phrase tokens.
To additional mitigate the problem, we assemble a graph to attach close by tokens in a kind doc. We design the sides of the graph based mostly on sturdy inductive biases in order that they’ve greater possibilities of belonging to the identical entity sort. For every token, we receive its Tremendous-Token embedding by making use of graph convolutions alongside these edges to combination semantically related info from neighboring tokens. We then use these Tremendous-Tokens as an enter to the RichAtt ETC structure. Which means regardless that an entity might get damaged up into a number of segments because of poor serialization, the Tremendous-Tokens discovered by the GCN may have retained a lot of the context of the entity phrase.
 |
| An illustration of the word-level graph, with blue edges between tokens, of a FUNSD doc. |
Key Outcomes
The Determine under exhibits mannequin dimension vs. F1 rating (the harmonic imply of the precision and recall) for latest approaches on the CORD benchmark. FormNet-A2 outperforms the newest DocFormer whereas utilizing a mannequin that’s 2.5x smaller. FormNet-A3 achieves state-of-the-art efficiency with a 97.28% F1 rating. For extra experimental outcomes, please confer with the paper.
 |
| Mannequin Dimension vs. Entity Extraction F1 Rating on CORD benchmark. FormNet considerably outperforms different latest approaches in absolute F1 efficiency and parameter effectivity. |
We research the significance of RichAtt and Tremendous-Token by GCN on the large-scale masked language modeling (MLM) pre-training activity throughout three FormNets. Each RichAtt and GCN parts enhance upon the ETC baseline on reconstructing the masked tokens by a big margin, exhibiting the effectiveness of their structural encoding functionality on kind paperwork. The perfect efficiency is obtained when incorporating each RichAtt and GCN.
 |
| Efficiency of the Masked-Language Modeling (MLM) pre-training. Each the proposed RichAtt and Tremendous-Token by GCN parts enhance upon ETC baseline by a big margin, exhibiting the effectiveness of their structural encoding functionality on large-scale kind paperwork. |
Utilizing BertViz, we visualize the local-to-local consideration scores for particular examples from the CORD dataset for the usual ETC and FormNet fashions. Qualitatively, we affirm that the tokens attend primarily to different tokens throughout the identical visible block for FormNet. Furthermore for that mannequin, particular consideration heads are attending to tokens aligned horizontally, which is a robust sign of which means for kind paperwork. No clear consideration sample emerges for the ETC mannequin, suggesting the RichAtt and Tremendous-Token by GCN allow the mannequin to be taught the structural cues and leverage format info successfully.
 |
| The eye scores for ETC and FormNet (ETC+RichAtt+GCN) fashions. Not like the ETC mannequin, the FormNet mannequin makes tokens attend to different tokens throughout the identical visible blocks, together with tokens aligned horizontally, thus strongly leveraging structural cues. |
Conclusion
We current FormNet, a novel mannequin structure for form-based doc understanding. We decide that the novel RichAtt mechanism and Tremendous-Token parts assist the ETC transformer excel at kind understanding despite sub-optimal, noisy serialization. We exhibit that FormNet recovers native syntactic info which will have been misplaced throughout textual content serialization and achieves state-of-the-art efficiency on three benchmarks.
Acknowledgements
This analysis was performed by Chen-Yu Lee, Chun-Liang Li, Timothy Dozat, Vincent Perot, Guolong Su, Nan Hua, Joshua Ainslie, Renshen Wang, Yasuhisa Fujii, and Tomas Pfister. Due to Evan Huang, Shengyang Dai, and Salem Elie Haykal for his or her priceless suggestions, and Tom Small for creating the animation on this submit.
[ad_2]

