



[ad_1]
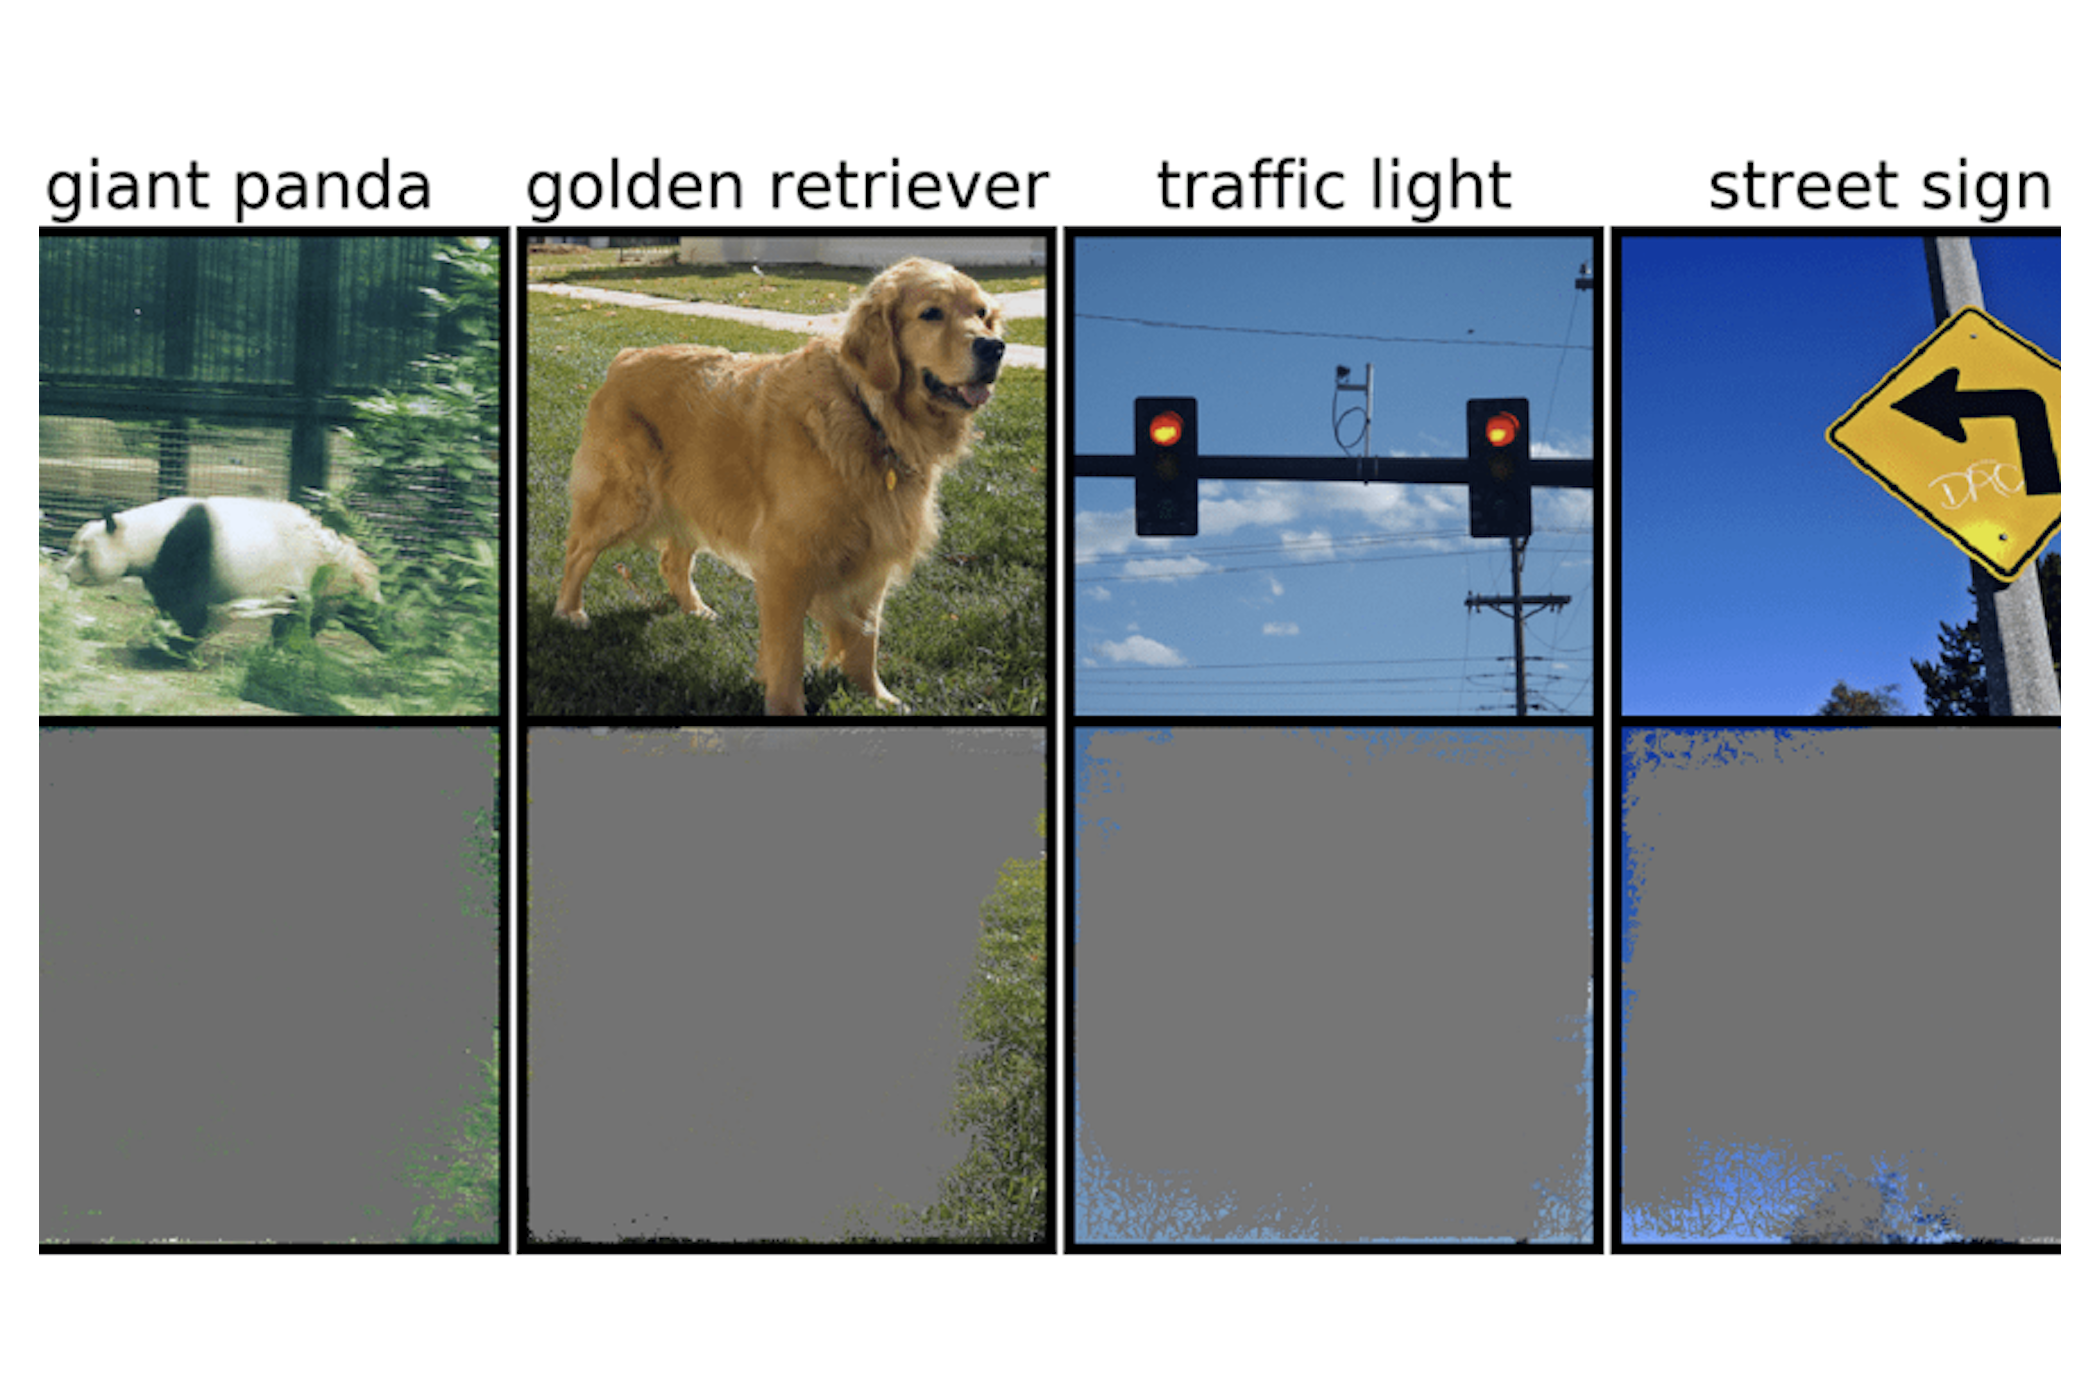
For all that neural networks can accomplish, we nonetheless don’t actually perceive how they function. Positive, we are able to program them to be taught, however making sense of a machine’s decision-making course of stays very like a elaborate puzzle with a dizzying, complicated sample the place loads of integral items have but to be fitted.
If a mannequin was making an attempt to categorise a picture of mentioned puzzle, for instance, it may encounter well-known, however annoying adversarial assaults, or much more run-of-the-mill information or processing points. However a brand new, extra refined sort of failure not too long ago recognized by MIT scientists is one other trigger for concern: “overinterpretation,” the place algorithms make assured predictions primarily based on particulars that don’t make sense to people, like random patterns or picture borders.
This could possibly be significantly worrisome for high-stakes environments, like split-second choices for self-driving vehicles, and medical diagnostics for illnesses that want extra instant consideration. Autonomous automobiles particularly rely closely on techniques that may precisely perceive environment after which make fast, protected choices. The community used particular backgrounds, edges, or specific patterns of the sky to categorise visitors lights and avenue indicators — no matter what else was within the picture.
The staff discovered that neural networks skilled on standard datasets like CIFAR-10 and ImageNet suffered from overinterpretation. Fashions skilled on CIFAR-10, for instance, made assured predictions even when 95 % of enter photos had been lacking, and the rest is not sensible to people.
“Overinterpretation is a dataset drawback that is brought on by these nonsensical alerts in datasets. Not solely are these high-confidence photos unrecognizable, however they comprise lower than 10 % of the unique picture in unimportant areas, corresponding to borders. We discovered that these photos had been meaningless to people, but fashions can nonetheless classify them with excessive confidence,” says Brandon Carter, MIT Pc Science and Synthetic Intelligence Laboratory PhD scholar and lead creator on a paper concerning the analysis.
Deep-image classifiers are extensively used. Along with medical analysis and boosting autonomous car expertise, there are use instances in safety, gaming, and even an app that tells you if one thing is or isn’t a sizzling canine, as a result of generally we’d like reassurance. The tech in dialogue works by processing particular person pixels from tons of pre-labeled photos for the community to “be taught.”
Picture classification is tough, as a result of machine-learning fashions have the flexibility to latch onto these nonsensical refined alerts. Then, when picture classifiers are skilled on datasets corresponding to ImageNet, they’ll make seemingly dependable predictions primarily based on these alerts.
Though these nonsensical alerts can result in mannequin fragility in the true world, the alerts are literally legitimate within the datasets, which means overinterpretation can’t be recognized utilizing typical analysis strategies primarily based on that accuracy.
To search out the rationale for the mannequin’s prediction on a selected enter, the strategies within the current research begin with the complete picture and repeatedly ask, what can I take away from this picture? Primarily, it retains masking up the picture, till you’re left with the smallest piece that also makes a assured determination.
To that finish, it may be potential to make use of these strategies as a sort of validation standards. For instance, you probably have an autonomously driving automotive that makes use of a skilled machine-learning technique for recognizing cease indicators, you may check that technique by figuring out the smallest enter subset that constitutes a cease signal. If that consists of a tree department, a selected time of day, or one thing that is not a cease signal, you may be involved that the automotive would possibly come to a cease at a spot it isn’t speculated to.
Whereas it could appear that the mannequin is the seemingly perpetrator right here, the datasets usually tend to blame. “There’s the query of how we are able to modify the datasets in a means that will allow fashions to be skilled to extra carefully mimic how a human would take into consideration classifying photos and due to this fact, hopefully, generalize higher in these real-world situations, like autonomous driving and medical analysis, in order that the fashions haven’t got this nonsensical habits,” says Carter.
This will likely imply creating datasets in additional managed environments. Presently, it’s simply footage which might be extracted from public domains which might be then categorized. However if you wish to do object identification, for instance, it may be mandatory to coach fashions with objects with an uninformative background.
This work was supported by Schmidt Futures and the Nationwide Institutes of Well being. Carter wrote the paper alongside Siddhartha Jain and Jonas Mueller, scientists at Amazon, and MIT Professor David Gifford. They’re presenting the work on the 2021 Convention on Neural Info Processing Methods.
[ad_2]

