


[ad_1]
An indication of the RvS coverage we be taught with simply supervised studying and a depth-two MLP. It makes use of no TD studying, benefit reweighting, or Transformers!
Offline reinforcement studying (RL) is conventionally approached utilizing value-based strategies based mostly on temporal distinction (TD) studying. Nonetheless, many latest algorithms reframe RL as a supervised studying drawback. These algorithms be taught conditional insurance policies by conditioning on objective states (Lynch et al., 2019; Ghosh et al., 2021), reward-to-go (Kumar et al., 2019; Chen et al., 2021), or language descriptions of the duty (Lynch and Sermanet, 2021).
We discover the simplicity of those strategies fairly interesting. If supervised studying is sufficient to remedy RL issues, then offline RL might develop into extensively accessible and (comparatively) simple to implement. Whereas TD studying should delicately stability an actor coverage with an ensemble of critics, these supervised studying strategies practice only one (conditional) coverage, and nothing else!
So, how can we use these strategies to successfully remedy offline RL issues? Prior work places ahead numerous intelligent suggestions and tips, however these tips are generally contradictory, making it difficult for practitioners to determine tips on how to efficiently apply these strategies. For instance, RCPs (Kumar et al., 2019) require rigorously reweighting the coaching knowledge, GCSL (Ghosh et al., 2021) requires iterative, on-line knowledge assortment, and Choice Transformer (Chen et al., 2021) makes use of a Transformer sequence mannequin because the coverage community.
Which, if any, of those hypotheses are right? Do we have to reweight our coaching knowledge based mostly on estimated benefits? Are Transformers essential to get a high-performing coverage? Are there different crucial design choices which have been neglected of prior work?
Our work goals to reply these questions by making an attempt to establish the important parts of offline RL through supervised studying. We run experiments throughout 4 suites, 26 environments, and eight algorithms. When the mud settles, we get aggressive efficiency in each setting suite we think about using remarkably easy parts. The video above exhibits the advanced conduct we be taught utilizing simply supervised studying with a depth-two MLP – no TD studying, knowledge reweighting, or Transformers!
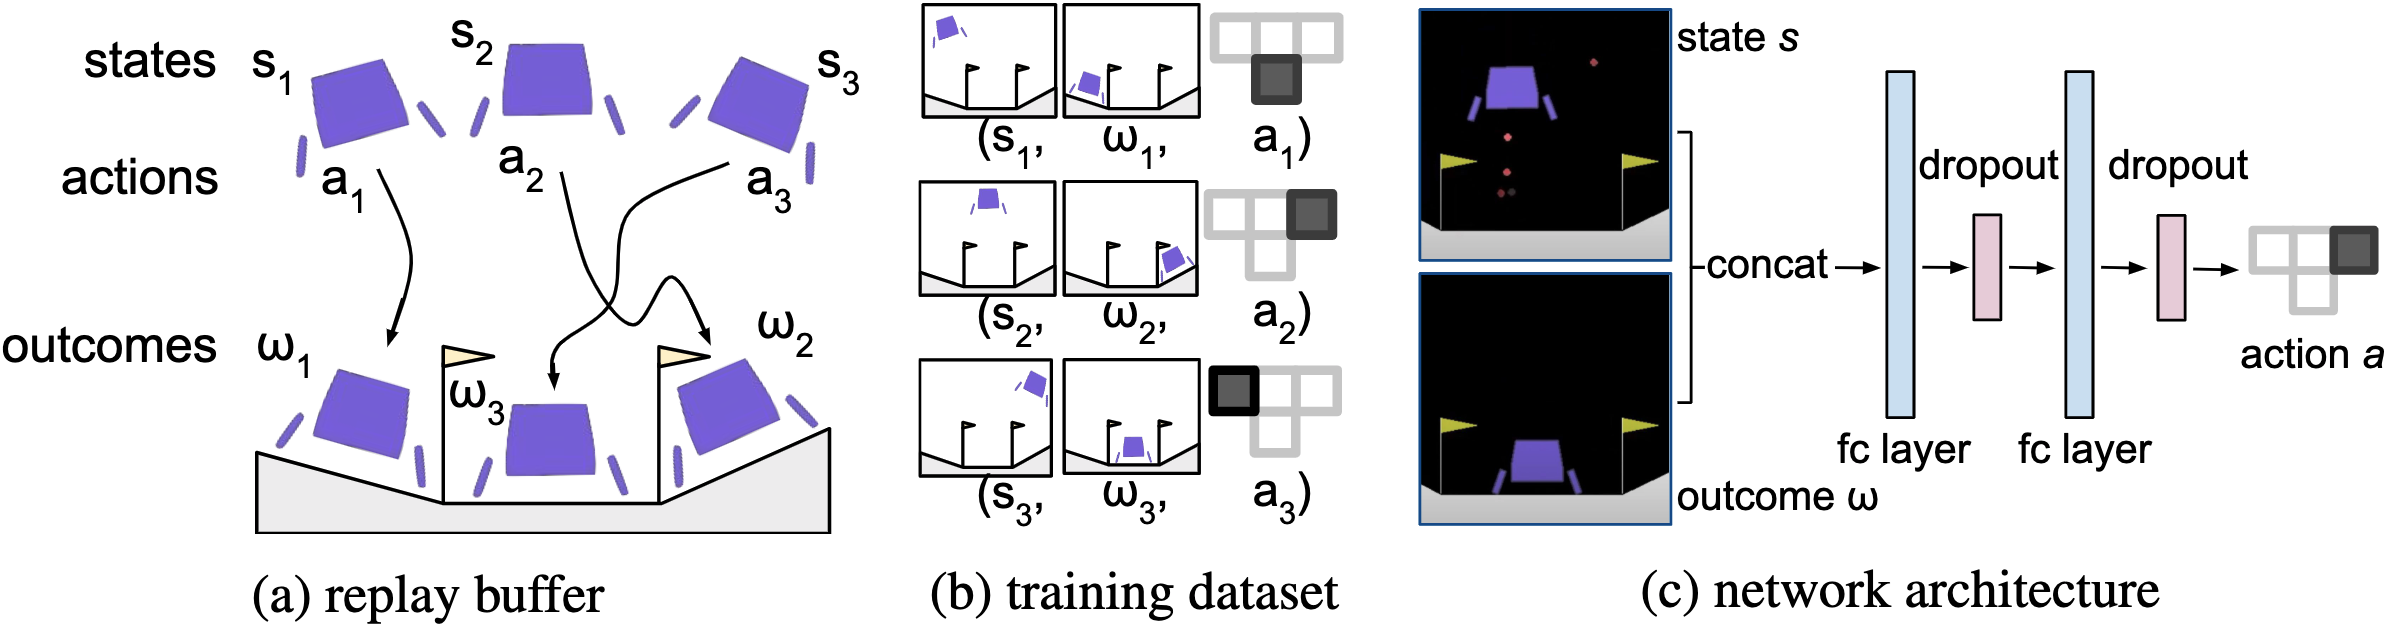
Let’s start with an outline of the algorithm we research. Whereas numerous prior work (Kumar et al., 2019; Ghosh et al., 2021; and Chen et al., 2021) share the identical core algorithm, it lacks a standard identify. To fill this hole, we suggest the time period RL through Supervised Studying (RvS). We’re not proposing any new algorithm however slightly exhibiting how prior work will be seen from a unifying framework; see Determine 1.
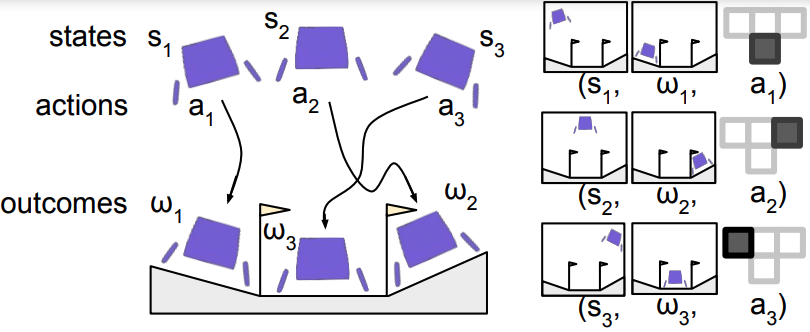
Determine 1. (Left) A replay buffer of expertise (Proper) Hindsight relabelled coaching knowledge
RL through Supervised Studying takes as enter a replay buffer of expertise together with states, actions, and outcomes. The outcomes will be an arbitrary perform of the trajectory, together with a objective state, reward-to-go, or language description. Then, RvS performs hindsight relabeling to generate a dataset of state, motion, and final result triplets. The instinct is that the actions which can be noticed present supervision for the outcomes which can be reached. With this coaching dataset, RvS performs supervised studying by maximizing the probability of the actions given the states and outcomes. This yields a conditional coverage that may situation on arbitrary outcomes at check time.
In our experiments, we give attention to the next three key questions.
- Which design choices are crucial for RL through supervised studying?
- How properly does RL through supervised studying really work? We will do RL through supervised studying, however would utilizing a distinct offline RL algorithm carry out higher?
- What kind of final result variable ought to we situation on? (And does it even matter?)
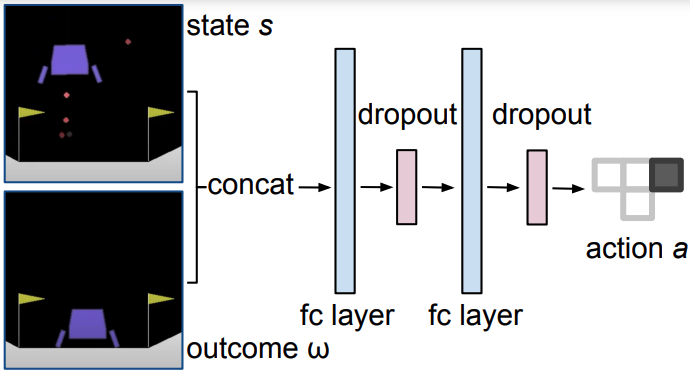
Determine 2. Our RvS structure. A depth-two MLP suffices in each setting suite we contemplate.
We get good efficiency utilizing only a depth-two multi-layer perceptron. The truth is, that is aggressive with all beforehand printed architectures we’re conscious of, together with a Transformer sequence mannequin. We simply concatenate the state and final result earlier than passing them by two fully-connected layers (see Determine 2). The keys that we establish are having a community with massive capability – we use width 1024 – in addition to dropout in some environments. We discover that this works properly with out reweighting the coaching knowledge or performing any extra regularization.
After figuring out these key design choices, we research the general efficiency of RvS compared to earlier strategies. This weblog submit will overview outcomes from two of the suites we contemplate within the paper.
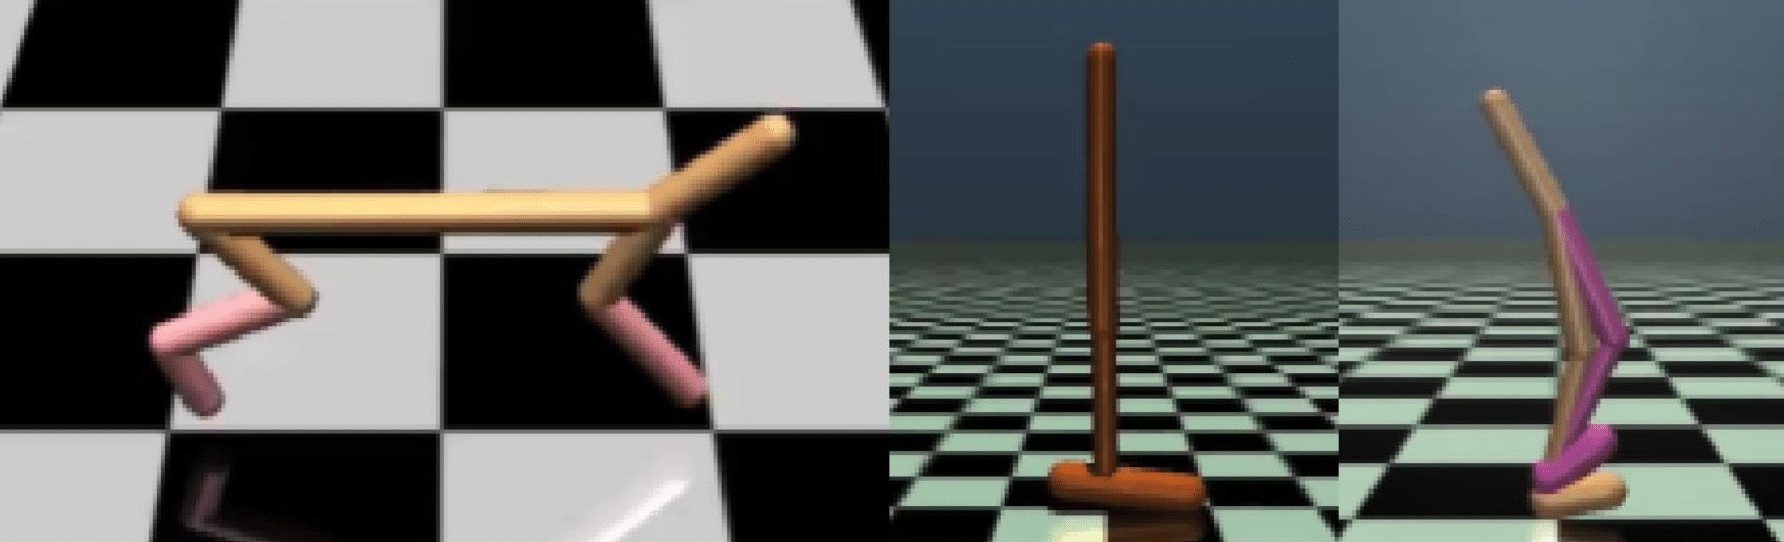
The primary suite is D4RL Gymnasium, which accommodates the usual MuJoCo halfcheetah, hopper, and walker robots. The problem in D4RL Gymnasium is to be taught locomotion insurance policies from offline datasets of various high quality. For instance, one offline dataset accommodates rollouts from a very random coverage. One other dataset accommodates rollouts from a “medium” coverage skilled partway to convergence, whereas one other dataset is a mix of rollouts from medium and knowledgeable insurance policies.
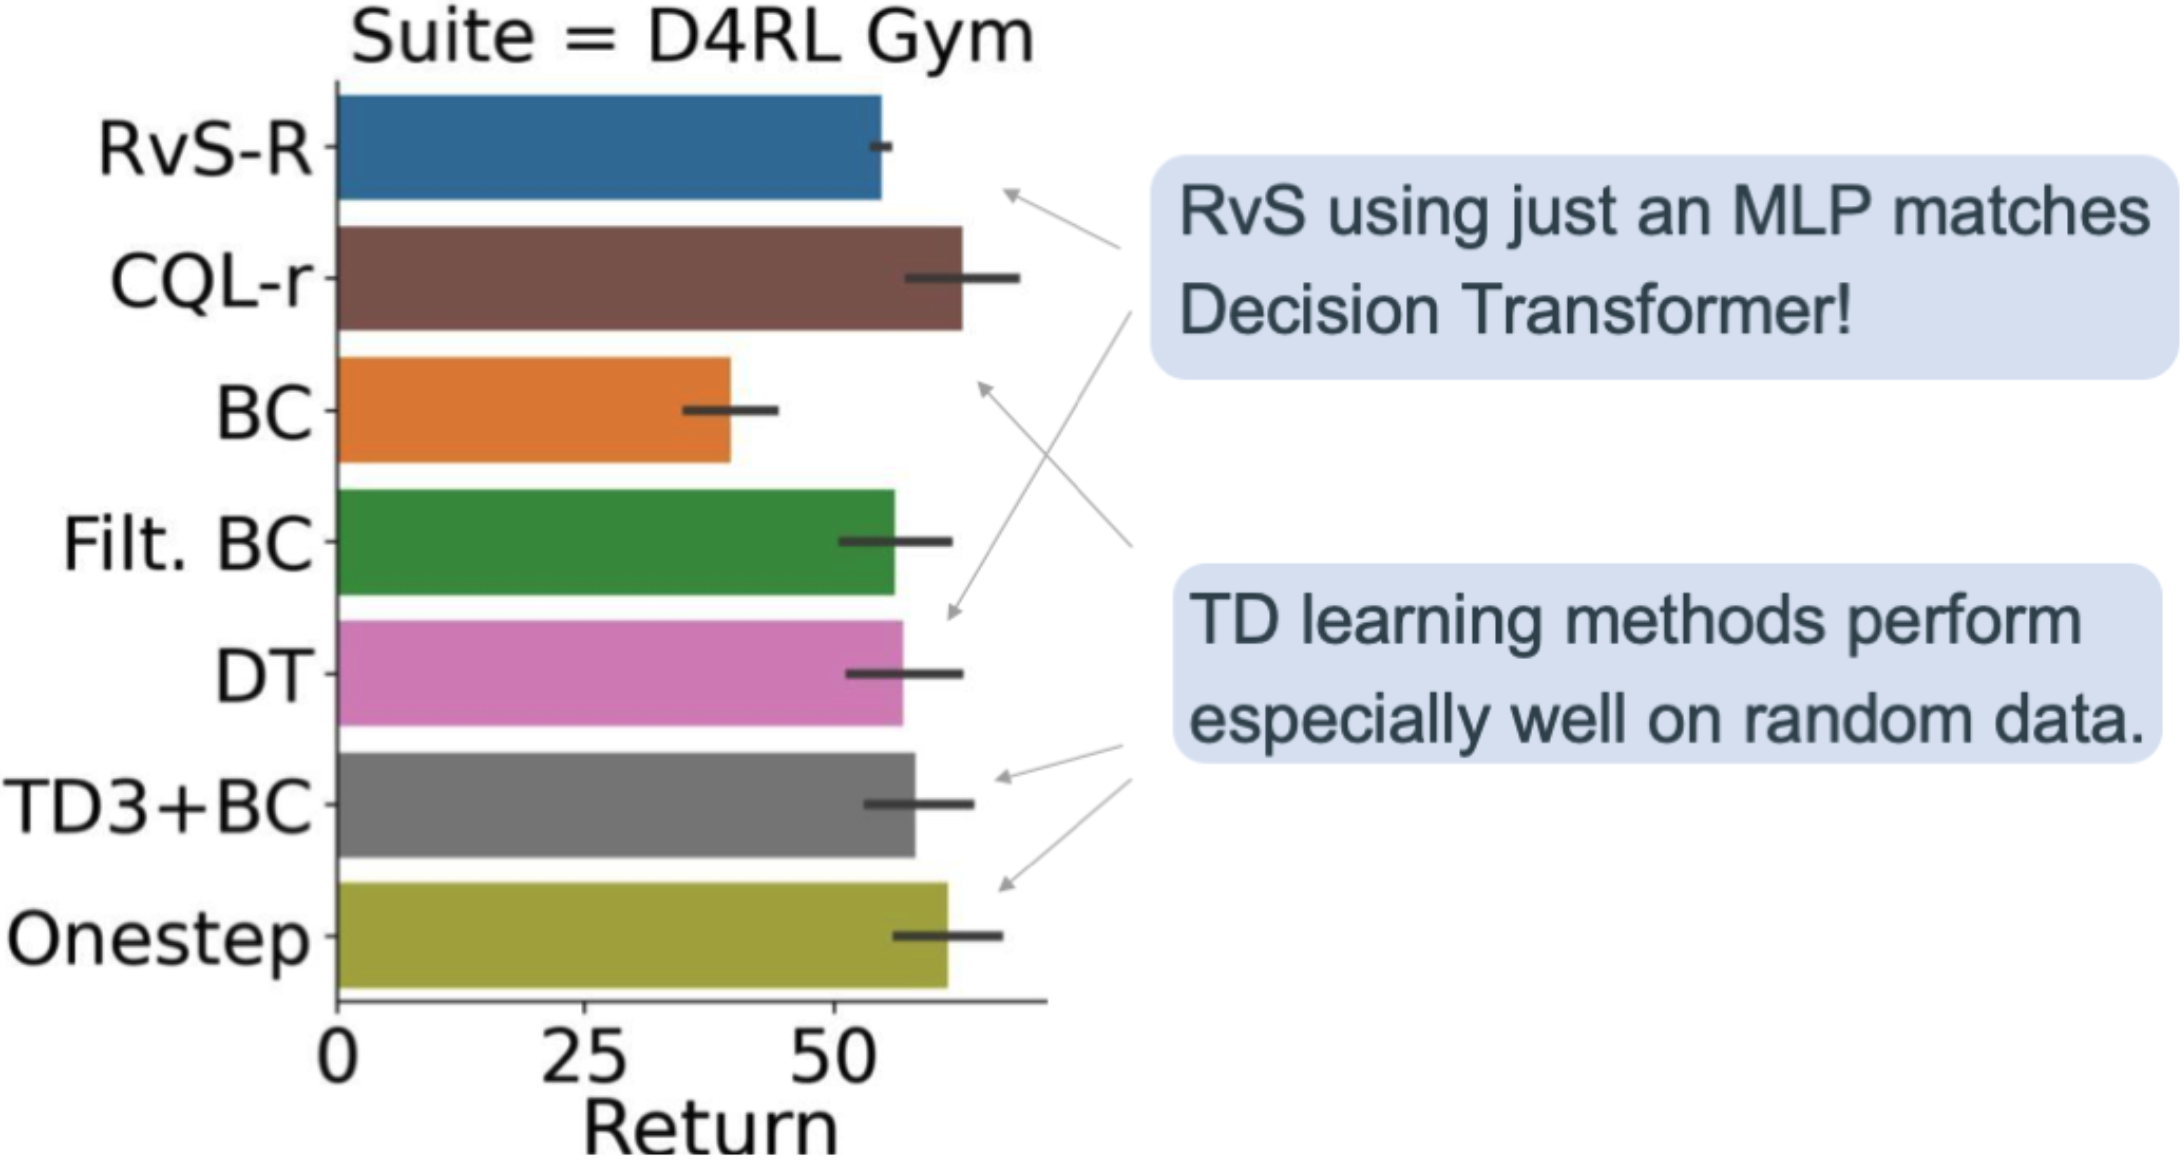
Determine 3. Total efficiency in D4RL Gymnasium.
Determine 3 exhibits our ends in D4RL Gymnasium. RvS-R is our implementation of RvS conditioned on rewards (illustrated in Determine 2). On common throughout all 12 duties within the suite, we see that RvS-R, which makes use of only a depth-two MLP, is aggressive with Choice Transformer (DT; Chen et al., 2021). We additionally see that RvS-R is aggressive with the strategies that use temporal distinction (TD) studying, together with CQL-R (Kumar et al., 2020), TD3+BC (Fujimoto et al., 2021), and Onestep (Brandfonbrener et al., 2021). Nonetheless, the TD studying strategies have an edge as a result of they carry out particularly properly on the random datasets. This means that one would possibly favor TD studying over RvS when coping with low-quality knowledge.
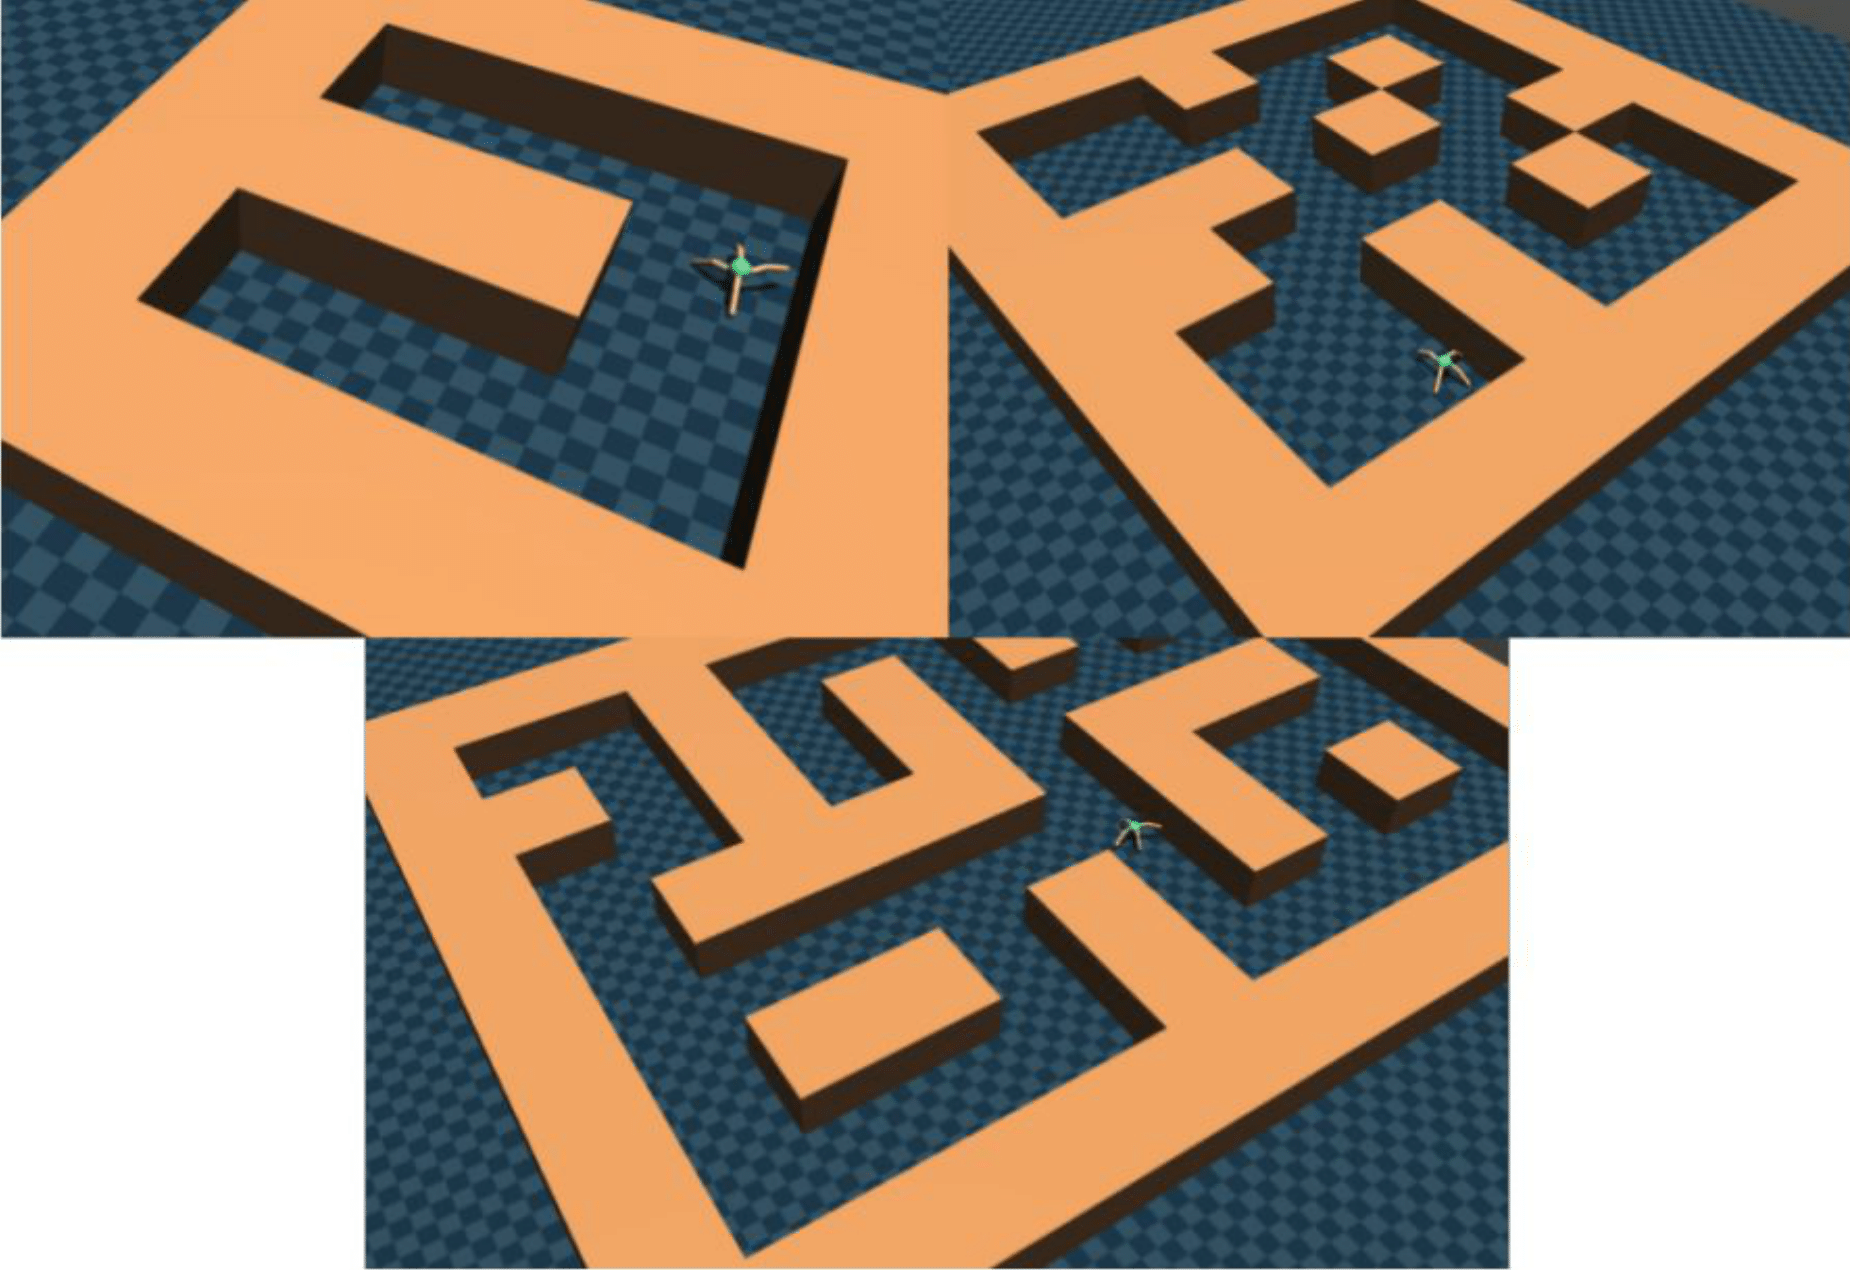
The second suite is D4RL AntMaze. This suite requires a quadruped to navigate to a goal location in mazes of various dimension. The problem of AntMaze is that many trajectories include solely items of the total path from the begin to the objective location. Studying from these trajectories requires stitching collectively these items to get the total, profitable path.
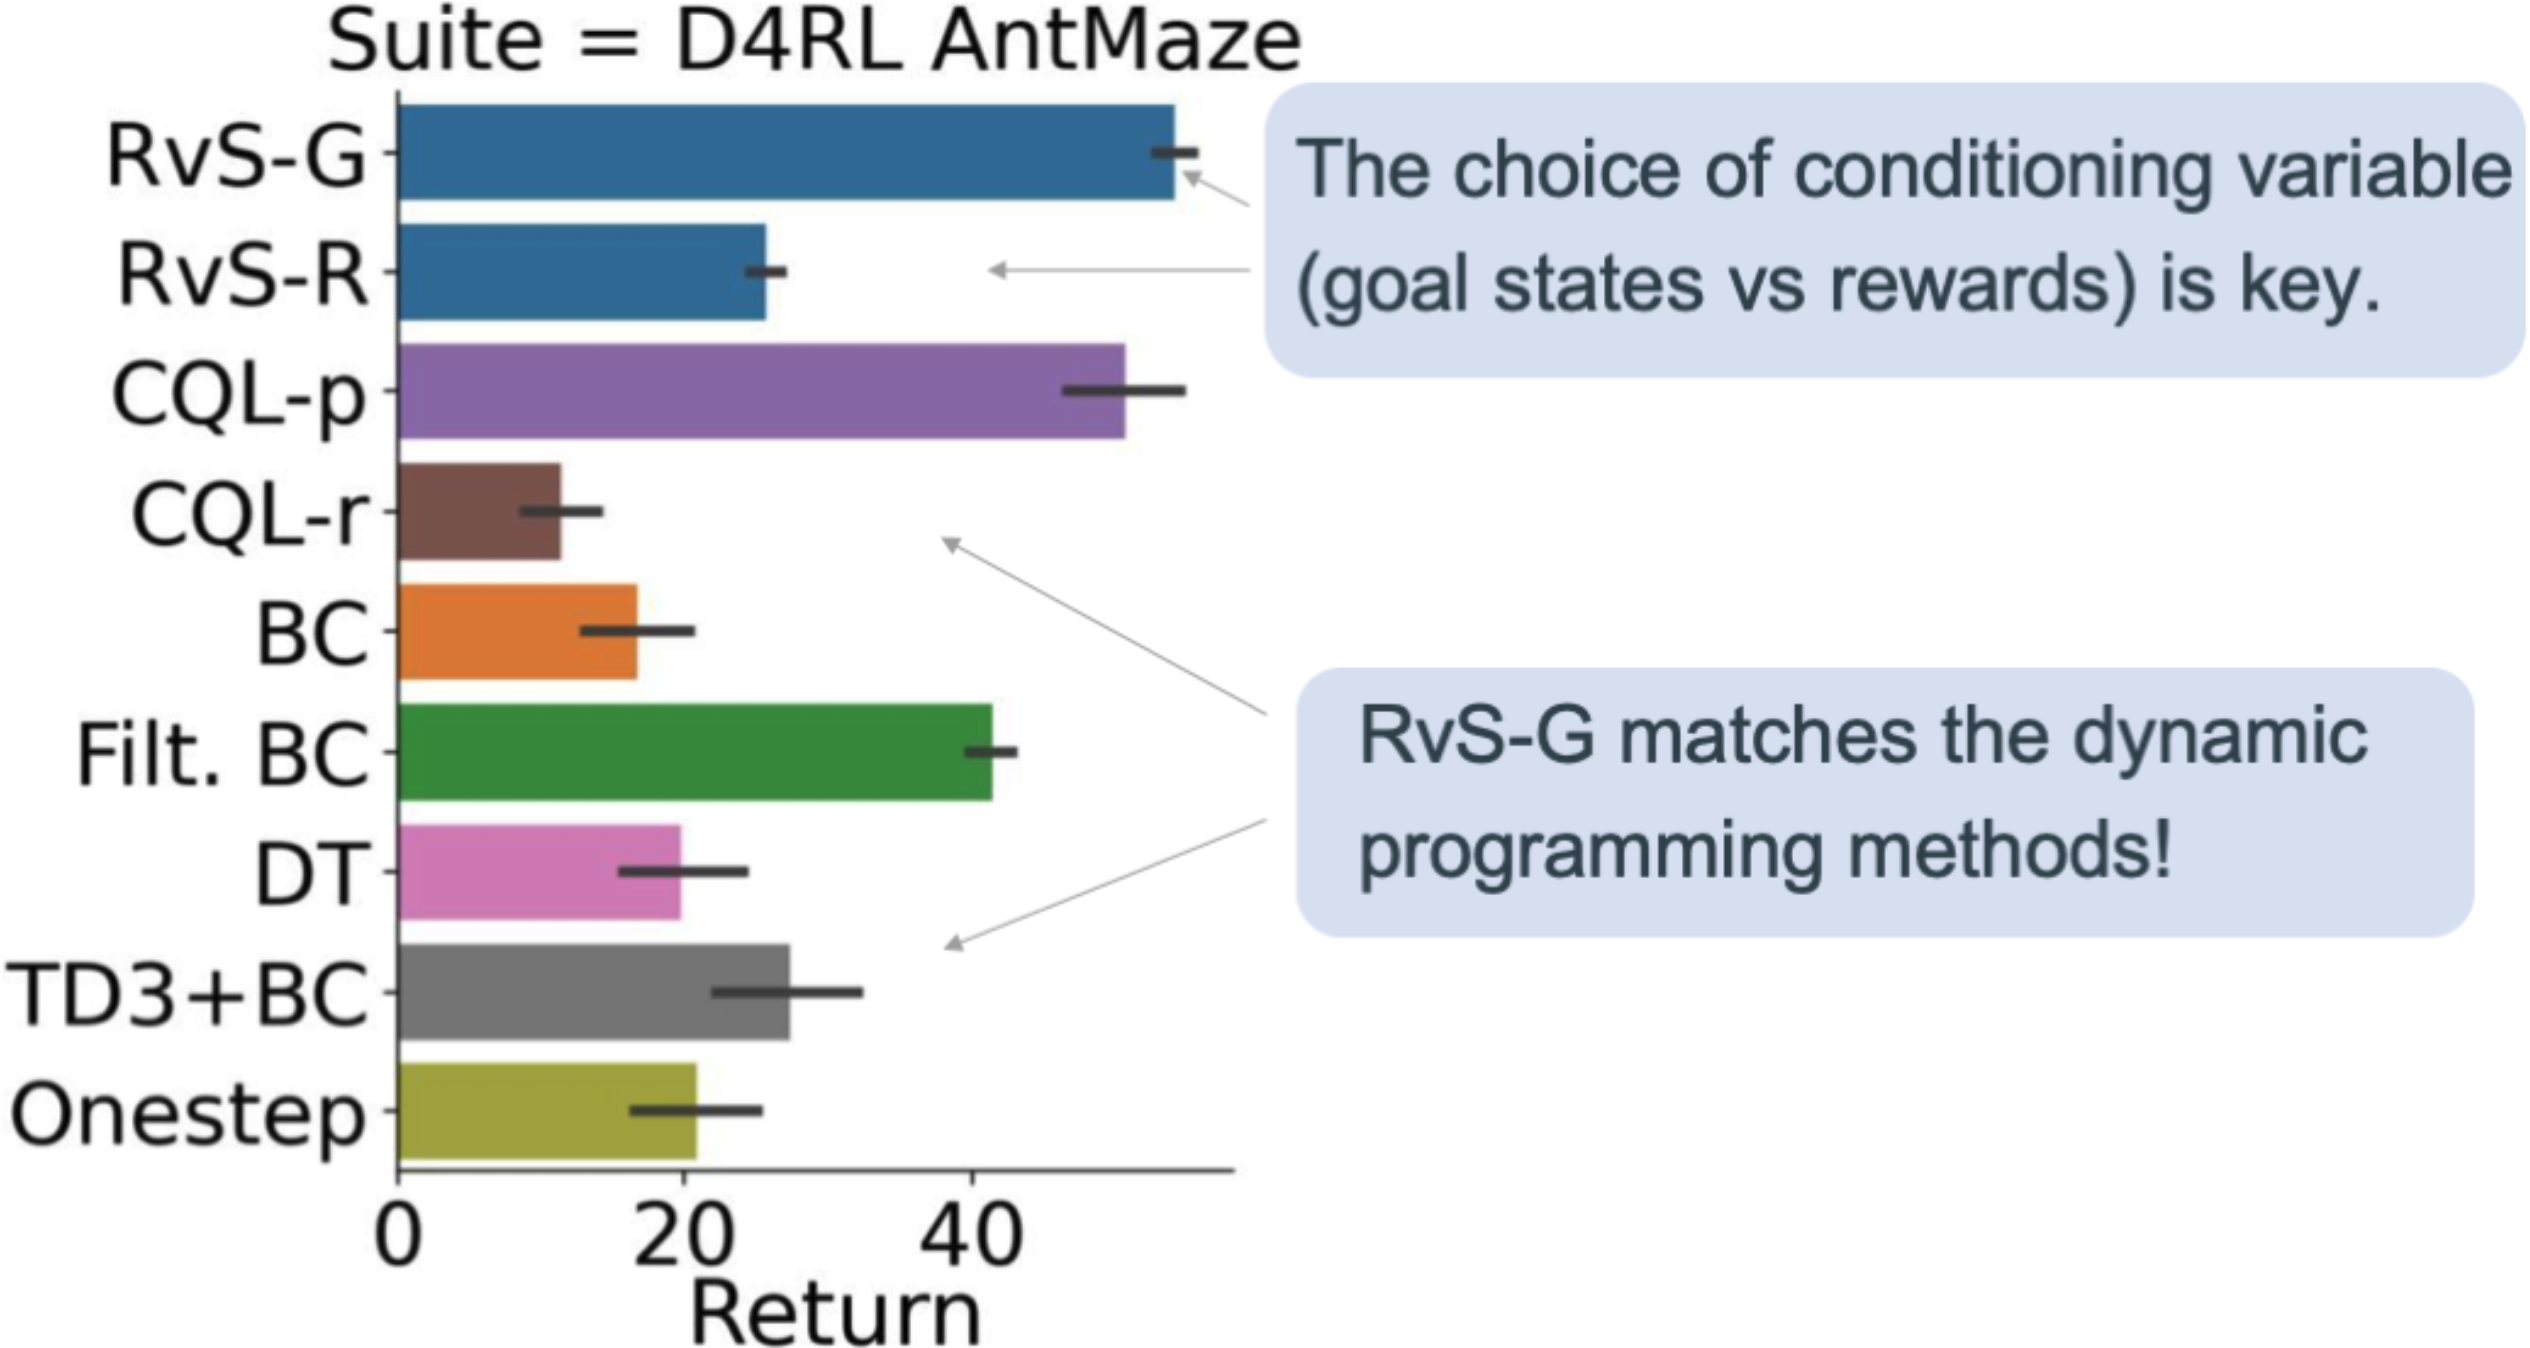
Determine 4. Total efficiency in D4RL AntMaze.
Our AntMaze ends in Determine 4 spotlight the significance of the conditioning variable. Whereas conditioning RvS on rewards (RvS-R) was your best option of the conditioning variable in D4RL Gymnasium, we discover that in D4RL AntMaze, it’s significantly better to situation RvS on $(x, y)$ objective coordinates (RvS-G). After we do that, we see that RvS-G compares favorably to TD studying! This was shocking to us as a result of TD studying explicitly performs dynamic programming utilizing the Bellman equation.
Why does goal-conditioning carry out higher than reward conditioning on this setting? Recall that AntMaze is designed so that straightforward imitation shouldn’t be sufficient: optimum strategies should sew collectively components of suboptimal trajectories to determine tips on how to attain the objective. In precept, TD studying can remedy this with temporal compositionality. With the Bellman equation, TD studying can mix a path from A to B with a path from B to C, yielding a path from A to C. RvS-R, together with different conduct cloning strategies, doesn’t profit from this temporal compositionality. We hypothesize that RvS-G, then again, advantages from spatial compositionality. It is because, in AntMaze, the coverage wanted to succeed in one objective is much like the coverage wanted to succeed in a close-by objective. We see correspondingly that RvS-G beats RvS-R.
In fact, conditioning RvS-G on $(x, y)$ coordinates represents a type of prior information concerning the activity. However this additionally highlights an vital consideration for RvS strategies: the selection of conditioning info is critically vital, and it could rely considerably on the duty.
Total, we discover that in a various set of environments, RvS works properly while not having any fancy algorithmic tips (equivalent to knowledge reweighting) or fancy architectures (equivalent to Transformers). Certainly, our easy RvS setup can match, and even outperform, strategies that make the most of (conservative) TD studying. The keys for RvS that we establish are mannequin capability, regularization, and the conditioning variable.
In our work, we handcraft the conditioning variable, equivalent to $(x, y)$ coordinates in AntMaze. Past the usual offline RL setup, this introduces an extra assumption, particularly, that now we have some prior details about the construction of the duty. We expect an thrilling route for future work could be to take away this assumption by automating the educational of the objective house.
We packaged our open-source code in order that it may routinely deal with all of the dependencies for you. After downloading the code, you’ll be able to run these 5 instructions to breed our experiments:
docker construct -t rvs:newest .
docker run -it --rm -v $(pwd):/rvs rvs:newest bash
cd rvs
pip set up -e .
bash experiments/launch_gym_rvs_r.sh
This submit is predicated on the paper:
RvS: What’s Important for Offline RL through Supervised Studying?
Scott Emmons, Benjamin Eysenbach, Ilya Kostrikov, Sergey Levine
Worldwide Convention on Studying Representations (ICLR), 2022
[Paper] [Code]
[ad_2]

