


[ad_1]
Whereas machine studying has been round a very long time, deep studying has taken on a lifetime of its personal these days. The explanation for that has principally to do with the rising quantities of computing energy which have develop into extensively obtainable—together with the burgeoning portions of information that may be simply harvested and used to coach neural networks.
The quantity of computing energy at individuals’s fingertips began rising in leaps and bounds on the flip of the millennium, when graphical processing models (GPUs) started to be
harnessed for nongraphical calculations, a development that has develop into more and more pervasive over the previous decade. However the computing calls for of deep studying have been rising even sooner. This dynamic has spurred engineers to develop digital {hardware} accelerators particularly focused to deep studying, Google’s Tensor Processing Unit (TPU) being a major instance.
Right here, I’ll describe a really totally different strategy to this downside—utilizing optical processors to hold out neural-network calculations with photons as an alternative of electrons. To know how optics can serve right here, it’s essential know somewhat bit about how computer systems at the moment perform neural-network calculations. So bear with me as I define what goes on beneath the hood.
Virtually invariably, synthetic neurons are constructed utilizing particular software program working on digital digital computer systems of some kind. That software program supplies a given neuron with a number of inputs and one output. The state of every neuron is determined by the weighted sum of its inputs, to which a nonlinear operate, referred to as an activation operate, is utilized. The outcome, the output of this neuron, then turns into an enter for numerous different neurons.
Lowering the power wants of neural networks may require computing with mild
For computational effectivity, these neurons are grouped into layers, with neurons related solely to neurons in adjoining layers. The good thing about arranging issues that means, versus permitting connections between any two neurons, is that it permits sure mathematical tips of linear algebra for use to hurry the calculations.
Whereas they aren’t the entire story, these linear-algebra calculations are probably the most computationally demanding a part of deep studying, notably as the scale of the community grows. That is true for each coaching (the method of figuring out what weights to use to the inputs for every neuron) and for inference (when the neural community is offering the specified outcomes).
What are these mysterious linear-algebra calculations? They are not so difficult actually. They contain operations on
matrices, that are simply rectangular arrays of numbers—spreadsheets if you’ll, minus the descriptive column headers you may discover in a typical Excel file.
That is nice information as a result of trendy laptop {hardware} has been very effectively optimized for matrix operations, which have been the bread and butter of high-performance computing lengthy earlier than deep studying turned fashionable. The related matrix calculations for deep studying boil right down to a lot of multiply-and-accumulate operations, whereby pairs of numbers are multiplied collectively and their merchandise are added up.
Over time, deep studying has required an ever-growing variety of these multiply-and-accumulate operations. Think about
LeNet, a pioneering deep neural community, designed to do picture classification. In 1998 it was proven to outperform different machine strategies for recognizing handwritten letters and numerals. However by 2012 AlexNet, a neural community that crunched via about 1,600 occasions as many multiply-and-accumulate operations as LeNet, was capable of acknowledge 1000’s of various kinds of objects in pictures.
Advancing from LeNet’s preliminary success to AlexNet required nearly 11 doublings of computing efficiency. Throughout the 14 years that took, Moore’s legislation offered a lot of that enhance. The problem has been to maintain this development going now that Moore’s legislation is working out of steam. The same old resolution is solely to throw extra computing sources—together with time, cash, and power—on the downside.
Consequently, coaching at the moment’s giant neural networks typically has a big environmental footprint. One
2019 examine discovered, for instance, that coaching a sure deep neural community for natural-language processing produced 5 occasions the CO2 emissions usually related to driving an vehicle over its lifetime.
Enhancements in digital digital computer systems allowed deep studying to blossom, to make sure. However that does not imply that the one solution to perform neural-network calculations is with such machines. Many years in the past, when digital computer systems have been nonetheless comparatively primitive, some engineers tackled troublesome calculations utilizing analog computer systems as an alternative. As digital electronics improved, these analog computer systems fell by the wayside. However it could be time to pursue that technique as soon as once more, specifically when the analog computations may be finished optically.
It has lengthy been identified that optical fibers can help a lot larger information charges than electrical wires. That is why all long-haul communication traces went optical, beginning within the late Seventies. Since then, optical information hyperlinks have changed copper wires for shorter and shorter spans, all the way in which right down to rack-to-rack communication in information facilities. Optical information communication is quicker and makes use of much less energy. Optical computing guarantees the identical benefits.
However there’s a large distinction between speaking information and computing with it. And that is the place analog optical approaches hit a roadblock. Standard computer systems are primarily based on transistors, that are extremely nonlinear circuit components—which means that their outputs aren’t simply proportional to their inputs, not less than when used for computing. Nonlinearity is what lets transistors swap on and off, permitting them to be common into logic gates. This switching is simple to perform with electronics, for which nonlinearities are a dime a dozen. However photons comply with Maxwell’s equations, that are annoyingly linear, which means that the output of an optical gadget is often proportional to its inputs.
The trick is to make use of the linearity of optical units to do the one factor that deep studying depends on most: linear algebra.
For example how that may be finished, I am going to describe right here a photonic gadget that, when coupled to some easy analog electronics, can multiply two matrices collectively. Such multiplication combines the rows of 1 matrix with the columns of the opposite. Extra exactly, it multiplies pairs of numbers from these rows and columns and provides their merchandise collectively—the multiply-and-accumulate operations I described earlier. My MIT colleagues and I revealed a paper about how this might be finished
in 2019. We’re working now to construct such an optical matrix multiplier.
Optical information communication is quicker and makes use of much less energy. Optical computing guarantees the identical benefits.
The essential computing unit on this gadget is an optical factor referred to as a
beam splitter. Though its make-up is in actual fact extra difficult, you may consider it as a half-silvered mirror set at a 45-degree angle. If you happen to ship a beam of sunshine into it from the facet, the beam splitter will permit half that mild to go straight via it, whereas the opposite half is mirrored from the angled mirror, inflicting it to bounce off at 90 levels from the incoming beam.
Now shine a second beam of sunshine, perpendicular to the primary, into this beam splitter in order that it impinges on the opposite facet of the angled mirror. Half of this second beam will equally be transmitted and half mirrored at 90 levels. The 2 output beams will mix with the 2 outputs from the primary beam. So this beam splitter has two inputs and two outputs.
To make use of this gadget for matrix multiplication, you generate two mild beams with electric-field intensities which might be proportional to the 2 numbers you wish to multiply. Let’s name these area intensities
x and y. Shine these two beams into the beam splitter, which is able to mix these two beams. This specific beam splitter does that in a means that can produce two outputs whose electrical fields have values of (x + y)/√2 and (x − y)/√2.
Along with the beam splitter, this analog multiplier requires two easy digital elements—photodetectors—to measure the 2 output beams. They do not measure the electrical area depth of these beams, although. They measure the facility of a beam, which is proportional to the sq. of its electric-field depth.
Why is that relation vital? To know that requires some algebra—however nothing past what you discovered in highschool. Recall that while you sq. (
x + y)/√2 you get (x2 + 2xy + y2)/2. And while you sq. (x − y)/√2, you get (x2 − 2xy + y2)/2. Subtracting the latter from the previous provides 2xy.
Pause now to ponder the importance of this easy little bit of math. It signifies that in the event you encode a quantity as a beam of sunshine of a sure depth and one other quantity as a beam of one other depth, ship them via such a beam splitter, measure the 2 outputs with photodetectors, and negate one of many ensuing electrical alerts earlier than summing them collectively, you should have a sign proportional to the product of your two numbers.
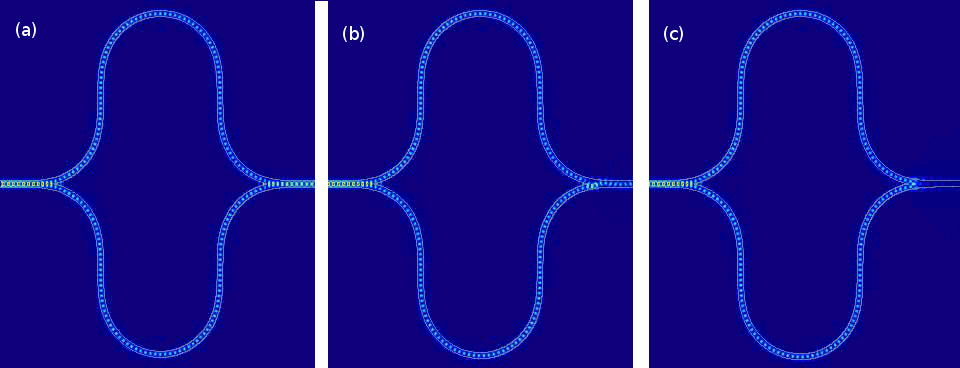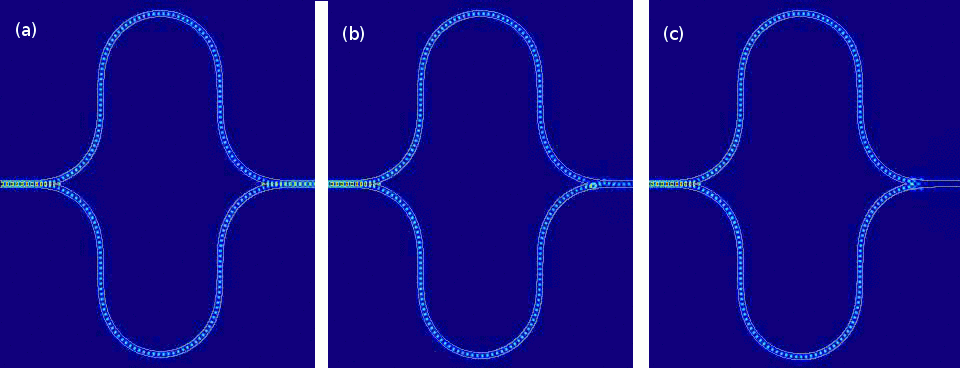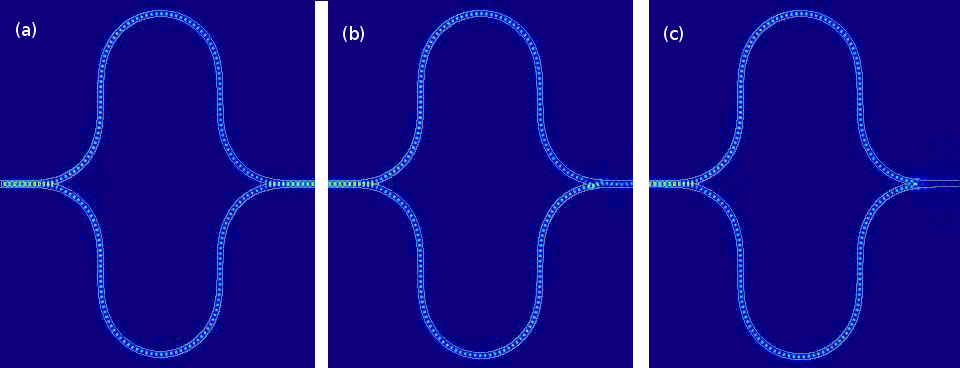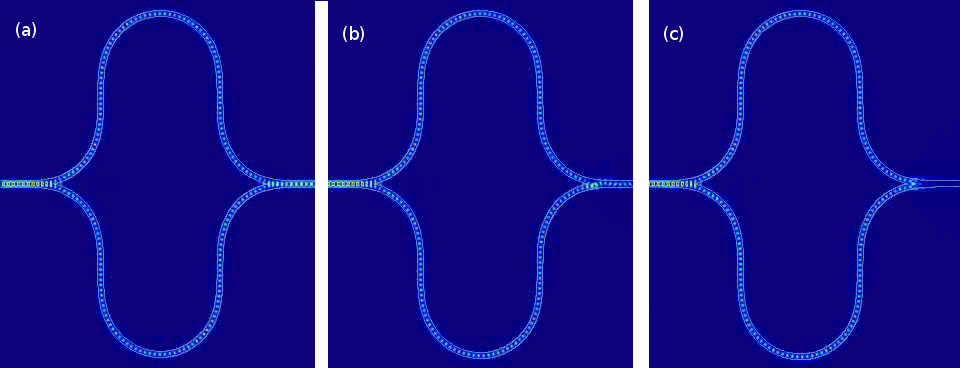
Simulations of the built-in Mach-Zehnder interferometer present in Lightmatter’s neural-network accelerator present three totally different situations whereby mild touring within the two branches of the interferometer undergoes totally different relative section shifts (0 levels in a, 45 levels in b, and 90 levels in c).
Lightmatter
My description has made it sound as if every of those mild beams should be held regular. In reality, you may briefly pulse the sunshine within the two enter beams and measure the output pulse. Higher but, you may feed the output sign right into a capacitor, which is able to then accumulate cost for so long as the heartbeat lasts. Then you may pulse the inputs once more for a similar length, this time encoding two new numbers to be multiplied collectively. Their product provides some extra cost to the capacitor. You possibly can repeat this course of as many occasions as you want, every time finishing up one other multiply-and-accumulate operation.
Utilizing pulsed mild on this means permits you to carry out many such operations in rapid-fire sequence. Probably the most energy-intensive a part of all that is studying the voltage on that capacitor, which requires an analog-to-digital converter. However you do not have to do this after every pulse—you may wait till the top of a sequence of, say,
N pulses. That signifies that the gadget can carry out N multiply-and-accumulate operations utilizing the identical quantity of power to learn the reply whether or not N is small or giant. Right here, N corresponds to the variety of neurons per layer in your neural community, which might simply quantity within the 1000’s. So this technique makes use of little or no power.
Typically it can save you power on the enter facet of issues, too. That is as a result of the identical worth is usually used as an enter to a number of neurons. Moderately than that quantity being transformed into mild a number of occasions—consuming power every time—it may be remodeled simply as soon as, and the sunshine beam that’s created may be break up into many channels. On this means, the power value of enter conversion is amortized over many operations.
Splitting one beam into many channels requires nothing extra difficult than a lens, however lenses may be difficult to place onto a chip. So the gadget we’re growing to carry out neural-network calculations optically might effectively find yourself being a hybrid that mixes extremely built-in photonic chips with separate optical components.
I’ve outlined right here the technique my colleagues and I’ve been pursuing, however there are different methods to pores and skin an optical cat. One other promising scheme is predicated on one thing referred to as a Mach-Zehnder interferometer, which mixes two beam splitters and two absolutely reflecting mirrors. It, too, can be utilized to hold out matrix multiplication optically. Two MIT-based startups, Lightmatter and Lightelligence, are growing optical neural-network accelerators primarily based on this strategy. Lightmatter has already constructed a prototype that makes use of an optical chip it has fabricated. And the corporate expects to start promoting an optical accelerator board that makes use of that chip later this 12 months.
One other startup utilizing optics for computing is
Optalysis, which hopes to revive a slightly outdated idea. One of many first makes use of of optical computing again within the Sixties was for the processing of synthetic-aperture radar information. A key a part of the problem was to use to the measured information a mathematical operation referred to as the Fourier rework. Digital computer systems of the time struggled with such issues. Even now, making use of the Fourier rework to giant quantities of information may be computationally intensive. However a Fourier rework may be carried out optically with nothing extra difficult than a lens, which for some years was how engineers processed synthetic-aperture information. Optalysis hopes to convey this strategy updated and apply it extra extensively.
Theoretically, photonics has the potential to speed up deep studying by a number of orders of magnitude.
There’s additionally an organization referred to as
Luminous, spun out of Princeton College, which is working to create spiking neural networks primarily based on one thing it calls a laser neuron. Spiking neural networks extra carefully mimic how organic neural networks work and, like our personal brains, are capable of compute utilizing little or no power. Luminous’s {hardware} continues to be within the early section of growth, however the promise of mixing two energy-saving approaches—spiking and optics—is kind of thrilling.
There are, in fact, nonetheless many technical challenges to be overcome. One is to enhance the accuracy and dynamic vary of the analog optical calculations, that are nowhere close to nearly as good as what may be achieved with digital electronics. That is as a result of these optical processors endure from numerous sources of noise and since the digital-to-analog and analog-to-digital converters used to get the information out and in are of restricted accuracy. Certainly, it is troublesome to think about an optical neural community working with greater than 8 to 10 bits of precision. Whereas 8-bit digital deep-learning {hardware} exists (the Google TPU is an efficient instance), this trade calls for larger precision, particularly for neural-network coaching.
There’s additionally the problem integrating optical elements onto a chip. As a result of these elements are tens of micrometers in measurement, they can not be packed almost as tightly as transistors, so the required chip space provides up rapidly.
A 2017 demonstration of this strategy by MIT researchers concerned a chip that was 1.5 millimeters on a facet. Even the largest chips are not any bigger than a number of sq. centimeters, which locations limits on the sizes of matrices that may be processed in parallel this manner.
There are a lot of extra questions on the computer-architecture facet that photonics researchers have a tendency to brush beneath the rug. What’s clear although is that, not less than theoretically, photonics has the potential to speed up deep studying by a number of orders of magnitude.
Primarily based on the expertise that is at the moment obtainable for the varied elements (optical modulators, detectors, amplifiers, analog-to-digital converters), it is affordable to suppose that the power effectivity of neural-network calculations might be made 1,000 occasions higher than at the moment’s digital processors. Making extra aggressive assumptions about rising optical expertise, that issue is perhaps as giant as one million. And since digital processors are power-limited, these enhancements in power effectivity will seemingly translate into corresponding enhancements in velocity.
Most of the ideas in analog optical computing are a long time outdated. Some even predate silicon computer systems. Schemes for optical matrix multiplication, and
even for optical neural networks, have been first demonstrated within the Seventies. However this strategy did not catch on. Will this time be totally different? Probably, for 3 causes.
First, deep studying is genuinely helpful now, not simply an educational curiosity. Second,
we will not depend on Moore’s Legislation alone to proceed bettering electronics. And at last, we now have a brand new expertise that was not obtainable to earlier generations: built-in photonics. These components recommend that optical neural networks will arrive for actual this time—and the way forward for such computations might certainly be photonic.
[ad_2]

