


[ad_1]
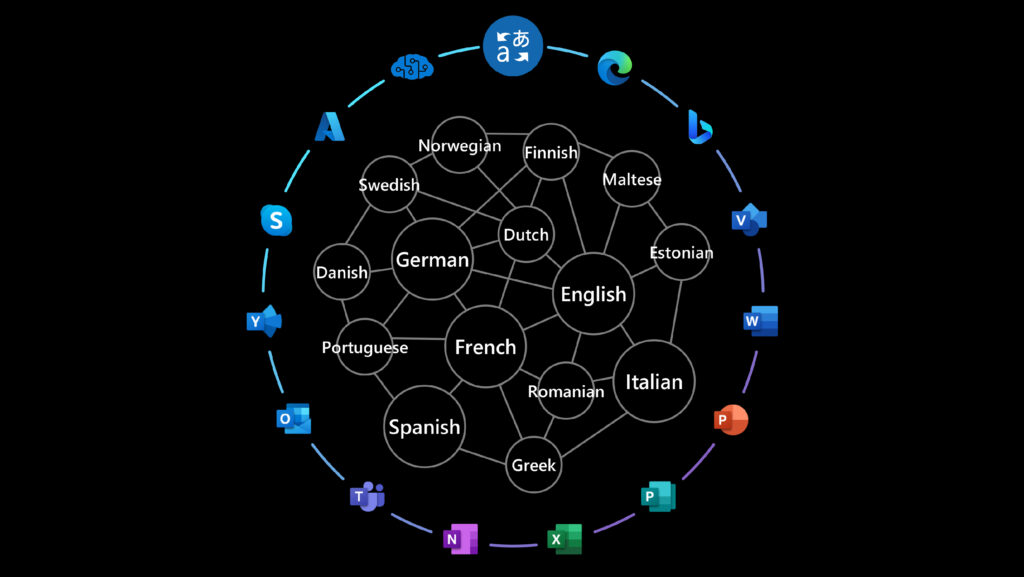
Translator, a Microsoft Azure Cognitive Service, is adopting Z-code Combination of Specialists fashions, a breakthrough AI know-how that considerably improves the standard of manufacturing translation fashions. As a part of Microsoft’s bigger XYZ-code initiative to mix AI fashions for textual content, imaginative and prescient, audio, and language, Z-code helps the creation of AI programs that may communicate, see, hear, and perceive. This effort is part of Azure AI and Challenge Turing, specializing in constructing multilingual, large-scale language fashions that help numerous manufacturing groups. Translator is utilizing NVIDIA GPUs and Triton Inference Server to deploy and scale these fashions effectively for high-performance inference. Translator is the primary machine translation supplier to introduce this know-how stay for patrons.
Z-code MoE boosts effectivity and high quality
Z-code fashions make the most of a brand new structure referred to as Combination of Specialists (MoE), the place completely different elements of the fashions can be taught completely different duties. The fashions be taught to translate between a number of languages on the identical time. The Z-code MoE mannequin makes use of extra parameters whereas dynamically deciding on which parameters to make use of for a given enter. This allows the mannequin to specialize a subset of the parameters (consultants) throughout coaching. At runtime, the mannequin makes use of the related consultants for the duty, which is extra computationally environment friendly than using all mannequin’s parameters.
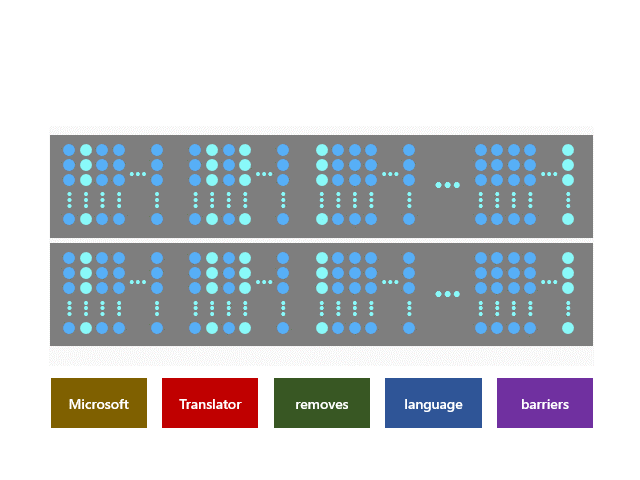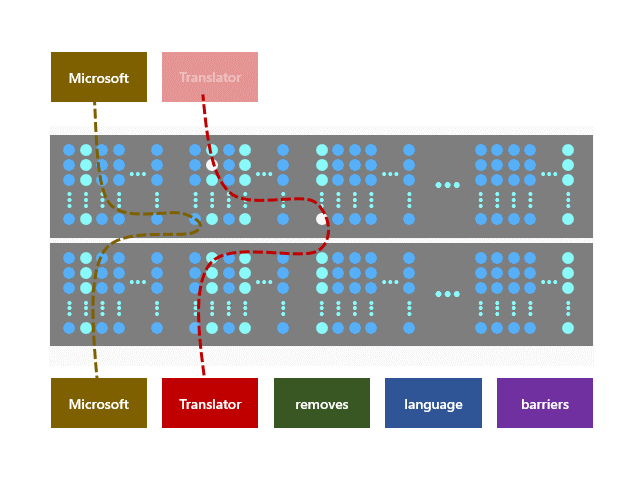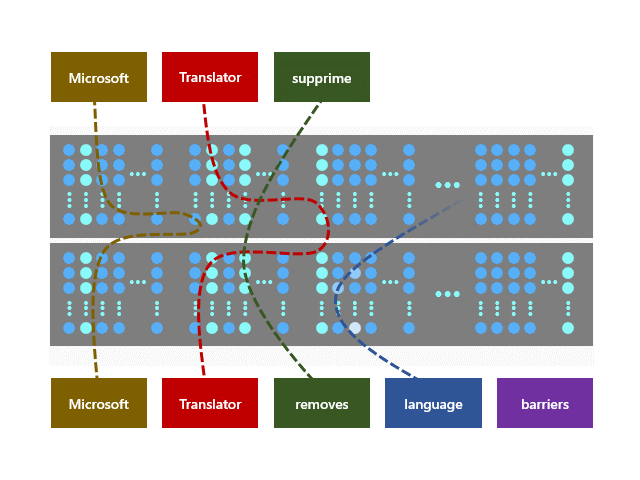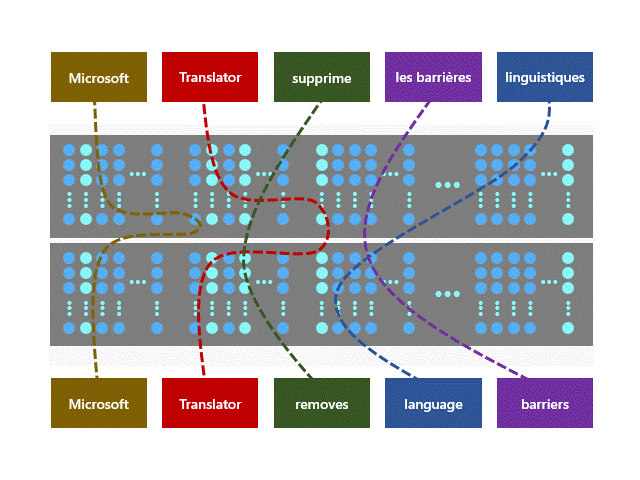
Newly launched Z-code MoE fashions leverage switch studying, which permits environment friendly information sharing throughout comparable languages. Furthermore, the fashions make the most of each parallel and monolingual knowledge in the course of the coaching course of. This opens the best way to prime quality machine translation past the high-resource languages and improves the standard of low-resource languages that lack vital coaching knowledge. This strategy can present a optimistic impression on AI equity, since each high-resource and low-resource languages see enhancements.
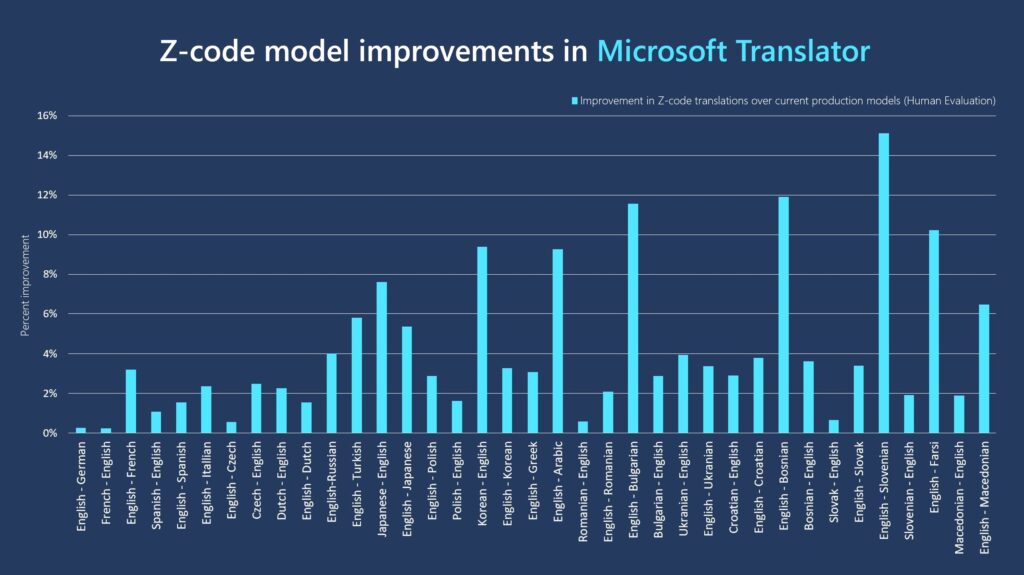
We have now educated translation programs for analysis functions with 200 billion parameters supporting 100 language pairs. Although such massive programs considerably improved the interpretation high quality, this additionally launched challenges to deploy them in a manufacturing surroundings cheaply. For our manufacturing mannequin deployment, we opted for coaching a set of 5 billion parameter fashions, that are 80 instances bigger than our presently deployed fashions. We educated a multilingual mannequin per set of languages, the place every mannequin can serve as much as 20 language pairs and due to this fact change as much as 20 of the present programs. This enabled our mannequin to maximise the switch studying amongst languages whereas being deployable with efficient runtime value. We in contrast the standard enhancements of the brand new MoE to the present manufacturing system utilizing human analysis. The determine beneath reveals the outcomes of the fashions on numerous language pairs. The Z-code-MoE programs outperformed particular person bilingual programs, with common enhancements of 4%. As an example, the fashions improved English to French translations by 3.2 %, English to Turkish by 5.8 %, Japanese to English by 7.6 %, English to Arabic by 9.3 %, and English to Slovenian by 15 %.
Coaching massive fashions with billions of parameters is difficult. The Translator workforce collaborated with Microsoft DeepSpeed to develop a high-performance system that helped practice large scale Z-code MoE fashions, enabling us to effectively scale and deploy Z-code fashions for translation.
We partnered with NVIDIA to optimize quicker engines that can be utilized at runtime to deploy the brand new Z-code/MoE fashions on GPUs. NVIDIA developed customized CUDA kernels and leveraged the CUTLASS and FasterTransformer libraries to effectively implement MoE layers on a single V100 GPU. This implementation achieved as much as 27x throughput enhancements over commonplace GPU (PyTorch) runtimes. We used NVIDIA’s open supply Triton Inference Server to serve Z-code MoE fashions. We used Triton’s dynamic batching characteristic to pool a number of requests into a giant batch for increased throughput that enabled us to ship massive fashions with comparatively low runtime prices.
How will you use the brand new Z-code fashions?
Z-code fashions can be found now by invitation to clients utilizing Doc Translation, a characteristic that interprets total paperwork, or volumes of paperwork, in quite a lot of completely different file codecs preserving their unique formatting. Z-code fashions will probably be made obtainable to all clients and to different Translator merchandise in phases. Please fill out this way to request entry to Doc Translation utilizing Z-code fashions.
Be taught extra
Acknowledgements
The next individuals contributed to this work: Abdelrahman Abouelenin, Ahmed Salah, Akiko Eriguchi, Alex Cheng, Alex Muzio, Amr Hendy, Arul Menezes, Brad Ballinger, Christophe Poulain, Evram Narouz, Fai Sigalov, Hany Hassan Awadalla, Hitokazu Matsushita, Mohamed Afify, Raffy Bekhit, Rohit Jain, Steven Nguyen, Vikas Raunak, Vishal Chowdhary, and Younger Jin Kim.
[ad_2]

