


[ad_1]
Massive neural networks are on the core of many current advances in AI, however coaching them is a tough engineering and analysis problem which requires orchestrating a cluster of GPUs to carry out a single synchronized calculation. As cluster and mannequin sizes have grown, machine studying practitioners have developed an growing number of methods to parallelize mannequin coaching over many GPUs. At first look, understanding these parallelism methods could seem daunting, however with only some assumptions in regards to the construction of the computation these methods turn into way more clear—at that time, you are simply shuttling round opaque bits from A to B like a community change shuttles round packets.
Information Parallelism

Pipeline Parallelism

Tensor Parallelism

Knowledgeable Parallelism

Information Parallelism
Pipeline Parallelism
Tensor Parallelism
Knowledgeable Parallelism
An illustration of varied parallelism methods on a three-layer mannequin. Every colour refers to at least one layer and dashed strains separate completely different GPUs.
No Parallelism
Coaching a neural community is an iterative course of. In each iteration, we do a cross ahead by a mannequin’s layers to compute an output for every coaching instance in a batch of information. Then one other cross proceeds backward by the layers, propagating how a lot every parameter impacts the ultimate output by computing a gradient with respect to every parameter. The common gradient for the batch, the parameters, and a few per-parameter optimization state is handed to an optimization algorithm, corresponding to Adam, which computes the following iteration’s parameters (which ought to have barely higher efficiency in your information) and new per-parameter optimization state. Because the coaching iterates over batches of information, the mannequin evolves to provide more and more correct outputs.
Numerous parallelism methods slice this coaching course of throughout completely different dimensions, together with:
- Information parallelism—run completely different subsets of the batch on completely different GPUs;
- Pipeline parallelism—run completely different layers of the mannequin on completely different GPUs;
- Tensor parallelism—break up the mathematics for a single operation corresponding to a matrix multiplication to be cut up throughout GPUs;
- Combination-of-Specialists—course of every instance by solely a fraction of every layer.
(On this submit, we’ll assume that you’re utilizing GPUs to coach your neural networks, however the identical concepts apply to these utilizing every other neural community accelerator.)
Information Parallelism
Information Parallel coaching means copying the identical parameters to a number of GPUs (typically known as “employees”) and assigning completely different examples to every to be processed concurrently. Information parallelism alone nonetheless requires that your mannequin matches right into a single GPU’s reminiscence, however helps you to make the most of the compute of many GPUs at the price of storing many duplicate copies of your parameters. That being stated, there are methods to extend the efficient RAM obtainable to your GPU, corresponding to quickly offloading parameters to CPU reminiscence between usages.
As every information parallel employee updates its copy of the parameters, they should coordinate to make sure that every employee continues to have related parameters. The best method is to introduce blocking communication between employees: (1) independently compute the gradient on every employee; (2) common the gradients throughout employees; and (3) independently compute the identical new parameters on every employee. Step (2) is a blocking common which requires transferring various information (proportional to the variety of employees occasions the dimensions of your parameters), which may harm your coaching throughput. There are numerous asynchronous synchronization schemes to take away this overhead, however they harm studying effectivity; in apply, folks usually stick to the synchronous method.
Pipeline Parallelism
With Pipeline Parallel coaching, we partition sequential chunks of the mannequin throughout GPUs. Every GPU holds solely a fraction of parameters, and thus the identical mannequin consumes proportionally much less reminiscence per GPU.
It’s simple to separate a big mannequin into chunks of consecutive layers. Nonetheless, there’s a sequential dependency between inputs and outputs of layers, so a naive implementation can result in a considerable amount of idle time whereas a employee waits for outputs from the earlier machine for use as its inputs. These ready time chunks are generally known as “bubbles,” losing the computation that could possibly be finished by the idling machines.

Ahead

Backward

Gradient replace

Idle

Illustration of a naive pipeline parallelism setup the place the mannequin is vertically cut up into 4 partitions by layer. Employee 1 hosts mannequin parameters of the primary layer of the community (closest to the enter), whereas employee 4 hosts layer 4 (which is closest to the output). “F”, “B”, and “U” characterize ahead, backward and replace operations, respectively. The subscripts point out on which employee an operation runs. Information is processed by one employee at a time because of the sequential dependency, resulting in massive “bubbles” of idle time.
We will reuse the concepts from information parallelism to cut back the price of the bubble by having every employee solely course of a subset of information components at one time, permitting us to cleverly overlap new computation with wait time. The core concept is to separate one batch into a number of microbatches; every microbatch must be proportionally quicker to course of and every employee begins engaged on the following microbatch as quickly because it’s obtainable, thus expediting the pipeline execution. With sufficient microbatches the employees will be utilized more often than not with a minimal bubble in the beginning and finish of the step. Gradients are averaged throughout microbatches, and updates to the parameters occur solely as soon as all microbatches have been accomplished.
The variety of employees that the mannequin is cut up over is usually generally known as pipeline depth.
Throughout the ahead cross, employees solely must ship the output (known as activations) of its chunk of layers to the following employee; in the course of the backward cross, it solely sends the gradients on these activations to the earlier employee. There’s an enormous design area of the way to schedule these passes and the way to combination the gradients throughout microbatches. GPipe has every employee course of ahead and backward passes consecutively after which aggregates gradients from a number of microbatches synchronously on the finish. PipeDream as a substitute schedules every employee to alternatively course of ahead and backward passes.
Ahead
Backward
Replace
Idle
GPipe

PipeDream

Comparability of GPipe and PipeDream pipelining schemes, utilizing 4 microbatches per batch. Microbatches 1-8 correspond to 2 consecutive information batches. Within the picture, “(quantity)” signifies on which microbatch an operation is carried out and the subscript marks the employee ID. Word that PipeDream will get extra effectivity by performing some computations with stale parameters.
Tensor Parallelism
Pipeline parallelism splits a mannequin “vertically” by layer. It is also doable to “horizontally” cut up sure operations inside a layer, which is normally known as Tensor Parallel coaching. For a lot of trendy fashions (such because the Transformer), the computation bottleneck is multiplying an activation batch matrix with a big weight matrix. Matrix multiplication will be regarded as dot merchandise between pairs of rows and columns; it is doable to compute impartial dot merchandise on completely different GPUs, or to compute components of every dot product on completely different GPUs and sum up the outcomes. With both technique, we will slice the load matrix into even-sized “shards”, host every shard on a distinct GPU, and use that shard to compute the related a part of the general matrix product earlier than later speaking to mix the outcomes.
One instance is Megatron-LM, which parallelizes matrix multiplications inside the Transformer’s self-attention and MLP layers. PTD-P makes use of tensor, information, and pipeline parallelism; its pipeline schedule assigns a number of non-consecutive layers to every system, decreasing bubble overhead at the price of extra community communication.
Generally the enter to the community will be parallelized throughout a dimension with a excessive diploma of parallel computation relative to cross-communication. Sequence parallelism is one such concept, the place an enter sequence is cut up throughout time into a number of sub-examples, proportionally lowering peak reminiscence consumption by permitting the computation to proceed with extra granularly-sized examples.
Combination-of-Specialists (MoE)
With the Combination-of-Specialists (MoE) method, solely a fraction of the community is used to compute the output for anybody enter. One instance method is to have many units of weights and the community can select which set to make use of through a gating mechanism at inference time. This allows many extra parameters with out elevated computation price. Every set of weights is known as “specialists,” within the hope that the community will be taught to assign specialised computation and expertise to every skilled. Totally different specialists will be hosted on completely different GPUs, offering a transparent approach to scale up the variety of GPUs used for a mannequin.
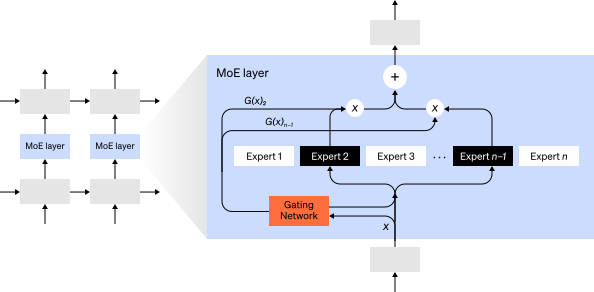
Illustration of a mixture-of-experts (MoE) layer. Solely 2 out of the n specialists are chosen by the gating community. (Picture tailored from: Shazeer et al., 2017)
GShard scales an MoE Transformer as much as 600 billion parameters with a scheme the place solely the MoE layers are cut up throughout a number of TPU gadgets and different layers are absolutely duplicated. Change Transformer scales mannequin measurement to trillions of parameters with even increased sparsity by routing one enter to a single skilled.
Different Reminiscence Saving Designs
There are a lot of different computational methods to make coaching more and more massive neural networks extra tractable. For instance:
-
To compute the gradient, you have to have saved the unique activations, which may devour a variety of system RAM. Checkpointing (also referred to as activation recomputation) shops any subset of activations, and recomputes the intermediate ones just-in-time in the course of the backward cross. This protects a variety of reminiscence on the computational price of at most one extra full ahead cross. One may also regularly commerce off between compute and reminiscence price by selective activation recomputation, which is checkpointing subsets of the activations which might be comparatively costlier to retailer however cheaper to compute.
-
Combined Precision Coaching is to coach fashions utilizing lower-precision numbers (mostly FP16). Fashionable accelerators can attain a lot increased FLOP counts with lower-precision numbers, and also you additionally save on system RAM. With correct care, the ensuing mannequin can lose virtually no accuracy.
-
Offloading is to quickly offload unused information to the CPU or amongst completely different gadgets and later learn it again when wanted. Naive implementations will decelerate coaching lots, however refined implementations will pre-fetch information in order that the system by no means wants to attend on it. One implementation of this concept is ZeRO which splits the parameters, gradients, and optimizer states throughout all obtainable {hardware} and materializes them as wanted.
-
Reminiscence Environment friendly Optimizers have been proposed to cut back the reminiscence footprint of the operating state maintained by the optimizer, corresponding to Adafactor.
-
Compression additionally can be utilized for storing intermediate leads to the community. For instance, Gist compresses activations which might be saved for the backward cross; DALL·E compresses the gradients earlier than synchronizing them.
At OpenAI, we’re coaching and bettering massive fashions from the underlying infrastructure all the way in which to deployment them for real-world issues. In the event you’d prefer to put the concepts from this submit into apply—particularly related for our Scaling and Utilized Analysis groups—we’re hiring!
[ad_2]

