



[ad_1]
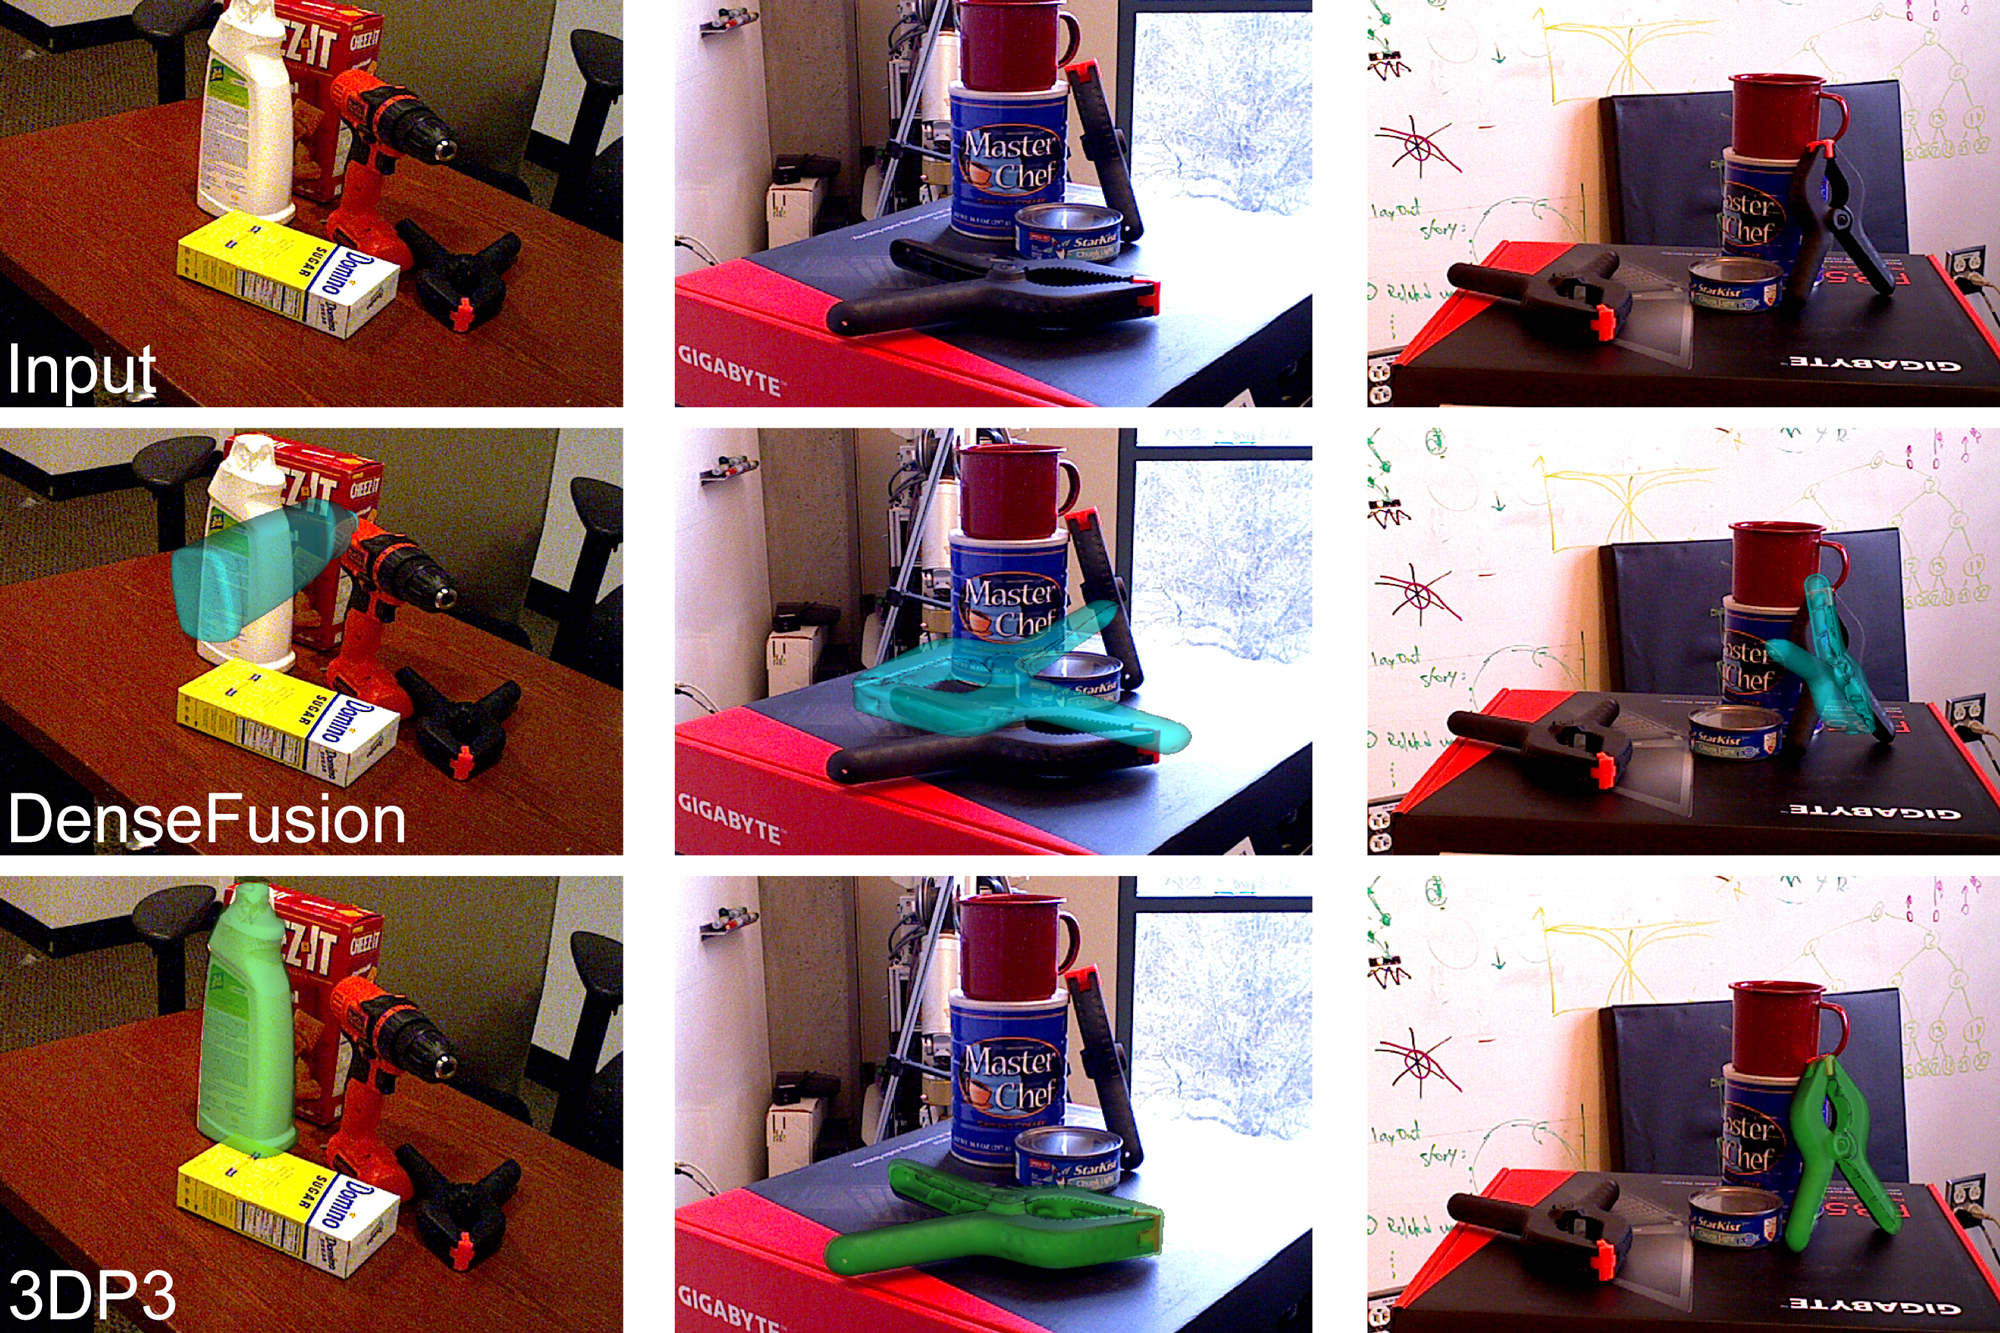
Laptop imaginative and prescient programs generally make inferences a few scene that fly within the face of frequent sense. For instance, if a robotic had been processing a scene of a dinner desk, it would fully ignore a bowl that’s seen to any human observer, estimate {that a} plate is floating above the desk, or misperceive a fork to be penetrating a bowl reasonably than leaning towards it.
Transfer that pc imaginative and prescient system to a self-driving automotive and the stakes turn out to be a lot greater — for instance, such programs have did not detect emergency autos and pedestrians crossing the road.
To beat these errors, MIT researchers have developed a framework that helps machines see the world extra like people do. Their new synthetic intelligence system for analyzing scenes learns to understand real-world objects from only a few pictures, and perceives scenes by way of these discovered objects.
The researchers constructed the framework utilizing probabilistic programming, an AI method that permits the system to cross-check detected objects towards enter knowledge, to see if the photographs recorded from a digicam are a probable match to any candidate scene. Probabilistic inference permits the system to deduce whether or not mismatches are seemingly as a result of noise or to errors within the scene interpretation that must be corrected by additional processing.
This common sense safeguard permits the system to detect and proper many errors that plague the “deep-learning” approaches which have additionally been used for pc imaginative and prescient. Probabilistic programming additionally makes it attainable to deduce possible contact relationships between objects within the scene, and use common sense reasoning about these contacts to deduce extra correct positions for objects.
“Should you don’t know concerning the contact relationships, then you could possibly say that an object is floating above the desk — that might be a sound clarification. As people, it’s apparent to us that that is bodily unrealistic and the thing resting on prime of the desk is a extra seemingly pose of the thing. As a result of our reasoning system is conscious of this kind of data, it will possibly infer extra correct poses. That may be a key perception of this work,” says lead creator Nishad Gothoskar, {an electrical} engineering and pc science (EECS) PhD pupil with the Probabilistic Computing Venture.
Along with enhancing the security of self-driving automobiles, this work might improve the efficiency of pc notion programs that should interpret difficult preparations of objects, like a robotic tasked with cleansing a cluttered kitchen.
Gothoskar’s co-authors embody current EECS PhD graduate Marco Cusumano-Towner; analysis engineer Ben Zinberg; visiting pupil Matin Ghavamizadeh; Falk Pollok, a software program engineer within the MIT-IBM Watson AI Lab; current EECS grasp’s graduate Austin Garrett; Dan Gutfreund, a principal investigator within the MIT-IBM Watson AI Lab; Joshua B. Tenenbaum, the Paul E. Newton Profession Growth Professor of Cognitive Science and Computation within the Division of Mind and Cognitive Sciences (BCS) and a member of the Laptop Science and Synthetic Intelligence Laboratory; and senior creator Vikash Ok. Mansinghka, principal analysis scientist and chief of the Probabilistic Computing Venture in BCS. The analysis is being offered on the Convention on Neural Data Processing Methods in December.
A blast from the previous
To develop the system, referred to as “3D Scene Notion through Probabilistic Programming (3DP3),” the researchers drew on an idea from the early days of AI analysis, which is that pc imaginative and prescient may be considered the “inverse” of pc graphics.
Laptop graphics focuses on producing pictures primarily based on the illustration of a scene; pc imaginative and prescient may be seen because the inverse of this course of. Gothoskar and his collaborators made this system extra learnable and scalable by incorporating it right into a framework constructed utilizing probabilistic programming.
“Probabilistic programming permits us to put in writing down our data about some points of the world in a means a pc can interpret, however on the similar time, it permits us to precise what we don’t know, the uncertainty. So, the system is ready to robotically be taught from knowledge and likewise robotically detect when the foundations don’t maintain,” Cusumano-Towner explains.
On this case, the mannequin is encoded with prior data about 3D scenes. For example, 3DP3 “is aware of” that scenes are composed of various objects, and that these objects usually lay flat on prime of one another — however they might not all the time be in such easy relationships. This permits the mannequin to motive a few scene with extra frequent sense.
Studying shapes and scenes
To research a picture of a scene, 3DP3 first learns concerning the objects in that scene. After being proven solely 5 pictures of an object, every taken from a distinct angle, 3DP3 learns the thing’s form and estimates the amount it could occupy in house.
“If I present you an object from 5 totally different views, you possibly can construct a fairly good illustration of that object. You’d perceive its colour, its form, and also you’d be capable of acknowledge that object in many alternative scenes,” Gothoskar says.
Mansinghka provides, “That is means much less knowledge than deep-learning approaches. For instance, the Dense Fusion neural object detection system requires hundreds of coaching examples for every object kind. In distinction, 3DP3 solely requires just a few pictures per object, and studies uncertainty concerning the components of every objects’ form that it does not know.”
The 3DP3 system generates a graph to characterize the scene, the place every object is a node and the traces that join the nodes point out which objects are in touch with each other. This permits 3DP3 to provide a extra correct estimation of how the objects are organized. (Deep-learning approaches depend on depth pictures to estimate object poses, however these strategies don’t produce a graph construction of contact relationships, so their estimations are much less correct.)
Outperforming baseline fashions
The researchers in contrast 3DP3 with a number of deep-learning programs, all tasked with estimating the poses of 3D objects in a scene.
In almost all situations, 3DP3 generated extra correct poses than different fashions and carried out much better when some objects had been partially obstructing others. And 3DP3 solely wanted to see 5 pictures of every object, whereas every of the baseline fashions it outperformed wanted hundreds of pictures for coaching.
When used at the side of one other mannequin, 3DP3 was capable of enhance its accuracy. For example, a deep-learning mannequin may predict {that a} bowl is floating barely above a desk, however as a result of 3DP3 has data of the contact relationships and may see that that is an unlikely configuration, it is ready to make a correction by aligning the bowl with the desk.
“I discovered it stunning to see how massive the errors from deep studying might generally be — producing scene representations the place objects actually didn’t match with what folks would understand. I additionally discovered it stunning that solely a bit of little bit of model-based inference in our causal probabilistic program was sufficient to detect and repair these errors. After all, there’s nonetheless an extended option to go to make it quick and sturdy sufficient for difficult real-time imaginative and prescient programs — however for the primary time, we’re seeing probabilistic programming and structured causal fashions enhancing robustness over deep studying on onerous 3D imaginative and prescient benchmarks,” Mansinghka says.
Sooner or later, the researchers wish to push the system additional so it will possibly find out about an object from a single picture, or a single body in a film, after which be capable of detect that object robustly in several scenes. They might additionally prefer to discover using 3DP3 to collect coaching knowledge for a neural community. It’s usually troublesome for people to manually label pictures with 3D geometry, so 3DP3 might be used to generate extra complicated picture labels.
The 3DP3 system “combines low-fidelity graphics modeling with common sense reasoning to appropriate massive scene interpretation errors made by deep studying neural nets. Such a method might have broad applicability because it addresses vital failure modes of deep studying. The MIT researchers’ accomplishment additionally exhibits how probabilistic programming know-how beforehand developed beneath DARPA’s Probabilistic Programming for Advancing Machine Studying (PPAML) program may be utilized to resolve central issues of common sense AI beneath DARPA’s present Machine Frequent Sense (MCS) program,” says Matt Turek, DARPA Program Supervisor for the Machine Frequent Sense Program, who was not concerned on this analysis, although this system partially funded the examine.
Extra funders embody the Singapore Protection Science and Know-how Company collaboration with the MIT Schwarzman Faculty of Computing, Intel’s Probabilistic Computing Middle, the MIT-IBM Watson AI Lab, the Aphorism Basis, and the Siegel Household Basis.
[ad_2]

