

[ad_1]
Logging is a strategy to retailer details about your script and observe occasions that happen. When writing any advanced script in Python, logging is important for debugging software program as you develop it. With out logging, discovering the supply of an issue in your code could also be extraordinarily time consuming.
After finishing this tutorial, you’ll know:
- Why we wish to use the logging module
- How you can use the logging module
- How you can customise the logging mechanism
Let’s get began.
Logging in Python
Picture by ilaria88. Some rights reserved.
Tutorial Overview
This tutorial is split into 4 elements; they’re:
- The advantages of logging
- Fundamental logging
- Superior configuration to logging
- An instance of using logging
Advantages of Logging
Chances are you’ll ask: “Why not simply use printing?”
While you run an algorithm and wish to affirm it’s doing what you anticipated, it’s pure so as to add some print() statements at strategic places to indicate this system’s state. Printing may help debug less complicated scripts, however as your code will get increasingly advanced, printing lacks the pliability and robustness that logging has.
With logging, you may pinpoint the place a logging name got here from, differentiate severity between messages, and write data to a file, which printing can’t do. For instance, we are able to activate and off the message from a specific module of a bigger program. We are able to additionally improve or lower the verbosity of the logging messages with out altering a whole lot of code.
Fundamental Logging
Python has a built-in library, logging, for this objective. It’s easy to create a “logger” to log messages or data that you just wish to see.
The logging system in Python operates underneath a hierarchical namespace and totally different ranges of severity. The Python script can create a logger underneath a namespace, and each time a message is logged, the script should specify its severity. The logged message can go to totally different locations relying on the handler we arrange for the namespace. The commonest handler is to easily print on the display screen, like the ever-present print() perform. Once we begin this system, we might register a brand new handler and arrange the extent of severity to which the handler will react.
There are 5 totally different logging ranges that point out the severity of the logs, proven in rising severity:
- DEBUG
- INFO
- WARNING
- ERROR
- CRITICAL
A quite simple instance of logging is proven under, utilizing the default logger or the foundation logger:
|
import logging
logging.debug(‘Debug message’) logging.information(‘Data message’) logging.warning(‘Warning message’) logging.error(‘Error message’) logging.crucial(‘Essential message’) |
These will emit log messages of various severity. Whereas there are 5 traces of logging, you might even see solely three traces of output if you happen to run this script, as follows:
|
WARNING:root:This is a warning message ERROR:root:This is an error message CRITICAL:root:This is a crucial message |
It is because the foundation logger, by default, solely prints the log messages of a severity stage of WARNING or above. Nonetheless, utilizing the foundation logger this fashion isn’t a lot totally different from utilizing the print() perform.
The settings for the foundation logger will not be set in stone. We are able to configure the foundation logger to output to a specific file, change its default severity stage, and format the output. Right here’s an instance:
|
import logging
logging.basicConfig(filename = ‘file.log’, stage = logging.DEBUG, format = ‘%(asctime)s:%(levelname)s:%(identify)s:%(message)s’)
logging.debug(‘Debug message’) logging.information(‘Data message’) logging.warning(‘Warning message’) logging.error(‘Error message’) logging.crucial(‘Essential message’) |
Working this script will produce no output to the display screen however can have the next within the newly created file file.log:
|
2022-03-22 20:41:08,151:DEBUG:root:Debug message 2022-03-22 20:41:08,152:INFO:root:Data message 2022-03-22 20:41:08,152:WARNING:root:Warning message 2022-03-22 20:41:08,152:ERROR:root:Error message 2022-03-22 20:41:08,152:CRITICAL:root:Essential message |
The decision to logging.basicConfig() is to change the foundation logger. In our instance, we set the handler to output to a file as an alternative of the display screen, alter the logging stage such that every one log messages of stage DEBUG or above are dealt with, and in addition change the format of the log message output to incorporate the time.
Observe that now all 5 messages had been output, so the default stage that the foundation logger logs is now “DEBUG.” The log document attributes (resembling %(asctime)s) that can be utilized to format the output might be discovered within the logging documentation.
Though there’s a default logger, we often wish to make and use different loggers that may be configured individually. It is because we might desire a totally different severity stage or format for various loggers. A brand new logger might be created with:
|
logger = logging.getLogger(“logger_name”) |
Internally, the loggers are organized in a hierarchy. A logger created with:
|
logger = logging.getLogger(“mum or dad.youngster”) |
can be a toddler logger created underneath the logger with the identify “mum or dad,” which, in flip, is underneath the foundation logger. Utilizing a dot within the string signifies that the kid logger is a toddler of the mum or dad logger. Within the above case, a logger with the identify “mum or dad.youngster” is created in addition to one with the identify "mum or dad" implicitly.
Upon creation, a toddler logger has all of the properties of its mum or dad logger till reconfigured. We are able to show this with the next instance:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 |
import logging
# Create `mum or dad.youngster` logger logger = logging.getLogger(“mum or dad.youngster”)
# Emit a log message of stage INFO, by default this isn’t print to the display screen logger.information(“that is information stage”)
# Create `mum or dad` logger parentlogger = logging.getLogger(“mum or dad”)
# Set mum or dad’s stage to INFO and assign a brand new handler handler = logging.StreamHandler() handler.setFormatter(logging.Formatter(“%(asctime)s:%(identify)s:%(levelname)s:%(message)s”)) parentlogger.setLevel(logging.INFO) parentlogger.addHandler(handler)
# Let youngster logger emit a log message once more logger.information(“that is information stage once more”) |
This code snippet will output just one line:
|
2022–03–28 19:23:29,315:mum or dad.youngster:INFO:this is information stage once more |
which is created by the StreamHandler object with the personalized format string. It occurs solely after we reconfigured the logger for mum or dad as a result of in any other case, the foundation logger’s configuration prevails, and no messages at stage INFO can be printed.
Superior Configuration to Logging
As we noticed within the final instance, we are able to configure the loggers we made.
Threshold of Stage
Like the fundamental configuration of the foundation logger, we are able to additionally configure the output vacation spot, severity stage, and formatting of a logger. The next is how we are able to set the threshold of the extent of a logger to INFO:
|
parent_logger = logging.getLogger(“mum or dad”) parent_logger.setLevel(logging.INFO) |
Now instructions with severity stage INFO and better can be logged by the parent_logger. But when that is all you probably did, you’ll not see something from parent_logger.information("messages") as a result of there are not any handlers assigned for this logger. In truth, there are not any handlers for root logger as properly except you arrange one with logging.basicConfig().
Log Handlers
We are able to configure the output vacation spot of our logger with handlers. Handlers are answerable for sending the log messages to the right vacation spot. There are a number of kinds of handlers; the commonest ones are StreamHandler and FileHandler. With StreamHandler, the logger will output to the terminal, whereas with FileHandler, the logger will output to a specific file.
Right here’s an instance of utilizing StreamHandler to output logs to the terminal:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 |
import logging
# Arrange root logger, and add a file handler to root logger logging.basicConfig(filename = ‘file.log’, stage = logging.WARNING, format = ‘%(asctime)s:%(levelname)s:%(identify)s:%(message)s’)
# Create logger, set stage, and add stream handler parent_logger = logging.getLogger(“mum or dad”) parent_logger.setLevel(logging.INFO) parent_shandler = logging.StreamHandler() parent_logger.addHandler(parent_shandler)
# Log message of severity INFO or above can be dealt with parent_logger.debug(‘Debug message’) parent_logger.information(‘Data message’) parent_logger.warning(‘Warning message’) parent_logger.error(‘Error message’) parent_logger.crucial(‘Essential message’) |
Within the code above, there are two handlers created: A FileHandler created by logging.basicConfig() for the foundation logger and a StreamHandler created for the mum or dad logger.
Observe that though there’s a StreamHandler that sends the logs to the terminal, logs from the mum or dad logger are nonetheless being despatched to file.log since it’s a youngster of the foundation logger, and the foundation logger’s handler can also be energetic for the kid’s log messages. We are able to see that the logs to the terminal embrace INFO stage messages and above:
|
Data message Warning message Error message Essential message |
However the output to the terminal isn’t formatted, as we have now not used a Formatter but. The log to file.log, nonetheless, has a Formatter arrange, and it is going to be like the next:
|
2022-03-22 23:07:12,533:INFO:mum or dad:Data message 2022-03-22 23:07:12,533:WARNING:mum or dad:Warning message 2022-03-22 23:07:12,533:ERROR:mum or dad:Error message 2022-03-22 23:07:12,533:CRITICAL:mum or dad:Essential message |
Alternatively, we are able to use FileHandler within the above instance of parent_logger:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 |
import logging
# Arrange root logger, and add a file handler to root logger logging.basicConfig(filename = ‘file.log’, stage = logging.WARNING, format = ‘%(asctime)s:%(levelname)s:%(identify)s:%(message)s’)
# Create logger, set stage, and add stream handler parent_logger = logging.getLogger(“mum or dad”) parent_logger.setLevel(logging.INFO) parent_fhandler = logging.FileHandler(‘mum or dad.log’) parent_fhandler.setLevel(logging.WARNING) parent_logger.addHandler(parent_fhandler)
# Log message of severity INFO or above can be dealt with parent_logger.debug(‘Debug message’) parent_logger.information(‘Data message’) parent_logger.warning(‘Warning message’) parent_logger.error(‘Error message’) parent_logger.crucial(‘Essential message’) |
The instance above demonstrated that you may additionally set the extent of a handler. The extent of parent_fhandler filters out logs that aren’t WARNING stage or increased. Nonetheless, if you happen to set the handler’s stage to DEBUG, that may be the identical as not setting the extent as a result of DEBUG logs would already be filtered out by the logger’s stage, which is INFO.
On this case, the output to mum or dad.log is:
|
Warning message Error message Essential message |
whereas that of file.log is similar as earlier than. In abstract, when a log message is recorded by a logger,
- The logger’s stage will decide if the message is extreme sufficient to be dealt with. If the logger’s stage isn’t set, the extent of its mum or dad (and finally the foundation logger) can be used for this consideration.
- If the log message can be dealt with, all handlers ever added alongside the logger hierarchy as much as the foundation logger will obtain a duplicate of the message. Every handler’s stage will decide if this explicit handler ought to honor this message.
Formatters
To configure the format of the logger, we use a Formatter. It permits us to set the format of the log, equally to how we did so within the root logger’s basicConfig(). That is how we are able to add a formatter to our handler:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 |
import logging
# Arrange root logger, and add a file handler to root logger logging.basicConfig(filename = ‘file.log’, stage = logging.WARNING, format = ‘%(asctime)s:%(levelname)s:%(identify)s:%(message)s’)
# Create logger, set stage, and add stream handler parent_logger = logging.getLogger(“mum or dad”) parent_logger.setLevel(logging.INFO) parent_fhandler = logging.FileHandler(‘mum or dad.log’) parent_fhandler.setLevel(logging.WARNING) parent_formatter = logging.Formatter(‘%(asctime)s:%(levelname)s:%(message)s’) parent_fhandler.setFormatter(parent_formatter) parent_logger.addHandler(parent_fhandler)
# Log message of severity INFO or above can be dealt with parent_logger.debug(‘Debug message’) parent_logger.information(‘Data message’) parent_logger.warning(‘Warning message’) parent_logger.error(‘Error message’) parent_logger.crucial(‘Essential message’) |
First, we create a formatter, then set our handler to make use of that formatter. If we wished to, we may make a number of totally different loggers, handlers, and formatters in order that we may combine and match primarily based on our preferences.
On this instance, the mum or dad.log can have:
|
2022-03-23 13:28:31,302:WARNING:Warning message 2022-03-23 13:28:31,302:ERROR:Error message 2022-03-23 13:28:31,303:CRITICAL:Essential message |
and the file.log related to the handler at root logger can have:
|
2022-03-23 13:28:31,302:INFO:mum or dad:Data message 2022-03-23 13:28:31,302:WARNING:mum or dad:Warning message 2022-03-23 13:28:31,302:ERROR:mum or dad:Error message 2022-03-23 13:28:31,303:CRITICAL:mum or dad:Essential message |
Under is the visualization of the circulation of loggers, handlers, and formatters from the documentation of the logging module:
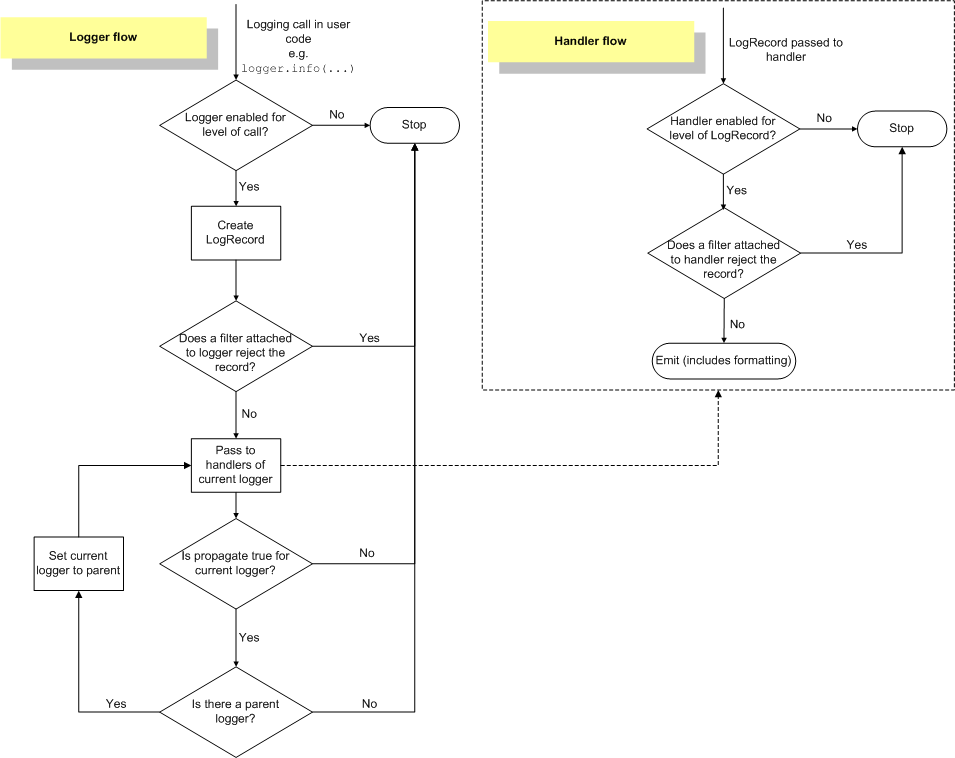
Circulate chart of loggers and handlers within the logging module
An Instance of the Use of Logging
Let’s contemplate the Nadam algorithm for instance:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 |
# gradient descent optimization with nadam for a two-dimensional check perform from math import sqrt from numpy import asarray from numpy.random import rand from numpy.random import seed
# goal perform def goal(x, y): return x**2.0 + y**2.0
# by-product of goal perform def by-product(x, y): return asarray([x * 2.0, y * 2.0])
# gradient descent algorithm with nadam def nadam(goal, by-product, bounds, n_iter, alpha, mu, nu, eps=1e–8): # generate an preliminary level x = bounds[:, 0] + rand(len(bounds)) * (bounds[:, 1] – bounds[:, 0]) rating = goal(x[0], x[1]) # initialize decaying transferring averages m = [0.0 for _ in range(bounds.shape[0])] n = [0.0 for _ in range(bounds.shape[0])] # run the gradient descent for t in vary(n_iter): # calculate gradient g(t) g = by-product(x[0], x[1]) # construct an answer one variable at a time for i in vary(bounds.form[0]): # m(t) = mu * m(t-1) + (1 – mu) * g(t) m[i] = mu * m[i] + (1.0 – mu) * g[i] # n(t) = nu * n(t-1) + (1 – nu) * g(t)^2 n[i] = nu * n[i] + (1.0 – nu) * g[i]**2 # mhat = (mu * m(t) / (1 – mu)) + ((1 – mu) * g(t) / (1 – mu)) mhat = (mu * m[i] / (1.0 – mu)) + ((1 – mu) * g[i] / (1.0 – mu)) # nhat = nu * n(t) / (1 – nu) nhat = nu * n[i] / (1.0 – nu) # x(t) = x(t-1) – alpha / (sqrt(nhat) + eps) * mhat x[i] = x[i] – alpha / (sqrt(nhat) + eps) * mhat # consider candidate level rating = goal(x[0], x[1]) # report progress print(‘>%d f(%s) = %.5f’ % (t, x, rating)) return [x, score]
# seed the pseudo random quantity generator seed(1) # outline vary for enter bounds = asarray([[–1.0, 1.0], [–1.0, 1.0]]) # outline the full iterations n_iter = 50 # steps measurement alpha = 0.02 # issue for common gradient mu = 0.8 # issue for common squared gradient nu = 0.999 # carry out the gradient descent search with nadam greatest, rating = nadam(goal, by-product, bounds, n_iter, alpha, mu, nu) print(‘Completed!’) print(‘f(%s) = %f’ % (greatest, rating)) |
The best use case is to make use of logging to interchange the print() perform. We are able to make the next change: First, create a logger with the identify nadam earlier than we run any code and assign a StreamHandler:
|
...
import logging
...
# Added: Create logger and assign handler logger = logging.getLogger(“nadam”) handler = logging.StreamHandler() handler.setFormatter(logging.Formatter(“%(asctime)s|%(levelname)s|%(identify)s|%(message)s”)) logger.addHandler(handler) logger.setLevel(logging.DEBUG) # seed the pseudo random quantity generator seed(1) ... # remainder of the code |
We should assign a handler as a result of we by no means configured the foundation logger, and this might be the one handler ever created. Then, within the perform nadam(), we re-create a logger nadam, however because it has already been arrange, the extent and handlers continued. On the finish of every outer for-loop in nadam(), we changed the print() perform with logger.information() so the message can be dealt with by the logging system:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 |
...
# gradient descent algorithm with nadam def nadam(goal, by-product, bounds, n_iter, alpha, mu, nu, eps=1e–8): # Create a logger logger = logging.getLogger(“nadam”) # generate an preliminary level x = bounds[:, 0] + rand(len(bounds)) * (bounds[:, 1] – bounds[:, 0]) rating = goal(x[0], x[1]) # initialize decaying transferring averages m = [0.0 for _ in range(bounds.shape[0])] n = [0.0 for _ in range(bounds.shape[0])] # run the gradient descent for t in vary(n_iter): # calculate gradient g(t) g = by-product(x[0], x[1]) # construct an answer one variable at a time for i in vary(bounds.form[0]): # m(t) = mu * m(t-1) + (1 – mu) * g(t) m[i] = mu * m[i] + (1.0 – mu) * g[i] # n(t) = nu * n(t-1) + (1 – nu) * g(t)^2 n[i] = nu * n[i] + (1.0 – nu) * g[i]**2 # mhat = (mu * m(t) / (1 – mu)) + ((1 – mu) * g(t) / (1 – mu)) mhat = (mu * m[i] / (1.0 – mu)) + ((1 – mu) * g[i] / (1.0 – mu)) # nhat = nu * n(t) / (1 – nu) nhat = nu * n[i] / (1.0 – nu) # x(t) = x(t-1) – alpha / (sqrt(nhat) + eps) * mhat x[i] = x[i] – alpha / (sqrt(nhat) + eps) * mhat # consider candidate level rating = goal(x[0], x[1]) # report progress utilizing logger logger.information(‘>%d f(%s) = %.5f’ % (t, x, rating)) return [x, score]
... |
If we have an interest within the deeper mechanics of the Nadam algorithm, we might add extra logs. The next is the whole code:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 |
# gradient descent optimization with nadam for a two-dimensional check perform import logging from math import sqrt from numpy import asarray from numpy.random import rand from numpy.random import seed
# goal perform def goal(x, y): return x**2.0 + y**2.0
# by-product of goal perform def by-product(x, y): return asarray([x * 2.0, y * 2.0])
# gradient descent algorithm with nadam def nadam(goal, by-product, bounds, n_iter, alpha, mu, nu, eps=1e–8): logger = logging.getLogger(“nadam”) # generate an preliminary level x = bounds[:, 0] + rand(len(bounds)) * (bounds[:, 1] – bounds[:, 0]) rating = goal(x[0], x[1]) # initialize decaying transferring averages m = [0.0 for _ in range(bounds.shape[0])] n = [0.0 for _ in range(bounds.shape[0])] # run the gradient descent for t in vary(n_iter): iterlogger = logging.getLogger(“nadam.iter”) # calculate gradient g(t) g = by-product(x[0], x[1]) # construct an answer one variable at a time for i in vary(bounds.form[0]): # m(t) = mu * m(t-1) + (1 – mu) * g(t) m[i] = mu * m[i] + (1.0 – mu) * g[i] # n(t) = nu * n(t-1) + (1 – nu) * g(t)^2 n[i] = nu * n[i] + (1.0 – nu) * g[i]**2 # mhat = (mu * m(t) / (1 – mu)) + ((1 – mu) * g(t) / (1 – mu)) mhat = (mu * m[i] / (1.0 – mu)) + ((1 – mu) * g[i] / (1.0 – mu)) # nhat = nu * n(t) / (1 – nu) nhat = nu * n[i] / (1.0 – nu) # x(t) = x(t-1) – alpha / (sqrt(nhat) + eps) * mhat x[i] = x[i] – alpha / (sqrt(nhat) + eps) * mhat iterlogger.information(“Iteration %d variable %d: mhat=%f nhat=%f”, t, i, mhat, nhat) # consider candidate level rating = goal(x[0], x[1]) # report progress logger.information(‘>%d f(%s) = %.5f’ % (t, x, rating)) return [x, score]
# Create logger and assign handler logger = logging.getLogger(“nadam”) handler = logging.StreamHandler() handler.setFormatter(logging.Formatter(“%(asctime)s|%(levelname)s|%(identify)s|%(message)s”)) logger.addHandler(handler) logger.setLevel(logging.DEBUG) logger = logging.getLogger(“nadam.iter”) logger.setLevel(logging.INFO) # seed the pseudo random quantity generator seed(1) # outline vary for enter bounds = asarray([[–1.0, 1.0], [–1.0, 1.0]]) # outline the full iterations n_iter = 50 # steps measurement alpha = 0.02 # issue for common gradient mu = 0.8 # issue for common squared gradient nu = 0.999 # carry out the gradient descent search with nadam greatest, rating = nadam(goal, by-product, bounds, n_iter, alpha, mu, nu) print(‘Completed!’) print(‘f(%s) = %f’ % (greatest, rating)) |
We ready two stage of loggers, nadam and nadam.iter, and set them in numerous ranges. Within the internal loop of nadam(), we use the kid logger to print some inner variables. While you run this script, it is going to print the next:
|
2022-03-29 12:24:59,421|INFO|nadam.iter|Iteration 0 variable 0: mhat=-0.597442 nhat=0.110055 2022-03-29 12:24:59,421|INFO|nadam.iter|Iteration 0 variable 1: mhat=1.586336 nhat=0.775909 2022-03-29 12:24:59,421|INFO|nadam|>0 f([-0.12993798 0.40463097]) = 0.18061 2022-03-29 12:24:59,421|INFO|nadam.iter|Iteration 1 variable 0: mhat=-0.680200 nhat=0.177413 2022-03-29 12:24:59,421|INFO|nadam.iter|Iteration 1 variable 1: mhat=2.020702 nhat=1.429384 2022-03-29 12:24:59,421|INFO|nadam|>1 f([-0.09764012 0.37082777]) = 0.14705 2022-03-29 12:24:59,421|INFO|nadam.iter|Iteration 2 variable 0: mhat=-0.687764 nhat=0.215332 2022-03-29 12:24:59,421|INFO|nadam.iter|Iteration 2 variable 1: mhat=2.304132 nhat=1.977457 2022-03-29 12:24:59,421|INFO|nadam|>2 f([-0.06799761 0.33805721]) = 0.11891 … 2022-03-29 12:24:59,449|INFO|nadam.iter|Iteration 49 variable 0: mhat=-0.000482 nhat=0.246709 2022-03-29 12:24:59,449|INFO|nadam.iter|Iteration 49 variable 1: mhat=-0.018244 nhat=3.966938 2022-03-29 12:24:59,449|INFO|nadam|>49 f([-5.54299505e-05 -1.00116899e-03]) = 0.00000 Completed! f([-5.54299505e-05 -1.00116899e-03]) = 0.000001 |
Setting totally different loggers not solely permits us to set a special stage or handlers, but it surely additionally lets us differentiate the place the log message comes from by wanting on the logger’s identify from the message printed.
In truth, one useful trick is to create a logging decorator and apply the decorator to some capabilities. We are able to preserve observe of each time that perform known as. For instance, we created a decorator under and utilized it to the capabilities goal() and by-product():
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 |
...
# A Python decorator to log the perform name and return worth def loggingdecorator(identify): logger = logging.getLogger(identify) def _decor(fn): function_name = fn.__name__ def _fn(*args, **kwargs): ret = fn(*args, **kwargs) argstr = [str(x) for x in args] argstr += [key+“=”+str(val) for key,val in kwargs.items()] logger.debug(“%s(%s) -> %s”, function_name, “, “.be a part of(argstr), ret) return ret return _fn return _decor
# goal perform @loggingdecorator(“nadam.perform”) def goal(x, y): return x**2.0 + y**2.0
# by-product of goal perform @loggingdecorator(“nadam.perform”) def by-product(x, y): return asarray([x * 2.0, y * 2.0]) |
Then we are going to see the next within the log:
|
2022-03-29 13:14:07,542|DEBUG|nadam.perform|goal(-0.165955990594852, 0.4406489868843162) -> 0.22171292045649288 2022-03-29 13:14:07,542|DEBUG|nadam.perform|by-product(-0.165955990594852, 0.4406489868843162) -> [-0.33191198 0.88129797] 2022-03-29 13:14:07,542|INFO|nadam.iter|Iteration 0 variable 0: mhat=-0.597442 nhat=0.110055 2022-03-29 13:14:07,542|INFO|nadam.iter|Iteration 0 variable 1: mhat=1.586336 nhat=0.775909 2022-03-29 13:14:07,542|DEBUG|nadam.perform|goal(-0.12993797816930272, 0.4046309737819536) -> 0.18061010311445824 2022-03-29 13:14:07,543|INFO|nadam|>0 f([-0.12993798 0.40463097]) = 0.18061 2022-03-29 13:14:07,543|DEBUG|nadam.perform|by-product(-0.12993797816930272, 0.4046309737819536) -> [-0.25987596 0.80926195] 2022-03-29 13:14:07,543|INFO|nadam.iter|Iteration 1 variable 0: mhat=-0.680200 nhat=0.177413 2022-03-29 13:14:07,543|INFO|nadam.iter|Iteration 1 variable 1: mhat=2.020702 nhat=1.429384 2022-03-29 13:14:07,543|DEBUG|nadam.perform|goal(-0.09764011794760165, 0.3708277653552375) -> 0.14704682419118062 2022-03-29 13:14:07,543|INFO|nadam|>1 f([-0.09764012 0.37082777]) = 0.14705 2022-03-29 13:14:07,543|DEBUG|nadam.perform|by-product(-0.09764011794760165, 0.3708277653552375) -> [-0.19528024 0.74165553] 2022-03-29 13:14:07,543|INFO|nadam.iter|Iteration 2 variable 0: mhat=-0.687764 nhat=0.215332 … |
the place we are able to see the parameters and return values of every name to these two capabilities within the message logged by the nadam.perform logger.
As we get increasingly log messages, the terminal display screen will turn out to be very busy. One strategy to make it simpler to look at for points is to focus on the logs in coloration with the colorama module. That you must have the module put in first:
Right here’s an instance of how you should utilize the colorama module with the logging module to vary your log colours and textual content brightness:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 |
import logging import colorama from colorama import Fore, Again, Fashion
# Initialize the terminal for coloration colorama.init(autoreset = True)
# Arrange logger as normal logger = logging.getLogger(“coloration”) logger.setLevel(logging.DEBUG) shandler = logging.StreamHandler() formatter = logging.Formatter(‘%(asctime)s:%(levelname)s:%(identify)s:%(message)s’) shandler.setFormatter(formatter) logger.addHandler(shandler)
# Emit log message with coloration logger.debug(‘Debug message’) logger.information(Fore.GREEN + ‘Data message’) logger.warning(Fore.BLUE + ‘Warning message’) logger.error(Fore.YELLOW + Fashion.BRIGHT + ‘Error message’) logger.crucial(Fore.RED + Again.YELLOW + Fashion.BRIGHT + ‘Essential message’) |
From the terminal, you’ll see the next: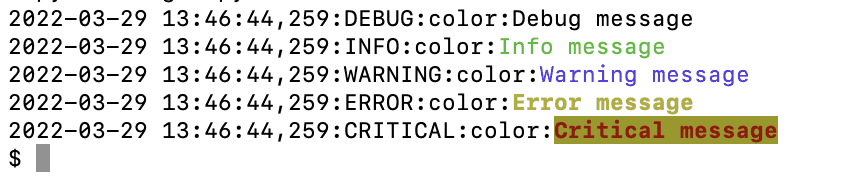
the place the Fore, Again, and Fashion from the colorama module management the foreground, background, and brightness type of the textual content printed. That is leveraging the ANSI escape characters and works solely on ANSI-supported terminals. Therefore this isn’t appropriate for logging to a textual content file.
In truth, we might derive the Formatter class with:
|
... colours = {“DEBUG”:Fore.BLUE, “INFO”:Fore.CYAN, “WARNING”:Fore.YELLOW, “ERROR”:Fore.RED, “CRITICAL”:Fore.MAGENTA} class ColoredFormatter(logging.Formatter): def format(self, document): msg = logging.Formatter.format(self, document) if document.levelname in colours: msg = colours[record.levelname] + msg + Fore.RESET return msg |
and use this as an alternative of logging.Formatter. The next is how we are able to additional modify the Nadam instance so as to add coloration:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 |
# gradient descent optimization with nadam for a two-dimensional check perform import logging import colorama from colorama import Fore
from math import sqrt from numpy import asarray from numpy.random import rand from numpy.random import seed
def loggingdecorator(identify): logger = logging.getLogger(identify) def _decor(fn): function_name = fn.__name__ def _fn(*args, **kwargs): ret = fn(*args, **kwargs) argstr = [str(x) for x in args] argstr += [key+“=”+str(val) for key,val in kwargs.items()] logger.debug(“%s(%s) -> %s”, function_name, “, “.be a part of(argstr), ret) return ret return _fn return _decor
# goal perform @loggingdecorator(“nadam.perform”) def goal(x, y): return x**2.0 + y**2.0
# by-product of goal perform @loggingdecorator(“nadam.perform”) def by-product(x, y): return asarray([x * 2.0, y * 2.0])
# gradient descent algorithm with nadam def nadam(goal, by-product, bounds, n_iter, alpha, mu, nu, eps=1e–8): logger = logging.getLogger(“nadam”) # generate an preliminary level x = bounds[:, 0] + rand(len(bounds)) * (bounds[:, 1] – bounds[:, 0]) rating = goal(x[0], x[1]) # initialize decaying transferring averages m = [0.0 for _ in range(bounds.shape[0])] n = [0.0 for _ in range(bounds.shape[0])] # run the gradient descent for t in vary(n_iter): iterlogger = logging.getLogger(“nadam.iter”) # calculate gradient g(t) g = by-product(x[0], x[1]) # construct an answer one variable at a time for i in vary(bounds.form[0]): # m(t) = mu * m(t-1) + (1 – mu) * g(t) m[i] = mu * m[i] + (1.0 – mu) * g[i] # n(t) = nu * n(t-1) + (1 – nu) * g(t)^2 n[i] = nu * n[i] + (1.0 – nu) * g[i]**2 # mhat = (mu * m(t) / (1 – mu)) + ((1 – mu) * g(t) / (1 – mu)) mhat = (mu * m[i] / (1.0 – mu)) + ((1 – mu) * g[i] / (1.0 – mu)) # nhat = nu * n(t) / (1 – nu) nhat = nu * n[i] / (1.0 – nu) # x(t) = x(t-1) – alpha / (sqrt(nhat) + eps) * mhat x[i] = x[i] – alpha / (sqrt(nhat) + eps) * mhat iterlogger.information(“Iteration %d variable %d: mhat=%f nhat=%f”, t, i, mhat, nhat) # consider candidate level rating = goal(x[0], x[1]) # report progress logger.warning(‘>%d f(%s) = %.5f’ % (t, x, rating)) return [x, score]
# Put together the coloured formatter colorama.init(autoreset = True) colours = {“DEBUG”:Fore.BLUE, “INFO”:Fore.CYAN, “WARNING”:Fore.YELLOW, “ERROR”:Fore.RED, “CRITICAL”:Fore.MAGENTA} class ColoredFormatter(logging.Formatter): def format(self, document): msg = logging.Formatter.format(self, document) if document.levelname in colours: msg = colours[record.levelname] + msg + Fore.RESET return msg
# Create logger and assign handler logger = logging.getLogger(“nadam”) handler = logging.StreamHandler() handler.setFormatter(ColoredFormatter(“%(asctime)s|%(levelname)s|%(identify)s|%(message)s”)) logger.addHandler(handler) logger.setLevel(logging.DEBUG) logger = logging.getLogger(“nadam.iter”) logger.setLevel(logging.DEBUG) # seed the pseudo random quantity generator seed(1) # outline vary for enter bounds = asarray([[–1.0, 1.0], [–1.0, 1.0]]) # outline the full iterations n_iter = 50 # steps measurement alpha = 0.02 # issue for common gradient mu = 0.8 # issue for common squared gradient nu = 0.999 # carry out the gradient descent search with nadam greatest, rating = nadam(goal, by-product, bounds, n_iter, alpha, mu, nu) print(‘Completed!’) print(‘f(%s) = %f’ % (greatest, rating)) |
If we run it on a supporting terminal, we are going to see the next output:

Observe that the colourful output may help us spot any irregular habits simpler. Logging helps with debugging and in addition permits us to simply management how a lot element we wish to see by altering just a few traces of code.
Additional Studying
This part offers extra sources on the subject if you’re seeking to go deeper.
APIs
Articles
Abstract
On this tutorial, you realized find out how to implement logging strategies in your scripts.
Particularly, you realized:
- Fundamental and superior logging strategies
- How you can apply logging to a script and the advantages of doing so
[ad_2]

