


[ad_1]
Sitemap auditing entails syntax, crawlability, and indexation checks for the URLs and tags in your sitemap recordsdata.
A sitemap file incorporates the URLs to index with additional data relating to the final modification date, precedence of the URL, pictures, movies on the URL, and different language alternates of the URL, together with the change frequency.
Sitemap index recordsdata can contain thousands and thousands of URLs, even when a single sitemap can solely contain 50,000 URLs on the high.
Auditing these URLs for higher indexation and crawling may take time.
However with the assistance of Python and web optimization automation, it’s attainable to audit thousands and thousands of URLs throughout the sitemaps.
What Do You Want To Carry out A Sitemap Audit With Python?
To know the Python Sitemap Audit course of, you’ll want:
- A elementary understanding of technical web optimization and sitemap XML recordsdata.
- Working data of Python and sitemap XML syntax.
- The power to work with Python Libraries, Pandas, Advertools, LXML, Requests, and XPath Selectors.
Which URLs Ought to Be In The Sitemap?
A wholesome sitemap XML sitemap file ought to embrace the next standards:
- All URLs ought to have a 200 Standing Code.
- All URLs ought to be self-canonical.
- URLs ought to be open to being listed and crawled.
- URLs shouldn’t be duplicated.
- URLs shouldn’t be comfortable 404s.
- The sitemap ought to have a correct XML syntax.
- The URLs within the sitemap ought to have an aligning canonical with Open Graph and Twitter Card URLs.
- The sitemap ought to have lower than 50.000 URLs and a 50 MB dimension.
What Are The Advantages Of A Wholesome XML Sitemap File?
Smaller sitemaps are higher than bigger sitemaps for sooner indexation. That is significantly vital in Information web optimization, as smaller sitemaps assist for growing the general legitimate listed URL depend.
Differentiate often up to date and static content material URLs from one another to offer a greater crawling distribution among the many URLs.
Utilizing the “lastmod” date in an sincere means that aligns with the precise publication or replace date helps a search engine to belief the date of the newest publication.
Whereas performing the Sitemap Audit for higher indexing, crawling, and search engine communication with Python, the standards above are adopted.
An Vital Observe…
In terms of a sitemap’s nature and audit, Google and Microsoft Bing don’t use “changefreq” for altering frequency of the URLs and “precedence” to grasp the prominence of a URL. The truth is, they name it a “bag of noise.”
Nevertheless, Yandex and Baidu use all these tags to grasp the web site’s traits.
A 16-Step Sitemap Audit For web optimization With Python
A sitemap audit can contain content material categorization, site-tree, or topicality and content material traits.
Nevertheless, a sitemap audit for higher indexing and crawlability primarily entails technical web optimization relatively than content material traits.
On this step-by-step sitemap audit course of, we’ll use Python to sort out the technical points of sitemap auditing thousands and thousands of URLs.
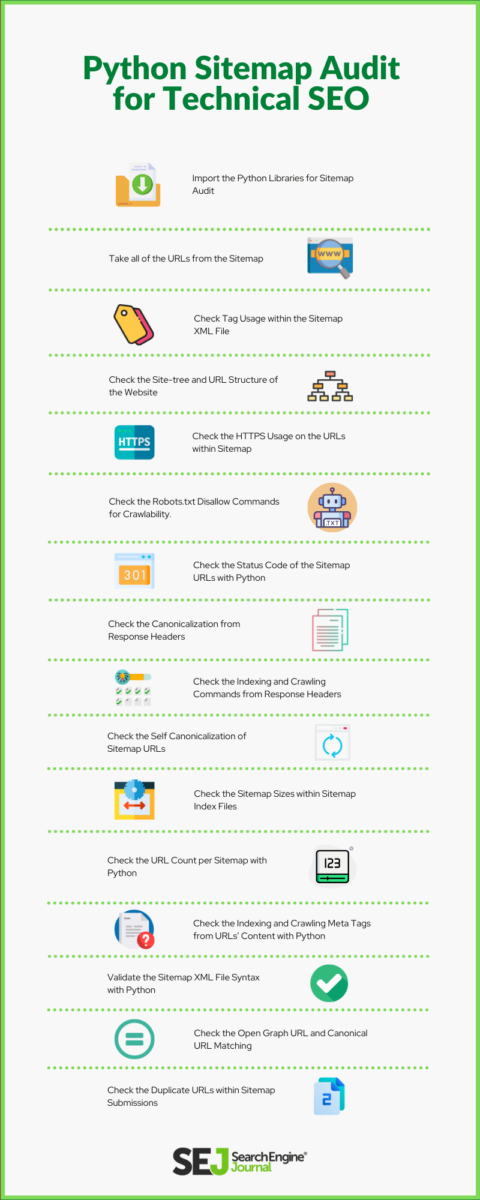 Picture created by the creator, February 2022
1. Import The Python Libraries For Your Sitemap Audit
The next code block is to import the mandatory Python Libraries for the Sitemap XML File audit.
import advertools as adv

import pandas as pd

from lxml import etree

from IPython.core.show import show, HTML

show(HTML("<fashion>.container { width:100% !vital; }</fashion>"))
Right here’s what you have to learn about this code block:
- Advertools is important for taking the URLs from the sitemap file and making a request for taking their content material or the response standing codes.
- “Pandas” is important for aggregating and manipulating the info.
- Plotly is important for the visualization of the sitemap audit output.
- LXML is important for the syntax audit of the sitemap XML file.
- IPython is optionally available to develop the output cells of Jupyter Pocket book to 100% width.
2. Take All Of The URLs From The Sitemap
Tens of millions of URLs may be taken right into a Pandas information body with Advertools, as proven beneath.
sitemap_url = "https://www.complaintsboard.com/sitemap.xml"
sitemap = adv.sitemap_to_df(sitemap_url)
sitemap.to_csv("sitemap.csv")
sitemap_df = pd.read_csv("sitemap.csv", index_col=False)
sitemap_df.drop(columns=["Unnamed: 0"], inplace=True)
sitemap_df
Above, the Complaintsboard.com sitemap has been taken right into a Pandas information body, and you may see the output beneath.
-
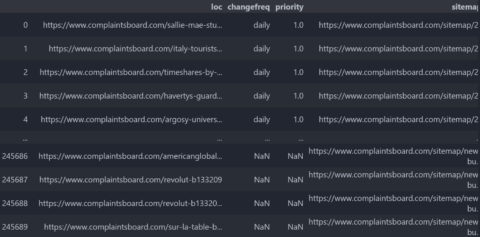 A Common Sitemap URL Extraction with Sitemap Tags with Python is above.
In whole, we’ve 245,691 URLs within the sitemap index file of Complaintsboard.com.
The web site makes use of “changefreq,” “lastmod,” and “precedence” with an inconsistency.
3. Test Tag Utilization Inside The Sitemap XML File
To know which tags are used or not throughout the Sitemap XML file, use the operate beneath.
def check_sitemap_tag_usage(sitemap):
     lastmod = sitemap["lastmod"].isna().value_counts()
     precedence = sitemap["priority"].isna().value_counts()
     changefreq = sitemap["changefreq"].isna().value_counts()
     lastmod_perc = sitemap["lastmod"].isna().value_counts(normalize = True) * 100
     priority_perc = sitemap["priority"].isna().value_counts(normalize = True) * 100
     changefreq_perc = sitemap["changefreq"].isna().value_counts(normalize = True) * 100
     sitemap_tag_usage_df = pd.DataFrame(information={"lastmod":lastmod,
     "precedence":precedence,
     "changefreq":changefreq,
     "lastmod_perc": lastmod_perc,
     "priority_perc": priority_perc,
     "changefreq_perc": changefreq_perc})
     return sitemap_tag_usage_df.astype(int)
The operate check_sitemap_tag_usage is a knowledge body constructor primarily based on the utilization of the sitemap tags.
It takes the “lastmod,” “precedence,” and “changefreq” columns by implementing “isna()” and “value_counts()” strategies through “pd.DataFrame”.
Under, you possibly can see the output.
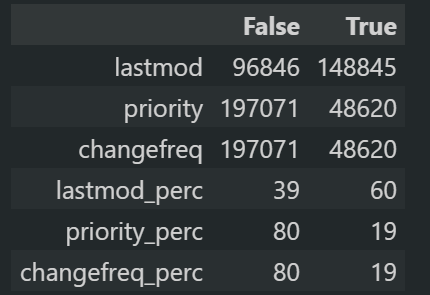 Sitemap Audit with Python for sitemap tags’ utilization.
The info body above exhibits that 96,840 of the URLs don’t have the Lastmod tag, which is the same as 39% of the full URL depend of the sitemap file.
The identical utilization proportion is nineteen% for the “precedence” and the “changefreq” throughout the sitemap XML file.
There are three important content material freshness alerts from a web site.
These are dates from an online web page (seen to the consumer), structured information (invisible to the consumer), “lastmod” within the sitemap.
If these dates usually are not in step with one another, search engines like google can ignore the dates on the web sites to see their freshness alerts.
4. Audit The Web site-tree And URL Construction Of The Web site
Understanding an important or crowded URL Path is important to weigh the web site’s web optimization efforts or technical web optimization Audits.
A single enchancment for Technical web optimization can profit hundreds of URLs concurrently, which creates a cheap and budget-friendly web optimization technique.
URL Construction Understanding primarily focuses on the web site’s extra distinguished sections and content material community evaluation understanding.
To create a URL Tree Dataframe from a web site’s URLs from the sitemap, use the next code block.
sitemap_url_df = adv.url_to_df(sitemap_df["loc"])
sitemap_url_df
With the assistance of “urllib” or the “advertools” as above, you possibly can simply parse the URLs throughout the sitemap into a knowledge body.
-
Making a URL Tree with URLLib or Advertools is simple.
- Checking the URL breakdowns helps to grasp the general data tree of a web site.
The info body above incorporates the “scheme,” “netloc,” “path,” and each “/” breakdown throughout the URLs as a “dir” which represents the listing.
Auditing the URL construction of the web site is distinguished for 2 goals.
These are checking whether or not all URLs have “HTTPS” and understanding the content material community of the web site.
Content material evaluation with sitemap recordsdata is just not the subject of the “Indexing and Crawling” instantly, thus on the finish of the article, we’ll speak about it barely.
Test the following part to see the SSL Utilization on Sitemap URLs.
5. Test The HTTPS Utilization On The URLs Inside Sitemap
Use the next code block to examine the HTTP Utilization ratio for the URLs throughout the Sitemap.
sitemap_url_df["scheme"].value_counts().to_frame()
The code block above makes use of a easy information filtration for the “scheme” column which incorporates the URLs’ HTTPS Protocol data.
utilizing the “value_counts” we see that each one URLs are on the HTTPS.
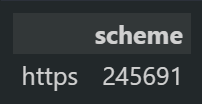 Checking the HTTP URLs from the Sitemaps may also help to seek out larger URL Property consistency errors.
6. Test The Robots.txt Disallow Instructions For Crawlability
The construction of URLs throughout the sitemap is helpful to see whether or not there’s a state of affairs for “submitted however disallowed”.
To see whether or not there’s a robots.txt file of the web site, use the code block beneath.
import requests
r = requests.get("https://www.complaintsboard.com/robots.txt")
R.status_code
200
Merely, we ship a “get request” to the robots.txt URL.
If the response standing code is 200, it means there’s a robots.txt file for the user-agent-based crawling management.
After checking the “robots.txt” existence, we are able to use the “adv.robotstxt_test” methodology for bulk robots.txt audit for crawlability of the URLs within the sitemap.
sitemap_df_robotstxt_check = adv.robotstxt_test("https://www.complaintsboard.com/robots.txt", urls=sitemap_df["loc"], user_agents=["*"])
sitemap_df_robotstxt_check["can_fetch"].value_counts()
We’ve created a brand new variable known as “sitemap_df_robotstxt_check”, and assigned the output of the “robotstxt_test” methodology.
We’ve used the URLs throughout the sitemap with the “sitemap_df[“loc”]”.
We’ve carried out the audit for the entire user-agents through the “user_agents = [“*”]” parameter and worth pair.
You possibly can see the end result beneath.
True     245690
False         1
Title: can_fetch, dtype: int64
It exhibits that there’s one URL that’s disallowed however submitted.
We will filter the precise URL as beneath.
pd.set_option("show.max_colwidth",255)
sitemap_df_robotstxt_check[sitemap_df_robotstxt_check["can_fetch"] == False]
We’ve used “set_option” to develop the entire values throughout the “url_path” part.
-
 A URL seems as disallowed however submitted through a sitemap as in Google Search Console Protection Stories.
- We see {that a} “profile” web page has been disallowed and submitted.
Later, the identical management may be achieved for additional examinations corresponding to “disallowed however internally linked”.
However, to try this, we have to crawl not less than 3 million URLs from ComplaintsBoard.com, and it may be a wholly new information.
Some web site URLs don’t have a correct “listing hierarchy”, which might make the evaluation of the URLs, by way of content material community traits, tougher.
Complaintsboard.com doesn’t use a correct URL construction and taxonomy, so analyzing the web site construction is just not simple for an web optimization or Search Engine.
However essentially the most used phrases throughout the URLs or the content material replace frequency can sign which subject the corporate really weighs on.
Since we give attention to “technical points” on this tutorial, you possibly can learn the Sitemap Content material Audit right here.
7. Test The Standing Code Of The Sitemap URLs With Python
Each URL throughout the sitemap has to have a 200 Standing Code.
A crawl must be carried out to examine the standing codes of the URLs throughout the sitemap.
However, because it’s pricey when you’ve gotten thousands and thousands of URLs to audit, we are able to merely use a brand new crawling methodology from Advertools.
With out taking the response physique, we are able to crawl simply the response headers of the URLs throughout the sitemap.
It’s helpful to lower the crawl time for auditing attainable robots, indexing, and canonical alerts from the response headers.
To carry out a response header crawl, use the “adv.crawl_headers” methodology.
adv.crawl_headers(sitemap_df["loc"], output_file="sitemap_df_header.jl")
df_headers = pd.read_json("sitemap_df_header.jl", strains=True)
df_headers["status"].value_counts()
The reason of the code block for checking the URLs’ standing codes throughout the Sitemap XML Recordsdata for the Technical web optimization facet may be seen beneath.
200    207866
404        23
Title: standing, dtype: int64
It exhibits that the 23 URL from the sitemap is definitely 404.
And, they need to be faraway from the sitemap.
To audit which URLs from the sitemap are 404, use the filtration methodology beneath from Pandas.
df_headers[df_headers["status"] == 404]
The end result may be seen beneath.
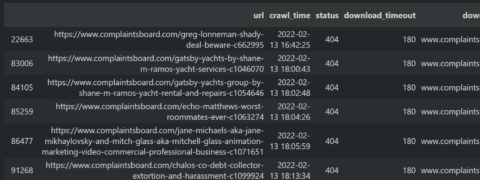 Discovering the 404 URLs from Sitemaps is useful towards Hyperlink Rot.
8. Test The Canonicalization From Response Headers
Every so often, utilizing canonicalization hints on the response headers is helpful for crawling and indexing sign consolidation.
On this context, the canonical tag on the HTML and the response header must be the identical.
If there are two totally different canonicalization alerts on an online web page, the various search engines can ignore each assignments.
For ComplaintsBoard.com, we don’t have a canonical response header.
- Step one is auditing whether or not the response header for canonical utilization exists.
- The second step is evaluating the response header canonical worth to the HTML canonical worth if it exists.
- The third step is checking whether or not the canonical values are self-referential.
Test the columns of the output of the header crawl to examine the Canonicalization from Response Headers.
df_headers.columns
Under, you possibly can see the columns.
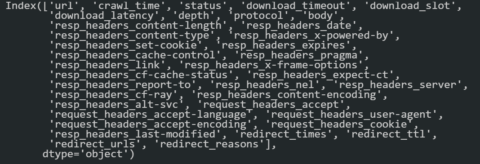 Python web optimization Crawl Output Information Body columns. “dataframe.columns” methodology is at all times helpful to examine.
In case you are not accustomed to the response headers, you might not know methods to use canonical hints inside response headers.
A response header can embrace the canonical trace with the “Hyperlink” worth.
It’s registered as “resp_headers_link” by the Advertools instantly.
One other downside is that the extracted strings seem throughout the “<URL>;” string sample.
It means we’ll use regex to extract it.
df_headers["resp_headers_link"]
You possibly can see the end result beneath.
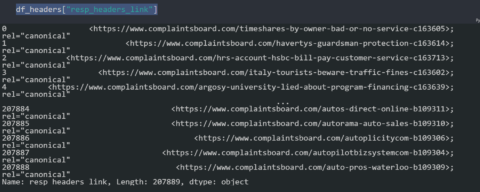 Screenshot from Pandas, February 2022
The regex sample “[^<>][a-z:/0-9-.]*” is nice sufficient to extract the precise canonical worth.
A self-canonicalization examine with the response headers is beneath.
df_headers["response_header_canonical"] = df_headers["resp_headers_link"].str.extract(r"([^<>][a-z:/0-9-.]*)")
(df_headers["response_header_canonical"] == df_headers["url"]).value_counts()
We’ve used two totally different boolean checks.
One to examine whether or not the response header canonical trace is the same as the URL itself.
One other to see whether or not the standing code is 200.
Since we’ve 404 URLs throughout the sitemap, their canonical worth will probably be “NaN”.
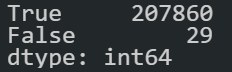 It exhibits there are particular URLs with canonicalization inconsistencies.
- We’ve 29 outliers for Technical web optimization. Each incorrect sign given to the search engine for indexation or rating will trigger the dilution of the rating alerts.
To see these URLs, use the code block beneath.
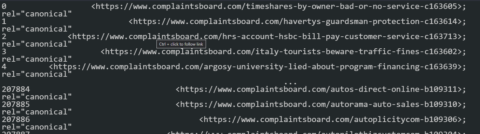 Screenshot from Pandas, February 2022.
The Canonical Values from the Response Headers may be seen above.
df_headers[(df_headers["response_header_canonical"] != df_headers["url"]) & (df_headers["status"] == 200)]
Even a single “/” within the URL could cause canonicalization battle as seems right here for the homepage.
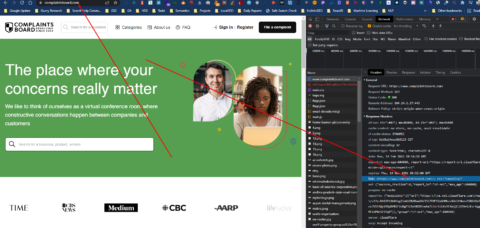 ComplaintsBoard.com Screenshot for checking the Response Header Canonical Worth and the Precise URL of the net web page.
- You possibly can examine the canonical battle right here.
Should you examine log recordsdata, you will notice that the search engine crawls the URLs from the “Hyperlink” response headers.
Thus in technical web optimization, this ought to be weighted.
9. Test The Indexing And Crawling Instructions From Response Headers
There are 14 totally different X-Robots-Tag specs for the Google search engine crawler.
The newest one is “indexifembedded” to find out the indexation quantity on an online web page.
The Indexing and Crawling directives may be within the type of a response header or the HTML meta tag.
This part focuses on the response header model of indexing and crawling directives.
- Step one is checking whether or not the X-Robots-Tag property and values exist throughout the HTTP Header or not.
- The second step is auditing whether or not it aligns itself with the HTML Meta Tag properties and values in the event that they exist.
Use the command beneath yo examine the X-Robots-Tag” from the response headers.
def robots_tag_checker(dataframe:pd.DataFrame):
     for i in df_headers:
          if i.__contains__("robots"):
               return i
          else:
               return "There isn't a robots tag"
robots_tag_checker(df_headers)
OUTPUT>>>
'There isn't a robots tag'
We’ve created a customized operate to examine the “X-Robots-tag” response headers from the net pages’ supply code.
It seems that our take a look at topic web site doesn’t use the X-Robots-Tag.
If there could be an X-Robots-tag, the code block beneath ought to be used.
df_headers["response_header_x_robots_tag"].value_counts()
df_headers[df_headers["response_header_x_robots_tag"] == "noindex"]
Test whether or not there’s a “noindex” directive from the response headers, and filter the URLs with this indexation battle.
Within the Google Search Console Protection Report, these seem as “Submitted marked as noindex”.
Contradicting indexing and canonicalization hints and alerts may make a search engine ignore the entire alerts whereas making the search algorithms belief much less to the user-declared alerts.
10. Test The Self Canonicalization Of Sitemap URLs
Each URL within the sitemap XML recordsdata ought to give a self-canonicalization trace.
Sitemaps ought to solely embrace the canonical variations of the URLs.
The Python code block on this part is to grasp whether or not the sitemap URLs have self-canonicalization values or not.
To examine the canonicalization from the HTML Paperwork’ “<head>” part, crawl the web sites by taking their response physique.
Use the code block beneath.
user_agent = "Mozilla/5.0 (Linux; Android 6.0.1; Nexus 5X Construct/MMB29P) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/W.X.Y.Z Cellular Safari/537.36 (suitable; Googlebot/2.1; +http://www.google.com/bot.html)"
The distinction between “crawl_headers” and the “crawl” is that “crawl” takes all the response physique whereas the “crawl_headers” is just for response headers.
adv.crawl(sitemap_df["loc"],

output_file="sitemap_crawl_complaintsboard.jl",

follow_links=False,

custom_settings={"LOG_FILE":"sitemap_crawl_complaintsboard.log", “USER_AGENT”:user_agent})
You possibly can examine the file dimension variations from crawl logs to response header crawl and whole response physique crawl.
 Python Crawl Output Measurement Comparability.
From 6GB output to the 387 MB output is kind of economical.
If a search engine simply needs to see sure response headers and the standing code, creating data on the headers would make their crawl hits extra economical.
How To Deal With Massive DataFrames For Studying And Aggregating Information?
This part requires coping with the big information frames.
A pc can’t learn a Pandas DataFrame from a CSV or JL file if the file dimension is bigger than the pc’s RAM.
Thus, the “chunking” methodology is used.
When a web site sitemap XML File incorporates thousands and thousands of URLs, the full crawl output will probably be bigger than tens of gigabytes.
An iteration throughout sitemap crawl output information body rows is important.
For chunking, use the code block beneath.
df_iterator = pd.read_json(

    'sitemap_crawl_complaintsboard.jl',

    chunksize=10000,

     strains=True)
for i, df_chunk in enumerate(df_iterator):

    output_df = pd.DataFrame(information={"url":df_chunk["url"],"canonical":df_chunk["canonical"], "self_canonicalised":df_chunk["url"] == df_chunk["canonical"]})
    mode="w" if i == 0 else 'a'

    header = i == 0

    output_df.to_csv(

        "canonical_check.csv",

        index=False,

        header=header,

        mode=mode

       )

df[((df["url"] != df["canonical"]) == True) & (df["self_canonicalised"] == False) & (df["canonical"].isna() != True)]
You possibly can see the end result beneath.
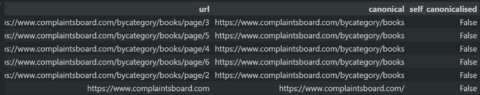 Python web optimization Canonicalization Audit.
We see that the paginated URLs from the “e book” subfolder give canonical hints to the primary web page, which is a non-correct observe in keeping with the Google tips.
11. Test The Sitemap Sizes Inside Sitemap Index Recordsdata
Each Sitemap File ought to be lower than 50 MB. Use the Python code block beneath within the Technical web optimization with Python context to examine the sitemap file dimension.
pd.pivot_table(sitemap_df[sitemap_df["loc"].duplicated()==True], index="sitemap")
You possibly can see the end result beneath.
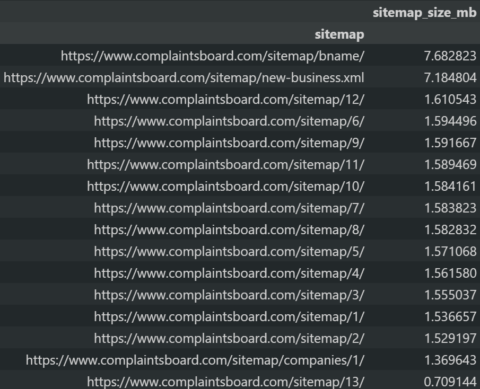 Python web optimization Sitemap Measurement Audit.
We see that each one sitemap XML recordsdata are below 50MB.
For higher and sooner indexation, protecting the sitemap URLs worthwhile and distinctive whereas reducing the scale of the sitemap recordsdata is helpful.
12. Test The URL Depend Per Sitemap With Python
Each URL throughout the sitemaps ought to have fewer than 50.000 URLs.
Use the Python code block beneath to examine the URL Counts throughout the sitemap XML recordsdata.
(pd.pivot_table(sitemap_df,

values=["loc"],

index="sitemap",

aggfunc="depend")

.sort_values(by="loc", ascending=False))
You possibly can see the end result beneath.
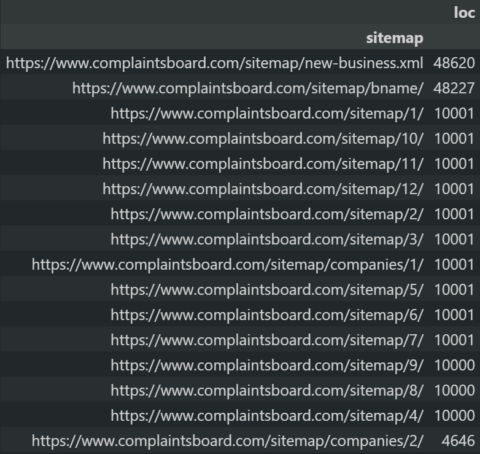 Python web optimization Sitemap URL Depend Audit.
- All sitemaps have lower than 50.000 URLs. Some sitemaps have just one URL, which wastes the search engine’s consideration.
Retaining sitemap URLs which are often up to date totally different from the static and rancid content material URLs is helpful.
URL Depend and URL Content material character variations assist a search engine to regulate crawl demand successfully for various web site sections.
13. Test The Indexing And Crawling Meta Tags From URLs’ Content material With Python
Even when an online web page is just not disallowed from robots.txt, it might probably nonetheless be disallowed from the HTML Meta Tags.
Thus, checking the HTML Meta Tags for higher indexation and crawling is important.
Utilizing the “customized selectors” is important to carry out the HTML Meta Tag audit for the sitemap URLs.
sitemap = adv.sitemap_to_df("https://www.holisticseo.digital/sitemap.xml")

adv.crawl(url_list=sitemap["loc"][:1000], output_file="meta_command_audit.jl",

follow_links=False,

xpath_selectors= {"meta_command": "//meta[@name="robots"]/@content material"},

custom_settings={"CLOSESPIDER_PAGECOUNT":1000})

df_meta_check = pd.read_json("meta_command_audit.jl", strains=True)

df_meta_check["meta_command"].str.incorporates("nofollow|noindex", regex=True).value_counts()
The “//meta[@name=”robots”]/@content material” XPATH selector is to extract all of the robots instructions from the URLs from the sitemap.
We’ve used solely the primary 1000 URLs within the sitemap.
And, I cease crawling after the preliminary 1000 responses.
I’ve used one other web site to examine the Crawling Meta Tags since ComplaintsBoard.com doesn’t have it on the supply code.
You possibly can see the end result beneath.
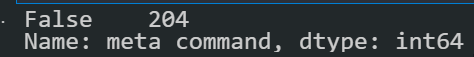 Python web optimization Meta Robots Audit.
- Not one of the URLs from the sitemap have “nofollow” or “noindex” throughout the “Robots” instructions.
To examine their values, use the code beneath.
df_meta_check[df_meta_check["meta_command"].str.incorporates("nofollow|noindex", regex=True) == False][["url", "meta_command"]]
You possibly can see the end result beneath.
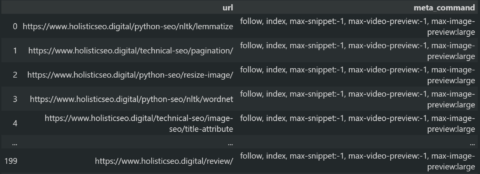 Meta Tag Audit from the Web sites.
14. Validate The Sitemap XML File Syntax With Python
Sitemap XML File Syntax validation is important to validate the mixing of the sitemap file with the search engine’s notion.
Even when there are particular syntax errors, a search engine can acknowledge the sitemap file through the XML Normalization.
However, each syntax error can lower the effectivity for sure ranges.
Use the code block beneath to validate the Sitemap XML File Syntax.
def validate_sitemap_syntax(xml_path: str, xsd_path: str)
    xmlschema_doc = etree.parse(xsd_path)
    xmlschema = etree.XMLSchema(xmlschema_doc)
    xml_doc = etree.parse(xml_path)
    end result = xmlschema.validate(xml_doc)
    return end result
validate_sitemap_syntax("sej_sitemap.xml", "sitemap.xsd")
For this instance, I’ve used “https://www.searchenginejournal.com/sitemap_index.xml”. The XSD file entails the XML file’s context and tree construction.
It’s said within the first line of the Sitemap file as beneath.
For additional data, you can even examine DTD documentation.
15. Test The Open Graph URL And Canonical URL Matching
It’s not a secret that search engines like google additionally use the Open Graph and RSS Feed URLs from the supply code for additional canonicalization and exploration.
The Open Graph URLs ought to be the identical because the canonical URL submission.
Every so often, even in Google Uncover, Google chooses to make use of the picture from the Open Graph.
To examine the Open Graph URL and Canonical URL consistency, use the code block beneath.
for i, df_chunk in enumerate(df_iterator):

    if "og:url" in df_chunk.columns:

        output_df = pd.DataFrame(information={

        "canonical":df_chunk["canonical"],

        "og:url":df_chunk["og:url"],

        "open_graph_canonical_consistency":df_chunk["canonical"] == df_chunk["og:url"]})

        mode="w" if i == 0 else 'a'

        header = i == 0

        output_df.to_csv(

            "open_graph_canonical_consistency.csv",

            index=False,

            header=header,

            mode=mode

        )
    else:

        print("There isn't a Open Graph URL Property")
There isn't a Open Graph URL Property
If there’s an Open Graph URL Property on the web site, it is going to give a CSV file to examine whether or not the canonical URL and the Open Graph URL are the identical or not.
However for this web site, we don’t have an Open Graph URL.
Thus, I’ve used one other web site for the audit.
if "og:url" in df_meta_check.columns:

     output_df = pd.DataFrame(information={

     "canonical":df_meta_check["canonical"],

     "og:url":df_meta_check["og:url"],

     "open_graph_canonical_consistency":df_meta_check["canonical"] == df_meta_check["og:url"]})

     mode="w" if i == 0 else 'a'

     #header = i == 0

     output_df.to_csv(

            "df_og_url_canonical_audit.csv",

            index=False,

            #header=header,

            mode=mode
     )

else:

     print("There isn't a Open Graph URL Property")

df = pd.read_csv("df_og_url_canonical_audit.csv")

df
You possibly can see the end result beneath.
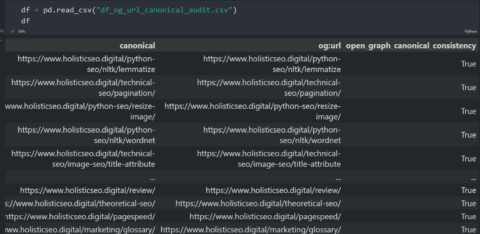 Python web optimization Open Graph URL Audit.
We see that each one canonical URLs and the Open Graph URLs are the identical.
 Python web optimization Canonicalization Audit.
16. Test The Duplicate URLs Inside Sitemap Submissions
A sitemap index file shouldn’t have duplicated URLs throughout totally different sitemap recordsdata or throughout the similar sitemap XML file.
The duplication of the URLs throughout the sitemap recordsdata could make a search engine obtain the sitemap recordsdata much less since a sure proportion of the sitemap file is bloated with pointless submissions.
For sure conditions, it might probably seem as a spamming try to manage the crawling schemes of the search engine crawlers.
use the code block beneath to examine the duplicate URLs throughout the sitemap submissions.
sitemap_df["loc"].duplicated().value_counts()
You possibly can see that the 49574 URLs from the sitemap are duplicated.
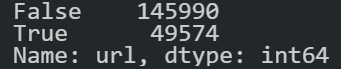 Python web optimization Duplicated URL Audit from the Sitemap XML Recordsdata
To see which sitemaps have extra duplicated URLs, use the code block beneath.
pd.pivot_table(sitemap_df[sitemap_df["loc"].duplicated()==True], index="sitemap", values="loc", aggfunc="depend").sort_values(by="loc", ascending=False)
You possibly can see the end result.
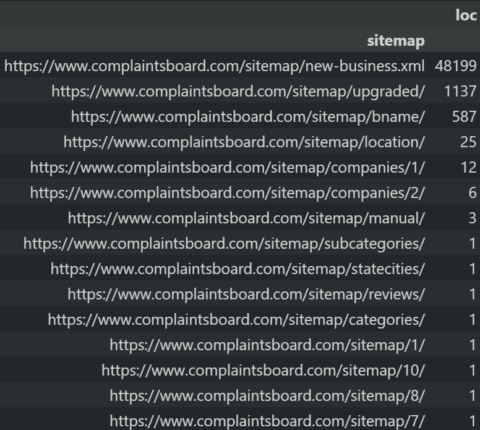 Python web optimization Sitemap Audit for duplicated URLs.
Chunking the sitemaps may also help with site-tree and technical web optimization evaluation.
To see the duplicated URLs throughout the Sitemap, use the code block beneath.
sitemap_df[sitemap_df["loc"].duplicated() == True]
You possibly can see the end result beneath.
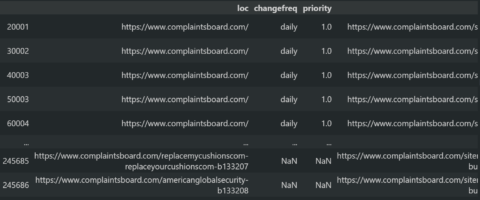 Duplicated Sitemap URL Audit Output.
Conclusion
I wished to indicate methods to validate a sitemap file for higher and more healthy indexation and crawling for Technical web optimization.
Python is vastly used for information science, machine studying, and pure language processing.
However, you can even use it for Technical web optimization Audits to help the opposite web optimization Verticals with a Holistic web optimization Strategy.
In a future article, we are able to develop these Technical web optimization Audits additional with totally different particulars and strategies.
However, generally, this is without doubt one of the most complete Technical web optimization guides for Sitemaps and Sitemap Audit Tutorial with Python.
Extra assets:
Featured Picture: elenasavchina2/Shutterstock
[ad_2]

