


[ad_1]
|
Take heed to this text  |
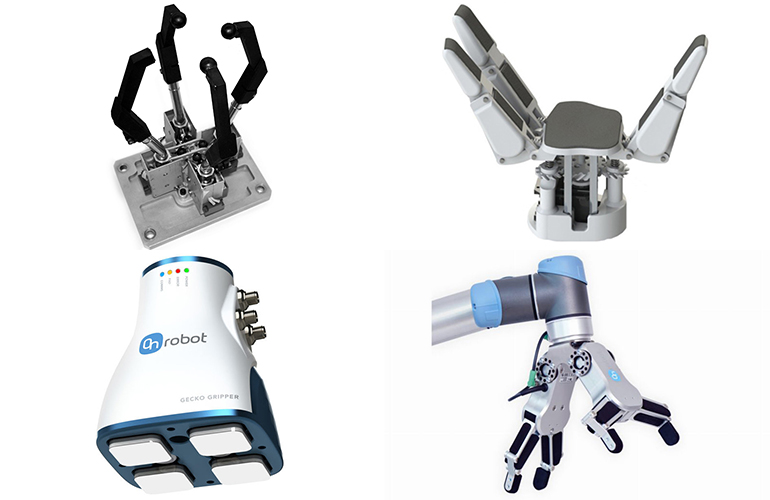
Completely different robotic finish effectors.
Roboticists often train robots new duties by remotely working them by performing a activity. The robotic then imitates the demonstration till it may possibly carry out the duty by itself.
Whereas this technique of instructing robots is efficient, it limits demonstrations to lab settings, and solely programmers and roboticists can do the demonstrations. A analysis group on the robotics division at Google has been growing a brand new means for robots to be taught.
People be taught by watching on a regular basis, however it’s not a easy activity for robots to tackle. That is tough for robots as a result of they appear completely different than people. For instance, a robotic with a two-fingered gripper received’t achieve a lot information about the best way to choose up a pen from watching a human with a five-fingered hand choose one up.
To sort out this downside, the group launched a self-supervised technique for Cross-Embodiment Inverse Reinforcement Studying (XIRL).
This technique of instructing focuses on the robotic studying the high-level activity goal from movies. So, as an alternative of making an attempt to make particular person human actions correspond with robotic actions, the robotic figures out what its finish objective is.
It then summarizes that info within the type of a reward perform that’s invariant to bodily variations like form, actions and finish effector dynamics. By using the discovered rewards and reinforcement studying, the analysis group taught robots the best way to deal with objects by trial and error.
The robots discovered extra when the pattern movies had been extra various. Experiments confirmed that the group’s studying technique led to 2 to 4 instances extra pattern environment friendly reinforcement studying on new embodiments.
The group has made an open-source implementation of its technique and X-MAGICAL, its simulated benchmark for cross-embodiment imitation, to let others prolong and construct on their work.
X-MAGICAL was created to guage XIRL’s efficiency in a constant atmosphere. This system challenges a set of agent embodiments, which have completely different shapes and finish effectors, to carry out a activity. The brokers carry out the duties in several methods and at completely different speeds.
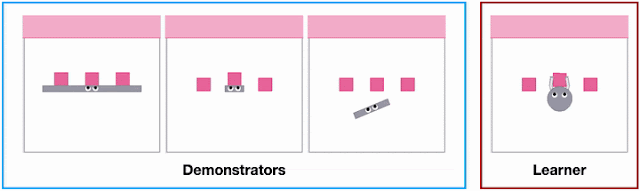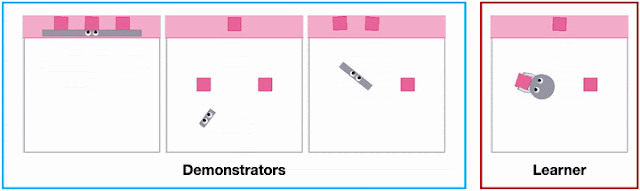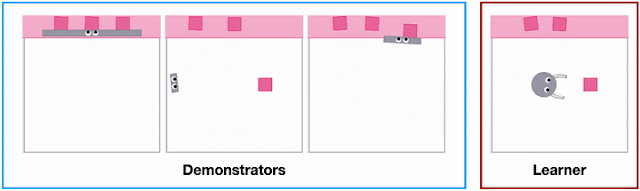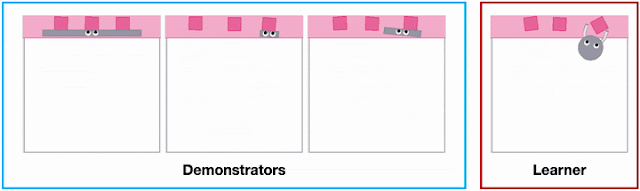
Demonstrating completely different shapes performing a activity in X-MAGICAL. | Supply: Google
The group additionally taught utilizing real-world human demonstrations of duties. They used their technique to coach a simulated Sawyer arm to push a puck right into a goal zone. Their instructing technique additionally outperformed baseline strategies.
The analysis group included Kevin Zakka, Andy Zeng, Pete Florence, Jonathan Tompson and Debidatta Dwibedi from robotics at Google, and Jeannette Bohg from Stanford College.
[ad_2]

