



[ad_1]
Reinforcement studying (RL) can be utilized to coach a coverage to carry out a job by way of trial and error, however a serious problem in RL is studying insurance policies from scratch in environments with exhausting exploration challenges. For instance, contemplate the setting depicted within the door-binary-v0 setting from the adroit manipulation suite, the place an RL agent should management a hand in 3D house to open a door positioned in entrance of it.
 |
| An RL agent should management a hand in 3D house to open a door positioned in entrance of it. The agent receives a reward sign solely when the door is totally open. |
Because the agent receives no middleman rewards, it can not measure how shut it’s to finishing the duty, and so should discover the house randomly till it will definitely opens the door. Given how lengthy the duty takes and the exact management required, that is extraordinarily unlikely.
For duties like this, we are able to keep away from exploring the state house randomly through the use of prior info. This prior info helps the agent perceive which states of the setting are good, and must be additional explored. We might use offline information (i.e., information collected by human demonstrators, scripted insurance policies, or different RL brokers) to coach a coverage, then use it to initialize a brand new RL coverage. Within the case the place we use neural networks to symbolize the insurance policies, this might contain copying the pre-trained coverage’s neural community over to the brand new RL coverage. This process makes the brand new RL coverage behave just like the pre-trained coverage. Nevertheless, naïvely initializing a brand new RL coverage like this typically works poorly, particularly for value-based RL strategies, as proven under.
 |
| A coverage is pre-trained on the antmaze-large-diverse-v0 D4RL setting with offline information (unfavourable steps correspond to pre-training). We then use the coverage to initialize actor-critic fine-tuning (constructive steps ranging from step 0) with this pre-trained coverage because the preliminary actor. The critic is initialized randomly. The actor’s efficiency instantly drops and doesn’t recuperate, because the untrained critic offers a poor studying sign and causes the nice preliminary coverage to be forgotten. |
With the above in thoughts, in “Bounce-Begin Reinforcement Studying” (JSRL), we introduce a meta-algorithm that may use a pre-existing coverage of any kind to initialize any kind of RL algorithm. JSRL makes use of two insurance policies to be taught duties: a guide-policy, and an exploration-policy. The exploration-policy is an RL coverage that’s educated on-line with new expertise that the agent collects from the setting, and the guide-policy is a pre-existing coverage of any kind that’s not up to date throughout on-line coaching. On this work, we deal with situations the place the guide-policy is discovered from demonstrations, however many other forms of guide-policies can be utilized. JSRL creates a studying curriculum by rolling within the guide-policy, which is then adopted by the self-improving exploration-policy, leading to efficiency that compares to or improves on aggressive IL+RL strategies.
The JSRL Method
The guide-policy can take any kind: it may very well be a scripted coverage, a coverage educated with RL, or perhaps a reside human demonstrator. The one necessities are that the guide-policy is affordable (i.e., higher than random exploration), and it might choose actions primarily based on observations of the setting. Ideally, the guide-policy can attain poor or medium efficiency within the setting, however can not additional enhance itself with extra fine-tuning. JSRL then permits us to leverage the progress of this guide-policy to take the efficiency even larger.
At the start of coaching, we roll out the guide-policy for a set variety of steps in order that the agent is nearer to aim states. The exploration-policy then takes over and continues appearing within the setting to succeed in these objectives. Because the efficiency of the exploration-policy improves, we progressively cut back the variety of steps that the guide-policy takes, till the exploration-policy takes over utterly. This course of creates a curriculum of beginning states for the exploration-policy such that in every curriculum stage, it solely must be taught to succeed in the preliminary states of prior curriculum levels.
 |
| Right here, the duty is for the robotic arm to choose up the blue block. The guide-policy can transfer the arm to the block, but it surely can not decide it up. It controls the agent till it grips the block, then the exploration-policy takes over, ultimately studying to choose up the block. Because the exploration-policy improves, the guide-policy controls the agent much less and fewer. |
Comparability to IL+RL Baselines
Since JSRL can use a previous coverage to initialize RL, a pure comparability can be to imitation and reinforcement studying (IL+RL) strategies that prepare on offline datasets, then fine-tune the pre-trained insurance policies with new on-line expertise. We present how JSRL compares to aggressive IL+RL strategies on the D4RL benchmark duties. These duties embody simulated robotic management environments, together with datasets of offline information from human demonstrators, planners, and different discovered insurance policies. Out of the D4RL duties, we deal with the troublesome ant maze and adroit dexterous manipulation environments.
For every experiment, we prepare on an offline dataset after which run on-line fine-tuning. We evaluate in opposition to algorithms designed particularly for every setting, which embody AWAC, IQL, CQL, and behavioral cloning. Whereas JSRL can be utilized together with any preliminary guide-policy or fine-tuning algorithm, we use our strongest baseline, IQL, as a pre-trained information and for fine-tuning. The total D4RL dataset contains a million offline transitions for every ant maze job. Every transition is a sequence of format (S, A, R, S’) which specifies what state the agent began in (S), the motion the agent took (A), the reward the agent obtained (R), and the state the agent ended up in (S’) after taking motion A. We discover that JSRL performs properly with as few as ten thousand offline transitions.
 |
 |
| Common rating (max=100) on the antmaze-medium-diverse-v0 setting from the D4RL benchmark suite. JSRL can enhance even with restricted entry to offline transitions. |
Imaginative and prescient-Based mostly Robotic Duties
Using offline information is very difficult in complicated duties resembling vision-based robotic manipulation as a result of curse of dimensionality. The excessive dimensionality of each the continuous-control motion house and the pixel-based state house current scaling challenges for IL+RL strategies by way of the quantity of knowledge required to be taught good insurance policies. To review how JSRL scales to such settings, we deal with two troublesome simulated robotic manipulation duties: indiscriminate greedy (i.e., lifting any object) and occasion greedy (i.e., lifting a selected goal object).
 |
| A simulated robotic arm is positioned in entrance of a desk with varied classes of objects. When the robotic lifts any object, a sparse reward is given for the indiscriminate greedy job. For the occasion greedy job, a sparse reward is barely given when a selected goal object is grasped. |
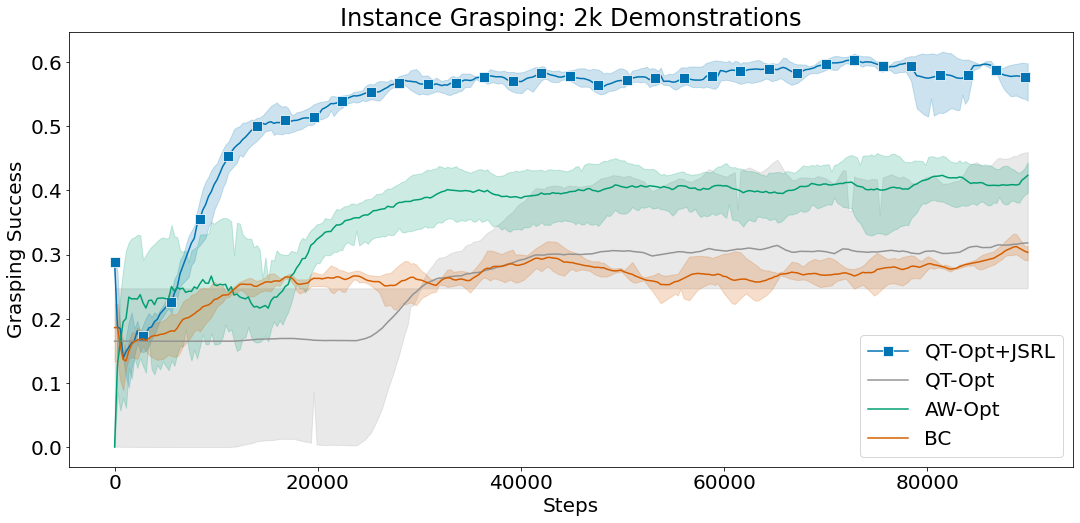
We evaluate JSRL in opposition to strategies which are in a position to scale to complicated vision-based robotics settings, resembling QT-Choose and AW-Choose. Every methodology has entry to the identical offline dataset of profitable demonstrations and is allowed to run on-line fine-tuning for as much as 100,000 steps.
In these experiments, we use behavioral cloning as a guide-policy and mix JSRL with QT-Go for fine-tuning. The mix of QT-Choose+JSRL improves sooner than all different strategies whereas reaching the best success price.
 |
 |
| Imply greedy success for indiscriminate and occasion greedy environments utilizing 2k profitable demonstrations. |
Conclusion
We proposed JSRL, a way for leveraging a previous coverage of any kind to enhance exploration for initializing RL duties. Our algorithm creates a studying curriculum by rolling in a pre-existing guide-policy, which is then adopted by the self-improving exploration-policy. The job of the exploration-policy is drastically simplified because it begins exploring from states nearer to the aim. Because the exploration-policy improves, the impact of the guide-policy diminishes, resulting in a totally succesful RL coverage. Sooner or later, we plan to use JSRL to issues resembling Sim2Real, and discover how we are able to leverage a number of guide-policies to coach RL brokers.
Acknowledgements
This work wouldn’t have been attainable with out Ikechukwu Uchendu, Ted Xiao, Yao Lu, Banghua Zhu, Mengyuan Yan, Joséphine Simon, Matthew Bennice, Chuyuan Fu, Cong Ma, Jiantao Jiao, Sergey Levine, and Karol Hausman. Particular because of Tom Small for creating the animations for this submit.
[ad_2]

