



[ad_1]
Deep machine studying (ML) techniques have achieved appreciable success in medical picture evaluation in recent times. One main contributing issue is entry to plentiful labeled datasets, that are used to coach extremely efficient supervised deep studying fashions. Nonetheless, within the real-world, these fashions could encounter samples exhibiting uncommon circumstances which are individually too rare for per-condition classification. However, such circumstances might be collectively frequent as a result of they comply with a long-tail distribution and when taken collectively can symbolize a good portion of instances — e.g., in a current deep studying dermatological research, tons of of uncommon circumstances composed round 20% of instances encountered by the mannequin at take a look at time.
To stop fashions from producing inaccurate outputs on uncommon samples at take a look at time, there stays a substantial want for deep studying techniques with the power to acknowledge when a pattern just isn’t a situation it may determine. Detecting beforehand unseen circumstances might be considered an out-of-distribution (OOD) detection process. By efficiently figuring out OOD samples, preventive measures might be taken, like abstaining from prediction or deferring to a human skilled.
Conventional laptop imaginative and prescient OOD detection benchmarks work to detect dataset distribution shifts. For instance, a mannequin could also be skilled on CIFAR photos however be introduced with avenue view home numbers (SVHN) as OOD samples, two datasets with very totally different semantic meanings. Different benchmarks search to detect slight variations in semantic data, e.g., between photos of a truck and a pickup truck, or two totally different pores and skin circumstances. The semantic distribution shifts in such near-OOD detection issues are extra refined compared to dataset distribution shifts, and thus, are tougher to detect.
In “Does Your Dermatology Classifier Know What it Doesn’t Know? Detecting the Lengthy-Tail of Unseen Situations”, printed in Medical Picture Evaluation, we deal with this near-OOD detection process within the software of dermatology picture classification. We suggest a novel hierarchical outlier detection (HOD) loss, which leverages present fine-grained labels of uncommon circumstances from the lengthy tail and modifies the loss perform to group unseen circumstances and enhance identification of those close to OOD classes. Coupled with numerous illustration studying strategies and the numerous ensemble technique, this method allows us to realize higher efficiency for detecting OOD inputs.
The Close to-OOD Dermatology Dataset
We curated a near-OOD dermatology dataset that features 26 inlier circumstances, every of that are represented by a minimum of 100 samples, and 199 uncommon circumstances thought of to be outliers. Outlier circumstances can have as little as one pattern per situation. The separation standards between inlier and outlier circumstances might be specified by the person. Right here the cutoff pattern dimension between inlier and outlier was 100, in keeping with our earlier research. The outliers are additional cut up into coaching, validation, and take a look at units which are deliberately mutually unique to imitate real-world eventualities, the place uncommon circumstances proven throughout take a look at time could haven’t been seen in coaching.
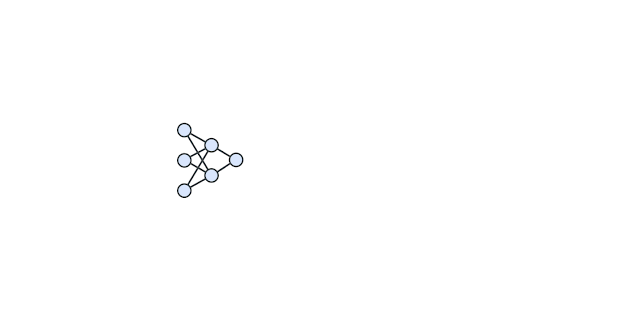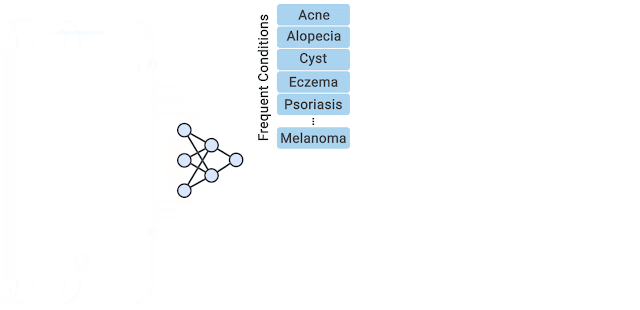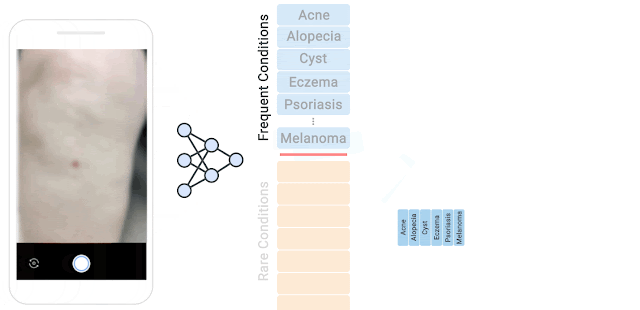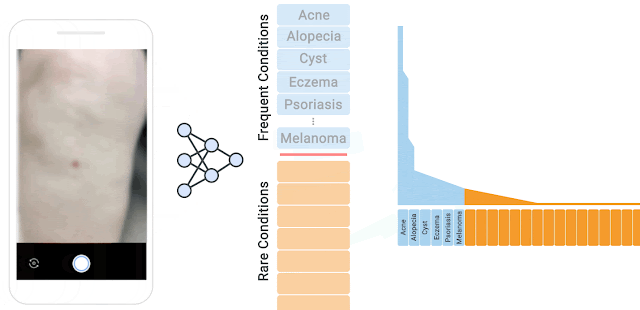 |
| Lengthy tail distribution of various dermatological circumstances in our dataset. The 26 inlier circumstances, with a minimum of 100 samples, (blue) and the remaining 199 uncommon outlier circumstances (orange). Outlier circumstances can have as little as one pattern per situation. |
 |
| Prepare set | Validation set | Take a look at set | ||||
| Inlier | Outlier | Inlier | Outlier | Inlier | Outlier | |
| Variety of courses | 26 | 68 | 26 | 66 | 26 | 65 |
| Variety of samples | 8854 | 1111 | 1251 | 1082 | 1192 | 937 |
| Inlier and outlier circumstances in our benchmark dataset and detailed dataset cut up statistics. The outliers are additional cut up into mutually unique practice, validation, and take a look at units. |
Hierarchical Outlier Detection Loss
We suggest to make use of “identified outlier” samples throughout coaching which are leveraged to assist detection of “unknown outlier” samples throughout take a look at time. Our novel hierarchical outlier detection (HOD) loss performs a fine-grained classification of particular person courses for all inlier or outlier courses and, in parallel, a coarse-grained binary classification of inliers vs. outliers in a hierarchical setup (see the determine under). Our experiments confirmed that HOD is more practical than performing a coarse-grained classification adopted by a fine-grained classification, as this might end in a bottleneck that impacted the efficiency of the fine-grained classifier.
We use the sum of the predictive chances of the outlier courses because the OOD rating. As a main OOD detection metric we use the space underneath receiver working traits (AUROC) curve, which ranges between 0 and 1 and offers us a measure of separability between inliers and outliers. An ideal OOD detector, which separates all inliers from outliers, is assigned an AUROC rating of 1. A preferred baseline technique, referred to as reject bucket, separates every inlier individually from the outliers, that are grouped right into a devoted single abstention class. Along with a fine-grained classification for every particular person inlier and outlier courses, the HOD loss–primarily based method separates the inliers collectively from the outliers with a coarse-grained prediction loss, leading to higher generalization. Whereas related, we exhibit that our HOD loss–primarily based method outperforms different baseline strategies that leverage outlier information throughout coaching, reaching an AUROC rating of 79.4% on the benchmark, a major enchancment over that of reject bucket, which achieves 75.6%.
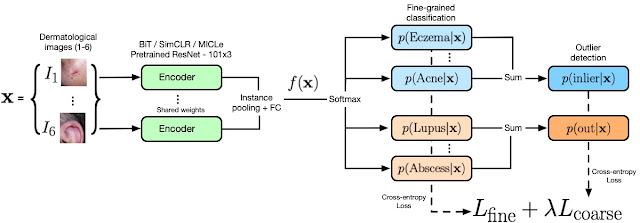 |
| Our mannequin structure and the HOD loss. The encoder (inexperienced) represents the broad ResNet 101×3 mannequin pre-trained with totally different illustration studying fashions (ImageNet, BiT, SimCLR, and MICLe; see under). The output of the encoder is distributed to the HOD loss the place fine-grained and coarse-grained predictions for inliers (blue) and outliers (orange) are obtained. The coarse predictions are obtained by summing over the fine-grained chances as indicated within the determine. The OOD rating is outlined because the sum of the possibilities of outlier courses. |
Illustration Studying and the Various Ensemble Technique
We additionally examine how various kinds of illustration studying assist in OOD detection along side HOD by pretraining on ImageNet, BiT-L, SimCLR and MICLe fashions. We observe that together with HOD loss improves OOD efficiency in comparison with the reject bucket baseline technique for all 4 illustration studying strategies.
| Illustration Studying Strategies |
OOD detection metric (AUROC %) | |
| With reject bucket | With HOD loss | |
| ImageNet | 74.7% | 77% |
| BiT-L | 75.6% | 79.4% |
| SimCLR | 75.2% | 77.2% |
| MICLe | 76.7% | 78.8% |
| OOD detection efficiency for various illustration studying fashions with reject bucket and with HOD loss. |
One other orthogonal method for enhancing OOD detection efficiency and accuracy is deep ensemble, which aggregates outputs from a number of independently skilled fashions to supply a remaining prediction. We construct upon deep ensemble, however as a substitute of utilizing a hard and fast structure with a hard and fast pre-training, we mix totally different illustration studying architectures (ImageNet, BiT-L, SimCLR and MICLe) and introduce goal loss features (HOD and reject bucket). We name this a numerous ensemble technique, which we exhibit outperforms the deep ensemble for OOD efficiency and inlier accuracy.
Downstream Medical Belief Evaluation
Whereas we primarily concentrate on enhancing the efficiency for OOD detection, the last word objective for our dermatology mannequin is to have excessive accuracy in predicting inlier and outlier circumstances. We transcend conventional efficiency metrics and introduce a “penalty” matrix that collectively evaluates inlier and outlier predictions for mannequin belief evaluation to approximate downstream impression. For a hard and fast confidence threshold, we depend the next forms of errors: (i) incorrect inlier predictions (i.e., mistaking inlier situation A as inlier situation B); (ii) incorrect abstention of inliers (i.e., abstaining from making a prediction for an inlier); and (iii) incorrect prediction for outliers as one of many inlier courses.
To account for the asymmetrical penalties of the various kinds of errors, penalties might be 0, 0.5, or 1. Each incorrect inlier and outlier-as-inlier predictions can doubtlessly erode person belief within the mannequin and have been penalized with a rating of 1. Incorrect abstention of an inlier as an outlier was penalized with a rating of 0.5, indicating that potential mannequin customers ought to search extra steerage given the model-expressed uncertainty or abstention. For proper choices no price is incurred, indicated by a rating of 0.
| Motion of the Mannequin | ||||
| Prediction as Inlier | Abstain | |||
| Inlier | 0 (Right)
1 (Incorrect, errors |
0.5 (Incorrect, abstains inliers) |
||
| Outlier | 1 (Incorrect, errors that will erode belief) |
0 (Right) | ||
| The penalty matrix is designed to seize the potential impression of various kinds of mannequin errors. |
As a result of real-world eventualities are extra advanced and include a wide range of unknown variables, the numbers used right here symbolize simplifications to allow qualitative approximations for the downstream impression on person belief of outlier detection fashions, which we consult with as “price”. We use the penalty matrix to estimate a downstream price on the take a look at set and evaluate our technique in opposition to the baseline, thereby making a stronger case for its effectiveness in real-world eventualities. As proven within the plot under, our proposed resolution incurs a a lot decrease estimated price compared to baseline over all potential working factors.
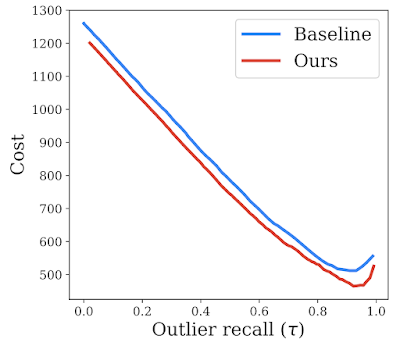 |
| Belief evaluation evaluating our proposed technique to the baseline (reject bucket) for a variety of outlier recall charges, indicated by 𝛕. We present that our technique reduces downstream estimated price, doubtlessly reflecting improved downstream impression. |
Conclusion
In real-world deployment, medical ML fashions could encounter circumstances that weren’t seen in coaching, and it’s necessary that they precisely determine once they have no idea a selected situation. Detecting these OOD inputs is a crucial step to enhancing security. We develop an HOD loss that leverages outlier information throughout coaching, and mix it with pre-trained illustration studying fashions and a various ensemble to additional increase efficiency, considerably outperforming the baseline method on our new dermatology benchmark dataset. We consider that our method, aligned with our AI Ideas, can assist profitable translation of ML algorithms into real-world eventualities. Though we now have primarily centered on OOD detection for dermatology, most of our contributions are pretty generic and might be simply included into OOD detection for different functions.
Acknowledgements
We wish to thank Shekoofeh Azizi, Aaron Loh, Vivek Natarajan, Basil Mustafa, Nick Pawlowski, Jan Freyberg, Yuan Liu, Zach Beaver, Nam Vo, Peggy Bui, Samantha Winter, Patricia MacWilliams, Greg S. Corrado, Umesh Telang, Yun Liu, Taylan Cemgil, Alan Karthikesalingam, Balaji Lakshminarayanan, and Jim Winkens for his or her contributions. We might additionally prefer to thank Tom Small for creating the publish animation.
[ad_2]

